# Add Context (/docs/add-context)
BibGenie does more than show the AI a filename. Add Context brings Zotero research objects, document content, and your current reading location into the conversation, so the AI knows which source you are studying, which section you are reading, and which passage matters.
You can start with an entire Zotero item, then narrow the context to a PDF page, an EPUB section, or a passage selected in a PDF, EPUB, or snapshot. The closer the context is to your question, the more focused the answer and the easier it is to verify against the source.
Add Context captures both “what source is this?” and “where am I reading?” You can add items, attachments, notes, collections, and tags, as well as the current PDF page, current EPUB section, or selected Reader text.
## Ways to Add Context [#ways-to-add-context]
Type a space followed by `@` in the input box to search for and insert Zotero items, attachments, notes, tags, collections, and more.
Click the Add Context button near the input box to open a selection dialog.
Add context from Zotero items, collections, tags, reader tabs, or selected text.
Paste images into the input box or use Zotero-side screenshots for figures, formulas, and page regions.
## Supported Context Types [#supported-context-types]
| Type | Best for |
| :--------------------------------------- | :------------------------------------------------------------------------- |
| Regular item | Bibliographic metadata, title, authors, year, and related attachments |
| PDF attachment | Full-paper reading, section summaries, methods, and results |
| EPUB attachment | Full-book reading, with access by logical page or section |
| Snapshot | Reading web pages saved in Zotero |
| Note | Using Zotero notes, excerpts, and research notes as context |
| Saved annotation | Working with a highlight, comment, color, tag, and its source location |
| Collection | Working with a set of papers |
| Tag | Working with papers under a specific tag |
| Selected text from PDF / EPUB / Snapshot | Precise explanation of a passage |
| Current PDF page context | Asking about the page you are reading |
| Current EPUB section | Reading the current EPUB content unit and returning to it from the message |
| Image / screenshot | Analyzing figures, formulas, diagrams, and page regions |
## Add Context With `@` [#add-context-with-]
Type a space followed by `@` in the input box to open the context search menu. You can then type a title, author, keyword, note name, tag name, or collection name to filter results.
Common examples:
```text
@attention is all you need
@Smith 2023
@my research note
@systematic-review
@my project collection
```
After selecting a result, it appears as a context block in the input box. You can add multiple context blocks before asking a question.
## Add Context From Zotero [#add-context-from-zotero]
You can add the current Zotero object directly to BibGenie:
* Right-click one or more library items and choose **Add to Chat**.
* Right-click a collection in the collection tree.
* Right-click a tag in the tag selector.
* Right-click a PDF, snapshot, or note tab.
* Select text in a PDF, EPUB, or snapshot and add it to chat.
* In the PDF Reader, add the current page; in the EPUB Reader, choose **Add Section to Chat** to add the current section.
These entry points can be enabled or disabled in [Add to Chat Settings](/docs/add-to-chat-settings).
## Add Precise Context From the Reader [#add-precise-context-from-the-reader]
BibGenie uses a reading unit suited to each document format:
| Reader | Precise context you can add | Best for |
| :------- | :------------------------------- | :---------------------------------------------------------- |
| PDF | Current page or selected text | Checking page-specific claims, figures, or passages |
| EPUB | Current section or selected text | Reading a chapter unit or explaining a specific passage |
| Snapshot | Selected text | Analyzing a specific passage from a webpage saved in Zotero |
The context appears in your message after you add it. When valid location data is available, click the context component in the message to reopen the appropriate Reader and return to the relevant location.
An EPUB's table of contents and file structure do not always map one to one. The current section usually corresponds to an XHTML content unit in the EPUB spine. If several nested TOC entries share one XHTML file, Add Section to Chat adds that complete content unit rather than extracting a single anchored subsection.
## Examples [#examples]
Add a PDF and ask:
```text
Summarize this paper by research question, method, data, main findings, and limitations.
```
Add the current section from the EPUB Reader and ask:
```text
Summarize the main argument in this section and explain how it relates to the book's overall theme.
```
Add several related papers and ask:
```text
Compare these papers by assumptions, methods, and conclusions. Return a comparison table.
```
Add a selected passage and ask:
```text
Explain the logic of this passage and identify the key concepts.
```
Add a figure screenshot and ask:
```text
Explain the axes, curves, and main conclusion of this figure.
```
## Tips [#tips]
* Add only the context that is relevant to the current question.
* For complex tasks, ask for a summary first, then follow up with details.
* For multi-paper comparisons, ask BibGenie to list each paper first before synthesizing.
* Screenshots are useful for figures and formulas, but add the source PDF or item if you need citation-level grounding.
# Add to Chat Settings (/docs/add-to-chat-settings)
BibGenie places **Add to Chat** in the parts of the Zotero library and Reader where you already work. You can send a relevant source or the passage you are reading to the AI without copying text, hunting down the attachment, and switching back to the chat first.
Different research habits call for different entry points. Keep PDF selections and EPUB sections if you use them often, or hide lower-frequency actions to keep Zotero's context menus clean.
Disabling an Add to Chat entry point usually hides that menu item or shortcut. It does not necessarily mean BibGenie cannot add that type of context by other methods.
## Available Toggles [#available-toggles]
| Setting | What it controls |
| :---------------------- | :------------------------------------------------------------------------ |
| Library Items | Shows Add to Chat for supported Zotero items, including saved annotations |
| Collections | Shows Add to Chat in the collection tree |
| Tags | Shows Add to Chat in the tag selector |
| Reader Tabs | Shows Add to Chat for open PDF, snapshot, and note tabs |
| PDF Text Selection | Adds selected PDF text to chat |
| EPUB Text Selection | Adds selected EPUB text to chat |
| Snapshot Text Selection | Adds selected snapshot text to chat |
| Reader Annotations | Adds one or more saved annotations from the Reader context menu |
| Reader Page Context | Shows Add Page to Chat in the PDF Reader and adds the current page |
| EPUB Section Context | Shows Add Section to Chat in the EPUB Reader and adds the current section |
## What These Entry Points Add [#what-these-entry-points-add]
Add to Chat works at three levels:
Items, collections, and tags tell BibGenie which sources or groups of sources you are working with.
Reader tabs add a PDF, snapshot, or note as a whole, which is useful for summaries and synthesis.
PDF pages, EPUB sections, and selected text focus the question on what you are reading right now.
When the context includes valid location data, you can click its component in your message to reopen the document and return to the relevant location.
## Recommended Defaults [#recommended-defaults]
If you are new to BibGenie, keep the default configuration. Common preferences:
Keep Library Items, Reader Tabs, and the Text Selection entries for the formats you use most.
Keep Collections and Tags enabled if you often work by project, theme, or literature group.
Disable lower-frequency entries if your Zotero context menus feel crowded.
## Tips [#tips]
* If you read PDFs heavily, enable PDF Text Selection and Reader Page Context.
* If you read ebooks, enable EPUB Text Selection and EPUB Section Context.
* If you analyze saved web pages, enable Snapshot Text Selection.
* If you write literature reviews, enable Collections and Tags.
* If you prefer a minimal setup, keep Library Items and the input-box `@` menu.
# BibGenie Citation (/docs/bibgenie-citations)
BibGenie Citation connects **AI answers**, **source evidence**, and **Zotero research objects** in one traceable system.
When BibGenie answers based on your Zotero library, PDFs, notes, snapshots, web pages, or OpenAlex results, it automatically adds citation markers such as `[1]` and `[2]` where appropriate. You do not need to turn it on manually or remember special prompts. When you see a citation marker, click it to return to the source and check what the answer is based on.
BibGenie distinguishes two kinds of links that look similar but serve different purposes:
* A **citation** points to evidence supporting an answer, such as a text block or selection in a PDF, EPUB, or snapshot.
* A **clickable entity** points to a Zotero object mentioned in the answer, such as an item, attachment, note, collection, or tag. It helps you continue working with that object, but does not claim the object itself is evidence for a sentence.
The goal is not to make answers look more academic. The goal is to help you judge:
* Where did this conclusion come from?
* Did the AI misread or overgeneralize the source?
* Is this information safe to use in notes, a literature review, or a research draft?
* If you want to follow up, which source should you reread?
Citations take you back to the evidence; clickable entities take you back to Zotero to continue your work. One answer can contain both.
## Two Kinds of Clickable Links [#two-kinds-of-clickable-links]
| Type | Question it answers | Common targets | Does it represent evidence? |
| :------------ | :----------------------------------------- | :-------------------------------------------------------------------------------- | :-------------------------- |
| Citation | “What supports this claim?” | Document blocks; selected text; saved annotations; notes; web or OpenAlex results | Yes |
| Zotero entity | “Which object is the answer referring to?” | Item, attachment, note, annotation, collection, or tag | No |
For example, BibGenie can cite a specific EPUB text block as evidence while rendering the EPUB attachment mentioned in the answer as a clickable object. The first lets you verify the claim; the second lets you open and continue working with the material.
## What It Solves [#what-it-solves]
When using AI for research, the biggest risk is often not a lack of answers. It is getting a fluent answer without knowing where it came from.
In real literature work, you often need to separate three things:
| Type | Meaning | Why it matters |
| :-------------- | :----------------------------------------------------------------- | :------------------------------------------------------- |
| Original source | A PDF, note, snapshot, web page, or OpenAlex result | This is the basis for the answer |
| AI summary | BibGenie's compression, organization, or explanation of the source | Useful, but still worth checking |
| Your judgment | Your conclusion based on the source and research context | This is what should guide writing and research decisions |
BibGenie Citation keeps a clear trail between these layers. It helps you move from an AI answer back to the source, then decide for yourself whether the answer is reliable.
## Supported Sources [#supported-sources]
BibGenie citations are not only for PDFs. As you work with different sources in Zotero, citations can cover different kinds of research material.
When BibGenie reads a PDF, answers can cite pages, text blocks, or paragraph locations. For PDF-specific paragraph jumps, see [Paragraph Citations](https://www.bibgenie.com/docs/paragraph-citations).
When BibGenie reads an EPUB or its current section, answers can cite specific extracted text blocks and return you to the relevant content in the Zotero EPUB Reader.
When an answer is based on Zotero notes, excerpts, or research notes, citations help you see which note content the information came from.
When BibGenie reads web snapshots saved in Zotero, answers can cite text blocks or valid selections and return you to the saved webpage material.
When you use web search or web extraction, citations can mark which search result or webpage body the answer used.
When BibGenie uses OpenAlex academic search, citations can point to papers, authors, venues, institutions, citation networks, and other external scholarly metadata.
Items, attachments, notes, collections, and tags can appear as clickable entities in an answer. You can open the Zotero object directly without treating it as source evidence.
## Selected Text Can Be Cited Too [#selected-text-can-be-cited-too]
You can add selected text from a PDF, EPUB, or snapshot to the conversation. Besides giving BibGenie the exact passage to work with, valid Reader location data creates a route back to the source:
Select the passage you want to explain or verify in the Reader, then choose **Add to Chat**.
Ask a question about the selection. BibGenie prioritizes the passage you explicitly provided.
When the answer cites that selection, click the citation to reopen the document and return to the relevant location. In supported cases such as PDF, a temporary highlight helps you find the source quickly.
Selected text can still be used as conversation context, but if its stored position is missing, damaged, or unsafe to resolve, BibGenie does not create a citation that looks clickable but cannot return to the source.
## How Document Citations Stay Precise [#how-document-citations-stay-precise]
When BibGenie reads PDFs, EPUBs, and snapshots, it organizes document content into text blocks with stable identifiers. An answer cites the block that actually supports a claim instead of labeling the entire attachment as the source.
This has three practical benefits:
* Clicking a citation is more likely to take you to the relevant page, section, or source location.
* When several attachments are analyzed together, you can tell which material supports each claim.
* When you copy an answer or save it as a Zotero note, citations retain readable source information.
## What Citations Help You Do [#what-citations-help-you-do]
For important conclusions, data, method descriptions, and author claims, click a citation to return to the source and confirm that the material really supports the answer.
When an answer is useful, citations take you back to the most relevant PDF, note, snapshot, or web content so you can keep reading.
When you turn research into notes, citations preserve the trail from summary back to source, so you do not have to rediscover the evidence later.
When you combine local Zotero items, web pages, and OpenAlex results, citations help you distinguish local library evidence from external search results.
## Common Use Cases [#common-use-cases]
You can ask BibGenie to summarize a paper's research question, method, experimental design, findings, and limitations. Citations in the answer help you return to the paper and check key claims.
If you want to learn about PDF citations that jump back to the exact source paragraph, read [Paragraph Citations](https://www.bibgenie.com/docs/paragraph-citations).
Add an entire EPUB attachment or the current section, then ask BibGenie to summarize an argument, explain a concept, or compare chapters. Citations in the answer point to the EPUB text blocks actually used, while the section component in your message can return you to the reading location you added.
Select text in a PDF, EPUB, or snapshot and add it to the conversation to focus the question on one passage. When the selection has valid location data, citations in the answer can take you back to the source context.
If you have excerpts, reading notes, or research ideas saved in Zotero, BibGenie can organize them by theme. Citations help you see which note a summary came from instead of merging everything into an untraceable answer.
When you save a project homepage, dataset description, tool documentation, or news page as a Zotero snapshot, BibGenie can read it and mark sources with citations. If you use web search or web extraction, citations also help you see which web pages informed the answer.
OpenAlex returns external scholarly metadata such as titles, authors, DOI, venues, citation counts, and citation relationships. Citations help you trace an answer back to a specific OpenAlex result and avoid treating external search metadata as if BibGenie had read the full paper.
You can combine local PDFs, Zotero notes, OpenAlex results, and web material in one workflow. Citations help you distinguish which parts of a synthesized answer come from saved literature and which come from external supporting material.
## How to Read Citations [#how-to-read-citations]
BibGenie answers often include citation markers such as `[1]` and `[2]`. Treat them as source entry points.
**Read the answer structure**: first check whether BibGenie understood the main point of your question.
**Find the claims that matter**: focus on conclusions you may adopt, save, quote, or use for follow-up.
**Click the citation**: return to the relevant PDF, note, snapshot, webpage, or OpenAlex source.
**Check the source content**: confirm whether the source supports the statement, paying attention to scope, wording, and context.
**Follow up or refine**: if the answer is too broad, ask BibGenie to restate it based on the cited source.
## Citations vs. Formal References [#citations-vs-formal-references]
BibGenie Citation is mainly for **reading, verification, and source tracing**. It is not the final reference format for a paper.
| Item | BibGenie Citation | Formal reference |
| :----------------- | :--------------------------------------------------- | :-------------------------------------------------------------- |
| Main purpose | Return to the source behind an AI answer | Meet the formatting requirements of a paper, report, or journal |
| Where it appears | In BibGenie chat answers | In the body and bibliography of a document |
| What it focuses on | Source tracing, evidence checking, continued reading | Citation style, publication metadata, formatting |
| Ready to submit | Not recommended as a formal citation | Must be generated and checked in the required style |
If you are writing a paper, assignment, grant proposal, or formal report, you should still use Zotero citation styles such as APA, MLA, Chicago, GB/T 7714, or the format required by your target venue.
BibGenie Citation is for checking where an answer came from. For formal writing, return to the Zotero item and original source, then use the required reference format.
## Why Some Answers Have No Citation [#why-some-answers-have-no-citation]
Not every sentence will have a citation. Common reasons include:
* **The question is operational**: for example, "help me organize this collection" may produce next-step guidance rather than cite a source passage.
* **The answer is synthesized**: some summaries combine multiple sources and may not map cleanly to one citation.
* **The source is not clear enough**: if the input does not contain traceable material, BibGenie may only provide general guidance.
* **External web or metadata is limited**: OpenAlex and web results are often summaries or metadata, not full-text reading.
* **Document structure or text quality affects parsing**: scanned PDFs, weak OCR, complex layouts, mismatches between an EPUB's table of contents and spine, or unusual snapshot markup can affect citation positioning.
If an important statement has no citation, you can naturally follow up by asking where that conclusion came from, or which paper, note, or webpage supports it. Citation itself is still added automatically whenever BibGenie can trace the source.
## Usage Tips [#usage-tips]
* Do not rely only on the AI summary for important conclusions. Click citations and check the source.
* When a citation points to a PDF, EPUB, or snapshot, read the nearby context instead of only the highlighted text.
* When a citation comes from OpenAlex, remember that it usually represents scholarly metadata, not full-paper reading.
* When a citation comes from the web, remember that web content can change. For formal use, confirm it on the original page or another authoritative source.
* When writing literature notes, keep the automatically generated citations so you can review the source later.
* For formal papers, do not copy BibGenie Citation directly. Use Zotero to generate standard references.
* If an answer has no citation, ask "what is this conclusion based on?" or "which paper, note, or webpage does it come from?"
## Relationship to Paragraph Citations [#relationship-to-paragraph-citations]
BibGenie Citation is the broader concept. It covers PDFs, notes, snapshots, web pages, OpenAlex, and other traceable sources. It answers:
**Where did the information in this AI answer come from?**
[Paragraph Citations](https://www.bibgenie.com/docs/paragraph-citations) is a more specific and more powerful PDF reading feature. It answers:
**Can this PDF-based conclusion jump back to the exact paragraph in the original paper?**
If you mainly care about close PDF reading, original-text highlights, and clicking citations to jump back to Zotero PDF Reader, continue with [Paragraph Citations](https://www.bibgenie.com/docs/paragraph-citations).
BibGenie Citation is the overview: it gives answers sources. Paragraph Citations is the PDF close-reading highlight: it lets PDF answers jump back to source paragraphs.
# Bring Your Own Key (/docs/byok)
BYOK means Bring Your Own Key. It lets you use your own model provider, API key, or local model with BibGenie.
## Why Use BYOK? [#why-use-byok]
Custom model requests go directly from the local Zotero plugin to the provider you configure.
Run models on your own machine with Ollama or LM Studio.
BYOK requests do not use BibGenie's official model service, so they do not consume BibGenie credits.
Use models that are not currently included in the official list.
## Does Data Pass Through BibGenie's Service? [#does-data-pass-through-bibgenies-service]
If you add a custom model, request data does not go through BibGenie's model service. The local Zotero plugin sends requests directly to the provider you configure.
That means:
* OpenAI API key: requests go directly to OpenAI.
* Anthropic API key: requests go directly to Anthropic.
* OpenAI-compatible proxy: requests go to the Base URL you enter.
* Ollama or LM Studio: requests can stay entirely on your machine.
BYOK bypasses BibGenie's model service, but cloud providers still receive the content you send to them. Choose providers according to your institution, lab, or project data policy.
## Supported Providers [#supported-providers]
BibGenie supports multiple provider types:
| Provider | Notes |
| :---------------- | :----------------------------- |
| OpenAI | OpenAI GPT models |
| Anthropic | Claude models |
| xAI | Grok models |
| DeepSeek | DeepSeek models |
| Google | Gemini models |
| Groq | Groq-hosted models |
| Moonshot AI | Kimi models |
| OpenRouter | Unified model routing platform |
| Ollama | Local model service |
| OpenAI Compatible | Any OpenAI-compatible API |
LM Studio is usually configured through **OpenAI Compatible**.
## When BYOK Is a Good Fit [#when-byok-is-a-good-fit]
* You already have a provider API key.
* You want provider billing to happen through your own account.
* You need to use an institutional model service.
* You want requests to bypass BibGenie's official model service.
* You want to process sensitive material with a local model.
* You need a model that is not in the official list yet.
## Next Step [#next-step]
Read [Custom Models](/docs/custom-models) to add a provider, enter the Base URL and API key, and test the connection.
# Citation Format (/docs/citation-format)
Citation Format controls how BibGenie displays Zotero items in chat context. It especially affects the item context style shown after you type `@` in the input box.
## What It Affects [#what-it-affects]
* Item display in `@` search results.
* Item display after being added to chat context.
* The citation-style representation BibGenie receives as context.
Citation Format only changes display. It does not edit item title, authors, year, journal, or other Zotero metadata.
## Choose a CSL Style [#choose-a-csl-style]
BibGenie uses CSL styles installed in Zotero. You can choose the default CSL style from **Citation Format** in Preferences.
Common styles include:
* APA
* Chicago
* MLA
* IEEE
* Nature
* Vancouver
## When to Change It [#when-to-change-it]
Choose the style required by your field, journal, or manuscript.
Author-year styles are often easier to scan in social sciences and humanities.
Numbered styles may fit engineering, computer science, or IEEE-style workflows.
## FAQ [#faq]
BibGenie reads CSL styles installed in Zotero. Install or enable the style in Zotero first.
No. This setting mainly affects BibGenie's chat context display.
# Conversation Management (/docs/conversation-management)
BibGenie preserves each conversation as a research path that you can revise, extend, or branch. You can correct your latest prompt, regenerate an answer, continue from an earlier response in a separate conversation, and compact older context when a thread becomes long.
Revise the latest user message that can be edited safely, then submit it again.
Ask BibGenie to generate the latest answer again from the same preceding context.
Start a separate conversation from a completed response without losing the original path.
Summarize older content while retaining recent messages for the next model request.
## Edit the latest prompt [#edit-the-latest-prompt]
Move the pointer over the latest editable user message and select **Edit**. After you revise and submit it, BibGenie continues the current conversation from the updated prompt.
Editing replaces everything that follows the selected message on the current path. The previous answer and any trailing state derived from it no longer belong to that path. If you may need the original line of inquiry, [fork the conversation](#fork-a-conversation) first.
Editing may be unavailable while the AI is responding, a tool is still running, or an approval is pending.
## Retry an answer [#retry-an-answer]
If the latest answer is not useful, select **Retry** beneath the response. BibGenie keeps the preceding context and generates that answer again.
Retry replaces the original answer on the current path. If a trailing compaction record depends on that answer, it becomes invalid as well. BibGenie evaluates the context again when you next send a message.
To preserve both results, fork from the original answer before retrying in one of the conversations.
## Fork a conversation [#fork-a-conversation]
Fork creates a new conversation from a completed response. Move the pointer over an eligible assistant response, select **Fork**, and confirm the action. BibGenie then creates and opens the new conversation.
```text
Original: Question 1 → Answer 1 → Question 2 → Answer 2
│
New fork: └→ New question → New answer
```
The fork inherits the selected response and all context before it. From that point on, the two conversations develop independently: sending, editing, or retrying in one does not rewrite the later messages in the other.
Fork is useful when you want to:
* Explore different interpretations or hypotheses from the same paper.
* Compare prompts, models, or analytical approaches.
* Preserve a result before trying an operation that may change what follows.
Only stable, completed assistant responses can be forked. Finish the current response, tool call, or approval before trying again.
## Compact long conversations [#compact-long-conversations]
Every model has a finite context window. As messages, papers, images, and tool results accumulate, a conversation approaches that limit. BibGenie can summarize older turns into compact context while retaining recent messages for continued work.
The BibGenie agent normally compacts a conversation automatically when needed. Unless you explicitly want to compact older context now, continue asking questions without selecting Compact yourself.
### Automatic compaction [#automatic-compaction]
BibGenie checks the available context at these points:
* Before sending a new message: if the projected request is approaching the model limit, BibGenie compacts older context first and then sends your message automatically.
* After a turn finishes: if context usage has reached the compaction threshold, BibGenie compacts older content in the background.
Automatic and manual compaction use the same progress indicator. If sending a message triggers compaction, the queued message continues automatically after compaction succeeds; you do not need to send it again.
### Manual compaction [#manual-compaction]
When you explicitly want to compact the current conversation, move the pointer over the **Context Window** indicator at the lower-right of the composer and select the compaction icon in the card's upper-right corner. While it runs, the conversation shows **Compacting earlier context…**. You can keep editing the composer or select **Cancel** before compaction finishes.
### Review the compacted summary [#review-the-compacted-summary]
After compaction, an **Earlier context compacted** divider appears in the conversation. Expand it to review:
* The summary of earlier turns.
* The context token count before compaction.
* The model and context-window information used for compaction.
The divider is not treated as a normal user prompt, and later answers do not respond to it directly. Before each model request, BibGenie combines the latest summary with the retained recent messages to form the effective context.
## How these actions work together [#how-these-actions-work-together]
| Action | Effect on the current conversation | Creates a new conversation | Calls the model |
| :------ | :------------------------------------------------------------------------------ | :------------------------: | :--------------: |
| Edit | Replaces the selected user message and everything after it on the current path | No | When resubmitted |
| Retry | Replaces the latest retryable answer and its trailing state | No | Yes |
| Fork | Preserves the original and creates an independent path from the selected answer | Yes | No |
| Compact | Summarizes older context while retaining recent messages | No | Yes |
If an operation may replace an answer you still need, fork the conversation first.
## When an action is unavailable [#when-an-action-is-unavailable]
Edit, Retry, Fork, or Compact may be temporarily unavailable when:
* BibGenie is generating an answer.
* A tool call is still running or waiting for your approval.
* The conversation is being compacted, or a submitted message is waiting for compaction to finish.
* The selected message is not at a position that can be edited or forked safely.
* The saved conversation history is damaged and has opened in read-only mode.
Finish or cancel the current operation, then try again. If a conversation opens as read-only, BibGenie preserves the history it can display safely and does not modify the original saved data.
# Custom Models (/docs/custom-models)
Custom models let you use your own API key, third-party provider, local model, or institutional model service. Once configured, BibGenie sends requests directly from the local Zotero plugin to the provider you choose.
## Add a Model [#add-a-model]
Open BibGenie and go to **Model Settings**.
Click **Add Model** in the Custom Models section.
Select or enter a **Provider ID**. BibGenie loads common providers from a model catalog and automatically fills Provider Name, Provider Type, and Base URL when possible.
Select or enter a **Model ID**. If the model exists in the catalog, BibGenie automatically fills Model Name, Family, Model Types, Context Window, Max Tokens, and Description.
Enter your API Key. For local services such as Ollama, an API key is usually not required.
Click **Test** to verify the connection. A successful test shows **Connected**. If the test fails, BibGenie shows the provider error message so you can correct the configuration.
Review the auto-filled fields and adjust Model Types, Context Window, or Max Tokens if needed.
Click **Add Model**. The model is saved, enabled, and becomes available in the chat model selector.
## Auto-Fill Behavior [#auto-fill-behavior]
Adding a custom model is not entirely manual. BibGenie loads provider and model information from the `models.dev` catalog when available:
* Provider ID supports searching common providers and entering a custom provider manually.
* Selecting a provider can auto-fill Provider Name, Provider Type, and Base URL.
* Model ID is filtered by the selected provider and supports both catalog models and custom model IDs.
* Selecting a catalog model can auto-fill Model Name, Family, Model Types, Context Window, Max Tokens, Description, and pricing metadata.
* If the model catalog cannot be loaded, BibGenie uses a built-in fallback provider list, and you can still add models manually.
If your provider and model appear in the search dropdowns, select them instead of typing everything manually. This reduces mistakes in Provider Type, Base URL, model capabilities, and context limits.
## Fields [#fields]
| Field | Required | Description |
| :------------- | :------- | :---------------------------------------------------------------------------------------------------------------------- |
| Provider ID | Required | Unique provider identifier, such as `openai`, `anthropic`, or `openrouter`; custom IDs are supported |
| Provider Name | Required | Display name for the provider; usually auto-filled from the catalog |
| Model ID | Required | Actual model ID used by the provider API, such as `gpt-4.1` or `claude-sonnet-4-5` |
| Model Name | Required | Display name shown in BibGenie; usually auto-filled from the catalog |
| API Key | Optional | Your provider API key; local providers such as Ollama usually do not require one |
| Base URL | Optional | API endpoint; often auto-filled for catalog providers, but compatible or local services may require manual confirmation |
| Provider Type | Required | API integration type, such as OpenAI, Anthropic, Ollama, or OpenAI Compatible |
| Family | Optional | Model family, such as `qwen`, `gpt`, or `claude`; often auto-filled |
| Model Types | Required | Capabilities such as Text, Vision, Reasoning, Function Calling, or Web Search |
| Context Window | Optional | Model context window; often auto-filled for catalog models |
| Max Tokens | Optional | Maximum output tokens; often auto-filled for catalog models |
| Description | Optional | Model description; often auto-filled |
## Provider Type Guide [#provider-type-guide]
| Provider Type | Use when |
| :---------------- | :----------------------------------------------------------------------- |
| OpenAI | You use the official OpenAI API |
| Anthropic | You use the Anthropic Claude API |
| xAI | You use the xAI Grok API |
| DeepSeek | You use the official DeepSeek API |
| Google | You use the Gemini API |
| Groq | You use the Groq API |
| Moonshot AI | You use Kimi / Moonshot models |
| OpenRouter | You use the OpenRouter API |
| Alibaba | Usually via OpenAI Compatible |
| Z.AI / Zhipu AI | Usually via OpenAI Compatible |
| Ollama | You use a local Ollama service |
| OpenAI Compatible | You use LM Studio, an API proxy, or an institutional compatible endpoint |
## Base URL [#base-url]
Many official providers have a default Base URL. You usually need to edit Base URL only when:
* You use OpenAI Compatible.
* You use an API proxy.
* You use a local model service.
* Your provider requires a custom endpoint.
Examples:
```text
https://api.openai.com/v1
https://openrouter.ai/api/v1
http://localhost:11434
http://localhost:1234/v1
```
Many compatible APIs require a Base URL ending in `/v1`. Missing the version path can cause NetworkError, 404, or model-not-found errors.
## Ollama Example [#ollama-example]
Make sure Ollama is installed and running.
Run `ollama list` in a terminal to confirm a local model is available.
If Ollama is not yet running, start it with `ollama serve`. You should see output confirming it is listening on `127.0.0.1:11434`.
Add a model in BibGenie and choose **Ollama** as Provider Type.
Use `http://localhost:11434` as Base URL.
Use the model name shown by `ollama list`, such as `llama3.1:8b`, as Model ID.
## LM Studio Example [#lm-studio-example]
LM Studio is usually configured through OpenAI Compatible:
Start the local API server in LM Studio.
Add a model in BibGenie and choose **OpenAI Compatible** as Provider Type.
Enter the LM Studio API address as Base URL, usually similar to `http://localhost:1234/v1`.
Enter the ID of the model currently loaded in LM Studio as Model ID.
## Model Types [#model-types]
Select capabilities according to what the model actually supports:
* **Text**: text chat; usually required.
* **Vision**: image, screenshot, and figure input.
* **Reasoning**: useful for complex reasoning tasks.
* **Function Calling**: affects search, reading, and library-management workflows.
* **Web Search**: enable only if the provider and model support it.
Incorrect capability settings can cause `ModelNotSupported` or tool-calling failures.
## FAQ [#faq]
Make sure the model was saved and enabled. If it still does not appear, reopen Model Settings or restart Zotero.
Custom model requests are sent directly from the local Zotero plugin to the provider you configure. See [Bring Your Own Key](/docs/byok) for data-flow details.
Make sure the local service is running, the port is correct, the Base URL is reachable, and no firewall or proxy is blocking the request.
Yes. Your API Key is encrypted and stored only in your local Zotero configuration. It is used directly to make requests to the model provider and will **never** pass through BibGenie's servers.
Click the **Reset** button in the Custom Models area to restore all custom configurations to their initial state. **Warning: this will delete all models you have manually added.**
# Troubleshooting (/docs/error-in-bibgenie)
This page helps you diagnose common BibGenie errors and choose the right next step.
Before troubleshooting, make sure you are using the latest version of BibGenie. Many model, Zotero compatibility, and network issues may already be fixed in a newer release.
Error dialogs often include useful details such as model name, request URL, provider response, and failure reason. Read them carefully before changing settings.
## ModelNotSupported [#modelnotsupported]
A dialog titled "ModelNotSupported".
The selected model does not support the current input type. This often happens when you send an image to a model that does not support vision input.
### How to Fix It [#how-to-fix-it]
Choose a model that supports the required capability, such as Vision for image or screenshot input.
If you are using a custom model and you know it supports images, check that the model is marked as a **Vision** model in Custom Models.
If the task requires tool use, make sure the model supports **Function Calling**.
## AI\_APICallError [#ai_apicallerror]
A dialog titled "AI\_APICallError".
The model API request failed. Common causes include invalid API key, wrong model ID, incorrect Base URL, provider timeout, or network failure.
### Common Error Types [#common-error-types]
Invalid or expired keys may produce messages like:
```text
Unauthorized Failure reason: Authentication Fails
(auth header format should be Bearer sk-...)
```
```text
Incorrect API key provided.
```
Check that the API key is complete, active, and belongs to the provider you selected.
Wrong model IDs may produce messages like:
```text
Model Not Exist
```
Compare the Model ID in BibGenie with the exact model ID shown by the provider.
Incorrect Base URLs may produce request or 404 errors.
Many providers require a Base URL ending in `/v1`. A URL such as `/v/` instead of `/v1/` will fail.
### How to Fix It [#how-to-fix-it-1]
Refresh the official model list in Model Settings. If the issue persists, update BibGenie and contact support with the full error message.
Check Provider Type, Provider ID, Model ID, API Key, and Base URL. Use the Test button in Custom Models to verify the connection.
Make sure Ollama, LM Studio, or your local server is running, the port is correct, and the Base URL is reachable from Zotero's browser environment.
## NetworkError [#networkerror]
An error such as `TypeError: NetworkError when attempting to fetch resource.`
BibGenie could not reach the provider endpoint.
Possible causes:
* Local model server is not running.
* Base URL or port is incorrect.
* Firewall, proxy, or network policy blocks the request.
* The provider endpoint is temporarily unavailable.
* The configured provider does not support browser-side requests in your environment.
## Attachment or Context Issues [#attachment-or-context-issues]
If BibGenie cannot read a PDF, snapshot, note, or selected text:
* Make sure the file exists on this device.
* If you use Zotero sync, verify that the attachment has been downloaded locally.
* For WebDAV users, check that Zotero file sync is working.
* Try opening the attachment directly in Zotero.
* Restart Zotero if the reader state appears stale.
## MCP Connection Issues [#mcp-connection-issues]
If an external MCP client cannot connect:
* Confirm **Enable MCP Server** is on.
* Copy the Server URL again.
* Click **Test Connection** in MCP Settings.
* Make sure Zotero is still running.
* Disconnect clients you do not trust.
## Getting Help [#getting-help]
If the issue persists, send the following information when asking for help:
* BibGenie version
* Zotero version
* Operating system
* Whether you are using an official or custom model
* Provider Type and Model ID
* Full error message
* Whether the issue happens with a specific PDF, note, or context type
You can join the [BibGenie Discord community](https://discord.gg/kDXFAAYDNE) for support.
# Getting Started (/docs/getting-started)
This guide takes you through the fastest path to a working setup: download the plugin, install it in Zotero, open the sidebar, and ask your first question about a paper.
BibGenie supports Zotero 7, Zotero 8, Zotero 9, and Zotero 10. We recommend using a recent Zotero version for the most stable plugin and reader experience.
## Download the Plugin [#download-the-plugin]
Go to the [BibGenie download page](https://www.bibgenie.com/download) and download the latest plugin release.
The downloaded file is usually named:
```text
bibgenie-.xpi
```
where `` is the release number.
## Install BibGenie in Zotero [#install-bibgenie-in-zotero]
Open Zotero and choose **Tools -> Plugins** from the menu bar.
In the Plugin Manager window, click the gear icon in the top-right corner and choose **Install Plugin From File...**.
Select the `bibgenie-.xpi` file you downloaded.
Restart Zotero after installation.
After restarting, open BibGenie from the Zotero toolbar or the Tools menu.
## Open BibGenie [#open-bibgenie]
You can open BibGenie in several ways:
* Click the BibGenie icon in the Zotero toolbar.
* Choose **Tools -> BibGenie** from the menu bar.
* Use the configured keyboard shortcut to show or switch the BibGenie sidebar.
If the shortcut conflicts with Zotero or your operating system, you can change it in [Keyboard Shortcuts](https://www.bibgenie.com/docs/keyboard-shortcuts).
## Sign In [#sign-in]
Free users can start with the core chat and context features. After you sign in, BibGenie can sync your subscription status, credit balance, and official model access.
Includes core research features, paper reading, and external discovery with OpenAlex, Web Search, and Web Extract.
Includes more monthly credits for frequent paper reading, comparison, and research workflows.
## Ask Your First Question [#ask-your-first-question]
A good first task is to start with a PDF paper:
Select a Zotero item that has a PDF attachment.
On first launch, BibGenie uses a built-in model by default. You do not need to configure an API key or manually choose a model before asking your first question.
In the BibGenie input box, type a space followed by `@`, then search for and add the paper. You can also right-click the Zotero item and choose **Add to Chat**.
Ask a concrete question, for example:
```text
Summarize this paper's research question, method, main findings, and limitations.
```
If the answer is useful, click **Save as Note** on the last assistant message to save it as a Zotero note.
When BibGenie answers from traceable sources, it can add citations automatically. Click citation markers to return to the source and verify the answer. To understand how this works across PDFs, notes, snapshots, web pages, and OpenAlex results, read [BibGenie Citation](https://www.bibgenie.com/docs/bibgenie-citations). For PDF-specific jumps back to exact source paragraphs, see [Paragraph Citations](https://www.bibgenie.com/docs/paragraph-citations).
If you want to use your own API key, a local model, or an institutional model service later, read [Bring Your Own Key](https://www.bibgenie.com/docs/byok) and [Custom Models](https://www.bibgenie.com/docs/custom-models).
Strong prompts specify both the goal and the expected format, such as "summarize in five bullet points", "use sections for method, results, and limitations", or "turn this into a literature review note".
## Next Steps [#next-steps]
* Learn how to add richer context: [Add Context](https://www.bibgenie.com/docs/add-context)
* Learn how to edit, retry, fork, and compact conversations: [Conversation Management](https://www.bibgenie.com/docs/conversation-management)
* Understand source tracing: [BibGenie Citation](https://www.bibgenie.com/docs/bibgenie-citations)
* Understand model choices: [Models](https://www.bibgenie.com/docs/models)
* Understand plans and credits: [Pricing & Credits](https://www.bibgenie.com/docs/pricing-credits)
* Create reusable prompts: [Quick Prompts](https://www.bibgenie.com/docs/quick-prompts)
## Updating BibGenie [#updating-bibgenie]
BibGenie checks for updates automatically when Zotero starts. When a new version is detected, an update button appears in the BibGenie menu bar — click it to install the latest release.
You can also enable automatic updates through Zotero's Plugin Manager:
Open Zotero and choose **Tools -> Plugins**.
Select BibGenie in the plugin list.
Set **Allow automatic updates** to On. Zotero will then update BibGenie automatically when new versions are available.
# Overview (/docs)
BibGenie is an AI research agent built directly into Zotero. Instead of acting like a separate web chatbot, it works inside your Zotero workspace with your library, PDFs, web snapshots, notes, and the material you are reading.
Add Zotero items, PDF attachments, snapshots, notes, selected text, page context, images, or screenshots to a conversation, then ask BibGenie to read, explain, search, organize, and preserve your research material.
BibGenie's core experience runs in your Zotero environment. Chat history and many settings are stored locally. When you use a custom or local model, requests are sent directly to the provider you configure.
## Core Workflow [#core-workflow]
Add Zotero items, PDFs, snapshots, notes, selected text, or screenshots so BibGenie understands the material you are working with.
Summarize papers, explain figures, search your library, compare articles, use OpenAlex for public scholarly records, or search the web for public information.
BibGenie adds citations automatically when answers are based on traceable sources, so you can return to PDFs, notes, snapshots, web pages, and OpenAlex results. Learn more in [BibGenie Citation](https://www.bibgenie.com/docs/bibgenie-citations).
Use OpenAlex to find external papers, authors, venues, citation neighbors, and publication trends while keeping them separate from saved Zotero items.
Cross-check paper records across arXiv, Semantic Scholar, OpenAlex, DBLP, and OpenReview, fill missing fields, and upgrade preprints to formal publications safely. Learn more in [Metadata Review](https://www.bibgenie.com/docs/metadata-review).
Save useful answers as Zotero notes, or ask BibGenie to help organize tags, collections, and metadata.
## What You Can Do With BibGenie [#what-you-can-do-with-bibgenie]
* Read papers: summarize research questions, methods, contributions, limitations, and future work.
* Deep-read excerpts: explain selected passages, formulas, figures, or experimental results.
* Check sources: use automatically added [BibGenie Citation](https://www.bibgenie.com/docs/bibgenie-citations) markers to return to PDFs, notes, snapshots, web pages, and OpenAlex results.
* Search your library: find relevant papers by keyword or by describing a research topic in natural language.
* Discover external literature: use OpenAlex to find public scholarly records, citation neighbors, authors, venues, and research trends beyond your Zotero library.
* Review and clean metadata: cross-check papers against arXiv, Semantic Scholar, OpenAlex, DBLP, and OpenReview, upgrade preprints to formal journal or conference entries, and safeguard Better BibTeX citation keys. Learn more in [Metadata Review](https://www.bibgenie.com/docs/metadata-review).
* Organize your library: manage tags, collections, metadata, and item movement.
* Save notes: turn structured AI responses into Zotero notes.
* Manage conversations: edit your latest prompt, retry answers, create branches, and compact older context.
* Connect external tools: expose local Zotero tools through BibGenie's MCP server.
## Recommended Reading Path [#recommended-reading-path]
**First-time setup**: start with [Getting Started](https://www.bibgenie.com/docs/getting-started) to install BibGenie and ask your first question.
**Understand models and credits**: read [Models](https://www.bibgenie.com/docs/models) and [Pricing & Credits](https://www.bibgenie.com/docs/pricing-credits).
**Learn the core features**: continue with [Add Context](https://www.bibgenie.com/docs/add-context), [Conversation Management](https://www.bibgenie.com/docs/conversation-management), [BibGenie Citation](https://www.bibgenie.com/docs/bibgenie-citations), [Literature Search](https://www.bibgenie.com/docs/literature-search), [OpenAlex Research](https://www.bibgenie.com/docs/openalex-research), [Metadata Review](https://www.bibgenie.com/docs/metadata-review), and [Save as Note](https://www.bibgenie.com/docs/save-as-note).
**Advanced setup**: if you have your own API key or a local model, read [Bring Your Own Key](https://www.bibgenie.com/docs/byok) and [Custom Models](https://www.bibgenie.com/docs/custom-models).
## Documentation Sections [#documentation-sections]
Installation, models, pricing, and credits.
Context, prompts, Zotero search, OpenAlex research, metadata review, web access, library management, notes, and MCP.
Custom models, MCP, Add to Chat, shortcuts, citation format, and semantic indexing.
Common errors, model failures, network issues, and Zotero compatibility.
# Keyboard Shortcuts (/docs/keyboard-shortcuts)
BibGenie supports a keyboard shortcut for showing or switching the chat sidebar. You can customize it to match your workflow.
## Change the Shortcut [#change-the-shortcut]
Open BibGenie Preferences.
Find the **Keyboard Shortcuts** section.
Choose a modifier, such as Ctrl + Shift or Command + Shift.
Enter the main key, such as `L`.
Check for conflict warnings and save.
## Conflict Detection [#conflict-detection]
BibGenie checks for conflicts with common Zotero commands. If a conflict is found, the settings page shows the conflicting command.
If the shortcut does not work, possible causes include:
* Conflict with a built-in Zotero shortcut.
* Conflict with an operating-system shortcut.
* Conflict with another Zotero plugin.
* Focus is currently inside an input, modal, or system control.
* Your input method or operating system intercepted the key combination.
## Troubleshooting [#troubleshooting]
Try a different combination, such as Ctrl / Command + Shift + L. Also click the main Zotero window before pressing the shortcut.
That usually means there is a conflict. Choose a less common main key in Keyboard Shortcuts.
Command + Shift is usually the better macOS convention.
# Library Management (/docs/library-management)
BibGenie can do more than read papers. It can help organize your Zotero library by managing tags, creating collections, moving items, and editing metadata.
Library management actions can modify your Zotero library. For batch operations, ask BibGenie to show a plan or preview before applying any changes.
## Supported Organization Tasks [#supported-organization-tasks]
| Task | Examples |
| :------------------------ | :--------------------------------------------------------------- |
| Tag management | Add, remove, and list tags |
| Collection management | Create collections, list collections, move items |
| Metadata editing | Edit title, abstract, publication title, DOI, and related fields |
| Metadata reading | Inspect authors, year, attachments, notes, and tags |
| Literature classification | Group papers by topic, method, year, or project |
If you need to query arXiv, Semantic Scholar, OpenAlex, DBLP, or OpenReview to automatically enrich missing abstracts, DOIs, journal abbreviations, or normalize casing, see the dedicated [Metadata Review & Cleaning](/docs/metadata-review) guide.
## Common Workflows [#common-workflows]
Add `literature-review` or a project tag to selected items.
Create a new collection around a research topic and move relevant papers into it.
Find papers missing DOI, abstract, or publication title.
Group papers into a clearer library structure based on research themes.
## Example Prompts [#example-prompts]
```text
Review the selected papers and propose a collection structure by research topic. Do not modify Zotero yet.
```
```text
Add the tags deep-research and llm-agent to the currently selected papers.
```
```text
Find papers in this collection that are missing a DOI or abstract, and return a table.
```
## Recommended Workflow [#recommended-workflow]
Ask BibGenie to search or list the candidate papers.
Ask for an organization plan, including which items will be modified.
Review the plan.
Explicitly authorize BibGenie to apply the changes.
Ask for a summary of what was changed.
For batch work, specify scope: "only selected items", "only this collection", or "do not edit metadata, only add tags".
## Use Extra Care With [#use-extra-care-with]
* Moving many papers at once.
* Removing tags in bulk.
* Overwriting titles, abstracts, DOI, or other key metadata.
* Creating or reorganizing collections across many items.
For these operations, work in smaller batches and ask BibGenie to list the affected items first.
# Literature Search (/docs/literature-search)
By default, BibGenie searches and reads your Zotero library first instead of going directly to the public web. This keeps responses grounded in the material you have already collected and organized.
When you need papers beyond your saved Zotero items, use [OpenAlex Research](/docs/openalex-research). OpenAlex searches public scholarly metadata such as works, authors, venues, institutions, topics, citation counts, and citation relationships. It does not mean the paper is already in your library.
## Three Search Modes [#three-search-modes]
Best when you know a title, author, year, DOI, tag, collection, or other explicit clue.
Best when you want to describe a research topic, theory, method, or problem in natural language.
Best for listing candidate papers, paging through results, or inspecting items within a defined scope.
## Keyword Search [#keyword-search]
Keyword search works well when you already know part of the target information:
* Words in the paper title
* Author name
* Year
* DOI
* Collection name
* Tag name
* Journal or conference name
Examples:
```text
Find papers in my Zotero library about contrastive learning.
```
```text
Find causal inference papers after 2022 with the tag review.
```
Keyword search is precise and easy to control. The trade-off is that it may miss relevant papers when your wording does not match the metadata.
## Semantic Search [#semantic-search]
Semantic search is designed for conceptual queries. You do not need to guess the exact terms used in titles or abstracts; describe the research topic instead.
Examples:
```text
Find papers that discuss how large language models affect academic writing norms.
```
```text
My project is about how AI tools change researchers' knowledge work. Find related papers.
```
Semantic search uses a local index of Zotero regular item titles and abstracts. Keep in mind:
* It is not PDF full-text search.
* Papers without abstracts may be harder to match.
* The first run may require time to build the semantic index.
See [Semantic Index](/docs/semantic-index) for index status and troubleshooting.
## List Items [#list-items]
List Items is used to display matching papers or continue browsing results.
Example requests:
```text
List the 20 most recent papers in this collection.
```
```text
Show more results.
```
```text
List papers tagged systematic-review and sort them by year.
```
List Items is especially useful when you want BibGenie to show a candidate set first, then decide which PDFs or notes to read next.
## Recommended Workflow [#recommended-workflow]
Use semantic search to find papers related to a broad topic.
Ask BibGenie to list titles, years, authors, and abstracts.
Select a few papers and add them as context.
Ask BibGenie to read PDFs, compare claims, generate a table, or save a note.
## When to Switch to OpenAlex [#when-to-switch-to-openalex]
Use Zotero library search when you want to work with saved items, selected papers, collections, tags, notes, or attached PDFs.
Use OpenAlex when you want to:
* Find papers you have not saved yet.
* Resolve an author, institution, journal, topic, publisher, or funder to a stable OpenAlex ID.
* Explore works that cite a seed paper, works cited by a seed paper, or related works.
* Group public scholarly records by year, source, country, topic, open-access status, or another supported field.
Keep the two result types separate in prompts when needed:
```text
First search my Zotero library for papers about LLM agents, then use OpenAlex to find external papers I may be missing. Keep Zotero results and external OpenAlex results separate.
```
Add year, tag, collection, or result limits to make searches more useful. For example: "only after 2020", "within the Methods collection", or "return at most 10 papers".
# MCP Settings (/docs/mcp-settings)
MCP Settings controls BibGenie's local MCP server. When enabled, external MCP clients can connect to the Server URL and access BibGenie's Zotero tools.
## Controls [#controls]
Starts or stops the local MCP server.
The URL external clients use to connect to BibGenie. It usually looks like `http://127.0.0.1:23119/bibgenie/mcp`, but the port can be different if Zotero uses a custom HTTP server port.
Copies the Server URL to your clipboard.
Sends an MCP initialize request with HTTP POST JSON-RPC to verify that the endpoint is reachable.
Opening the Server URL directly in your browser is not the same as an MCP connection. MCP clients send POST JSON-RPC requests, while the browser address bar sends a GET request. Use **Test Connection** for the real check.
## Status Reference [#status-reference]
| Status | Meaning |
| :------------------ | :----------------------------------------- |
| Server is off | MCP Server is disabled |
| Starting | Server is starting |
| Server running | Server is ready for external clients |
| Testing connection | Connection test is running |
| Connection verified | Test succeeded |
| Connection failed | Test failed; check the URL or server state |
## When Connection Fails [#when-connection-fails]
* Make sure Zotero is running.
* Make sure BibGenie is enabled in Zotero.
* Make sure **Enable MCP Server** is on.
* Copy the displayed Server URL instead of assuming port `23119`.
* Restart Zotero if the server was recently enabled or the plugin was updated.
## Enable MCP [#enable-mcp]
Open BibGenie Preferences.
Find the **MCP Server** section.
Turn on **Enable MCP Server**.
Wait for the Server URL to appear.
Click Copy and paste the URL into your external MCP client.
Click Test Connection to verify it works.
## Disable MCP [#disable-mcp]
When you are not using external clients, turn off **Enable MCP Server**. External clients will no longer be able to access BibGenie's MCP tools.
MCP tools may read or modify your Zotero library. Share the Server URL only with clients you trust.
# MCP (/docs/mcp)
MCP stands for Model Context Protocol. BibGenie can start a local MCP server that lets MCP-compatible clients access Zotero-related tools.
If you only chat inside the BibGenie plugin, you do not need to configure MCP. MCP is mainly for advanced users, external clients, and automated workflows.
## What Can MCP Do? [#what-can-mcp-do]
External clients can use BibGenie's Zotero tools to:
* Search Zotero items
* Run semantic literature search
* Read PDF attachments
* Read snapshots
* Read Zotero notes
* List tags and collections
* Create Zotero notes
* Manage tags and collections
* Get or edit metadata
## What is Zotero MCP? [#what-is-zotero-mcp]
Zotero MCP is BibGenie's local bridge between your Zotero library and external AI clients. Instead of exporting files or manually copying metadata, an MCP-compatible client can ask BibGenie for Zotero context through a local protocol.
For example, an external client can search your library, inspect collections, read a PDF attachment, or create a Zotero note through BibGenie's MCP tools.
## Core Advantages [#core-advantages]
BibGenie's MCP server runs inside the Zotero plugin. You do not need a separate Python service or custom local backend.
The MCP endpoint runs on Zotero's local HTTP server. Your external client talks to Zotero on your own device.
The tools are designed for Zotero workflows: papers, PDFs, collections, tags, notes, snapshots, and metadata.
MCP lets tools such as Cursor, Claude Code, Claude Desktop, and Cherry Studio use Zotero context without leaving their own interface.
## Core Features [#core-features]
| Feature | What it helps with |
| :------------------- | :-------------------------------------------------------------------------------------------------------------------------------- |
| Item search | Find papers by title, author, publication, keyword, or topic. |
| Semantic search | Discover related papers by meaning, not only exact keywords. |
| Metadata access | Read detailed Zotero item metadata before citing, organizing, or editing. |
| PDF reading | Read text from Zotero PDF attachments when the client needs paper content. |
| Visual PDF reading | Render PDF pages as images when figures, tables, or scanned pages need visual inspection. |
| Notes and snapshots | Read Zotero notes and web snapshots from your library. |
| Library organization | List collections and tags, create collections, and manage tags or collection membership. |
| Metadata review | Run read-only `review_metadata` to aggregate arXiv, Semantic Scholar, OpenAlex, DBLP, and OpenReview facts with rule diagnostics. |
| Controlled writing | Create notes or validate and apply metadata updates through `edit_metadata` tool calls. |
## Plugin Chat vs MCP [#plugin-chat-vs-mcp]
| Mode | Best for | Setup required |
| :---------------------- | :--------------------------------------------- | :------------- |
| BibGenie in-plugin chat | Most users | No |
| Local MCP Server | Users connecting Zotero to external AI clients | Yes |
## Server Type and URL [#server-type-and-url]
BibGenie's MCP server uses **Streamable HTTP**. The Server URL usually looks like:
```text
http://127.0.0.1:23119/bibgenie/mcp
```
The port can be different if your Zotero HTTP server uses a custom port. Always copy the Server URL shown in BibGenie settings instead of typing it by hand.
MCP clients connect by sending HTTP POST JSON-RPC requests. Opening the Server URL directly in a browser sends a GET request and is not a reliable MCP connection test. Use **Test Connection** in BibGenie settings or an MCP client instead.
## Enable MCP Server [#enable-mcp-server]
Open BibGenie settings.
Find the **MCP Server** section.
Turn on **Enable MCP Server**.
Copy the displayed Server URL.
Paste the URL into your external MCP client.
Click **Test Connection** to verify it works.
## Connect External Clients [#connect-external-clients]
Use the Server URL from BibGenie settings in clients that support Streamable HTTP MCP.
### Cursor [#cursor]
Cursor can connect directly to BibGenie's Streamable HTTP endpoint.
Open Cursor Settings and go to **Tools & MCP**.
Click **+ New MCP Server**.
Paste this configuration:
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"url": "http://127.0.0.1:23119/bibgenie/mcp"
}
}
}
```
Replace the URL if BibGenie settings show a different port.
Save the configuration. When Cursor shows the MCP server as connected, you can use Zotero context in Cursor chat.
### Claude Code [#claude-code]
Claude Code supports HTTP MCP servers directly:
```bash
claude mcp add ZoteroBibGenie --transport http http://127.0.0.1:23119/bibgenie/mcp
```
Replace the URL if BibGenie settings show a different port.
### Claude Desktop [#claude-desktop]
Some Claude Desktop builds connect to stdio MCP servers more reliably than local HTTP endpoints. In that case, use `mcp-remote` as a small bridge from Claude Desktop to BibGenie's local HTTP server.
Install Node.js if `node` and `npx` are not available on your system.
Open Claude Desktop.
Open **Settings**, then go to the **Developer** section.
Click **Edit Config** to open `claude_desktop_config.json`.
Add this configuration:
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"command": "npx",
"args": ["mcp-remote", "http://127.0.0.1:23119/bibgenie/mcp"]
}
}
}
```
Replace the URL if BibGenie settings show a different port.
Save the file and restart Claude Desktop.
### Cherry Studio [#cherry-studio]
Cherry Studio supports Streamable HTTP MCP directly.
Open Cherry Studio Settings and switch to the **MCP** tab.
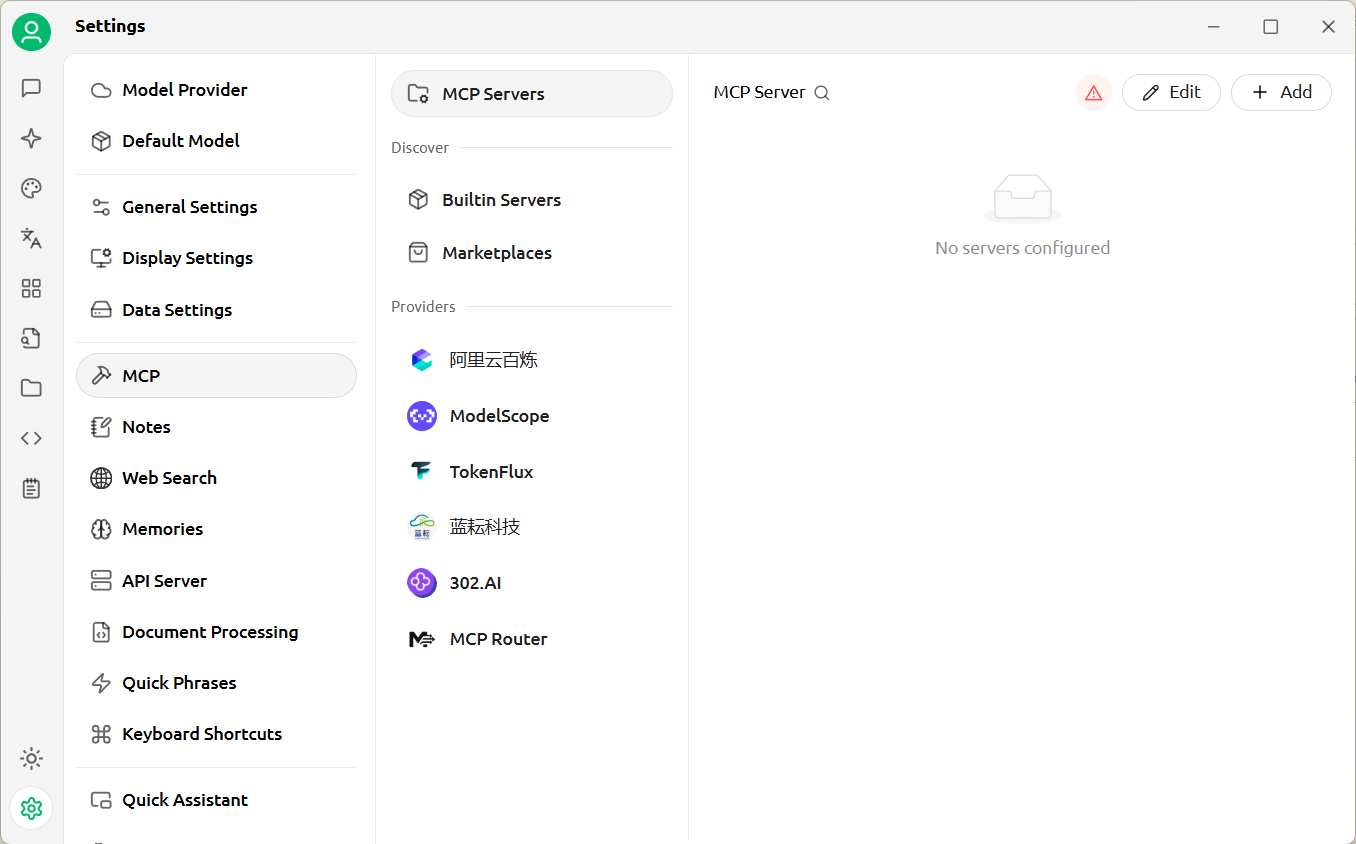
Click **Add** and choose **Quick Create**.
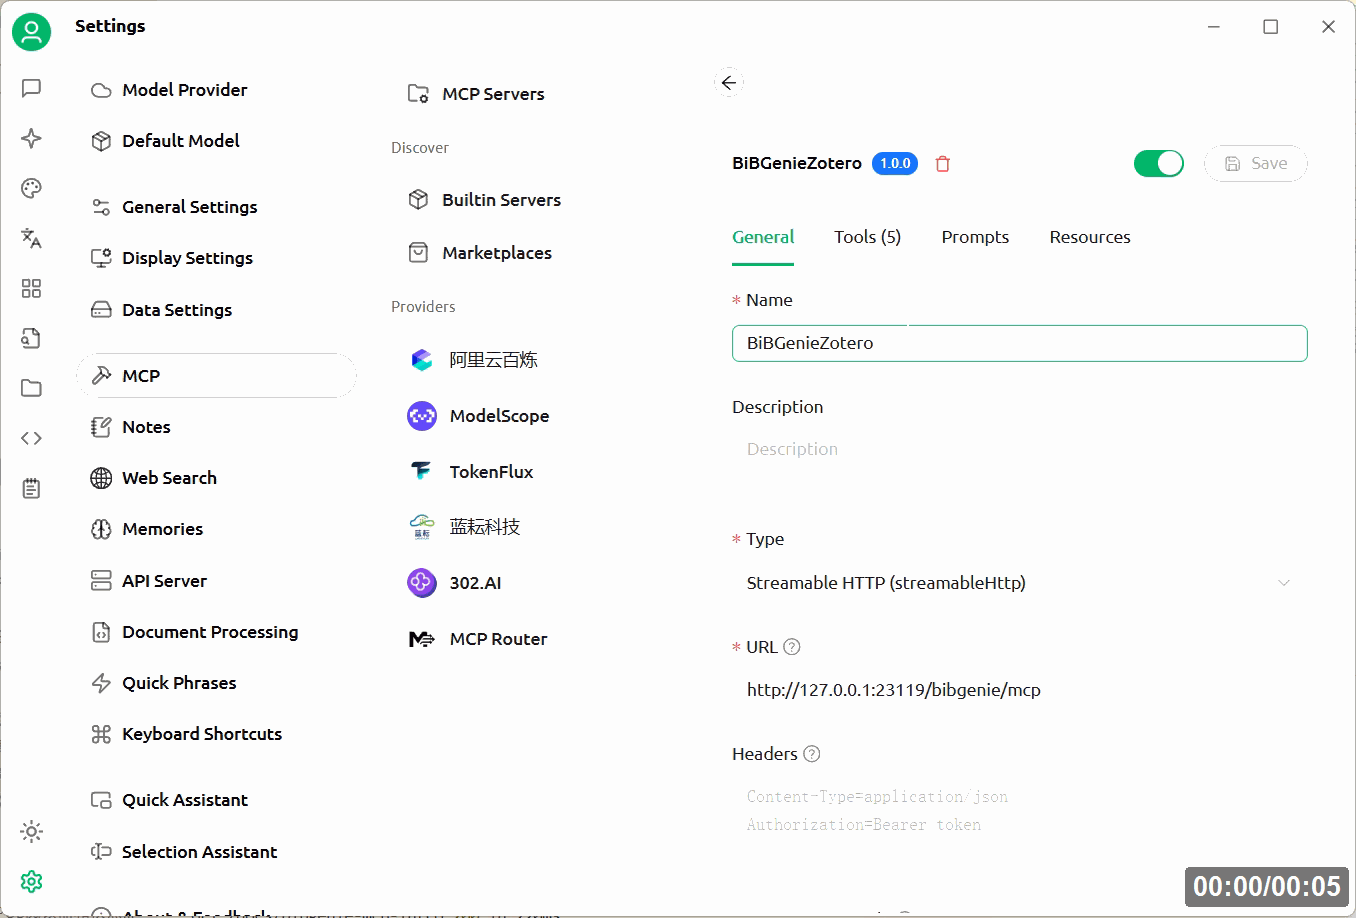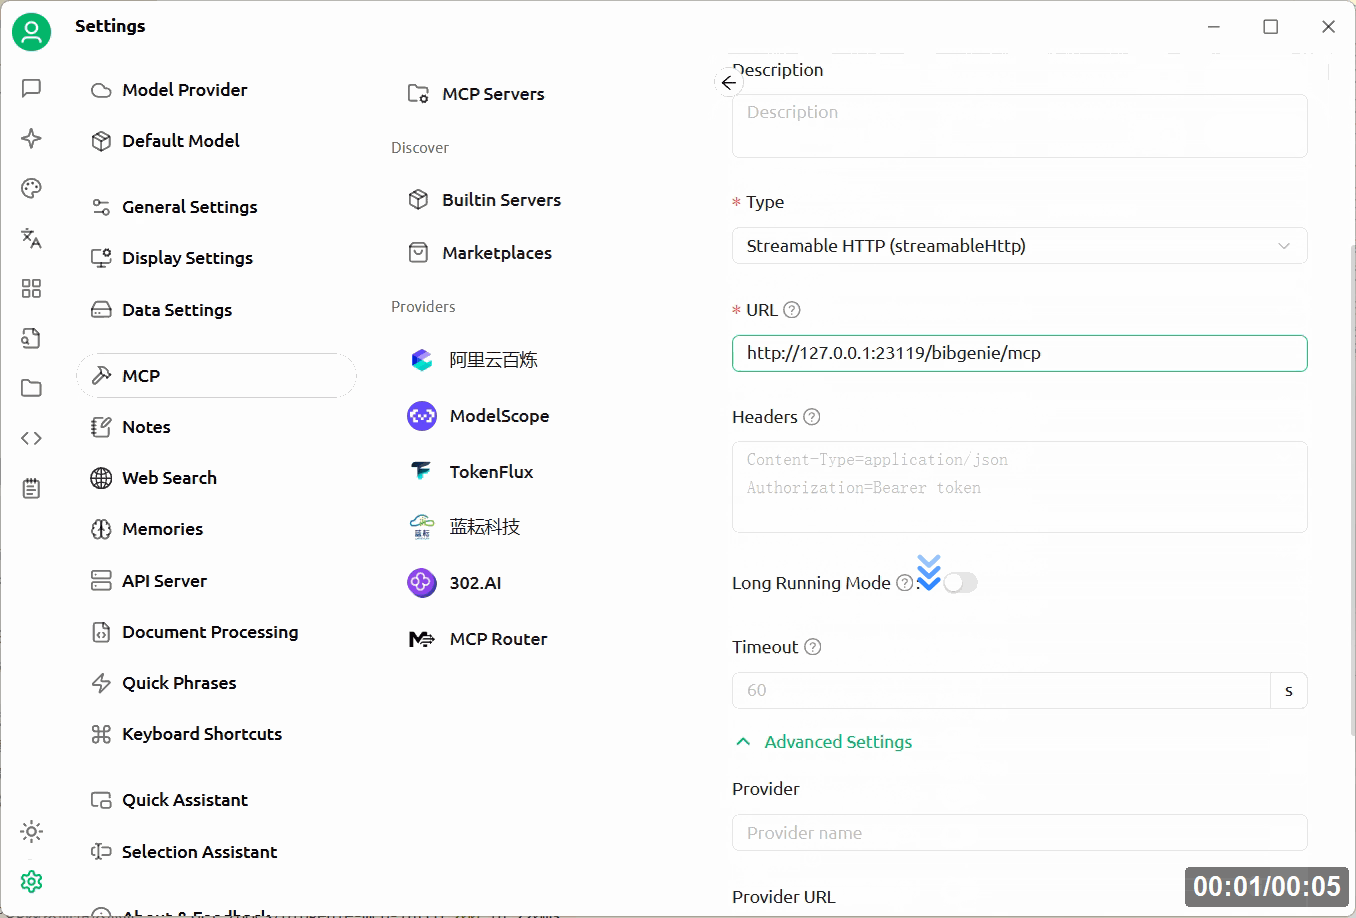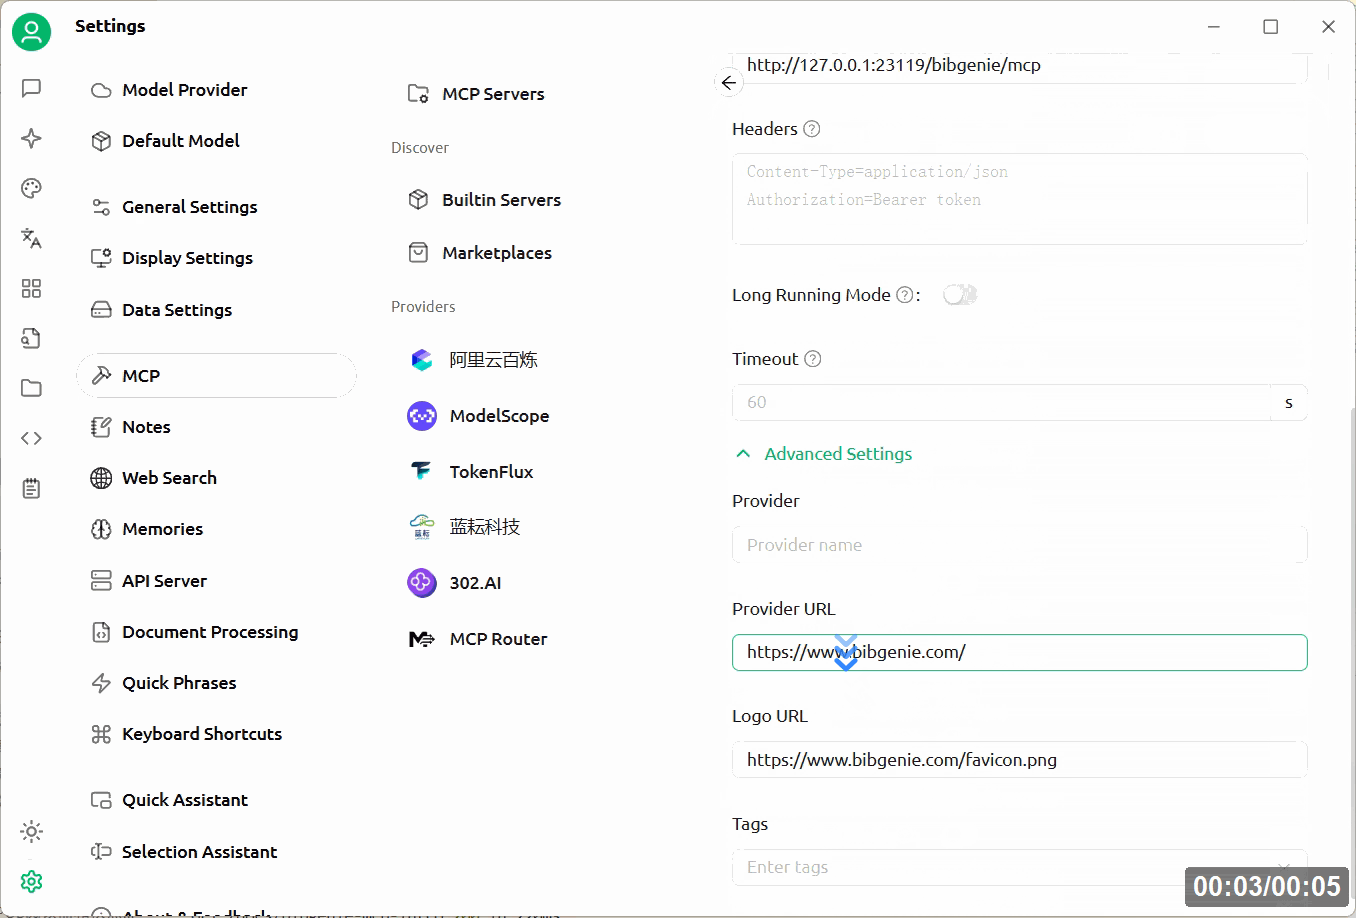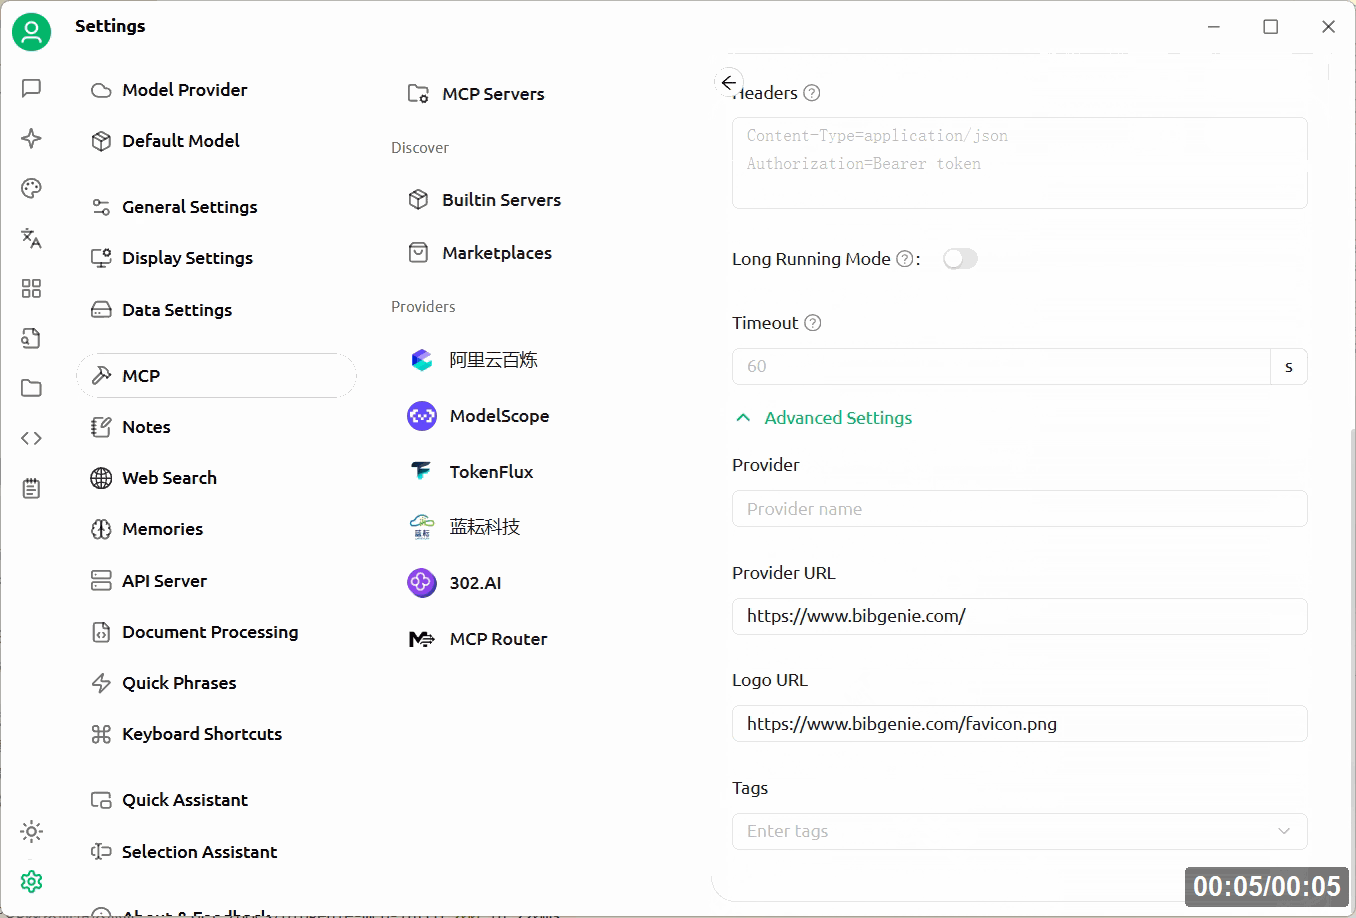
Fill in:
* **Name**: `ZoteroBibGenie`
* **Type**: `Streamable HTTP`
* **URL**: the Server URL copied from BibGenie settings
Optional: open **Advanced Settings** and set:
* **Provider URL**: `https://www.bibgenie.com/`
* **Logo URL**: `https://www.bibgenie.com/favicon.png`
Click **Save**, turn the service on, and use Cherry Studio's verify button to check the connection.
## Example Prompts [#example-prompts]
* "Find Zotero papers about retrieval-augmented generation published after 2023."
* "Read the PDF attachment for this Zotero item and summarize the paper's core contribution."
* "List items in my machine learning collection and find entries missing year metadata."
## Security Recommendations [#security-recommendations]
* Share the MCP Server URL only with clients you trust.
* Be careful with tools that write to your Zotero library, such as creating notes, editing metadata, or managing tags and collections.
* Turn off the server when you are not using MCP.
* If an external client behaves unexpectedly, stop the MCP server and review the client configuration.
## FAQ [#faq]
No. In-plugin chat can use BibGenie's internal capabilities directly. MCP is only for external clients.
No. It is a local service running in your Zotero and BibGenie environment.
Make sure the MCP server is enabled, the URL was copied correctly, Zotero is running, and Test Connection succeeds. If your Zotero HTTP server uses a custom port, the URL may not use `23119`.
No. The browser address bar sends a GET request, while MCP clients use POST JSON-RPC requests. Use Test Connection or configure an MCP client.
Tool lists are loaded by the MCP client. Restart the external client, make sure BibGenie is updated, and reconnect the MCP server. Some clients also cache tool lists until the app restarts.
Yes. The basic Zotero MCP connection provided by **BibGenie** is free. You can use it to connect any client that supports MCP.
# Metadata Review & Cleaning (/docs/metadata-review)
Metadata Review & Cleaning is a core capability of BibGenie. Papers imported from various academic websites, PDFs, or generic web extractors often suffer from incomplete metadata (missing abstracts, DOIs, page numbers, or journal titles), all-uppercase titles, missing journal abbreviations, unlinked preprint updates, and truncated author lists.
BibGenie pairs **large language models' scholarly intelligence** with **multi-source authoritative academic databases**. With a strictly read-only review engine, transparent candidate evidence, and visual diff approvals, you can effortlessly maintain a clean and standardized Zotero library.
The review phase is strictly read-only and never silently modifies your library in the background. The AI generates a **visual diff preview card** comparing current values against proposed changes. Edits are safely written to Zotero only when you explicitly click "Approve".
## Key Capabilities [#key-capabilities]
Aggregates arXiv, Semantic Scholar, OpenAlex, DBLP, and OpenReview, intelligently routing based on DOI, arXiv ID, or DBLP keys.
Choose between `lint` (local formatting), `blank` (fill missing facts, default), and `all` (full refresh and sync).
Unlike rigid regex tools, BibGenie understands academic terms, protecting `mRNA`, `CRISPR-Cas9`, `PyTorch`, and Roman numerals from casing errors.
Visual old-vs-new previews, type-change mapping warnings, Better BibTeX Citation Key retention, and atomic failure rollback.
## Supported Academic Data Sources [#supported-academic-data-sources]
BibGenie integrates specialized academic discovery channels tailored for different disciplines and publication stages:
| Source | Coverage & Highlights | Best For |
| :--------------------- | :---------------------------------------------------- | :-------------------------------------------------------------------------------- |
| **OpenAlex** | 250M+ open scholarly graph across all fields | Comprehensive lookup, missing base metadata, citation contexts |
| **arXiv** | Physics, Computer Science, Math preprint repositories | Preprint metadata, official version identifiers, published DOI links |
| **DBLP** | Computer science bibliography | Top CS conferences/journals, author disambiguation |
| **OpenReview** | Machine learning and AI venues (ICLR, NeurIPS, etc.) | Submission track verification, anonymous author protection, camera-ready tracking |
| **Semantic Scholar** | High-precision CS and biomedicine corpus | Exact paper identifiers, TLDR summaries, citation analysis |
| **Zotero Translators** | Zotero native publisher translators | Direct resolution from publisher landing pages (IEEE, ACM, Springer, Nature) |
## Three Review Modes [#three-review-modes]
Depending on your workflow needs, you can instruct BibGenie to run under different modes:
**Default mode**. Queries authoritative academic sources to **propose updates only for empty local fields and creators**:
* Preserves existing non-empty titles, authors, years, and publication titles without overwriting.
* Fills missing abstracts, page ranges, DOIs, publication titles, or proceedings titles.
* Ideal for the vast majority of everyday library enrichment tasks.
**Local standardization mode**. Skips external fact retrieval and runs built-in scholarly rules to audit and clean existing metadata:
* Sentence case normalization for titles.
* Journal abbreviation standardization using LTWA dictionaries.
* Precise ISO-639-1 language detection.
* Identifies publisher domains misplaced in metadata fields.
* Ideal for items that already have complete data and only need typographical standardization.
**Full synchronization mode**. Queries external sources to **compare and propose updates to existing fields, with full author list replacement**:
* Suited for fixing inaccurate or poorly parsed data from low-quality web imports.
* Great for updating a preprint after it has been officially published in a journal or conference.
* *Note: Do not upgrade to `all` solely because fields are missing; use `blank` for missing field completion.*
## Safety & Ecosystem Compatibility [#safety--ecosystem-compatibility]
1. **Better BibTeX Compatibility**:
* Many researchers rely on Better BibTeX for LaTeX citation keys. BibGenie's Extra field processor strictly preserves `Citation Key:`, `tex.*`, `bibtex:`, and unstructured notes, never stripping or modifying your citation keys.
2. **Item Type Change Safeguards**:
* When proposing an item type conversion (e.g., from `preprint` to `journalArticle`), the approval card provides clear warnings of fields that may be mapped or discarded.
3. **Scholarly Intelligence Over Heuristics**:
* Rigid casing rules often damage technical acronyms, chemical formulas, or library names. BibGenie's LLM context filters out inappropriate heuristic suggestions.
## Example Prompts [#example-prompts]
```text
Please inspect my currently selected paper and use blank mode to fill in any missing abstract, pages, and DOI.
```
```text
Help me standardize the title case and journal abbreviations for these selected items while preserving technical terminology.
```
```text
This paper was previously an arXiv preprint. Please check DBLP or Semantic Scholar to see if it has been published in a peer-reviewed venue, and propose updating the item type and metadata if so.
```
```text
Find items in this collection that lack an abstract or DOI, and review them to fill in the missing details.
```
## Recommended Workflow [#recommended-workflow]
**Select Items**: Highlight one or more items in the Zotero library, and add them to context using `@` or direct instructions.
**Read-Only Review**: BibGenie retrieves multi-source facts and evaluates rules, generating structured proposals.
**Review Visual Diff**: A visual **Action Preview** card appears in the chat, highlighting changes between old and new values.
**Approve and Write**: Click "Approve" to atomically apply the changes to your Zotero items. If rejected, your library remains completely unchanged.
# Models (/docs/models)
BibGenie supports two kinds of models: **official models** and **custom models**.
* Official models are maintained by BibGenie and work out of the box. You do not need to configure your own API key.
* Custom models are configured by you, including the provider, Base URL, API key, and model capabilities.
You can manage both from **Model Settings**.
## Official Models [#official-models]
There are many AI models on the market, but only a small subset works well as a Zotero agent. BibGenie does not choose models based only on public benchmarks. We care about whether they can reliably handle real research workflows:
* Long-context paper reading
* Multi-paper comparison
* Complex research reasoning
* Tool calling and structured output
* Multimodal inputs such as figures, formulas, and screenshots
* Accurate answers grounded in Zotero context
Provider configuration also matters. The same model can behave very differently across providers because of context limits, tool-calling support, rate limits, parameter defaults, and network reliability.
To reduce configuration work for users, BibGenie does several things:
We test a selected set of models on paper reading, literature search, library management, and note-taking workflows.
We discuss recommended deployment and usage patterns with model or provider teams when possible.
We work with selected providers to make sure models are served in a way that works well for BibGenie.
We benchmark model-provider combinations and maintain a recommendation list.
## Custom Models [#custom-models]
If you have your own API key or want to use a local model, you can add a custom model.
Custom models are useful when:
* You already pay for a provider such as OpenAI, Anthropic, DeepSeek, or OpenRouter.
* Your institution requires requests to go directly to a specific provider.
* You want to use Ollama or LM Studio locally.
* You need a model that is not currently included in the official list.
See [Custom Models](/docs/custom-models) for setup instructions.
## What Do the Multipliers Mean? [#what-do-the-multipliers-mean]
You may see labels such as `0x`, `1.5x`, or `2x` after a model name.
These labels indicate the approximate speed at which the model may consume credits:
| Label | Meaning |
| :------------- | :----------------------------------------------------------------------------- |
| `1x` | Standard consumption speed. |
| `1.5x` | May consume credits faster than a standard model for a similar task. |
| `2x` or higher | Usually indicates a higher-cost model, best reserved for more demanding tasks. |
Multipliers are shown as a user-facing hint. Actual credit usage is calculated from input tokens, output tokens, model pricing, and tool usage.
## Refreshing the Model List [#refreshing-the-model-list]
The official model list refreshes automatically. You can also refresh it manually:
Open BibGenie.
Go to **Model Settings**.
Click **Refresh** in the official models section.
If a model is missing, possible reasons include:
* Your plugin version is out of date.
* The model list has not refreshed yet.
* The model is temporarily unavailable or being adjusted.
* Your account status has not synced.
## Choosing a Model [#choosing-a-model]
Start with an official model with a low multiplier.
Use an official model with reliable context handling and strong output quality.
Use a model with stronger reasoning ability and a longer context window.
Use BYOK, a custom provider, Ollama, or LM Studio.
# OpenAlex Academic Search (/docs/openalex-research)
OpenAlex Research is available in BibGenie v0.7.0 and helps you explore the public scholarly catalog beyond your Zotero library. Use it when you want to discover new papers, find authors or institutions, analyze research trends, or map citations around a known work.
OpenAlex results are external bibliographic metadata. They do not mean a paper is already saved in your Zotero library, and they do not replace reading the paper itself.
OpenAlex search is available to all users. On Free, each successful OpenAlex tool call costs **1 credit**; paid plans include these calls at **no additional credit cost**.
## What It Can Do [#what-it-can-do]
Search public scholarly records by topic, exact phrase, DOI, PMID, PMCID, OpenAlex ID, and supported filters or sort fields.
Find stable OpenAlex IDs for authors, institutions, journals, topics, publishers, and funders.
Find works that cite a seed paper, works referenced by a seed paper, or related works.
Group and count results by publication year, open-access status, country, source, topic, or another supported field.
## When to Use OpenAlex [#when-to-use-openalex]
Use OpenAlex when your question is about public scholarly records outside your current Zotero library:
* Find recent papers on a research topic.
* Discover influential earlier work or review papers.
* Follow citations around a DOI or OpenAlex work ID.
* Randomly sample matching records when you want exploratory coverage instead of only relevance or citation-count ranking.
* Compare publication activity by year, source, institution, country, topic, or funding body.
* Identify authors, journals, institutions, publishers, or funders before filtering papers by them.
Use Zotero library search instead when you are asking about saved items, selected papers, collections, tags, notes, or attached PDFs.
OpenAlex can identify papers worth considering, but it does not add them to Zotero automatically. Ask BibGenie explicitly before importing, tagging, moving, or editing any Zotero items.
## How to Ask [#how-to-ask]
```text
Search OpenAlex for recent review papers about retrieval augmented generation after 2023. Return title, year, venue, authors, citation count, DOI, and why each result may be useful.
```
```text
Use OpenAlex to find papers by Geoffrey Hinton about deep learning. Resolve the author first, then list the most cited works with year, venue, DOI, and citation count.
```
```text
Use OpenAlex to explore papers that cite 10.48550/arXiv.1706.03762. Focus on papers after 2021 and explain which ones look most relevant to LLM research.
```
```text
Use OpenAlex to analyze publication trends for graph neural networks from 2018 to 2025. Group by publication year and summarize the trend carefully.
```
## Recommended Workflow [#recommended-workflow]
Start with a broad OpenAlex search using a small result count.
Ask BibGenie to refine by year, work type, open-access status, source, author, institution, or topic.
For a promising seed paper, ask for citation neighbors, references, or related works.
Add only the most relevant candidates to Zotero after you review the results.
## Good Prompt Patterns [#good-prompt-patterns]
```text
Search OpenAlex for papers about AI tools in academic writing. Prefer review articles after 2020 and return at most 10 results.
```
```text
Find the OpenAlex record for this DOI, then show its cited-by papers and related works:
10.1038/nature12373
```
```text
Resolve "Stanford University" in OpenAlex, then find highly cited works about human-computer interaction from that institution since 2020.
```
```text
First search my Zotero library for papers about LLM agents, then use OpenAlex to find external papers I may be missing. Keep Zotero results and external OpenAlex results separate.
```
## Important Limits [#important-limits]
* OpenAlex provides metadata such as title, authors, year, venue, DOI, open-access status, and citation count.
* Do not treat citation count as proof of quality.
* Do not infer a paper's methods, claims, or findings from metadata alone.
* For close reading, add the paper to Zotero or provide readable full text, then ask BibGenie to read the source content.
# Paragraph-Level Citations (/docs/paragraph-citations)
When you are reading research papers, an answer that "looks right" is not enough. A reliable AI reading assistant has to answer a stricter question:
**Where exactly did this statement come from in the paper?**
That is what BibGenie's paragraph-level citations are built for. They trace key claims in AI answers back to specific text blocks in the PDF. Click a citation marker in the answer, and BibGenie takes you back to Zotero PDF Reader with the matching passage highlighted in the original text.
This is not about making answers look more "academic." The real value is that every key judgment made by the AI can be checked, reread, and confirmed by you.
Paragraph-level citations turn AI answers from "here is the conclusion" into "here is the evidence" - click a citation marker to jump directly to the matching paragraph in the PDF.
## How Paragraph-Level Citations Differ From Regular Citations [#how-paragraph-level-citations-differ-from-regular-citations]
Different citation granularity gives you very different ways to judge an answer:
| Citation granularity | What you can know | Best for | Enough for close reading? |
| :--------------------------- | :----------------------------------------------- | :------------------------------------------------------------------- | :-------------------------------------------------- |
| Paper-level citation | Which paper the answer roughly comes from | Skimming, building reference lists, quickly understanding background | Too broad; you only know the source |
| Page-level citation | Which PDF page the answer roughly comes from | Quickly locating the overall page content | Still broad; one page contains too much information |
| **Paragraph-level citation** | **Which original text block the answer maps to** | **Close reading, fact-checking, writing notes, literature reviews** | **Yes; you can inspect the evidence directly** |
Paper-level citations tell you the source. Page-level citations help you find the page. **Paragraph-level citations let you inspect the evidence directly**.
BibGenie is not just trying to tell you "this paper supports the answer." It helps you see, with your own eyes, "this passage supports the answer." For researchers, the second is much more important than the first. You do not need a ready-made conclusion as much as you need enough evidence to judge whether the conclusion holds up.
## From Answers to Evidence [#from-answers-to-evidence]
In the past, using AI to read papers usually meant asking the AI to summarize something.
That is useful, of course. You can quickly understand a paper's general topic, methods, and conclusions. But in serious literature work, the time-consuming part is rarely "getting the gist." It is making judgments like these:
* Did the authors actually state this conclusion?
* Did the AI merge the meaning of different paragraphs too aggressively?
* Are details such as experimental results, variable definitions, and evaluation metrics accurate?
* Is this sentence a core claim from the authors, or is it the AI's own summary?
* Can this point safely go into your notes, review, or draft?
If the AI only gives you a fluent answer, you still have to go back to the PDF, search, flip pages, locate the passage, and reread. That breaks your flow, and it can make verification feel easy to skip.
Paragraph-level citations remove that extra step.
When BibGenie answers from PDF text, it automatically embeds citation markers such as `[1]` and `[2]` in the answer. Click a marker, and BibGenie opens the corresponding PDF, jumps to the relevant page, and highlights the cited paragraph in the original text.
In other words, BibGenie does not only tell you "what the answer is." It puts "where the answer came from" back into your reading environment.
## Why Paragraph-Level Citations Matter [#why-paragraph-level-citations-matter]
Academic reading is not browsing the news. You need more than a conclusion; you need to understand how the paper supports that conclusion.
That is why more AI research and AI products now emphasize source attribution, grounded answers, and citation verification. AI can generate explanations that look true, and it can also generate citations that look true. But "looks true" is not the same as "can be verified."
In literature work, reliable citations need to satisfy three conditions:
1. **Real source**: the citation must not be a fabricated paper record.
2. **Clear location**: the citation must point to the specific evidence location, not only to an entire paper.
3. **Matching content**: the cited text must actually support what the AI just said.
You often need to judge:
* Did the authors really say this?
* Did the AI mix together different paragraphs, experiments, or even different papers?
* Do the method details come from the main text, a figure caption, an appendix, or the AI's own summary?
* Can this sentence safely go into your notes or draft?
* Is this citation only "related-looking," or does it actually support the specific claim in the answer?
Traditional AI citations usually tell you only "which paper was referenced" or "which page this came from." That can be enough for skimming, but it is far from enough for close reading. A single PDF page can contain the research question, method, formulas, experimental setup, result interpretation, and limitations all at once. Page-level citations can only tell you "it is somewhere on this page." Paragraph-level citations narrow the evidence down to the place you actually need to check.
## Why Not Just Page Numbers? [#why-not-just-page-numbers]
Many AI literature tools provide page numbers. Page numbers are useful, but they are not the finish line.
An academic PDF page can be extremely dense. In double-column papers, review articles, methods papers, and medical or engineering experiment papers, one page may contain:
* Two or three separate paragraphs
* A table or figure caption
* Multiple formulas
* Experimental setup, evaluation metrics, and result interpretation
* Author caveats about limitations
If the AI says "the authors argue that this method improves generalization" and only tells you "see page 6," you still have to figure out whether it is pointing to the results paragraph, the ablation study, or the explanation in the Discussion section.
Paragraph-level citations are not meant to replace page numbers. They go one step further: they show you the small piece of evidence the AI used. This is especially helpful when the same page contains several possible sources of evidence.
## Why Not Make Citations Even More Fine-Grained? [#why-not-make-citations-even-more-fine-grained]
You might think the finer the citation, the better. Ideally, every sentence and every claim would be located exactly. But in real literature reading, evidence is rarely a single isolated sentence. Authors often define a concept, describe the experimental setup, and then explain the result in the next sentence. Pulling out one sentence alone can remove necessary context.
Paragraph-level citation is a natural compromise:
* More precise than an entire paper
* Easier to verify than a whole PDF page
* More context-preserving than a sentence-level citation
* Less noisy than citing several paragraphs at once
It also matches how researchers actually read papers. You do not stare at one sentence in isolation. You read a short passage, understand the surrounding qualifications, and then decide whether it supports a point.
## What It Helps You Do [#what-it-helps-you-do]
Click a citation marker in an answer to return directly to the original Zotero PDF location. No more manual page-flipping, keyword searching, or guessing which passage the AI used.
When AI summarizes methods, results, or research limitations, you can immediately check the original text and judge whether the answer is faithful to the paper.
For theoretical definitions, experimental settings, variable explanations, figure conclusions, and author caveats, paragraph-level citations fit the way researchers actually verify claims better than page numbers do.
Answers, citation markers, PDF pages, and original highlights stay connected, so your follow-up questions, notes, and judgments all have clear sources.
## Common Use Cases [#common-use-cases]
When reading one paper carefully, you can ask BibGenie to organize the research question, method, experimental design, main findings, and limitations. Previously, you might get a complete summary but still have to find the evidence one point at a time. Now the answer includes clickable citations, so you can check each point against the original text.
```text
Read this paper closely and summarize it by problem, method, experiments, main findings, and limitations.
```
AI is good at turning complex material into fluent prose, but fluency can hide problems. For example, a paper may only say that a method performs better on one dataset, while AI summarizes it as "the method outperforms existing methods overall." A paper may say the authors observed a trend, while AI writes that the authors proved a mechanism. Paragraph-level citations let you quickly return to the original text and check whether the AI's wording goes beyond what the authors actually claimed.
```text
List the 5 conclusions in this paper that are easiest to misread or overgeneralize.
```
Good literature notes record not only "what this paper says," but also "why I understand it this way." Paragraph-level citations help connect AI-generated structured notes to the original evidence. When you revisit your notes later, you can jump back to the PDF paragraph you relied on instead of searching through the whole paper again.
```text
Turn this paper into a Zotero note draft, keeping the research question, method, findings, and limitations.
```
Literature reviews are most vulnerable to two problems: inaccurate citations and unclear origins of claims. When you compare multiple papers, paragraph-level citations give each comparison point a source: how paper A defines the problem, what dataset paper B uses, what limitation paper C reports. Each point can jump back to the original text, making it easier to distinguish what the authors said, what AI summarized, and what you concluded.
```text
Compare these papers by research question, method assumptions, experimental setup, and limitations.
```
Method and experiment details leave little room for ambiguity. Dataset size, baselines, evaluation metrics, hyperparameters, exclusion criteria, statistical tests, ablation studies - misreading any one of these can distort everything that follows. Paragraph-level citations let you jump quickly to the passages that contain these details and check whether the AI missed any important qualifications.
```text
Extract the experimental setup of this paper, including datasets, baselines, evaluation metrics, and main comparison results.
```
## How It Works [#how-it-works]
When BibGenie reads a PDF, it parses pages into structured text blocks. Each text block keeps its page number, reading order, and position on the page.
When the AI cites a text block in an answer, BibGenie renders it as a citation marker such as `[1]` or `[2]`. After you click the marker, BibGenie will:
1. Open the corresponding Zotero PDF.
2. Jump to the page that contains the citation.
3. Highlight the cited paragraph or text block in the original text.
What you see is not "this paper supports the answer," but "this passage supports the answer."
## Close Reading With Evidence [#close-reading-with-evidence]
Paragraph-level citations help you build an evidence-checking habit for AI-assisted close reading:
**Add PDF context**: Add the PDF attachment from Zotero to the BibGenie conversation, or ask questions directly around the PDF you are currently reading.
**Ask a reading question**: For example, ask BibGenie to summarize the method, explain the experimental design, organize the limitations, or compare differences across papers.
**Scan the answer structure**: First look at the overall structure from the AI and decide whether it has captured the main thread of the paper.
**Click citations to check the original text**: For any conclusion you plan to use, click the citation marker to return to the Zotero PDF and check whether the highlighted passage really supports it.
**Follow up or revise**: If you find that the AI overgeneralized or missed a qualification, ask a follow-up such as "Please rephrase this based on the cited passage."
The point of this workflow is not to make AI read the paper for you. It is to help you reach a verifiable close-reading state faster.
## Limits and Notes [#limits-and-notes]
Paragraph-level citations make answers much more traceable, but they are not magic proof that an answer is correct. Keep these points in mind:
* **A relevant citation location does not guarantee a correct interpretation**: AI may find a relevant paragraph but still misunderstand it.
* **The highlight range is for locating evidence, not final citation formatting**: For formal writing, still format citations according to APA, MLA, Chicago, GB/T 7714, or your target journal's requirements.
* **PDF text-layer quality affects results**: Scanned files, poor OCR, complex layouts, or formula-heavy pages can affect text block parsing and positioning accuracy.
* **Figures and formulas require visual reading**: If a question depends on figures, scanned pages, or visual layout, consider adding a screenshot or page image as well.
* **AI does not replace your academic judgment**: Paragraph-level citations make checking easier, but final judgment should still be based on the original text, the study design, and your own expertise.
Let BibGenie narrow the evidence range for you, then decide for yourself whether the original passage truly supports the conclusion.
## Tips [#tips]
* Build the habit of clicking citations to check important conclusions, data, experimental settings, and author claims against the original text.
* If the AI's wording is too broad, ask "Please rephrase this based on the cited original text."
* For scanned PDFs or PDFs with poor text layers, citation positioning may be less accurate. Consider adding page images as well.
* For formal writing, treat AI answers as reading assistance and use the original paper as the final authority.
* When comparing multiple papers, verify the evidence in each individual paper before relying on BibGenie's synthesis.
* When you encounter an unfamiliar term, click the citation and read the original text first, then ask BibGenie to explain the context.
* When an answer involves causality, mechanism explanations, or statistical conclusions, always return to the cited paragraph and confirm whether the authors really phrased it that way.
Citation markers in AI answers are easy to treat as "trust badges." When people see `[1]` or `[2]`, they naturally feel that the sentence has already been backed by evidence.
A better habit is to treat each citation as an entry point.
Open it, return to the original text, and check three things:
1. Whether the original text really discusses this issue.
2. The tone of the original text - is it a strong conclusion, a weak observation, or a hypothetical discussion?
3. Whether the AI summary omitted conditions, scope, or counterexamples.
This step only takes a few extra seconds, but it greatly reduces the risk of "reading" something without actually verifying it. Especially when you write reviews, prepare research presentations, or organize research hypotheses, this kind of checking directly affects the reliability of the work that follows.
# Pricing & Credits (/docs/pricing-credits)
BibGenie uses credits to meter official model usage. Credits are not the same as request counts: the cost of a request depends on the model, context length, output length, and tool usage.
All plans can use OpenAlex, Web Search, and Web Extract. Free charges 1 credit per successful external tool call; paid plans include those calls at no additional credit cost and provide more monthly credits. Max provides the highest monthly credits for heavy reading, comparison, and review workflows.
## Plan Comparison [#plan-comparison]
| Plan | Price | Monthly credits | Main capabilities |
| :---------- | :------------ | :--------------------- | :------------------------------------------------------------------------------------ |
| Free | $0 | 200 credits / month | Core features + OpenAlex, Web Search, and Web Extract at 1 credit per successful call |
| Pro Monthly | $9.99 / month | 10,000 credits / month | Everything in Free + no additional credit charge for external tool calls |
| Pro Yearly | $99 / year | 10,000 credits / month | Everything in Pro Monthly |
| Max Monthly | $30 / month | 35,000 credits / month | Everything in Pro + more room for deep reading, comparison, and review generation |
| Max Yearly | $295 / year | 35,000 credits / month | Everything in Max Monthly |
| Lifetime | $199 one-time | 10,000 credits / month | Long-term Pro benefits |
Prices, discounts, and promotions may change. The final price is the one shown on the Pricing page and in Stripe Checkout.
## Credit Booster [#credit-booster]
Free and paid users can buy an additional credit package:
| Package | Amount | Price | Expiration |
| :------ | :------------ | :---- | :--------- |
| Booster | 5,000 credits | $6.99 | 6 months |
## How Credits Are Consumed [#how-credits-are-consumed]
Credit usage is mainly affected by:
* Model choice: higher-cost models usually consume credits faster.
* Input length: PDFs, notes, snapshots, images, and chat history increase input tokens.
* Output length: long reviews, long tables, and full notes use more tokens.
* Tool usage: search, attachment reading, web search, and web extraction may involve multiple model calls.
* **External tools**: on Free, each successful OpenAlex, Web Search, or Web Extract call costs **1 credit**. Paid plans include these calls at **no additional credit cost**. Model usage in the surrounding conversation is metered separately.
* Model multiplier: labels such as `1.5x` or `2x` provide an approximate usage hint.
Custom models, Ollama, and LM Studio do not use BibGenie's official model service, so they do not consume BibGenie credits. Any cost or compute usage is handled by your provider or your local machine.
## How Many Credits Does Reading a Paper Use? [#how-many-credits-does-reading-a-paper-use]
There is no fixed amount. Credit usage depends on the selected model, input context, output length, and current model pricing. Check the Usage page for the exact charge recorded for each request.
## What Happens When Credits Run Out? [#what-happens-when-credits-run-out]
If your credit balance is insufficient, official model requests may not continue. You can:
* Wait for the next monthly refresh.
* Upgrade to Pro, Max, or Lifetime.
* Buy a Credit Booster.
* Use BYOK or a local model.
## Checking Your Balance [#checking-your-balance]
After signing in, BibGenie syncs your account status and credit balance. You can also check your balance from the website account area or the plugin user page.
# Quick Prompts (/docs/quick-prompts)
Quick Prompts are reusable shortcuts for recurring research tasks. Save prompts you use often, insert them quickly into the input box, and adapt them to the current context.
## What Are Quick Prompts Good For? [#what-are-quick-prompts-good-for]
Summarize research questions, methods, contributions, limitations, and future work.
Translate selected text, polish English paragraphs, or adjust academic tone.
Extract claims, generate comparison tables, and organize related work.
Analyze assumptions, methodological weaknesses, evidence strength, and reproducibility.
## Create a Quick Prompt [#create-a-quick-prompt]
Open BibGenie and go to **Prompts Settings**.
Click the add button to create a new quick prompt.
Enter a name, prompt content, description, and tags.
Use the toggle to control whether it appears on the chat page.
Save your settings and return to chat.
## Use a Quick Prompt [#use-a-quick-prompt]
On the chat page, click a Quick Prompt or search for it from the prompt menu. Once inserted, it becomes part of the current input, so you can continue editing it, add context, or specify an output format.
Example:
```text
Based on the paper I added, please use the following structure:
1. Research question
2. Method and data
3. Core findings
4. Limitations
5. How I might cite this paper
```
## Quick Prompts vs Custom Instructions [#quick-prompts-vs-custom-instructions]
| Type | Scope | Best for |
| :------------------ | :------------------------------- | :---------------------------------------------------------------------------- |
| Quick Prompts | The current input | Task templates such as summarization, translation, comparison, and extraction |
| Custom Instructions | Longer-term behavior preferences | Response language, tone, role, and formatting preferences |
Put stable personal preferences in Custom Instructions and task-specific workflows in Quick Prompts.
## System Prompt [#system-prompt]
System Prompts guide the AI's overall behavior across all conversations. Unlike Quick Prompts (which apply to the current input), a System Prompt takes effect **globally** — every conversation follows the same instruction.
For example, setting the system prompt to:
```text
Always respond in English. Use academic writing conventions appropriate for computer science.
```
means every response will follow this instruction without you needing to repeat it.
You can set one System Prompt in **Prompts Settings**. The default is `Always respond in English.` You can change it to match your preferred response language, tone, role, or formatting style.
## Quick Prompt Configuration [#quick-prompt-configuration]
Each Quick Prompt has the following fields:
Required. When enabled, this name is displayed as a button above the chat input box.
Required. The text that will be sent to the AI model as context.
Optional. Describes the purpose of the prompt, shown on hover.
Optional. Used for categorization and filtering when managing many prompts.
## Example Templates [#example-templates]
```text
Read the paper I added and summarize it using this structure:
- Research question
- Core hypothesis
- Method and data
- Main findings
- Limitations
- Relevance to my current research
```
```text
Explain the selected text I added:
- What is the passage saying?
- What are the key concepts?
- How does it relate to the paper's main argument?
- What should I be careful about if I cite it?
```
```text
Extract material from these papers for a literature review:
- Core claim of each paper
- Agreements and disagreements between papers
- Themes that can be synthesized
- Remaining research gaps
```
# Save as Note (/docs/save-as-note)
Save as Note turns useful BibGenie responses into Zotero notes that you can keep, search, and reuse in your research workflow.
## Two Ways to Save [#two-ways-to-save]
Tell BibGenie: "Save the summary above as a note for this paper."
Click **Save as Note** on the last assistant message to save the latest response.
## Supported Content [#supported-content]
BibGenie converts Markdown / HTML content into Zotero notes. Common supported content includes:
* Headings and paragraphs
* Ordered and unordered lists
* Mathematical formulas
* Code blocks
* Tables
* Citations and links
* Bold text and inline code
Zotero notes have their own editor and HTML support. Most common formats work well, but very complex Markdown or custom HTML may be simplified.
## Parent Item Logic [#parent-item-logic]
When saving a note, BibGenie places it in the most appropriate location it can determine.
| Input | Result |
| :----------------------------------- | :-------------------------------------------------------------------------------------------------------- |
| Regular item specified | Creates a child note under that item |
| PDF attachment specified | Finds the attachment's regular parent item when possible and attaches the note there |
| Child note specified | Finds the child note's regular parent item when possible and attaches the note there |
| No parent specified | Creates a standalone note |
| Parent and collection both specified | The collection is ignored because Zotero child notes inherit collection membership from their parent item |
## Examples [#examples]
```text
Save the paper summary above as a Zotero note for this item, titled "Paper Summary".
```
```text
Turn the comparison above into a literature review note and save it to Zotero.
```
```text
Convert the method section into reproducible experimental steps and save it as a note. Preserve code blocks and tables.
```
## Tips [#tips]
* Ask BibGenie to structure the response before saving it.
* For long conversations, first ask BibGenie to "rewrite this as a note", then save.
* If the note should belong to a specific paper, name the target item explicitly.
* If you want a standalone note, say that it should not be attached to a paper.
# Semantic Index (/docs/semantic-index)
Semantic Index powers BibGenie's semantic literature search. It indexes Zotero regular-item titles and abstracts locally, so you can describe a research topic in natural language instead of relying only on keywords.
## What Does It Index? [#what-does-it-index]
The semantic index currently focuses on Zotero regular items:
* Title
* Abstract
* Selected metadata useful for search
Semantic Search is not the same as PDF full-text search. If a paper has no abstract or incomplete metadata, semantic matching may be less accurate.
## Status Reference [#status-reference]
| Status | Meaning |
| :------------ | :--------------------------------------- |
| bootstrapping | Indexing capability is initializing |
| indexing | The index is being built |
| updating | Existing index entries are being updated |
| idle | The index is ready |
| error | An indexing error occurred |
## Metrics [#metrics]
| Metric | Meaning |
| :------------ | :----------------------------------- |
| Indexed Count | Number of items successfully indexed |
| Failed Count | Number of items that failed indexing |
| Message | Current status or error message |
## When to Check Semantic Index [#when-to-check-semantic-index]
* Semantic search returns very few results.
* BibGenie reports that the semantic index is unavailable.
* Newly imported papers do not appear in semantic search.
* Failed Count keeps increasing.
* Zotero just started and the index is still bootstrapping or indexing.
## Troubleshooting [#troubleshooting]
Open Preferences and check the Semantic Index status.
If it is indexing or updating, wait for it to finish.
If there are failed items, retry failed indexing.
Check whether the relevant papers have titles and abstracts.
If failures continue, restart Zotero and check again.
## Tips [#tips]
* Complete abstracts improve semantic search quality.
* Use natural language descriptions instead of only keywords.
* Combine semantic search with year, tag, or collection filters.
* After finding candidate papers, add the PDFs or notes as context for deep reading.
# How BibGenie Understands Your Library (/docs/semantic-understanding)
## Why this page exists [#why-this-page-exists]
When you search in BibGenie, the goal is not only to find papers that contain the exact same words you typed. In many cases, you want BibGenie to find papers that are **about the same idea**, even if they use different terminology.
That is where **embeddings** and **indexing** come in.
## What is an embedding? [#what-is-an-embedding]
An embedding is a way to turn a piece of text into a numeric representation that captures its meaning.
You do not need to think about the math behind it. The practical idea is simple:
* Similar text tends to produce similar embeddings
* Different topics tend to produce more distant embeddings
* This lets BibGenie compare meaning, not only exact wording
For example, a paper about *drug discovery with knowledge graphs* may still be found when you search for *graph methods for biomedical research*, even if the wording is not identical.
## How BibGenie uses embeddings [#how-bibgenie-uses-embeddings]
BibGenie currently builds semantic search from the **title** and **abstract** of your regular Zotero items.
The process is:
1. BibGenie reads the title and abstract of a paper.
2. It converts that text into an embedding.
3. It stores the result in a local search index for your Zotero library.
4. When you ask a topic-style question, BibGenie converts your query into an embedding too.
5. It compares your query with the indexed papers and returns the closest matches.
This is why semantic search can surface papers that are relevant in meaning, not only in wording.
## What is indexing? [#what-is-indexing]
Indexing is the preparation step that makes semantic search fast and practical.
Instead of recomputing everything every time you search, BibGenie first prepares a local index of embeddings for your library. Once that index exists, BibGenie can search across your papers much more efficiently.
In short:
* **Embedding** helps BibGenie represent meaning
* **Indexing** helps BibGenie search that meaning quickly
## What does this help with? [#what-does-this-help-with]
Semantic indexing is especially useful when you want to:
* Find papers related to a research topic
* Discover work that uses different wording for a similar idea
* Explore a method, theory, or problem area
* Search a large Zotero library more naturally
Keyword search is still useful when you know the exact author, title, term, or phrase. Semantic search is more helpful when your question is conceptual.
## What content is included? [#what-content-is-included]
BibGenie currently uses:
* Paper titles
* Paper abstracts
BibGenie does **not** currently build this semantic index from:
* PDF full text
* Notes
* Annotations
* Attachments
This helps keep indexing focused, predictable, and fast.
## Do I need to rebuild the index often? [#do-i-need-to-rebuild-the-index-often]
Usually, **no**.
Most of the time, BibGenie handles indexing updates automatically in the background as your library changes. If you add papers, modify records, or remove items, BibGenie will usually take care of the necessary updates for you.
You may want to rebuild the index in a few situations:
* The first time you set up semantic indexing
* After switching to a different embedding model
* After a large import, if results seem incomplete or outdated
* If BibGenie tells you the current index needs attention
* If semantic results look clearly wrong and you want a clean rebuild
If semantic search is working normally, you usually do not need to do anything. Rebuild only when the app suggests it, or when results no longer match your expectations.
## What do the buttons mean on the Indexing page? [#what-do-the-buttons-mean-on-the-indexing-page]
### Build / Rebuild [#build--rebuild]
This creates the index for the first time, or rebuilds it from scratch when needed.
Use it when:
* You are setting up indexing for the first time
* You changed embedding models
* You want to refresh the entire index
### Retry Failed Items [#retry-failed-items]
This only retries papers that failed during previous indexing attempts.
Use it when:
* The failed item count is greater than zero
* You want a lighter recovery step before trying a full rebuild
## Common questions [#common-questions]
Keyword search looks for matching words. Semantic search looks for related meaning. Because of that, semantic search can return papers that are relevant even when the wording is different.
Without embeddings, BibGenie would mostly depend on exact terms. Embeddings make it possible to search by topic, concept, and semantic similarity.
A paper may not have been indexed yet, may not contain enough title/abstract content, or the index may need attention. If the issue persists, try rebuilding the index.
No. In normal use, BibGenie is designed to update the index automatically. Manual rebuild is mainly for first setup, model changes, and recovery scenarios.
## Next Steps [#next-steps]
* Check index status and troubleshoot issues: [Semantic Index](/docs/semantic-index)
* Learn how to use semantic search in practice: [Literature Search](/docs/literature-search)
# Web Search & Web Extract (/docs/web-search-extract)
By default, BibGenie searches and reads your Zotero library first. Web Search / Web Extract are available to all users and let BibGenie supplement your library with information from the public web.
On Free, each successful Web Search or Web Extract call costs **1 credit**. Paid plans include these external tool calls at **no additional credit cost**. Model usage in the surrounding conversation may still consume credits normally.
## Web Search vs Web Extract [#web-search-vs-web-extract]
Searches the public web and returns ranked, AI-readable excerpts.
Reads a specific web page and extracts its main content for the conversation.
## When to Use Web Access [#when-to-use-web-access]
Web Search / Web Extract is useful when you need to:
* Find a paper's project page, code repository, or dataset page.
* Gather recent background information.
* Read public documentation for a model, tool, institution, or product.
* Supplement information that is not yet in your Zotero library.
* Summarize, extract, or compare web page content.
Web content can change and may be inaccurate. For formal citations, verify information against the original paper, official documentation, or another authoritative source.
## How to Turn It On [#how-to-turn-it-on]
Sign in to your BibGenie account.
Find the **Web Search** button below the chat input box.
Click the button to turn web search on or off.
When enabled, ask BibGenie explicitly to search the web or read a web page.
## Examples [#examples]
```text
Search the web to see whether this paper has an official project page, code repository, or dataset page.
```
```text
Read this web page and summarize the parts relevant to my paper topic:
https://example.com
```
```text
First search my Zotero library, then search the web for recent developments in this area.
```
## Privacy Note [#privacy-note]
Web tools access public web pages. Avoid including sensitive, unpublished, or confidential material in requests that require web access. For private work, use Zotero library context, local context, BYOK, or local models instead.
# Zotero Annotations (/docs/zotero-annotations)
BibGenie can work directly with saved Zotero annotations, including highlights, comments, image annotations, ink annotations, and underlines. It can retrieve annotations from a known attachment or search across your library, then use their content in a conversation with a traceable link back to Zotero.
## Two Annotation Tools [#two-annotation-tools]
| Tool | Use it when | Supported scope and filters |
| :------------------- | :---------------------------------------------- | :------------------------------------------------------------------------------------------------- |
| `get_annotations` | You know the PDF, EPUB, or snapshot attachment | Returns that attachment's annotations in reading order |
| `search_annotations` | You need to find annotations across the library | Highlighted text, comment, tag, color, type, author, attachment, collection, and modification time |
Both tools return paginated results. BibGenie continues from the next offset only when more results are needed.
`get_annotations` works with an attachment, not its parent bibliographic item. If you start from a regular Zotero item, BibGenie first identifies its attachment and then retrieves the annotations.
## Example Requests [#example-requests]
```text
Show me the highlights and comments in this PDF.
```
```text
Find my yellow highlights tagged methods in the Literature Review collection.
```
```text
Search my recent annotations for comments about sampling bias.
```
## Add Saved Annotations to Chat [#add-saved-annotations-to-chat]
You can add an annotation without asking BibGenie to search for it:
* In a Zotero Reader, select one or more saved annotations, right-click, and choose **Add to Chat**.
* In the Library view, select annotation items and choose **Add to Chat**.
* Use the **Reader Annotations** toggle in [Add to Chat Settings](/docs/add-to-chat-settings) to control the Reader context-menu entry. The **Library Items** toggle controls the Library entry.
The annotation context includes its highlighted text, comment, type, color, tags, attachment identity, and a stable reference when available.
Annotation comments are written by the annotation author and should not be treated as source-document content. For citation behavior, see [BibGenie Citation](/docs/bibgenie-citations).
Click an annotation reference in the conversation to open its parent attachment and navigate to the saved annotation. Navigation depends on the location data stored by Zotero and may be less precise for damaged or unusual documents.
## Current Limits [#current-limits]
* BibGenie can read and search existing annotations, but it does not edit or delete them.
* Image and ink annotations may contain little or no searchable text.
* Deleted annotations and annotations whose parent attachment is unavailable are not returned.
* For stronger evidence or surrounding context, ask BibGenie to read the relevant PDF page, EPUB section, or snapshot content.
# Zotero Collections & Tags Guide (/docs/zotero-collections-tags-best-practices)
Zotero's collections and tags both help you organize references, but they solve different problems. A maintainable Zotero library rarely relies on just collections or just tags alone. Instead, use collections as project or topic entry points, tags as cross-collection search dimensions, and saved searches for dynamic workflows.
If you use BibGenie, this guide is more than a "how to organize" methodology — it becomes an actionable workflow. BibGenie's Library Organization feature can inventory your existing collections, tags, and items, propose an organization plan based on your research system, then (after your confirmation) batch-create collections, add or remove tags, move items, and rename or merge messy tags.
Collections answer "Which project, course, review, or topic entry point do these references belong to?" Tags answer "What characteristics, methods, statuses, objects, or use cases does this reference have?"
Zotero provides the basic organizing capabilities — collections and tags. BibGenie's Library Organization feature acts as your library organization assistant: it first understands how you already organize, then proposes a reviewable plan, and finally executes after your approval.
For a complete introduction to BibGenie's library organization capabilities and example prompts, see the [Library Management documentation](https://www.bibgenie.com/docs/library-management).
## Quick Reference [#quick-reference]
If you're just starting to organize your Zotero, follow these rules:
| Scenario | Recommended | How BibGenie helps |
| :--------------------------------------------------------------------- | :----------------------- | :----------------------------------------------------------------------------------------------------------- |
| Paper, course, project, thesis, dissertation | Collection | Generate a project collection structure from selected items and add references to the matching collection |
| Research topic, method, data type, region, theoretical framework | Tag | Read titles, abstracts, and metadata, and suggest consistent topic/method/status tags |
| `to-read`, `read`, `important`, `reviewed` | Colored tag or plain tag | Batch add or remove status tags for your current reading workflow |
| Recently added (7 days), unread, missing DOI, tag combinations | Saved search | Help design search criteria and follow-up organization rules |
| Book review and the reviewed book, different versions of the same work | Related items | Identify potentially related entries, though establishing relationships is best left for manual confirmation |
| Too many nested subcollections | Avoid | Identify overly deep, fragmented, or duplicate collections and suggest merging |
## What BibGenie's Library Organization Can Do [#what-bibgenies-library-organization-can-do]
When manually organizing Zotero collections and tags, the time-consuming part isn't clicking buttons — it's deciding: which tags are duplicates, which items belong in which collection, which metadata is missing, and which operations affect too many items. That's where BibGenie's Library Organization feature shines.
| Task | What BibGenie can do |
| :---------------------------- | :------------------------------------------------------------------------------------------------------------------------- |
| Audit existing structure | List collection hierarchy, tag vocabulary, items under a specific collection or tag |
| Find items to organize | Locate unfiled items, recently added references, entries missing DOI/abstract, items by tag or collection |
| Design an organization scheme | Propose a classification system based on titles, abstracts, metadata, existing tags and collections |
| Batch-organize items | Add or remove tags, add to or remove from collections for specified items |
| Create collections | Create new collections under the right parent, optionally placing candidate items inside |
| Clean up tags | Rename tags, merge old tags into existing ones, delete library-wide unused tags |
| Organize collections | Rename collections, move collections, delete empty or unused collections (deleting a collection does not delete its items) |
| Check metadata | Read full metadata, identify missing fields, and help correct them when reliable sources are available |
Modifying metadata, creating collections, moving items, batch-editing tags, renaming or deleting collections/tags are all write operations. BibGenie will propose actions and wait for your approval. It should never modify your Zotero library without explicit confirmation.
A good BibGenie organization request should include scope, goal, and constraints:
```text
Please organize the currently selected items. First read the existing collections and tags, then propose an organization plan based on titles, abstracts, and metadata.
Prefer reusing existing collections and tags; only suggest creating new ones if there is genuinely no suitable place.
Do not modify Zotero yet. First output which items will be affected, which tags will be added, and which collections will be used.
```
The principle behind this prompt is the core workflow of BibGenie's Library Organization feature: first discover the current state, then identify items to organize, then propose a plan, and finally execute.
## What Are Collections [#what-are-collections]
Collections are the folders and subfolders in Zotero's left sidebar. Zotero's official documentation recommends thinking of collections as "playlists" rather than file system folders: the same item can appear in multiple collections without duplicating the reference. The true complete library remains `My Library` or the corresponding group library.
Collections work best as entry points. For example:
* `PhD Thesis`
* `2026 Systematic Review`
* `Course - Research Methods`
* `Project - AI Literature Review`
* `Topic - Retrieval-Augmented Generation`
The advantage is clarity, visibility, and project-readiness. Open a collection and you see the core references needed for that work right now.
When using BibGenie, ask it to draft a collection structure aligned with your project goals before moving items:
```text
Please list my existing collections first, then decide whether the selected items can fit into existing collections.
If the existing structure isn't sufficient, design a one-to-two-level collection draft for my "literature review writing project."
Output each collection's purpose and the proposed items it would contain. Do not modify Zotero.
```
Deleting a regular collection only removes this organizational entry point, not the items inside it. To truly delete items, you need to move them to the Trash. This distinction is important for new users.
This is also why BibGenie explicitly warns you when deleting a collection: deleting a collection only removes the organizational entry; items remain in the Zotero library. If a collection has subcollections, BibGenie will refuse to delete the parent directly and will ask you to decide how to handle the subcollections first.
## What Are Tags [#what-are-tags]
Tags are text labels attached to items, attachments, and notes. They have no hierarchy but can describe the same paper from multiple angles. Zotero's official documentation notes that tags can be used for topic, method, status, rating, or personal workflow.
Tags work best as dimensions. For example:
* Topic: `llm-agent`, `scientific-discovery`, `citation-network`
* Method: `survey`, `experiment`, `meta-analysis`, `case-study`
* Object: `clinical-trial`, `graduate-students`, `zotero-users`
* Status: `to-read`, `read`, `skimmed`, `cited`
* Use: `intro-section`, `related-work`, `method-baseline`
The power of tags lies in combinatorial search. You can filter within a collection for items tagged with both `llm-agent` and `survey`, or search your entire library for everything tagged `to-read` and `citation-network`.
BibGenie's strength is batch-suggesting tags based on item content. Start by asking it to analyze only:
```text
Please list my existing tags first, then review the titles, abstracts, and existing tags of items in this collection.
Prefer reusing existing tags; only suggest new tags when no suitable one exists.
Finally, present recommended tags to keep, merge, add, and delete in a table. Do not modify Zotero.
```
## Collections vs Tags [#collections-vs-tags]
| Dimension | Collections | Tags |
| :-------------------------------------- | :-------------------------------------------- | :-------------------------------------------------- |
| Organization | Hierarchical with subcollections | Flat, no native subtags |
| Best for expressing | Projects, courses, papers, topic entry points | Topic, method, status, quality, use case attributes |
| Can an item appear in multiple? | Yes | Yes |
| Preserved when copying across libraries | Usually not | Usually yes with the item |
| Browsing | Strong | Moderate |
| Cross-filtering | Moderate | Strong |
| Maintenance risk | Collection bloat | Tag synonym and spelling drift |
| Recommended granularity | Few, stable | Can be finer, but naming must be consistent |
If you already have a `Topic - LLM Agents` collection, you don't necessarily need to tag every item in it with `llm-agents`, unless you want to search for that topic across other collections.
When using BibGenie to organize, add this principle to your prompt:
```text
Please avoid making tags and collections fully redundant. Don't mechanically add the same tag to every item when the collection already expresses the project membership. Only add topic tags when cross-collection search is needed.
```
## Recommended Organization Model [#recommended-organization-model]
For most researchers, a solid Zotero structure has three layers.
### 1. A Few Top-Level Collections for Big Directions [#1-a-few-top-level-collections-for-big-directions]
Don't create too many top-level collections. Design them as entry points you won't frequently rename:
```text
My Library
Inbox
Thesis
Papers
Projects
Topics
Teaching
Archive
```
Or more closely aligned with your research domain:
```text
My Library
Domain - AI for Science
Domain - Bibliometrics
Domain - Human-Computer Interaction
Project - BibGenie SEO
Project - Zotero Workflow Study
```
### 2. One to Two Levels of Subcollections for Projects [#2-one-to-two-levels-of-subcollections-for-projects]
Don't drill down indefinitely. Two levels is usually enough:
```text
Project - Systematic Review
01 Search Results
02 Screening
03 Included Studies
04 Background Reading
05 Cited in Manuscript
```
This structure maps to the research workflow, making it more practical for actual writing than a dozen topic-based subdivisions.
### 3. Tags as Composable Cross-Cutting Dimensions [#3-tags-as-composable-cross-cutting-dimensions]
Tags shouldn't replace all collections. They're better for recording "what else is searchable about this paper":
```text
method:survey
method:experiment
topic:semantic-search
topic:zotero
status:to-read
status:read
use:background
use:key-citation
```
Zotero has no native hierarchical tags, but you can simulate namespaces with prefixes like `method:`, `topic:`, `status:`. This reduces ambiguity and makes scanning in the tag selector easier.
## Tag Naming Conventions [#tag-naming-conventions]
A good tag system isn't about having more tags; it's about being consistent.
| Rule | Recommended | Not Recommended |
| :------------------------------------------------ | :------------------ | :------------------------------------- |
| Use lowercase | `semantic-search` | `Semantic Search`, `semantic Search` |
| Use hyphens for compound words | `citation-network` | `citation network`, `citation_network` |
| Prefix categories | `method:survey` | Mixed `survey`, `surveys` |
| Keep status tags consistent | `status:to-read` | Mixed `unread`, `to read`, `todo` |
| Avoid overly broad tags | `topic:llm-agent` | `ai`, `paper`, `research` |
| Avoid overly temporary tags polluting the library | `use:intro-section` | `maybe-use-in-chapter-2-later` |
If you already have duplicate tags, rename the old tag to the target name in the tag selector to merge them. For example, rename `to read` to `status:to-read`.
If tags are already messy, ask BibGenie to do a tag audit first:
```text
Please list the current library's tags and identify potentially duplicate or synonymous tags — for example, different casing, spaces vs hyphens, singular vs plural.
Give merge suggestions and note how many items each tag affects.
Do not execute any renaming or deletion yet.
```
Then confirm before executing:
```text
I confirm the merge plan. Please rename the tag `to read` to `status:to-read`.
If `status:to-read` already exists, merge the two tags. Before executing, confirm how many items will be affected.
```
BibGenie's tag renaming and merging doesn't loop through items one by one; it uses Zotero's library-wide tag operations. When you rename an old tag to an existing tag name, Zotero merges them. This is more reliable and better suited for cleaning up long-accumulated synonymous tags than manually adding new tags and removing old ones item by item.
## How to Use Colored Tags [#how-to-use-colored-tags]
Zotero supports assigning colors to a small number of tags, which can be quickly added or removed with number keys. The current official documentation states a maximum of 9 colored tags.
Colored tags are best for "high-frequency statuses," not for all topics:
| Colored tag | Purpose |
| :----------------- | :------------------- |
| `status:to-read` | To read |
| `status:reading` | Currently reading |
| `status:read` | Read |
| `use:key-citation` | Key citation |
| `use:write-next` | For upcoming writing |
Avoid assigning colored tag status to ordinary topic tags like `machine-learning`, `history`, or `statistics`. Topics multiply over time, but colored tag slots are scarce.
BibGenie can't decide which tags should permanently occupy your colored tag slots, but it can help identify your most frequently used status-like tags and suggest whether to consolidate them into fewer high-frequency tags.
## Should You Keep Automatic Tags [#should-you-keep-automatic-tags]
When Zotero saves items from databases, websites, or library catalogs, it sometimes automatically imports subject headings or keywords. These automatic tags can sometimes be useful, but they often create noise: inconsistent casing, messy granularity, overly broad terms, and tag bloat.
Recommended strategies:
1. New libraries or heavy organizers: Turn off automatic tags and maintain core tags manually.
2. Medical, legal, library science users relying on controlled vocabularies: Keep automatic tags initially, then clean up periodically.
3. Users with a large backlog of automatic tags: Hide automatic tags first, then batch-delete after confirming they're useless.
To disable, go to Zotero Settings / Preferences > General and uncheck `Automatically tag items with keywords and subject headings`.
If you're unsure which automatic tags are valuable, ask BibGenie to group them by frequency and semantics:
```text
Please check the current library's tags and list those that may be from automatic import, overly broad, or inconsistently cased. Do not delete anything, just give cleanup suggestions.
```
## Saved Searches Are an Underrated Organization Tool [#saved-searches-are-an-underrated-organization-tool]
Saved searches are like "smart collections." They store search criteria, not fixed results, so they automatically update as your library changes.
Good use cases for saved searches:
* `Unread`: tag is not `status:read`
* `Recent Additions`: items added in the last 7 days
* `Missing DOI`: items where DOI is empty
* `Need Review`: items tagged `status:to-read` in a specific collection
* `Key RAG Papers`: items with both `topic:rag` and `use:key-citation`
If you find yourself repeatedly using the same filter criteria, consider creating a saved search rather than a new static collection.
BibGenie is better suited to helping you design saved search rules than converting every dynamic task into a collection. For example:
```text
I want to create a dynamic view of "unread RAG papers."
Please review my existing tags and collections first, then suggest Zotero saved search criteria.
If existing tags aren't suitable, explain which tags need to be standardized first.
```
BibGenie can also use a similar saved-search approach to find items to organize, such as "items added in the last 30 days that haven't been placed in any collection," "journal articles missing DOIs," or "items with old tags but no new tags." These tasks are best handled by first outputting a candidate list, then deciding whether to make batch changes.
## How to Use Related Items [#how-to-use-related-items]
Related items shouldn't replace tags or collections. As discussed in Zotero forums, the problem with Related is that it only expresses "two items are related" without clarifying "why they are related." It's therefore best for explicit one-to-one or small-scale relationships:
* A book review and the reviewed book
* A conference paper and its extended journal version
* A dataset paper and the benchmark paper that uses it
* A preprint, published version, and corrigendum of the same study
* Core source papers repeatedly discussed in a review article
If you simply want to express "these items all belong to the same topic," use tags or collections instead.
## Three Common Workflows [#three-common-workflows]
### Workflow A: Writing a Paper or Review [#workflow-a-writing-a-paper-or-review]
Create a collection for your writing project, e.g., `Project - LLM Agent Review`.
Place candidate papers in `01 Search Results` or `Inbox` first.
Use tags to mark topics, methods, and statuses, e.g., `topic:tool-use`, `method:benchmark`, `status:to-read`.
After screening, move or add core papers to `03 Included Studies`.
Use `use:key-citation`, `use:intro-section`, `use:method-section` to mark writing purposes.
Suitable BibGenie prompt:
```text
Please examine the `Project - LLM Agent Review` collection.
First list the existing subcollections and tags, then classify the papers into five categories following a review writing workflow: search results, screening, included, background, and cited.
Prefer using existing subcollections; justify any new ones needed.
First output a table, do not move any items yet.
```
After confirmation:
```text
I confirm this classification table. Please add these items to the corresponding collections per the table, and add the `use:key-citation` tag to core papers.
After completion, summarize how many items were modified, which collections were used, and which tags were added.
```
### Workflow B: Building a Long-Term Research Domain [#workflow-b-building-a-long-term-research-domain]
Create a long-term collection, e.g., `Domain - AI for Science`.
Create a limited number of subcollections only when truly needed, e.g., `Foundation Papers`, `Benchmarks`, `Applications`.
Use fine-grained tags to record topics, methods, datasets, and experimental subjects.
Periodically check `Unfiled Items` and add orphaned items to appropriate collections or delete them.
Suitable BibGenie prompt:
```text
Please analyze the items in `Domain - AI for Science`.
First read the existing tags, identify 5 to 8 stable research topics, and suggest corresponding `topic:` tags.
Avoid creating too many subcollections; prefer tags unless a topic will be maintained separately long-term.
```
### Workflow C: Lightweight Users [#workflow-c-lightweight-users]
If you don't want to maintain a complex system, follow these minimal rules:
* Collections: Create by project or course.
* Tags: Use only 5 to 15 high-frequency statuses or topics.
* Colored tags: Only mark `to-read`, `read`, `important`.
* Monthly cleanup: Automatic tags, duplicates, and unfiled items.
A lightweight system that's maintained is more reliable than a complex one that isn't.
Lightweight users can still use BibGenie, but the focus should be on reducing maintenance overhead, not generating more tags:
```text
Please classify the currently selected items into only three statuses: `status:to-read`, `status:reading`, `status:read`. If you can't determine the status, put it in `status:to-read` and show a preview first.
```
## Monthly Maintenance Checklist [#monthly-maintenance-checklist]
Perform Zotero library housekeeping monthly:
* Open `Unfiled Items` and process items not in any collection.
* Open `Duplicate Items` and merge duplicates rather than deleting one.
* Check the tag selector for synonymous tags, e.g., `methods` and `research-methods`.
* Hide or delete useless automatic tags.
* Check recently added items for clean title, author, year, DOI, and abstract.
* Delete temporary subcollections that have lost their purpose to avoid collection bloat.
Ask BibGenie to list candidate items and proposed changes before executing batch tag additions, collection creations, item moves, or metadata checks. For any batch operation, preview first and scope it, e.g., "only process the currently selected items" or "only process this collection."
A solid BibGenie monthly organization prompt:
```text
Please help me with Zotero library housekeeping:
1. First list existing collections and tags.
2. Check for unfiled items, duplicate or synonymous tags, overly deep collections, and recently added unorganized items.
3. When checking items missing DOI or abstract, consider the item type to determine whether a DOI is actually expected.
4. Only output the problem list, impact scope, and suggested actions. Do not modify Zotero.
```
If you want to place unfiled items in appropriate locations, ask BibGenie to execute a more specific task:
```text
Please find the most recent 50 unfiled items and determine which collections they best fit into based on existing collections.
Do not create new collections unless the existing structure clearly has no suitable place.
First output each item, the suggested collection, the reason, and your confidence level.
```
## Common Mistakes [#common-mistakes]
### Mistake 1: Using Collections as Your Only Organization System [#mistake-1-using-collections-as-your-only-organization-system]
If you create a subcollection for every minor topic, you'll end up with dozens or hundreds of collections after a few years. Items get buried in deep trees, making them harder to find.
When using BibGenie, don't ask it to create collections for every small topic. A better instruction: "Only create collections for long-term projects, courses, papers, or stable topics; use tags for fine-grained concepts."
### Mistake 2: Tags Without Naming Rules [#mistake-2-tags-without-naming-rules]
If `to read`, `ToRead`, `unread`, `todo` all coexist, search breaks down. Tag systems fear synonym drift most of all.
BibGenie can detect this drift and rename old tags to unified ones. Renaming to an existing tag effectively merges them.
### Mistake 3: Using Related to Express Topic Membership [#mistake-3-using-related-to-express-topic-membership]
Related is better for explicit relationships, not for linking a batch of topically similar items. Topic membership should use tags or collections.
### Mistake 4: Forgetting Subcollection Display Settings [#mistake-4-forgetting-subcollection-display-settings]
In Zotero, subcollection items don't necessarily show in the parent collection by default. Change this via `View -> Show Items from Subcollections`. This setting affects how you understand parent-child collection relationships, so it's best to standardize in team workflows.
### Mistake 5: Ignoring Automatic Tags for Too Long [#mistake-5-ignoring-automatic-tags-for-too-long]
Auto-imported tags clutter the tag selector. Unless you explicitly rely on these keywords, periodically hide, delete, or disable automatic tags.
### Mistake 6: Treating "Organize My Entire Library" as a Vague Command [#mistake-6-treating-organize-my-entire-library-as-a-vague-command]
"Please organize my entire library" sounds convenient but is usually too broad. BibGenie's Library Organization feature is better suited to starting with specific pain points, such as:
* Recently added but unorganized items.
* Items in a collection that need further subdivision.
* Duplicate or synonymous tags.
* Entries missing DOI, abstract, or publication title.
* Core papers to mark with `use:key-citation` for an upcoming writing project.
A better prompt:
```text
Please don't organize the entire library yet. Help me diagnose the 3 most pressing categories of issues: unfiled items, duplicate tags, and missing metadata. Only output the problem scope and suggested next steps.
```
### Mistake 7: Having AI Fill Unverifiable Metadata [#mistake-7-having-ai-fill-unverifiable-metadata]
BibGenie can check metadata and help correct it when reliable sources are available, but you should never ask AI to write its own DOI, abstract, journal name, author, or page number. For metadata writes, reliable sources should come from Zotero's existing metadata, user-provided information, already-read item content, or BibGenie's verifiable external reference lookups.
A good prompt:
```text
Please check the metadata completeness of the most recent 20 items. For entries missing a DOI or abstract, only suggest corrections when verifiable through reliable sources. Mark unverifiable items as "unconfirmed" and do not generate or guess content.
```
## Recommended Template [#recommended-template]
You can start directly from this template:
```text
Collections
Inbox
Project - [Project Name]
01 Search Results
02 To Screen
03 Included
04 Background
05 Cited
Domain - [Long-term Topic]
Foundation Papers
Methods
Applications
Archive
Tags
status:to-read
status:reading
status:read
use:key-citation
use:intro-section
use:method-section
method:survey
method:experiment
method:case-study
topic:[Topic Name]
```
## Safety Workflow for Using BibGenie [#safety-workflow-for-using-bibgenie]
BibGenie can manage tags, collections, item membership, and some metadata, but library organization involves modifying Zotero data. Always follow this four-step process:
Ask BibGenie to read the existing structure: collections, tags, and the scope of items to organize.
Require BibGenie to prefer reusing existing collections and tags; only create new ones if genuinely no suitable place exists.
Ask BibGenie to output the organization plan, including tags to add, tags to remove, collections to move items to, which items are affected, and which operations require approval.
After manual confirmation, explicitly authorize BibGenie to execute. After execution, ask for a summary of modifications, skipped items, and incomplete tasks.
Recommended prompt template:
```text
Please organize the currently selected items. The goal is to establish clear Zotero collections and tags:
1. First list existing collections and tags.
2. Prefer reusing existing collections and tags; don't create similar names unnecessarily.
3. Determine which items should go into the same collection.
4. Then suggest consistent `topic:`, `method:`, `status:` tags.
5. Output which tags and collections will be added or removed for each item.
6. Do not modify Zotero yet; wait for my confirmation.
```
After confirmation:
```text
I confirm the organization plan above. Please execute these changes, then summarize how many items were modified, which tags were added, and which collections were used.
```
For batch operations on 50+ items, be more specific:
```text
This is a large batch organization task. First give a brief plan including which existing collections/tags will be used, whether new ones are needed, how many items will be affected, and which write operations need my approval.
After I confirm, execute in focused batches by shared purpose. Do not run one operation per item.
```
If you only need to rename, merge, or delete a library-wide tag, don't have BibGenie modify items one by one. Describe the tag-level operation directly:
```text
Please merge the library-wide tag `methodology` into the existing tag `method:methods`.
First confirm that both tags exist and how many items are affected, then wait for my approval.
```
If you only need to rename or move a collection, have BibGenie operate on the collection itself rather than creating a new collection and moving all items:
```text
Please rename the collection `Old Thesis Reading` to `Project - Dissertation Reading`.
First list the matching collection key and its item count, wait for my confirmation, then execute.
```
## References [#references]
* [Zotero Official Docs: Collections and Tags](https://www.zotero.org/support/collections_and_tags)
* [Zotero Official KB: Organizing a library](https://www.zotero.org/support/kb/organizing_a_library)
* [Zotero Forums: tags and collections best practice?](https://forums.zotero.org/discussion/115437/tags-and-collections-best-practice)
* [Zotero Forums: Collections vs tags](https://forums.zotero.org/discussion/116758/collections-vs-tags)
* [Zotero Forums: best use for related, tags, collections](https://forums.zotero.org/discussion/129569/best-use-for-related-tags-collections)
* [Mastering Zotero: Working with Tags](https://pressbooks.library.yorku.ca/masteringzotero/chapter/working-with-tags/)
* [Zotero Manual: Tags](https://zotero-manual.github.io/tags/)
* [Harvard Library: Organize Your Zotero Library](https://guides.library.harvard.edu/c.php?g=1245347\&p=9129454)
* [UMGC Library: Collections & Tags](https://libguides.umgc.edu/c.php?g=930616\&p=6753118)
* [Massachusetts General Hospital: Organizing Your Library](https://libguides.massgeneral.org/zotero/organizing-library)
* [Catherine Pope: Keeping Your Zotero Library Tidy](https://catherinepope.com/posts/keeping-your-zotero-library-tidy/)
* [Reddit: Collections and Tags](https://www.reddit.com/r/zotero/comments/1izhq0m/collections_and_tags/)
# Zotero WebDAV (/docs/zotero-webdav)
Zotero sync lets you keep your library available across devices. In Zotero, syncing has two separate parts: **data syncing** and **file syncing**. WebDAV is used for file syncing, which includes PDFs, images, snapshots, and other attachments.
WebDAV does not directly affect BibGenie's official models, credits, or chat features. However, if you use Zotero on multiple devices, WebDAV can help ensure attachments are available locally, which affects whether BibGenie can read PDFs or snapshots on a given device.
## Data Syncing vs File Syncing [#data-syncing-vs-file-syncing]
| Type | What it syncs | Notes |
| :----------- | :-------------------------------------------------------------------------------- | :------------------------------------------------------------------------------------ |
| Data syncing | Items, titles, authors, publication years, notes, tags, collections, and metadata | Zotero provides unlimited data syncing for free |
| File syncing | PDFs, images, snapshots, audio, and other attachment files | Zotero's free file storage is limited to 300 MB; WebDAV can be used as an alternative |
To use Zotero sync, you usually need to sign in to a Zotero account and enable data syncing. WebDAV handles attachment files only; it does not replace Zotero account data syncing.
Set up Zotero data syncing first by signing in to your Zotero account in Zotero preferences. WebDAV only replaces the file storage part.
## What Is WebDAV? [#what-is-webdav]
WebDAV is a protocol that lets applications manage files on a remote server. Zotero can use WebDAV as an alternative to Zotero's own file storage, allowing attachments to sync through supported third-party storage providers.
This is useful if you want PDFs and attachments available across devices without buying Zotero's official file storage plan.
## Common WebDAV Providers [#common-webdav-providers]
| Provider | Free space / limits | Website | Notes |
| :--------- | :------------------------------------------------------------------------- | :--------------------------------------------------------- | :-------------------------------- |
| Koofr | 2 GB initially; up to 10 GB after completing account tasks | [https://koofr.eu/](https://koofr.eu/) | Easy to set up; servers in Europe |
| Jianguoyun | 1 GB/month upload traffic and 3 GB/month download traffic on the free tier | [https://www.jianguoyun.com/](https://www.jianguoyun.com/) | Often faster from mainland China |
See Zotero's official [WebDAV Providers](https://www.zotero.org/support/kb/webdav_services) page for more options.
## Configure Koofr WebDAV [#configure-koofr-webdav]
Koofr is a Europe-based cloud storage provider. It is commonly recommended because setup is straightforward and Koofr provides Zotero-specific WebDAV guidance.
Sign up for a [Koofr account](https://koofr.eu/) and log in to the Koofr web app.
Click your avatar in the upper-right corner and open **Preferences**.
Select **Password** in the left menu, then scroll to **App Passwords**.
Enter an app name such as `Zotero`, click **Generate**, and save the generated password. Koofr shows this password only once.
Open Zotero and go to **Edit -> Preferences -> Sync**. On macOS, use **Zotero -> Settings -> Sync**.
In **File Syncing**, enable attachment file syncing and choose **WebDAV**.
Enter:
* **URL**: `https://app.koofr.net/dav/Koofr`
* **Username**: your Koofr account email
* **Password**: the Koofr app password you generated
Click **Verify Server**. After verification succeeds, click **OK** to save the settings.
Click Zotero's sync button to start syncing attachment files.
The `Koofr` segment in the URL must start with a capital K.
## Configure Jianguoyun WebDAV [#configure-jianguoyun-webdav]
Log in to [Jianguoyun](https://www.jianguoyun.com/) in your browser.
Click your account name in the upper-right corner and open **Account Info**.
Open **Security Options**.
In **Third-party App Management**, click **Add Application**.
Enter a name such as `Zotero`, generate a password, and save it. This is an app-specific password, not your Jianguoyun login password.
Open Zotero and go to **Edit -> Preferences -> Sync**. On macOS, use **Zotero -> Settings -> Sync**.
In **File Syncing**, enable **Sync attachment files in My Library** and choose **WebDAV**.
Enter:
* **URL**: `https://dav.jianguoyun.com/dav/`
* **Username**: your Jianguoyun account, usually your email
* **Password**: the app-specific password generated in Jianguoyun
Click **Verify Server**. If Zotero asks to create a `zotero` folder on the WebDAV server, confirm it.
The usual Jianguoyun WebDAV server address is `https://dav.jianguoyun.com/dav/`.
If you use Zotero on multiple computers, configure the same WebDAV settings on each device and make sure Zotero data sync uses the same account.
# 添加上下文 (/zh/docs/add-context)
BibGenie 不只是让 AI “看到一个文件名”。Add Context 会把 Zotero 中的研究对象、文档内容和当前阅读位置带入对话,让 AI 知道你正在研究哪篇文献、阅读哪一章,以及具体关注哪一段文字。
你可以从整个 Zotero item 开始提问,也可以逐步缩小到某个 PDF 页面、EPUB section,甚至 PDF、EPUB 或网页快照中的一段选中文字。上下文越贴近问题,回答越聚焦,也越容易回到原文核对。
Add Context 同时支持“这是什么文献”和“我正在看哪里”两类信息。你可以添加 item、attachment、note、collection 和 tag,也可以添加当前 PDF 页面、当前 EPUB section 或 Reader 中的选中文字。
## 添加方式 [#添加方式]
在输入框中输入空格加 `@`,搜索并插入 Zotero item、attachment、note、tag、collection 等上下文。
点击输入框附近的 Add Context 按钮,打开选择窗口后添加材料。
在 Zotero item、collection、tag、reader tab 或选中文字处右键添加到对话。
将图片粘贴到输入框,或使用 Zotero 内部截图能力把图表、公式和页面区域交给 AI。
## 支持的上下文类型 [#支持的上下文类型]
| 类型 | 适合场景 |
| :------------------------- | :------------------------------- |
| Regular item | 让 AI 知道文献元信息、标题、作者、年份和关联附件 |
| PDF attachment | 阅读论文全文、总结章节、解释方法和结果 |
| EPUB attachment | 阅读电子书全文,并按逻辑页面或 section 获取相关内容 |
| Snapshot | 阅读 Zotero 保存的网页快照 |
| Note | 使用 Zotero 笔记、摘录和研究记录作为上下文 |
| 已保存标注 | 使用高亮、评论、颜色、tag 及其来源位置作为上下文 |
| Collection | 让 AI 围绕某个文献集合进行检索或整理 |
| Tag | 让 AI 围绕某个标签下的文献工作 |
| PDF / EPUB / Snapshot 选中文字 | 精确解释某一段内容 |
| 当前 PDF 页面上下文 | 围绕正在看的页面提问 |
| 当前 EPUB section | 阅读正在浏览的 EPUB 内容单元,并可从消息返回 Reader |
| 图片 / 截图 | 分析图表、公式、流程图和页面区域 |
## 用 `@` 添加上下文 [#用--添加上下文]
在输入框中输入空格加 `@` 后,BibGenie 会弹出上下文搜索菜单。你可以继续输入标题、作者、关键词、笔记名称、tag 或 collection 名称来筛选结果。
常见用法:
```text
@attention is all you need
@Smith 2023
@我的研究笔记
@systematic-review
@我的项目 collection
```
选择结果后,它会以上下文块的形式出现在输入框中。你可以继续输入问题,也可以添加多个上下文后一起提问。
## 从 Zotero 右键添加 [#从-zotero-右键添加]
你可以在 Zotero 中直接把当前对象添加到 BibGenie:
* 选中一个或多个 library items 后右键 **Add to Chat**。
* 在 collection 树上右键 **Add to Chat**。
* 在 tag selector 中右键 tag 后添加。
* 在 PDF、snapshot 或 note tab 上右键添加当前 reader tab。
* 选中 PDF、EPUB 或 snapshot 中的一段文字后添加。
* 在 PDF Reader 中右键添加当前页面,或在 EPUB Reader 中右键 **Add Section to Chat** 添加当前 section。
这些入口可以在 [Add to Chat Settings](/docs/add-to-chat-settings) 中自由开启或关闭。
## 在 Reader 中精确添加 [#在-reader-中精确添加]
BibGenie 针对不同文档格式使用适合它们的阅读单位:
| Reader | 可添加的精确上下文 | 适合场景 |
| :------- | :-------------- | :------------------- |
| PDF | 当前页面、选中文字 | 核对页码、图表附近内容或具体段落 |
| EPUB | 当前 section、选中文字 | 阅读章节内容或解释电子书中的具体片段 |
| Snapshot | 选中文字 | 分析 Zotero 保存网页中的具体内容 |
添加后的上下文会显示在用户消息中。对于带有有效位置的信息,点击消息中的上下文组件,可以重新打开对应 Reader 并返回相关位置。
EPUB 的目录层级和文件结构并不总是一一对应。当前 section 通常对应 EPUB spine 中的一个 XHTML 内容单元。如果多个二级目录共用同一个 XHTML,Add Section to Chat 会添加这个完整内容单元,而不是只截取其中一个目录锚点。
## 典型示例 [#典型示例]
添加一篇 PDF 后提问:
```text
请按「研究问题、方法、数据、主要发现、局限」总结这篇论文。
```
在 EPUB Reader 中添加当前 section 后提问:
```text
请总结这一节的核心论点,并说明它与全书主题的关系。
```
添加多篇相关论文后提问:
```text
请比较这几篇论文对同一问题的假设、方法和结论差异,并给出一张对比表。
```
选中 PDF 中的一段后提问:
```text
请解释这段话的逻辑,并指出其中最关键的概念。
```
截取论文图表后提问:
```text
请解释这张图中每个坐标轴、曲线和主要结论。
```
## 使用建议 [#使用建议]
* 尽量只添加与当前问题相关的上下文。
* 复杂任务可以先让 AI 总结,再继续追问细节。
* 多篇文献对比时,先让 AI 列出每篇文献的基本信息,再要求综合分析。
* 截图适合图表和公式,但如果需要严格引用,请同时添加原 PDF 或 item。
# Add to Chat 设置 (/zh/docs/add-to-chat-settings)
BibGenie 把 **Add to Chat** 放在 Zotero 文库和 Reader 的原生操作位置,让你不必先复制文字、查找附件,再回到聊天窗口粘贴。看到相关文献或正在阅读的内容时,可以直接把它交给 AI。
不同研究习惯需要不同入口。你可以保留常用的 PDF 选区和 EPUB section,也可以隐藏低频入口,让 Zotero 的右键菜单保持简洁。
关闭某个 Add to Chat 入口,通常只是隐藏该位置的右键菜单或快捷入口,不代表 BibGenie 完全不能添加对应类型的上下文。
## 可配置入口 [#可配置入口]
| 设置项 | 作用 |
| :---------------------- | :------------------------------------------------- |
| Library Items | 为支持的 Zotero items(包括已保存标注)显示 Add to Chat |
| Collections | 在 collection 树中显示 Add to Chat |
| Tags | 在 tag selector 中显示 Add to Chat |
| Reader Tabs | 在已打开的 PDF、snapshot 和 note tab 中显示 Add to Chat |
| PDF Text Selection | 选中 PDF 文字后显示 Add to Chat |
| EPUB Text Selection | 选中 EPUB 文字后显示 Add to Chat |
| Snapshot Text Selection | 选中 snapshot 文字后显示 Add to Chat |
| Reader Annotations | 从 Reader 右键菜单将一个或多个已保存标注加入对话 |
| Reader Page Context | 在 PDF Reader 中显示 Add Page to Chat,添加当前页面上下文 |
| EPUB Section Context | 在 EPUB Reader 中显示 Add Section to Chat,添加当前 section |
## 这些入口提供什么能力 [#这些入口提供什么能力]
Add to Chat 的入口可以分为三个层级:
Item、collection 和 tag 告诉 BibGenie 你正在围绕哪些文献或文献集合工作。
Reader tab 把 PDF、网页快照或笔记作为整体上下文加入对话,适合总结和综合分析。
PDF 页面、EPUB section 和选中文字把问题限定在当前阅读位置,适合解释、核对和精读。
对于带有有效定位信息的 Reader 上下文,添加后还可以在用户消息中点击对应组件,重新打开文档并返回相关位置。
## 推荐配置 [#推荐配置]
如果你刚开始使用,可以保留默认配置。常见推荐如下:
保留 Library Items、Reader Tabs,以及你常用格式的 Text Selection。
如果经常按 collection 或 tag 工作,保留 Collections 和 Tags。
关闭低频入口,让 Zotero 右键菜单更简洁。
## 使用建议 [#使用建议]
* 经常精读 PDF:开启 PDF Text Selection 和 Reader Page Context。
* 经常阅读电子书:开启 EPUB Text Selection 和 EPUB Section Context。
* 经常分析保存的网页:开启 Snapshot Text Selection。
* 经常做文献综述:开启 Collections 和 Tags。
* 只想保留最简单入口:保留 Library Items 和输入框 `@` 添加即可。
# BibGenie Citation (/zh/docs/bibgenie-citations)
BibGenie Citation 是连接 **AI 回答**、**原文证据** 和 **Zotero 研究对象** 的可追溯系统。
当 BibGenie 基于你的 Zotero 文库、PDF、笔记、网页快照、网页或 OpenAlex 结果作答时,会在合适的位置自动添加 `[1]`、`[2]` 这样的引用标记。你不需要手动开启,也不需要记住特殊提示词。看到引用标记时,点击它就可以回到来源,检查回答依据。
BibGenie 会区分两种容易混淆、但作用不同的链接:
* **Citation** 指向支持回答的证据,例如 PDF、EPUB 或网页快照中的文本块和选区。
* **可点击实体** 指向回答中提到的 Zotero 对象,例如 item、attachment、note、collection 或 tag。它方便继续操作,但不表示该对象本身就是某句话的证据。
这套系统的目标不是让回答看起来更像学术论文,而是帮助你判断:
* 这个结论来自哪里?
* AI 有没有误读或过度概括?
* 这条信息能不能写进笔记、综述或研究草稿?
* 如果我要继续追问,应该回到哪个来源重新阅读?
Citation 让你回到原文核对证据,可点击实体让你回到 Zotero 继续工作。一个回答可以同时包含这两种链接。
## 两种可点击链接 [#两种可点击链接]
| 类型 | 回答的问题 | 常见目标 | 是否表示证据 |
| :-------- | :------------ | :--------------------------------------------- | :----- |
| Citation | “这句话依据什么?” | 文档文本块、选中文字、已保存标注、笔记、网页或 OpenAlex 结果 | 是 |
| Zotero 实体 | “回答提到的是哪个对象?” | Item、attachment、note、annotation、collection、tag | 否 |
例如,BibGenie 可以引用 EPUB 某个文本块来支持结论,同时把回答中提到的 EPUB 附件显示为可点击对象。前者用于核对证据,后者用于打开和继续操作这份材料。
## 它解决什么问题 [#它解决什么问题]
使用 AI 做研究时,最大的风险通常不是“没有答案”,而是“答案看起来很顺,但你不知道它从哪里来”。
在真实的文献工作中,你经常需要区分三类内容:
| 类型 | 含义 | 为什么要区分 |
| :---- | :----------------------------- | :------------- |
| 原始来源 | PDF、笔记、网页快照、网页或 OpenAlex 返回的信息 | 这是回答的基础 |
| AI 总结 | BibGenie 对来源内容的整理、压缩和解释 | 可能有用,但需要核对 |
| 你的判断 | 你基于原文和研究背景形成的结论 | 最终写作和研究决策应以此为准 |
BibGenie Citation 的作用,就是在这三者之间保留一条清晰的线索。它帮助你从 AI 回答回到信息来源,再由你判断这个回答是否可靠。
## 支持哪些来源 [#支持哪些来源]
BibGenie 引用不只适用于 PDF。随着你在 Zotero 中使用不同来源,引用也会覆盖不同类型的研究材料。
当 BibGenie 阅读 PDF 时,回答可以引用具体页面、文本块或段落位置。对于 PDF 原文段落级跳转,请阅读 [段落级引用](https://www.bibgenie.com/zh/docs/paragraph-citations)。
当 BibGenie 阅读 EPUB 全文或当前 section 时,回答可以引用抽取出的具体文本块,并从引用返回 Zotero EPUB Reader 中的相关内容。
当回答基于 Zotero 笔记、摘录或研究记录时,引用可以帮助你知道信息来自哪条笔记内容。
当 BibGenie 阅读 Zotero 保存的网页快照时,回答可以引用快照中的文本块或有效选区,方便你回到保存时的网页材料。
当你使用联网搜索或网页提取时,citation 可以标记回答参考了哪些网页结果或网页正文。
当 BibGenie 使用 OpenAlex 学术检索时,引用可以关联到论文、作者、期刊、机构、引用网络等外部学术元数据。
Item、attachment、note、collection 和 tag 可以作为可点击实体出现在回答中。你可以从回答直接回到 Zotero 对象,但它们不会被冒充成原文证据。
## 选中文字也可以成为引用 [#选中文字也可以成为引用]
你可以把 PDF、EPUB 或网页快照中的选中文字添加到对话。除了让 BibGenie 直接理解这段内容,有效的 Reader 位置信息还会建立一条返回原文的路径:
在 Reader 中选中需要解释或核对的文字,然后点击 **Add to Chat**。
围绕选区提问。BibGenie 会优先使用你明确提供的这段内容。
当回答引用该选区时,点击 citation 可以重新打开对应文档并返回相关位置;PDF 等场景还可以显示临时高亮,帮助你快速找到原文。
选中文字仍然可以作为对话上下文使用,但如果保存的位置缺失、损坏或无法安全定位,BibGenie 不会为它生成一个看似可点击、实际无法返回原文的 citation。
## 文档引用如何保持精确 [#文档引用如何保持精确]
BibGenie 阅读 PDF、EPUB 和网页快照时,会把文档内容组织成带稳定标识的文本块。回答引用的是实际支持结论的文本块,而不是笼统地把整个附件都标成来源。
这带来三个直接好处:
* 点击引用时,更容易回到相关页面、section 或原文位置。
* 同时分析多份附件时,可以区分结论分别来自哪份材料。
* 复制回答或保存为 Zotero note 时,引用仍然保留可读的来源信息。
## Citation 能帮你做什么 [#citation-能帮你做什么]
对重要结论、数据、方法描述和作者观点,点击引用回到来源,确认 AI 的表达是否真的被材料支持。
当某个回答很有价值时,引用可以把你带回最相关的 PDF、笔记、网页快照或网页内容,继续深入阅读。
生成研究笔记时,引用帮助你保留“这段总结来自哪里”的线索,日后复查时不用重新搜索整篇文献。
在同时使用本地 Zotero 文献、网页和 OpenAlex 时,引用可以帮助你区分哪些信息来自本地文献,哪些来自外部检索。
## 典型使用场景 [#典型使用场景]
你可以让 BibGenie 总结研究问题、方法、实验设计、主要发现和局限。回答中的引用可以帮助你回到论文原文核对关键表述。
如果你希望了解 PDF 中“点击引用跳回原文段落”的能力,请阅读 [段落级引用](https://www.bibgenie.com/zh/docs/paragraph-citations)。
你可以把整个 EPUB attachment 或当前 section 添加到对话,让 BibGenie 总结论点、解释概念或比较不同章节。回答中的引用会关联到 EPUB 中实际使用的文本块,而用户消息中的 section 组件还可以带你返回添加时的阅读位置。
在 PDF、EPUB 或网页快照中选中文字并添加到对话,可以把问题精确限定到一个片段。当该选区具有有效定位信息时,回答中的 citation 可以带你回到原文核对上下文。
如果你已经在 Zotero 中积累了摘录、阅读笔记或想法记录,可以让 BibGenie 基于这些笔记整理主题。引用能帮助你区分 AI 的总结来自哪条笔记,而不是把所有笔记混成一段无法追溯的回答。
当你把项目主页、数据集说明、工具文档或新闻页面保存为 Zotero 网页快照时,BibGenie 可以读取这些内容并用引用标记来源。如果你使用联网搜索或网页提取,引用也能帮助你知道回答参考了哪些网页。
OpenAlex 返回的是外部学术元数据,例如论文标题、作者、DOI、期刊、引用次数和引用关系。引用可以帮助你追踪某个回答来自哪条 OpenAlex 结果,避免把外部检索结果误认为本地已读论文结论。
你可以同时让 BibGenie 使用本地 PDF、Zotero 笔记、OpenAlex 结果和网页材料。引用能帮助你在综合回答中区分来源,知道哪些信息来自已保存文献,哪些信息来自外部补充材料。
## 如何阅读回答中的引用 [#如何阅读回答中的引用]
BibGenie 的回答中通常会出现 `[1]`、`[2]` 这样的引用标记。你可以把它们理解为“来源入口”。
**先看回答结构**:快速判断 BibGenie 是否抓住了你的问题重点。
**找到关键结论**:优先关注你准备采纳、写入笔记或继续追问的内容。
**点击引用**:回到相关 PDF、笔记、网页快照、网页或 OpenAlex 来源。
**核对来源内容**:确认来源是否真的支持回答中的说法,尤其注意限定条件、语气和上下文。
**继续追问或修正**:如果回答太笼统,可以要求 BibGenie 基于引用处内容重新表述。
## Citation 和正式参考文献的区别 [#citation-和正式参考文献的区别]
BibGenie Citation 主要用于 **阅读、核对和追溯来源**。它不是最终论文中的参考文献格式。
| 项目 | BibGenie Citation | 正式参考文献 |
| :------ | :---------------- | :------------- |
| 主要用途 | 帮你回到 AI 回答所依据的来源 | 满足论文、报告或期刊格式要求 |
| 出现位置 | BibGenie 对话回答中 | 文档正文和参考文献列表中 |
| 关注重点 | 来源追溯、证据核对、继续阅读 | 引文格式、出版信息、规范排版 |
| 是否可直接提交 | 不建议直接作为正式引用 | 需要按目标格式生成和检查 |
如果你要写论文、课程作业、基金申请或正式报告,仍然需要使用 Zotero 的引用样式,例如 APA、MLA、Chicago、GB/T 7714 或目标期刊要求的格式。
BibGenie Citation 适合用来核对“回答从哪里来”。正式写作时,请回到 Zotero 条目和原始来源,使用规范的参考文献格式。
## 为什么有些回答没有 Citation [#为什么有些回答没有-citation]
并不是每一句回答都会有 citation。这通常有几类原因:
* **问题是操作型问题**:例如“帮我整理一下这个 collection”,回答可能是在解释下一步操作,而不是引用某段来源。
* **回答是综合判断**:有些总结来自多个来源的综合,不一定能用一个 citation 精确覆盖。
* **来源不够明确**:如果输入中没有足够可追溯的材料,BibGenie 可能只能给出一般性建议。
* **外部网页或元数据有限**:OpenAlex 和网页检索结果通常是摘要或元数据,不等同于全文阅读。
* **文档结构或文本质量影响解析**:扫描 PDF、OCR 较差、复杂排版、EPUB 目录与 spine 不一致,或网页快照结构异常,都可能影响引用定位。
如果回答中的某个重要说法没有 citation,你仍然可以自然地继续追问,例如“这个结论依据是什么?”或“它来自哪篇文献、哪条笔记或哪个网页?”。这类追问适合用来进一步核对来源,但 citation 本身会在 BibGenie 能追溯来源时自动添加。
## 使用建议 [#使用建议]
* 重要结论不要只看 AI 总结,尽量点击 citation 回到来源核对。
* 当引用指向 PDF、EPUB 或网页快照时,优先阅读引用附近的上下文,而不是只看高亮片段。
* 当引用来自 OpenAlex 时,记住它通常代表学术元数据,不代表 BibGenie 已经阅读论文全文。
* 当引用来自网页时,注意网页内容可能变化,正式使用前建议回到原网页或权威来源确认。
* 写文献笔记时,保留自动生成的引用,方便之后复查。
* 写正式论文时,不要直接复制 BibGenie Citation;应使用 Zotero 生成规范参考文献。
* 如果回答没有引用,可以追问“这个结论依据是什么?”或“它来自哪篇文献、哪条笔记或哪个网页?”。
## 和段落级引用的关系 [#和段落级引用的关系]
BibGenie Citation 是一个更宽的概念,覆盖 PDF、笔记、网页快照、网页、OpenAlex 等多种来源。它回答的是:
**AI 回答中的信息,来自哪里?**
[段落级引用](https://www.bibgenie.com/zh/docs/paragraph-citations) 是其中一个更具体、更强的 PDF 阅读能力。它回答的是:
**AI 回答中的 PDF 结论,能不能跳回原文中的具体段落?**
如果你主要关心 PDF 精读、原文高亮、点击引用跳回 Zotero PDF Reader,请继续阅读 [段落级引用](https://www.bibgenie.com/zh/docs/paragraph-citations)。
BibGenie Citation 是总览:它让回答带来源。段落级引用是 PDF 精读亮点:它让 PDF 回答能跳回原文段落。
# 自带 API Key (/zh/docs/byok)
BYOK 是 Bring Your Own Key 的缩写,意思是使用你自己的模型 provider、API Key 或本地模型。
## BYOK 的核心价值 [#byok-的核心价值]
自定义模型请求直接从本地 Zotero 插件发往你配置的 provider。
通过 Ollama 或 LM Studio,让模型运行在你的电脑上。
BYOK 请求不走 BibGenie 官方模型服务,因此不消耗官方 Credit。
使用官方模型列表之外的模型或机构内部模型服务。
## 数据会经过 BibGenie 服务吗? [#数据会经过-bibgenie-服务吗]
如果你添加了自定义模型,请求数据不会通过 BibGenie 的模型服务,而是由本地 Zotero 插件直接发送到你配置的 provider。
这意味着:
* 使用 OpenAI API Key,请求会直接发往 OpenAI。
* 使用 Anthropic API Key,请求会直接发往 Anthropic。
* 使用 OpenAI Compatible 中转服务,请求会发往你填写的 Base URL。
* 使用 Ollama 或 LM Studio,请求可以完全留在本机。
BYOK 不经过 BibGenie 服务,但如果你使用云端 provider,文献内容和上下文会发送给该 provider。请根据你的机构、实验室或项目数据政策选择 provider。
## 支持的 provider [#支持的-provider]
BibGenie 支持多种 provider 类型:
| Provider | 说明 |
| :---------------- | :-------------------- |
| OpenAI | OpenAI GPT 系列模型 |
| Anthropic | Claude 系列模型 |
| xAI | Grok 系列模型 |
| DeepSeek | DeepSeek 模型 |
| Google | Gemini 模型 |
| Groq | Groq 托管的高速模型 |
| Moonshot AI | Kimi 系列模型 |
| OpenRouter | 统一模型路由平台 |
| Ollama | 本地模型服务 |
| OpenAI Compatible | 任何兼容 OpenAI API 格式的服务 |
LM Studio 通常可以通过 **OpenAI Compatible** 接入。
## BYOK 什么时候适合你? [#byok-什么时候适合你]
* 你已经有 provider API Key。
* 你希望费用由自己的 provider 账户承担。
* 你需要使用机构内部模型服务。
* 你希望请求完全不经过 BibGenie 官方模型服务。
* 你想使用本地模型处理敏感材料。
* 你需要某个官方模型列表中暂时没有的模型。
## 下一步 [#下一步]
阅读 [Custom Models](/docs/custom-models),按照 provider 类型添加模型、填写 Base URL 和 API Key,并测试连接。
# 引用格式 (/zh/docs/citation-format)
Citation Format 决定 BibGenie 在聊天上下文中如何显示 Zotero item。它尤其会影响你在输入框中输入 `@` 后,item 类型上下文的展示样式。
## 它会影响什么? [#它会影响什么]
* `@` 搜索结果中 item 的引用展示。
* 添加到 chat context 后的 item 显示。
* AI 读取上下文时看到的 item 引用格式。
Citation Format 只影响显示样式,不会修改文献标题、作者、年份、期刊等 Zotero item 元数据。
## 选择 CSL 样式 [#选择-csl-样式]
BibGenie 使用 Zotero 已安装的 CSL 样式。你可以在 Preferences 的 **Citation Format** 区域选择默认 CSL Style。
常见样式包括:
* APA
* Chicago
* MLA
* IEEE
* Nature
* Vancouver
## 什么时候需要修改? [#什么时候需要修改]
如果你正在按特定期刊或学科格式写作,可以选择对应 CSL 样式。
作者年份格式更适合快速识别社会科学、人文学科文献。
数字编号格式可能更适合工程、计算机或 IEEE 风格工作流。
## 常见问题 [#常见问题]
BibGenie 读取 Zotero 已安装的 CSL 样式。请先在 Zotero 中安装或启用对应样式。
不会。这里主要影响 BibGenie chat context 的展示方式。
# 管理对话 (/zh/docs/conversation-management)
BibGenie 会把每段对话保存为可以继续、修正和分支的研究过程。你可以修改最近的提问、重新生成回答、从历史回答创建新的对话,也可以压缩长对话的早期内容,为后续研究保留上下文空间。
修改当前分支中最近一条可以安全编辑的用户消息,并重新发送。
让 BibGenie 根据相同的对话上下文重新生成最近的回答。
从一条稳定的历史回答开始新的对话,同时保留原对话。
总结较早的内容并保留近期消息,减少长对话占用的上下文空间。
## 编辑最近的提问 [#编辑最近的提问]
将鼠标移到最近一条可编辑的用户消息上,然后选择 **编辑**。修改内容并重新发送后,BibGenie 会使用新的提问继续当前对话。
编辑会替换这条消息之后的对话内容。原回答以及依赖原回答产生的尾部状态将不再属于当前分支,因此请先确认这些内容不需要保留。如果希望保留原来的研究路线,请先[创建对话分支](#创建对话分支)。
在 AI 正在生成回答、工具仍在执行或等待你确认时,编辑可能暂时不可用。
## 重试回答 [#重试回答]
如果最近的回答不符合预期,选择回答下方的 **重试** 按钮。BibGenie 会保留此前的对话上下文,并重新生成这次回答。
重试会替换当前分支中的原回答。若原回答之后存在依赖它生成的尾部压缩记录,该记录也会随原回答失效;BibGenie 会在后续发送消息时重新判断是否需要压缩上下文。
如果你希望同时保留两个答案,可以先从原回答创建分支,再在其中一个对话中重试。
## 创建对话分支 [#创建对话分支]
Fork 可以把一条历史回答作为新对话的起点。将鼠标移到一条可分支的助手回答上,选择 **Fork**,确认后 BibGenie 会创建并打开一个新对话。
```text
原对话:问题 1 → 回答 1 → 问题 2 → 回答 2
│
新分支: └→ 新问题 → 新回答
```
新分支会继承所选回答及其之前的对话内容。创建完成后,两个对话可以独立继续:在一个分支中发送消息、编辑或重试,不会改写另一个分支的后续内容。
Fork 适合以下场景:
* 从同一篇论文探索不同的解释或研究假设。
* 比较不同提示词、模型或分析路线。
* 保留当前结果,同时继续尝试可能改变后续对话的操作。
只有已经稳定完成的助手回答可以用于 Fork。AI 正在生成、工具仍在执行或等待确认时,请先完成当前操作。
## 压缩长对话 [#压缩长对话]
模型一次能够处理的内容有限。随着消息、论文、图片和工具结果不断增加,对话会逐渐接近当前模型的 Context Window。BibGenie 可以把较早的对话总结为一段紧凑上下文,同时保留近期消息供模型继续使用。
BibGenie Agent 通常会在需要时自动压缩对话。除非你明确希望立即压缩早期上下文,否则可以继续正常提问,不必手动选择 Compact。
### 自动压缩 [#自动压缩]
BibGenie 会在以下时机检查上下文:
* 发送新消息前:如果新消息会使对话接近模型上限,先压缩早期上下文,再自动发送你的消息。
* 一轮回答完成后:如果上下文占用已经达到压缩阈值,在后台压缩早期内容。
自动压缩与手动压缩使用相同的进度提示。若你在发送后触发了压缩,待发送消息会在压缩成功后继续发送,不需要再次点击发送。
### 手动压缩 [#手动压缩]
如果你明确希望立即压缩当前对话,可以将鼠标移到输入框右下角的 **Context Window** 指示器上,然后选择弹窗右上角的压缩图标。压缩期间,对话区会显示 **Compacting earlier context…**;你可以继续编辑输入框中的内容,也可以选择 **Cancel** 取消尚未完成的压缩。
### 查看压缩摘要 [#查看压缩摘要]
压缩完成后,对话中会出现 **Earlier context compacted** 分隔标记。展开它可以查看:
* 较早对话的摘要。
* 压缩前的上下文 token 数量。
* 执行压缩时使用的模型和上下文窗口信息。
压缩不会把摘要显示成普通用户提问,也不会让后续回答直接回复这条标记。BibGenie 会在发送给模型前,把最新摘要与保留的近期消息组合为有效上下文。
## 这些操作如何配合 [#这些操作如何配合]
| 操作 | 当前对话会发生什么 | 是否创建新对话 | 是否调用模型 |
| :------ | :----------------- | :-----: | :----: |
| 编辑 | 替换目标用户消息及其后的当前分支内容 | 否 | 重新发送时会 |
| 重试 | 替换最近一次可重试的回答及其尾部状态 | 否 | 是 |
| Fork | 保留原对话,并从所选回答创建独立分支 | 是 | 否 |
| Compact | 总结较早上下文,并保留近期消息 | 否 | 是 |
如果一个操作可能替换你仍想保留的回答,先使用 Fork 创建分支。
## 操作暂时不可用 [#操作暂时不可用]
以下情况可能会暂时禁用编辑、重试、Fork 或 Compact:
* BibGenie 正在生成回答。
* 工具调用尚未结束,或正在等待你批准。
* 对话正在压缩,或已有消息等待压缩后发送。
* 当前目标不在允许修改或分支的位置。
* 保存的对话历史损坏,当前会话只能查看。
先完成或取消当前操作,再重新尝试。如果对话以只读方式打开,BibGenie 会保留能够安全显示的历史,但不会修改原始保存数据。
# 自定义模型 (/zh/docs/custom-models)
自定义模型让你可以使用自己的 API Key、第三方 provider、本地模型或机构内部模型服务。配置完成后,BibGenie 会从本地 Zotero 插件直接向你填写的 provider 发起请求。
## 添加模型 [#添加模型]
打开 BibGenie,进入 **Model Settings**。
在 Custom Models 区域点击 **Add Model**。
先选择或输入 **Provider ID**。BibGenie 会从模型目录中加载常见 provider,并在你选择后自动补全 Provider Name、Provider Type 和 Base URL。
再选择或输入 **Model ID**。如果该模型存在于目录中,BibGenie 会自动补全 Model Name、Family、Model Types、Context Window、Max Tokens、Description 等字段。
填写 API Key。如果是 Ollama 等本地服务,通常不需要 API Key。
点击 **Test** 测试连接。连接成功后会显示 Connected;失败时会显示错误信息。
检查自动补全的字段是否正确,必要时手动调整 Model Types、Context Window 或 Max Tokens。
点击 **Add Model** 保存。保存后模型会自动启用,并出现在聊天页面的模型选择器中。
## 自动补全 [#自动补全]
Add Custom Model 并不是完全手动填写。BibGenie 会尝试从 `models.dev` 的模型目录加载 provider 和 model 信息:
* Provider ID 输入框支持搜索常见 provider,也支持手动输入 custom provider。
* 选择 provider 后,会自动填入 Provider Name、Provider Type 和 Base URL。
* Model ID 输入框会根据当前 provider 显示可选模型,也支持手动输入 custom model。
* 选择目录中的模型后,会自动填入 Model Name、Family、Model Types、Context Window、Max Tokens、Description,以及模型价格信息。
* 如果模型目录加载失败,BibGenie 会使用内置 fallback provider 列表,仍然可以手动添加模型。
如果你的 provider 和 model 能在下拉搜索中找到,建议优先选择目录项,而不是手动输入。这样可以减少 Provider Type、Base URL、模型能力和上下文长度配置错误。
## 配置字段 [#配置字段]
\| 字段 | 是否必填 | 说明 |
\| :--- | :--- |
\| Provider ID | 必填 | provider 的唯一标识,例如 `openai`、`anthropic`、`openrouter`,也可以手动输入自定义 provider ID |
\| Provider Name | 必填 | provider 的展示名称,选择目录中的 provider 后会自动补全 |
\| Model ID | 必填 | provider API 实际调用的模型 ID,例如 `gpt-4.1`、`claude-sonnet-4-5` |
\| Model Name | 必填 | 在 BibGenie UI 中显示的模型名称,选择目录中的模型后会自动补全 |
\| API Key | 可选 | 你的 provider 密钥;Ollama 等本地模型通常不需要 |
\| Base URL | 可选 | API 请求地址;选择目录中的 provider 后通常会自动补全,兼容服务或本地服务可能需要手动确认 |
\| Provider Type | 必填 | 模型服务类型,例如 OpenAI、Anthropic、Ollama、OpenAI Compatible |
\| Family | 可选 | 模型家族,例如 `qwen`、`gpt`、`claude`,目录模型通常会自动补全 |
\| Model Types | 必填 | 模型能力,如 Text、Vision、Reasoning、Function Calling、Web Search |
\| Context Window | 可选 | 模型上下文窗口,目录模型通常会自动补全 |
\| Max Tokens | 可选 | 单次输出上限,目录模型通常会自动补全 |
\| Description | 可选 | 模型说明,目录模型通常会自动补全 |
## Provider Type 怎么选? [#provider-type-怎么选]
| Provider Type | 适用情况 |
| :---------------- | :--------------------------- |
| OpenAI | 使用 OpenAI 官方 API |
| Anthropic | 使用 Anthropic Claude API |
| xAI | 使用 xAI Grok API |
| DeepSeek | 使用 DeepSeek 官方 API |
| Google | 使用 Gemini API |
| Groq | 使用 Groq API |
| Moonshot AI | 使用 Kimi / Moonshot API |
| OpenRouter | 使用 OpenRouter API |
| Alibaba | 通常按 OpenAI Compatible 接入 |
| Z.AI / Zhipu AI | 通常按 OpenAI Compatible 接入 |
| Ollama | 使用本地 Ollama 服务 |
| OpenAI Compatible | 使用 LM Studio、中转服务、机构内部兼容 API |
## Base URL [#base-url]
许多官方 provider 已经内置默认 Base URL。通常只有以下情况需要手动填写:
* 使用 OpenAI Compatible provider。
* 使用中转服务。
* 使用本地模型服务。
* 你的 provider 要求使用自定义 endpoint。
示例:
```text
https://api.openai.com/v1
https://openrouter.ai/api/v1
http://localhost:11434
http://localhost:1234/v1
```
很多兼容 API 需要 Base URL 以 `/v1` 结尾。如果少写版本路径,可能出现 NetworkError、404 或模型不存在。
## Ollama 示例 [#ollama-示例]
确认 Ollama 已安装并启动。
在终端运行 `ollama list`,确认本地已有模型。
如果 Ollama 尚未运行,请先执行 `ollama serve` 启动服务。启动成功后你会看到类似 `Listening on 127.0.0.1:11434` 的输出。
在 BibGenie 中添加模型,Provider Type 选择 **Ollama**。
Base URL 使用 `http://localhost:11434`。
Model ID 填写 `ollama list` 中显示的模型名,例如 `llama3.1:8b`。
## LM Studio 示例 [#lm-studio-示例]
LM Studio 通常通过 OpenAI Compatible 接入:
在 LM Studio 中启动本地 API Server。
在 BibGenie 中添加模型,Provider Type 选择 **OpenAI Compatible**。
Base URL 填写 LM Studio 显示的地址,通常类似 `http://localhost:1234/v1`。
Model ID 填写 LM Studio 当前加载模型的 ID。
## 能力标记 [#能力标记]
请根据模型真实能力勾选:
* **Text**:文本对话,通常必须开启。
* **Vision**:支持图片、截图和图表输入。
* **Reasoning**:适合复杂推理任务。
* **Function Calling**:支持工具调用,影响检索、读取和整理类任务体验。
* **Web Search**:只有 provider 和模型本身支持时才应开启。
如果错误标记模型能力,可能出现 `ModelNotSupported` 或工具调用失败。
## 常见问题 [#常见问题]
请确认模型已保存并启用。如果仍看不到,尝试重新打开 Model Settings 或重启 Zotero。
自定义模型的请求由本地 Zotero 插件直接发往你配置的 provider。请同时阅读 [Bring Your Own Key](/docs/byok) 了解数据流。
确认本地服务已启动、端口正确、Base URL 可访问,并检查防火墙或代理设置。
安全。你的 API Key 会被加密后仅保存在本地 Zotero 配置中。它会直接用于向 model provider 发起请求,**绝不会**经过 BibGenie 的服务器。
点击 Custom Models 区域的 **Reset** 按钮可以恢复所有自定义配置到初始状态。**注意:这会删除你手动添加的所有模型。**
# 错误排查 (/zh/docs/error-in-bibgenie)
在使用 BibGenie 过程中,您可能会遇到一些错误提示。本页面将帮助您快速定位问题原因并找到解决方案。
在排查问题之前,请先确认 BibGenie 已更新到最新版本。很多模型、Zotero 兼容性和网络调用问题,可能已经在新版本中修复。
错误对话框中通常会包含详细的错误信息,请仔细阅读这些信息,它们能帮助您更快地定位问题。
## ModelNotSupported [#modelnotsupported]
对话框出现以 "ModelNotSupported" 为标题的错误提示。
选择的模型不支持当前输入类型。通常发生在用户输入图片,但所选模型不支持图片输入时。
### 解决方案 [#解决方案]
### 更换支持图片的模型 [#更换支持图片的模型]
切换到支持视觉输入的模型,例如:
* GLM-4V
* GPT-4o
* Claude 3.5 Sonnet
* 其他支持 Vision 的模型
### 检查自定义模型配置 [#检查自定义模型配置]
如果您确信所选模型支持图片输入但仍出现此错误,请检查自定义模型配置是否正确将模型标记为 **Vision 模型**。
***
## AI\_APICallError [#ai_apicallerror]
对话框出现以 "AI\_APICallError" 为标题的错误提示。
模型 API 调用失败。可能的原因包括:配置错误、密钥无效、端点错误、调用超时等。
### 常见错误信息 [#常见错误信息]
密钥格式不正确或已过期时,会出现类似以下错误信息:
```text
Unauthorized Failure reason: Authentication Fails
(auth header format should be Bearer sk-...)
Model: deepseek-reasoner
Request URL: https://api.deepseek.com/v1/chat/completions
```
```text
Incorrect API key provided: ''.
You can find your API key at https://platform.openai.com/account/api-keys.
```
```text
Failure reason: [{"error":{"code":400,"message":"Missing Authorization header.","status":"INVALID_ARGUMENT"}}]
```
模型 ID 不正确或不存在时,会出现类似以下错误信息:
```text
Model Not Exist Failure reason:
{"error":{"message":"Model Not Exist","type":"invalid_request_error","param":null,"code":"invalid_request_error"}}
```
Base URL 配置不正确时,会出现类似以下错误信息:
```text
Base URL Not Found Failure reason:
{"error":{"message":"Base URL Not Found","type":"invalid_request_error","param":null,"code":"invalid_request_error"}}
```
```text
Model: deepseek-chat
Request URL: https://api.deepseek.com/v/chat/completions
```
请注意上方示例中 URL 路径错误:`/v/` 应为 `/v1/`。
### 解决方案 [#解决方案-1]
1. 进入 **llm-settings** 页面
2. 点击 **刷新** 或 **重置** 模型配置
3. 如果问题仍未解决,请在 [Discord](https://discord.gg/kDXFAAYDNE) 上联系我们
1. 进入 **自定义模型** 设置页面
2. 检查以下配置项是否正确:
* API 密钥格式和有效性
* 模型 ID 是否与服务商提供的一致
* Base URL 是否正确(注意不要遗漏版本号如 `/v1`)
***
## NetworkError [#networkerror]
对话框出现以 "Error" 为标题的错误,内容为 `TypeError: NetworkError when attempting to fetch resource.`
连接模型 API 时网络请求失败。
### 可能的原因 [#可能的原因]
使用 Ollama、LM Studio 等本地模型时:
* 模型 API 地址配置不正确
* 本地模型服务未启动
* 端口被占用或防火墙阻止
**排查步骤:**
1. 确认本地模型服务已启动
2. 在浏览器中访问模型 API 地址进行测试
3. 查阅 [Ollama](https://ollama.ai/docs) 或 [LM Studio](https://lmstudio.ai/docs) 官方文档
使用内置模型(如 OpenAI、Claude 等)时:
* 网络环境无法访问对应的 API 服务
* 代理配置不正确
**排查步骤:**
1. 检查网络代理设置是否正确
2. 尝试在浏览器中直接访问 API 端点
3. 如在中国大陆,部分服务可能需要配置代理
如果以上方案无法解决您的问题,欢迎加入我们的 [Discord 社区](https://discord.gg/kDXFAAYDNE) 获取支持。
# 快速开始 (/zh/docs/getting-started)
这篇文档会带你完成 BibGenie 的最短上手路径:下载插件、安装到 Zotero、打开侧边栏,并用一篇文献完成第一次提问。
BibGenie 支持 Zotero 7、Zotero 8、Zotero 9 和 Zotero 10。建议使用较新的 Zotero 版本,以获得更稳定的插件和阅读器体验。
## 下载插件 [#下载插件]
访问 [BibGenie 下载页面](https://www.bibgenie.com/download),下载最新版插件。
下载得到的文件通常名为:
```text
bibgenie-.xpi
```
其中 `` 是具体版本号。
## 安装到 Zotero [#安装到-zotero]
打开 Zotero,点击菜单栏 **Tools -> Plugins**。
在 Plugin Manager 窗口右上角点击齿轮图标,选择 **Install Plugin From File...**。
选择刚刚下载的 `bibgenie-.xpi` 文件。
安装完成后,重启 Zotero。
重启后,在 Zotero 右上角或工具菜单中找到 BibGenie。
## 打开 BibGenie [#打开-bibgenie]
BibGenie 支持多种打开方式:
* 点击 Zotero 右上角的 BibGenie 图标。
* 使用菜单栏 **Tools -> BibGenie**。
* 使用快捷键呼出或切换 BibGenie 侧边栏。
如果快捷键与系统或 Zotero 其他命令冲突,可以在 [Keyboard Shortcuts](https://www.bibgenie.com/zh/docs/keyboard-shortcuts) 中修改。
## 登录账户 [#登录账户]
Free 用户可以直接开始体验核心聊天和上下文能力。登录账户后,BibGenie 可以同步你的订阅状态、Credit 余额和官方模型权限。
包含核心科研能力、文献阅读,以及 OpenAlex、Web Search 和 Web Extract 等外部检索能力。
拥有更多月度 Credit,适合更高频的文献阅读、对比和科研工作流。
## 第一次提问 [#第一次提问]
推荐从一篇 PDF 开始:
在 Zotero 中选中一篇带 PDF 的文献。
初次启动时,BibGenie 默认会使用内置模型,你不需要先配置 API Key 或手动选择模型。
在 BibGenie 输入框中输入空格加 `@`,搜索并添加这篇文献,或在 Zotero 中右键选择 **Add to Chat**。
输入一个具体问题,例如:
```text
请总结这篇论文的研究问题、方法、主要发现和局限性。
```
如果回答有价值,可以点击最后一条消息的 **Save as Note**,保存到 Zotero note。
当 BibGenie 基于可追溯来源回答时,会自动添加 citation。你可以点击 citation 回到来源,核对回答依据。要了解它如何覆盖 PDF、note、snapshot、网页和 OpenAlex 结果,请阅读 [BibGenie Citation](https://www.bibgenie.com/zh/docs/bibgenie-citations)。如果你关心 PDF 中点击引用跳回原文段落的能力,请继续阅读 [段落级引用](https://www.bibgenie.com/zh/docs/paragraph-citations)。
如果你想使用自己的 API Key、本地模型或机构内部模型,可以之后再阅读 [Bring Your Own Key](https://www.bibgenie.com/zh/docs/byok) 和 [Custom Models](https://www.bibgenie.com/zh/docs/custom-models)。
尽量让问题包含目标和输出格式。例如「用 5 个要点总结」「按研究问题、方法、结果、局限输出」「生成适合写 literature review 的笔记」。
## 下一步 [#下一步]
* 学习如何添加更多类型上下文:[Add Context](https://www.bibgenie.com/zh/docs/add-context)
* 学习如何编辑、重试、Fork 和压缩对话:[管理对话](https://www.bibgenie.com/zh/docs/conversation-management)
* 理解来源追溯:[BibGenie Citation](https://www.bibgenie.com/zh/docs/bibgenie-citations)
* 理解模型选择:[Models](https://www.bibgenie.com/zh/docs/models)
* 理解套餐与 Credit:[Pricing & Credits](https://www.bibgenie.com/zh/docs/pricing-credits)
* 创建常用提示词:[Quick Prompts](https://www.bibgenie.com/zh/docs/quick-prompts)
## 更新 BibGenie [#更新-bibgenie]
BibGenie 在 Zotero 启动时会自动检查更新。检测到新版本后,BibGenie 菜单栏会出现更新按钮,点击即可安装最新版。
你也可以通过 Zotero 的 Plugin Manager 开启自动更新:
打开 Zotero,点击菜单栏 **工具 -> 插件**。
在插件列表中找到 BibGenie。
将 **Allow automatic updates** 设置为 On。之后 Zotero 会在有新版本时自动更新 BibGenie。
# 概览 (/zh/docs)
BibGenie 是运行在 Zotero 内部的 AI research agent。它不是一个独立的网页聊天工具,而是直接嵌入 Zotero 侧边栏,围绕你的文献库、PDF、网页快照、笔记和当前阅读上下文工作。
你可以把 Zotero item、PDF attachment、snapshot、note、选中的文字、当前页面内容或截图添加到对话中,然后让 AI 帮你阅读、解释、检索、整理和沉淀研究材料。
BibGenie 的核心交互发生在你的 Zotero 环境中。聊天记录和许多配置保存在本地;当你使用自定义模型或本地模型时,请求会直接发往你配置的 provider。
## 核心工作流 [#核心工作流]
从 Zotero item、PDF、snapshot、note、选中文字或截图中选择材料,让 AI 知道你正在研究什么。
让 AI 总结论文、解释图表、检索文献库、对比多篇文章,使用 OpenAlex 查询公开学术记录,或联网检索公开信息。
当回答基于可追溯来源时,BibGenie 会自动添加 citation。你可以点击 citation 回到 PDF、note、snapshot、网页或 OpenAlex 结果核对依据。了解更多:[BibGenie Citation](https://www.bibgenie.com/zh/docs/bibgenie-citations)。
使用 OpenAlex 发现 Zotero library 之外的论文、作者、期刊、引用邻居和发表趋势,并与本地已保存条目保持区分。
跨 arXiv、Semantic Scholar、OpenAlex、DBLP、OpenReview 多源检索,核验作者与期刊,补齐缺失信息并将预印本升级为正式出版物。了解更多:[元数据核对与规范化](https://www.bibgenie.com/zh/docs/metadata-review)。
把回答保存为 Zotero note,或让 AI 协助整理 tag、collection 和元信息。
## 你可以用 BibGenie 做什么 [#你可以用-bibgenie-做什么]
* 阅读论文:总结研究问题、方法、贡献、局限和未来工作。
* 精读片段:解释选中的段落、公式、图表或实验结果。
* 核对来源:使用自动添加的 [BibGenie Citation](https://www.bibgenie.com/zh/docs/bibgenie-citations) 回到 PDF、note、snapshot、网页和 OpenAlex 结果。
* 检索文献:用关键词或自然语言在 Zotero library 中找到相关文献。
* 发现外部文献:使用 OpenAlex 查找 Zotero library 之外的公开学术记录、引用关系、作者、期刊和研究趋势。
* 核对与升级元数据:跨多学术数据源核验条目信息,平滑升级 arXiv 预印本为正式期刊/会议记录,规范学术大小写与缩写,并严格保护 Better BibTeX 引文键。了解更多:[元数据核对与规范化](https://www.bibgenie.com/zh/docs/metadata-review)。
* 整理文献库:管理 tags、collections、元信息和文献移动。
* 保存笔记:把 AI 的结构化回答保存为 Zotero note。
* 管理对话:编辑最近的提问、重试回答、创建对话分支,并压缩长对话的早期上下文。
* 连接外部工具:通过本地 MCP Server 让支持 MCP 的客户端访问 Zotero 工具。
## 推荐阅读路径 [#推荐阅读路径]
**第一次使用**:阅读 [快速开始](https://www.bibgenie.com/zh/docs/getting-started),完成下载、安装、打开、登录和第一次提问。
**理解模型和 Credit**:阅读 [模型](https://www.bibgenie.com/zh/docs/models) 与 [价格与 Credit](https://www.bibgenie.com/zh/docs/pricing-credits),了解官方模型、自定义模型和 Credit 消耗。
**学习核心功能**:从 [添加上下文](https://www.bibgenie.com/zh/docs/add-context)、[管理对话](https://www.bibgenie.com/zh/docs/conversation-management)、[BibGenie Citation](https://www.bibgenie.com/zh/docs/bibgenie-citations)、[文献检索](https://www.bibgenie.com/zh/docs/literature-search)、[OpenAlex 学术检索](https://www.bibgenie.com/zh/docs/openalex-research)、[元数据核对与规范化](https://www.bibgenie.com/zh/docs/metadata-review)、[保存为笔记](https://www.bibgenie.com/zh/docs/save-as-note) 开始。
**高级配置**:如果你有自己的 API Key 或本地模型,阅读 [自带 API Key](https://www.bibgenie.com/zh/docs/byok) 和 [自定义模型](https://www.bibgenie.com/zh/docs/custom-models)。
## 文档分区 [#文档分区]
安装、模型、价格和 Credit 的基础概念。
上下文、对话管理、提示词、Zotero 检索、OpenAlex 学术检索、元数据核对、联网、库整理、笔记和 MCP。
自定义模型、MCP、Add to Chat、快捷键、引用格式和语义索引。
常见错误、模型请求失败、网络问题和 Zotero 兼容性问题。
# 快捷键 (/zh/docs/keyboard-shortcuts)
BibGenie 支持使用快捷键呼出或切换聊天侧边栏。你可以根据自己的操作习惯修改快捷键。
## 修改快捷键 [#修改快捷键]
打开 BibGenie Preferences。
找到 **Keyboard Shortcuts** 区域。
选择 modifier,例如 Ctrl + Shift 或 Command + Shift。
输入主按键,例如 `L`。
查看冲突提示并保存。
## 冲突检测 [#冲突检测]
BibGenie 会尝试检测快捷键是否与常见 Zotero 命令冲突。如果检测到冲突,设置页会提示对应命令。
如果快捷键不生效,可能原因包括:
* 与 Zotero 内置快捷键冲突。
* 与系统快捷键冲突。
* 与其他 Zotero 插件冲突。
* 当前焦点在某个输入框、弹窗或系统控件中。
* 输入法或操作系统拦截了该组合键。
## 排查建议 [#排查建议]
尝试换一个组合键,例如 Ctrl / Command + Shift + L。也可以先点击 Zotero 主窗口,再使用快捷键。
说明存在冲突。进入 Keyboard Shortcuts 设置,换一个不常用的主按键。
建议优先使用 Command + Shift 组合,符合 macOS 常见快捷键习惯。
# 文献库整理 (/zh/docs/library-management)
BibGenie 不只可以阅读文献,也可以协助整理 Zotero library。你可以让 AI 查找文献、管理 tag、创建 collection、移动 item,或编辑元信息。
批量整理会改变 Zotero library。建议先让 AI 给出整理计划或预览,再确认执行实际修改。
## 支持的整理能力 [#支持的整理能力]
| 能力 | 示例 |
| :------------- | :------------------------------------------ |
| 管理 tags | 添加、删除、列出 tags |
| 管理 collections | 创建 collection、列出 collection、移动文献 |
| 编辑元信息 | 修改 title、abstract、publication title、DOI 等字段 |
| 读取 metadata | 查看 item 的作者、年份、附件、笔记、tags |
| 文献归类 | 根据主题、方法、年份或项目移动到 collection |
如果你需要从 arXiv、Semantic Scholar、OpenAlex、DBLP、OpenReview 等多源检索补齐缺失的摘要、DOI、期刊缩写或规范大小写,请参阅专门的 [元数据审查与多源清洗](/docs/metadata-review) 文档。
## 常见任务 [#常见任务]
给选中的文献添加 `literature-review` 或项目标签。
根据研究主题创建新的 collection,并把相关文献移动进去。
找出缺失 DOI、摘要或 publication title 的文献。
把同一研究方向的文献分组整理,形成更清晰的 library 结构。
## 示例提示词 [#示例提示词]
```text
请检查我选中的这些文献,按研究主题分组,并先给出建议的 collection 结构。不要直接修改 Zotero。
```
```text
请给当前选中的文献添加 tag:deep-research 和 llm-agent。
```
```text
请找出这个 collection 中缺少 DOI 或摘要的文献,并列成表格。
```
## 推荐工作流 [#推荐工作流]
让 BibGenie 搜索或列出需要整理的候选文献。
要求 AI 先输出整理计划,包括将要修改哪些 item。
检查计划是否符合预期。
明确授权 AI 执行修改。
执行后让 AI 总结完成了哪些操作。
批量整理时,最好指定范围,例如「只处理当前选中文献」「只处理这个 collection」「不要修改元信息,只添加 tag」。
## 谨慎使用的操作 [#谨慎使用的操作]
* 大批量移动文献。
* 批量删除 tag。
* 覆盖 title、abstract、DOI 等关键元数据。
* 给大量文献创建或移动 collection。
这些操作建议分批执行,并在每次执行前要求 AI 列出将要修改的对象。
# 文献检索 (/zh/docs/literature-search)
BibGenie 默认优先在你的 Zotero library 中搜索和阅读文献,而不是直接访问互联网。这样可以让 AI 围绕你已经收集、整理和标注过的材料工作。
当你需要查找 Zotero library 之外的论文时,可以使用 [OpenAlex 学术检索](/docs/openalex-research)。OpenAlex 检索的是公开学术元数据,包括 works、authors、sources、institutions、topics、引用次数和引用关系。它不代表论文已经保存在你的 Zotero library 中。
## 三种检索方式 [#三种检索方式]
适合标题、作者、年份、DOI、tag、collection 等明确线索。
适合用自然语言描述研究主题、理论、方法或问题。
适合列出候选文献、分页查看更多结果,或查看某个范围内的 item。
## Keyword Search [#keyword-search]
关键词检索适合你已经知道一部分准确信息的情况:
* 论文标题中的关键词
* 作者名
* 年份
* DOI
* collection 名称
* tag 名称
* 期刊或会议名称
示例:
```text
帮我找 Zotero 里关于 contrastive learning 的论文。
```
```text
找一下 2022 年以后,tag 是 review 的 causal inference 文献。
```
关键词检索的优势是可控、精确、容易解释。缺点是如果你的描述和文献元数据不匹配,可能漏掉相关文献。
## Semantic Search [#semantic-search]
语义检索适合概念性问题。你不需要猜文献标题里用了什么关键词,只需要描述你想找的研究主题。
示例:
```text
找一些讨论大型语言模型如何影响学术写作规范的文献。
```
```text
我的研究关注 AI 工具对研究者知识工作的影响,请找相关论文。
```
语义检索基于本地索引的 regular item 标题和摘要。它适合发现主题相关文献,但需要注意:
* 它不是 PDF 全文检索。
* 如果文献没有摘要,匹配质量可能下降。
* 第一次使用时可能需要等待语义索引构建。
你可以在 [Semantic Index](/docs/semantic-index) 中查看索引状态。
## List Items [#list-items]
List Items 用于列出符合条件的文献或继续查看更多结果。
适合这些请求:
```text
列出这个 collection 下面最近 20 篇文献。
```
```text
继续显示更多结果。
```
```text
列出 tag 为 systematic-review 的文献,并按年份排序。
```
List Items 的价值在于让 AI 先把候选范围展示出来,再由你决定下一步读取哪些 PDF 或 note。
## 推荐工作流 [#推荐工作流]
先用语义检索找到主题相关文献。
让 AI 列出候选文献的标题、年份、作者和摘要。
选择其中几篇添加为上下文。
让 AI 阅读 PDF、比较观点、生成表格或保存为 note。
## 什么时候切换到 OpenAlex [#什么时候切换到-openalex]
如果你要处理的是已保存 item、当前选中的论文、collection、tag、note 或 PDF 附件,优先使用 Zotero library search。
如果你的目标是下面这些,适合使用 OpenAlex:
* 查找尚未保存到 Zotero 的外部论文。
* 将作者、机构、期刊、主题、出版社或资助方解析成稳定的 OpenAlex ID。
* 围绕一篇种子论文查看 citing works、cited works 或 related works。
* 按年份、来源、国家、主题、开放获取状态或其他支持字段统计公开学术记录。
需要同时使用两者时,可以要求 BibGenie 明确区分结果来源:
```text
请先在我的 Zotero library 中搜索 LLM agents 相关论文,再用 OpenAlex 查找我可能遗漏的外部论文。请把 Zotero 结果和 OpenAlex 外部结果分开。
```
加上年份、tag、collection、数量限制,会让结果更可控。例如「只看 2020 年以后」「限制在 Methods collection」「最多返回 10 篇」。
# MCP 设置 (/zh/docs/mcp-settings)
MCP Settings 用于管理 BibGenie 的本地 MCP Server。开启后,外部 MCP 客户端可以通过 Server URL 访问 BibGenie 暴露的 Zotero 工具。
## 设置项 [#设置项]
开启或关闭本地 MCP Server。
外部客户端连接 BibGenie MCP Server 时使用的地址。通常类似 `http://127.0.0.1:23119/bibgenie/mcp`,但如果 Zotero 使用自定义 HTTP Server 端口,端口可能不同。
将 Server URL 复制到剪贴板。
通过 HTTP POST JSON-RPC 发送 MCP initialize 请求,验证端点是否可达。
直接在浏览器中打开 Server URL 不等于 MCP 连接。MCP 客户端发送的是 POST JSON-RPC 请求,而浏览器地址栏发送的是 GET 请求。请使用 **Test Connection** 做真实检测。
## 状态说明 [#状态说明]
| 状态 | 含义 |
| :------------------ | :------------------ |
| Server is off | MCP Server 未开启 |
| Starting | 正在启动 |
| Server running | 已启动,可供外部客户端连接 |
| Testing connection | 正在测试连接 |
| Connection verified | 测试成功 |
| Connection failed | 测试失败,需要检查 URL 或运行状态 |
## 连接失败时检查 [#连接失败时检查]
* 确认 Zotero 正在运行。
* 确认 BibGenie 插件已在 Zotero 中启用。
* 确认 **Enable MCP Server** 已开启。
* 复制设置页显示的 Server URL,不要默认认为端口一定是 `23119`。
* 如果刚开启 Server 或刚更新插件,可以重启 Zotero 后再试。
## 开启 MCP [#开启-mcp]
进入 BibGenie Preferences。
找到 **MCP Server** 区域。
打开 **Enable MCP Server**。
等待 Server URL 出现。
点击 Copy,把 URL 粘贴到外部 MCP 客户端。
点击 Test Connection 验证可用性。
## 关闭 MCP [#关闭-mcp]
不使用外部客户端时,可以关闭 **Enable MCP Server**。关闭后,外部客户端将无法继续访问 BibGenie 的 MCP 工具。
MCP 工具可能读取或修改 Zotero library。请只把 Server URL 提供给你信任的客户端。
# MCP (/zh/docs/mcp)
MCP 是 Model Context Protocol。BibGenie 可以启动一个本地 MCP Server,让支持 MCP 的外部客户端访问 Zotero 相关工具。
如果你只在 BibGenie 插件内聊天,不需要手动配置 MCP。MCP 主要面向高级用户、外部客户端和自动化工作流。
## MCP 可以做什么? [#mcp-可以做什么]
通过 BibGenie 暴露的 Zotero 工具,外部客户端可以完成这些任务:
* 搜索 Zotero items
* 基于语义检索文献
* 读取 PDF attachment
* 读取 snapshot
* 读取 Zotero note
* 列出 tags 和 collections
* 创建 Zotero note
* 管理 tags 和 collections
* 获取或编辑 metadata
## 什么是 Zotero MCP? [#什么是-zotero-mcp]
Zotero MCP 是 BibGenie 在你的 Zotero library 和外部 AI 客户端之间建立的本地桥梁。你不需要导出文件,也不需要手动复制 metadata,支持 MCP 的外部客户端可以通过本地协议向 BibGenie 请求 Zotero 上下文。
例如,外部客户端可以通过 BibGenie 的 MCP tools 搜索你的 library、查看 collections、读取 PDF attachment,或创建 Zotero note。
## 核心优势 [#核心优势]
BibGenie 的 MCP Server 运行在 Zotero 插件内部,不需要额外安装 Python 服务或自定义本地后端。
MCP endpoint 运行在 Zotero 的本地 HTTP Server 上。外部客户端是在你的设备上和 Zotero 通信。
MCP tools 围绕 Zotero 场景设计,包括 papers、PDFs、collections、tags、notes、snapshots 和 metadata。
MCP 让 Cursor、Claude Code、Claude Desktop、Cherry Studio 等工具可以在自己的界面里使用 Zotero 上下文。
## 核心功能 [#核心功能]
| 功能 | 适合做什么 |
| :------------------- | :-------------------------------------------------------------------------------------- |
| Item search | 按 title、author、publication、keyword 或 topic 查找论文。 |
| Semantic search | 按语义发现相关论文,而不是只做关键词匹配。 |
| Metadata access | 在引用、整理或编辑前读取完整 Zotero item metadata。 |
| PDF reading | 当外部客户端需要论文内容时,读取 Zotero PDF attachment 的文本。 |
| Visual PDF reading | 当页面包含图表、版面或扫描内容时,将 PDF 页面渲染为图片供视觉检查。 |
| Notes and snapshots | 读取 Zotero notes 和 web snapshots。 |
| Library organization | 列出 collections 和 tags,创建 collections,管理 tags 或 collection membership。 |
| Metadata review | 运行只读 `review_metadata`,聚合 arXiv、Semantic Scholar、OpenAlex、DBLP、OpenReview 多源检索并提供规范化建议。 |
| Controlled writing | 可信客户端可以通过明确的 MCP tool call 创建 notes,或调用 `edit_metadata` 校验并写入元数据。 |
## 插件内聊天和 MCP 的区别 [#插件内聊天和-mcp-的区别]
| 使用方式 | 适合用户 | 是否需要配置 |
| :------------- | :------------------------ | :------- |
| BibGenie 插件内聊天 | 大多数用户 | 不需要 |
| 本地 MCP Server | 想把 Zotero 连接到外部 AI 客户端的用户 | 需要在设置中开启 |
## Server 类型和 URL [#server-类型和-url]
BibGenie 的 MCP Server 使用 **Streamable HTTP**。Server URL 通常类似:
```text
http://127.0.0.1:23119/bibgenie/mcp
```
如果你的 Zotero HTTP Server 使用了自定义端口,端口可能不是 `23119`。请优先复制 BibGenie 设置页中显示的 Server URL,不要手动猜地址。
MCP 客户端使用 HTTP POST JSON-RPC 请求连接。浏览器地址栏直接打开 Server URL 发出的是 GET 请求,不能可靠判断 MCP 是否可用。请使用 BibGenie 设置里的 **Test Connection**,或用真正的 MCP 客户端测试。
## 如何启用 MCP Server [#如何启用-mcp-server]
打开 BibGenie 设置页面。
找到 **MCP Server** 区域。
打开 **Enable MCP Server**。
复制显示出来的 Server URL。
在外部 MCP 客户端中填写该 URL。
点击 **Test Connection** 验证连接是否可用。
## 连接外部客户端 [#连接外部客户端]
在支持 Streamable HTTP MCP 的客户端中,填写 BibGenie 设置页显示的 Server URL。
### Cursor [#cursor]
Cursor 可以直接连接 BibGenie 的 Streamable HTTP endpoint。
打开 Cursor Settings,进入 **Tools & MCP**。
点击 **+ New MCP Server**。
粘贴以下配置:
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"url": "http://127.0.0.1:23119/bibgenie/mcp"
}
}
}
```
如果 BibGenie 设置页显示的端口不是 `23119`,请替换为实际 URL。
保存配置。Cursor 显示 MCP server 已连接后,就可以在 Cursor chat 中使用 Zotero 上下文。
### Claude Code [#claude-code]
Claude Code 可以直接添加 HTTP MCP Server:
```bash
claude mcp add ZoteroBibGenie --transport http http://127.0.0.1:23119/bibgenie/mcp
```
如果 BibGenie 设置页显示的端口不同,请替换为实际 URL。
### Claude Desktop [#claude-desktop]
有些 Claude Desktop 版本连接 stdio MCP Server 更稳定。此时可以用 `mcp-remote` 作为桥接,把 Claude Desktop 连接到 BibGenie 的本地 HTTP Server。
如果系统中不能使用 `node` 和 `npx`,先安装 Node.js。
打开 Claude Desktop。
打开 **Settings**,进入 **Developer** 区域。
点击 **Edit Config**,打开 `claude_desktop_config.json`。
添加以下配置:
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"command": "npx",
"args": ["mcp-remote", "http://127.0.0.1:23119/bibgenie/mcp"]
}
}
}
```
如果 BibGenie 设置页显示的端口不同,请替换配置里的 URL。
保存文件并重启 Claude Desktop。
### Cherry Studio [#cherry-studio]
Cherry Studio 可以直接连接 Streamable HTTP MCP。
打开 Cherry Studio Settings,切换到 **MCP** 标签。
点击 **Add**,选择 **Quick Create**。
填写:
* **Name**: `ZoteroBibGenie`
* **Type**: `Streamable HTTP`
* **URL**: 从 BibGenie 设置页复制的 Server URL

可选:展开 **Advanced Settings**,填写:
* **Provider URL**: `https://www.bibgenie.com/`
* **Logo URL**: `https://www.bibgenie.com/favicon.png`

点击 **Save**,开启该服务,并使用 Cherry Studio 的 verify 按钮测试连接。
## 示例 Prompt [#示例-prompt]
* “帮我找 Zotero 中 2023 年之后关于 RAG 的论文。”
* “读取这个 Zotero item 的 PDF attachment,并总结论文核心贡献。”
* “列出 Machine Learning collection 里的文献,并检查哪些条目缺少年份 metadata。”
## 安全建议 [#安全建议]
* 只把 MCP Server URL 提供给可信客户端。
* 涉及写入 Zotero library 的工具,例如创建 note、编辑 metadata、管理 tags/collections,应谨慎授权。
* 不使用 MCP 时可以关闭 Server。
* 如果外部客户端行为异常,先停止 MCP Server,再检查客户端配置。
## 常见问题 [#常见问题]
不会。插件内聊天可以直接使用 BibGenie 的内部能力。MCP 只是给外部客户端使用的本地接口。
不是。它是本地服务,运行在你的 Zotero / BibGenie 环境中。
请确认 MCP Server 已开启、URL 没有复制错误、Zotero 正在运行,并尝试点击 Test Connection。如果 Zotero HTTP Server 使用自定义端口,URL 可能不是 `23119`。
不可以。浏览器地址栏发出的是 GET 请求,而 MCP 客户端使用 POST JSON-RPC 请求。请使用 Test Connection 或外部 MCP 客户端测试。
MCP 客户端会加载并缓存 tool list。请重启外部客户端,确认 BibGenie 已更新,并重新连接 MCP Server。有些客户端只有重启应用后才会刷新工具列表。
是的,**BibGenie** 提供的 **Zotero MCP** 基础连接功能是完全免费的。你可以使用它连接任意支持 MCP 的客户端。
# 元数据审查与多源清洗 (/zh/docs/metadata-review)
元数据审查与多源清洗是 BibGenie 的重要核心能力。从各类学术网站、PDF 文件或网页抓取导入的文献,往往存在元数据残缺(缺少摘要、DOI、页码或期刊)、标题全大写、缺少标准期刊缩写、预印本转正未更新、以及顶会论文作者被截断等痛点。
BibGenie 将**大语言模型的学术理解力**与**多源权威学术数据库**相结合,提供只读审查、证据比对与可视化差异审批机制,助你高效打造整洁、规范的 Zotero 文献库。
审查过程全程只读,不会在后台静默修改你的文献库。AI 会将外部多源书目事实与清洗建议生成**可视化差异对比卡片**(展示旧值与新值),只有在你点击「批准」后才会安全写入 Zotero。
## 核心能力 [#核心能力]
联网聚合 arXiv、Semantic Scholar、OpenAlex、DBLP 与 OpenReview,自动根据 DOI、arXiv ID、DBLP Key 等线索智能路由。
支持 `lint`(格式规范)、`blank`(智能补空,默认)与 `all`(全量刷新同步),按需选择最合适的操作策略。
区别于传统机械正则替换,BibGenie 理解学术专有名词,保护 `mRNA`、`CRISPR-Cas9`、`PyTorch` 等大小写不被误伤。
提供修改前后高亮对比、类型转换字段映射警示、Better BibTeX Citation Key 保护及写入失败原子回滚。
## 支持的权威学术源 [#支持的权威学术源]
BibGenie 针对不同学术学科与发布形态,内置了多种权威学术检索通道:
| 数据源 | 覆盖领域与特色 | 适用场景 |
| :--------------------- | :-------------------------- | :------------------------------------ |
| **OpenAlex** | 全学科 2.5 亿+ 开放学术图谱 | 全科文献查找、缺失基础字段补全、引用上下文挖掘 |
| **arXiv** | 物理、计算机、数学等预印本库 | 预印本元数据获取、官方版本识别、关联正式出版 DOI |
| **DBLP** | 计算机科学权威文献库 | 计算机顶级会议/期刊元数据校准、作者消歧整理 |
| **OpenReview** | 机器学习与 AI 顶会(ICLR、NeurIPS 等) | 会议投稿状态核验、匿名作者识别与保护、相机就绪版本追踪 |
| **Semantic Scholar** | 计算机与生物医药高精度图谱 | 精准论文标识符解析、TLDR 摘要、引用关系分析 |
| **Zotero Translators** | Zotero 原生网页与出版商解析器 | 出版商官网直接解析(IEEE、ACM、Springer、Nature 等) |
## 三种审查模式 [#三种审查模式]
根据你的整理诉求,你可以让 BibGenie 采用不同的模式进行处理:
**默认模式**。联网检索权威学术库,**仅对本地为空的字段和作者列表提出补全建议**。
* 本地已有的标题、作者、年份、期刊等非空数据原样保留,绝不覆写。
* 自动补充缺失的摘要(Abstract)、页码(Pages)、DOI、期刊名称或会议论文集(Proceedings Title)。
* 适合绝大多数文献补全场景。
**本地规范化模式**。跳过外部论文事实检索,仅运行内置标准学术规则对已有字段进行体检与规范:
* 标题句式大小写规范(Sentence Case)。
* 期刊标准缩写(LTWA 与标准词典查询补齐)。
* 多语言精准检测(ISO-639-1)。
* 识别出版商域名误入条目字段并提示核验。
* 适合已有完整元数据、仅需统一书目排版格式的场景。
**全量同步模式**。联网检索外部最新元数据,**对比并对已有非空字段提出更新建议,并支持整体替换作者列表**。
* 适用于早期录入错误、从低质量网站抓取的脏数据。
* 适用于追踪预印本(Preprint)在正式发表(Journal/Conference)后的元数据更新与条目类型转换。
* *注意:不得仅因缺少部分字段而滥用 all 模式,补全缺失应使用 blank。*
## 安全性与生态保护 [#安全性与生态保护]
1. **Better BibTeX 生态无缝兼容**:
* 许多学者依赖 Better BibTeX 插件管理 LaTeX `Citation Key`。BibGenie 的 Extra 处理模块严格保护 `Citation Key:`、`tex.*`、`bibtex:` 等结构化键和自由文本,绝不删除或改写你的引用键。
2. **条目类型转换安全防护**:
* 当条目类型发生变更时(例如从 `preprint` 转为 `journalArticle`),审批卡片会以强警告明确列出可能被映射或不兼容的旧字段,用户完全知情并确认后才继续。
3. **专业术语保护(Scholarly Intelligence)**:
* 传统插件常使用机械大小写规则,导致生物化学分子、代码库或罗马数字被破坏。BibGenie 结合大模型的领域常识,智能剔除机械误伤,保持标准学术拼写。
## 典型提示词示例 [#典型提示词示例]
```text
请检查我当前选中的这篇论文,使用 blank 模式补全它缺失的摘要、页码和 DOI。
```
```text
请帮我规范选中文献的标题大小写和期刊缩写,保持专业术语原本的写法。
```
```text
这篇论文之前是 arXiv 预印本,请使用 DBLP 或 Semantic Scholar 检索它是否已经在顶会或期刊正式发表。如果有,请给出更新条目类型和元数据的建议。
```
```text
请检查这个 collection 中缺少摘要或 DOI 的文献,并帮我批量进行元数据审查与补齐。
```
## 推荐操作流程 [#推荐操作流程]
**选中条目**:在 Zotero 主界面选中一篇或多篇需要审查整理的条目,在对话框中输入 `@` 加入上下文,或直接提出要求。
**AI 运行只读审查**:BibGenie 自动调度学术数据源检索与规则分析,提取出结构化建议。
**查看可视化差异卡片**:聊天界面会弹出 **审批差异预览卡片(Action Preview)**,红绿对比展示修改前后的字段值。
**确认授权写入**:点击卡片上的「批准」按钮,修改将原子性地保存至 Zotero 条目中;如不满意可直接拒绝,文献库毫发无损。
# 模型 (/zh/docs/models)
BibGenie 中的模型分为两类:**官方模型** 和 **自定义模型**。
* 官方模型由 BibGenie 维护,开箱即用,不需要你自己配置 API Key。
* 自定义模型由你自己配置 provider、Base URL、API Key 和模型能力。
你可以在 **Model Settings** 页面统一管理这些模型。
## 官方模型 [#官方模型]
市面上有大量 AI 模型,但只有少数模型适合作为 Zotero agent 使用。BibGenie 关注的不只是模型跑分,而是它能否稳定完成科研场景中的任务:
* 长文献理解
* 多篇文献对比
* 复杂科研问题推理
* 工具调用与结构化输出
* 图表、公式、截图等多模态输入
* 在 Zotero 上下文中保持回答准确
不同提供商的配置方式也差异很大。同一个模型在不同 provider 上,可能会因为上下文长度、工具调用、限速、参数配置和网络稳定性不同,表现出完全不同的质量。
为了解决这个问题,BibGenie 做了几件事:
测试一组选定模型,重点观察它们在文献阅读、检索、整理和笔记任务中的表现。
与模型或 provider 团队讨论如何以更合适的方式运行这些模型。
与若干 provider 合作,确保模型被正确提供,并尽量减少用户配置负担。
对模型和 provider 的组合做基准测试,整理出我们认为值得推荐的官方模型列表。
## 自定义模型 [#自定义模型]
如果你有自己的 API Key,或希望使用本地模型,可以添加自定义模型。
自定义模型适合这些情况:
* 你已经购买了 OpenAI、Anthropic、DeepSeek、OpenRouter 等 provider 的 API。
* 你的机构要求请求直接发送给指定 provider。
* 你想使用 Ollama 或 LM Studio 等本地模型。
* 你需要某个官方列表中暂时没有的模型。
自定义模型的详细配置方式见 [Custom Models](/docs/custom-models)。
## 模型后面的倍率是什么意思? [#模型后面的倍率是什么意思]
你可能会在模型名称后看到类似 `0x`、`1.5x`、`2x` 的标记。
这些数字表示该模型可能消耗 Credit 的速度:
| 标记 | 含义 |
| :------- | :------------------ |
| `1x` | 标准消耗速度。 |
| `1.5x` | 相同任务下可能比标准模型消耗更快。 |
| `2x` 或更高 | 通常代表模型成本更高,适合更复杂任务。 |
倍率主要用于前端提示。真实 Credit 扣减会根据输入 token、输出 token、模型价格和工具调用情况计算。
## 刷新模型列表 [#刷新模型列表]
官方模型列表会自动刷新。你也可以手动同步:
打开 BibGenie。
进入 **Model Settings**。
在官方模型区域点击 **Refresh**。
如果你看不到某个模型,可能原因包括:
* 当前插件版本过旧。
* 模型列表尚未刷新。
* 该模型暂时下线或调整。
* 当前账户状态尚未同步。
## 如何选择模型 [#如何选择模型]
可以优先尝试低倍率的官方模型。
选择上下文能力稳定、输出质量较好的官方模型。
选择 reasoning 能力更强、上下文更长的模型。
使用 BYOK、自定义 provider、Ollama 或 LM Studio。
# OpenAlex 学术检索 (/zh/docs/openalex-research)
OpenAlex Research 是 BibGenie v0.7.0 新增的外部学术检索能力。它可以帮助你在 Zotero library 之外探索公开学术目录,例如发现新论文、查找作者或机构、分析研究趋势,以及围绕一篇已知论文扩展引用网络。
OpenAlex 返回的是外部书目信息和计量信息。它不代表论文已经存在于你的 Zotero library 中,也不能替代阅读论文正文。
所有用户都可以使用 OpenAlex 学术检索。Free 用户每次成功调用 OpenAlex 工具消耗 **1 Credit**;付费方案调用时**不额外消耗 Credit**。
## 可以做什么 [#可以做什么]
按主题、精确短语、DOI、PMID、PMCID、OpenAlex ID,以及支持的过滤和排序字段检索公开学术记录。
为作者、机构、期刊、主题、出版社和资助方查找稳定的 OpenAlex ID。
查找引用某篇论文的文献、某篇论文引用的文献,或 OpenAlex 判断相关的论文。
按发表年份、开放获取状态、国家、来源、主题等字段对结果进行分组和计数。
## 什么时候使用 OpenAlex [#什么时候使用-openalex]
当问题涉及 Zotero library 之外的公开学术记录时,适合使用 OpenAlex:
* 查找某个研究主题的新论文。
* 发现高被引的早期论文或综述论文。
* 围绕 DOI 或 OpenAlex work ID 追踪引用关系。
* 当你想做探索性覆盖,而不是只看相关性或引用数排名时,可以对匹配记录进行随机抽样。
* 比较不同年份、来源、机构、国家、主题或资助方的发表活动。
* 先解析作者、期刊、机构、出版社或资助方,再用稳定 ID 过滤论文。
如果你问的是已保存条目、当前选中的论文、collection、tag、note 或 PDF 附件,应优先使用 Zotero library search。
OpenAlex 可以帮助你发现值得关注的论文,但不会自动把论文加入 Zotero。只有在你明确要求时,BibGenie 才会继续执行导入、打标签、移动或编辑 Zotero 条目等操作。
## 使用示例 [#使用示例]
```text
请用 OpenAlex 搜索 2023 年之后关于 retrieval augmented generation 的综述论文。返回标题、年份、期刊或会议、作者、引用次数、DOI,以及每篇为什么值得看。
```
```text
请用 OpenAlex 查找 Geoffrey Hinton 关于 deep learning 的论文。先解析作者身份,再列出被引次数最高的作品,包括年份、来源、DOI 和引用次数。
```
```text
请用 OpenAlex 查看引用 10.48550/arXiv.1706.03762 的论文。重点关注 2021 年之后的论文,并说明哪些与 LLM 研究最相关。
```
```text
请用 OpenAlex 分析 2018 到 2025 年 graph neural networks 的发表趋势。按发表年份分组,并谨慎总结趋势。
```
## 推荐流程 [#推荐流程]
先用较小结果数做一次宽泛的 OpenAlex 检索。
根据需要按年份、论文类型、开放获取状态、来源、作者、机构或主题继续收窄。
对有价值的种子论文,继续查看引用它的论文、它引用的论文或相关论文。
审阅结果之后,只把真正相关的候选论文加入 Zotero。
## 好用的 Prompt 模式 [#好用的-prompt-模式]
```text
请用 OpenAlex 搜索关于 AI tools in academic writing 的论文。优先返回 2020 年之后的综述论文,最多 10 条。
```
```text
请先找到这个 DOI 的 OpenAlex 记录,然后展示它的 cited-by papers 和 related works:
10.1038/nature12373
```
```text
请在 OpenAlex 中解析 "Stanford University",然后查找该机构 2020 年以来关于 human-computer interaction 的高被引论文。
```
```text
请先在我的 Zotero library 中搜索 LLM agents 相关论文,再用 OpenAlex 查找我可能遗漏的外部论文。请把 Zotero 结果和 OpenAlex 外部结果分开。
```
## 重要限制 [#重要限制]
* OpenAlex 提供的是标题、作者、年份、来源、DOI、开放获取状态、引用次数等元数据。
* 不要把引用次数当作论文质量的直接证明。
* 不要只根据标题或摘要推断论文的方法、结论或实验结果。
* 如果需要精读,请把论文加入 Zotero 或提供可读全文,再让 BibGenie 阅读正文内容。
# 段落级引用 (/zh/docs/paragraph-citations)
在文献阅读中,一个回答“看起来对”远远不够。真正可靠的 AI 阅读助手,必须能回答一个更严格的问题:
**这句话究竟出自论文的哪个位置?**
BibGenie 的段落级引用就是为此设计的。它能把 AI 回答中的关键结论追溯到 PDF 中的具体文本块——你点击回答里的引用标记,就能直接跳回 Zotero PDF Reader,并在原文中看到对应的高亮区域。
这不是为了让回答看起来更“学术”。它的核心价值在于:AI 做出的每一个关键判断,你都可以重新检查、重新阅读、重新确认。
段落级引用让 AI 回答从“告诉你结论”升级为“指给你看证据来源”——你点击引用标记,就能直接跳回 PDF 原文中的对应段落。
## 段落级引用与常规引用有何不同 [#段落级引用与常规引用有何不同]
同样是引用,粒度不同,你能做的判断也完全不同:
| 引用粒度 | 你能知道什么 | 适合场景 | 精读时够用吗 |
| :-------- | :--------------- | :------------------ | :----------- |
| 文献级引用 | 回答大致来自哪篇论文 | 泛读、列参考文献、快速了解背景 | 太粗,只能知道来源 |
| 页级引用 | 回答大致来自 PDF 哪一页 | 快速定位某一页的整体内容 | 仍然偏粗,一页信息太多 |
| **段落级引用** | **回答对应到原文哪个文本块** | **精读、核对事实、写笔记、做综述** | **可以直接检查证据** |
文献级引用告诉你来源,页级引用帮你找到页面,**段落级引用让你直接检查证据**。
BibGenie 的重点不是只告诉你“这篇论文支持了这个回答”,而是让你亲眼看到“这段原文支持了这个回答”。对研究者来说,后者远比前者重要——你需要的不是一个现成的结论,而是能自己判断结论是否站得住脚。
## 从“给答案”到“给证据” [#从给答案到给证据]
过去用 AI 读论文,体验大多停留在“让 AI 总结一下”。
这当然有用——你可以快速了解一篇论文的大致内容、方法和结论。但在严肃的文献工作中,真正耗时的从来不是“看懂大概”,而是下面这些判断:
* 作者到底有没有明确提出这个结论?
* AI 有没有把不同段落的意思过度合并?
* 实验结果、变量定义、评价指标这些细节是否准确?
* 这句话是作者的核心主张,还是 AI 自己做的概括?
* 这个观点能否安全地写进自己的笔记、综述或论文草稿?
如果 AI 只给一段流畅的回答,你还是得回到 PDF 里搜索、翻页、定位、重读。这个过程不仅打断思路,还会让人索性放弃核对。
段落级引用把这一步省掉了。
当 BibGenie 基于 PDF 原文回答时,回答中会自动嵌入 `[1]`、`[2]` 这样的引用标记。点击标记,BibGenie 就会打开对应的 PDF,跳到相关页面,并在原文位置高亮被引用的段落。
换句话说,BibGenie 不仅告诉你“答案是什么”,还把“答案从哪里来”直接放回你的阅读现场。
## 为什么段落级引用很重要 [#为什么段落级引用很重要]
学术阅读不是浏览新闻。你不仅要得到一个结论,更要理解这个结论是如何被论文支持的。
这也是为什么越来越多 AI 研究和产品都在强调来源追溯(source attribution)、有据回答(grounded answer)和引用验证(citation verification)。AI 可以生成看起来很真的解释,也可以生成看起来很真的引用。但“看起来真”不等于“经得起核验”。
在文献场景中,可靠的引用需要同时满足三个条件:
1. **来源真实**:引用不能是编造出来的论文条目。
2. **位置明确**:引用不能只给出一整篇论文,而要指出证据的具体位置。
3. **内容匹配**:引用的原文确实能支撑 AI 刚才的说法。
你经常需要判断:
* 这个结论作者真的说过吗?
* AI 有没有把不同段落、不同实验甚至不同论文混为一谈?
* 方法细节来自正文、图注、附录,还是 AI 自己的概括?
* 这句话能放心写进笔记或论文草稿吗?
* 这条引用是不是只“看起来相关”,实际并不支持回答中的具体说法?
传统的 AI 引用通常只能告诉你“参考了哪篇论文”或“来自第几页”。泛读时这够用,但精读时远远不够——一页 PDF 里可能同时包含研究问题、方法、公式、实验设置、结果解释和局限讨论。页级引用只能告诉你“大概在这一页”,而段落级引用则把证据范围缩小到了你真正需要核对的位置。
## 为什么不是只给页码 [#为什么不是只给页码]
很多 AI 文献工具会提供页码。页码当然有用,但它不是终点。
一页学术 PDF 的信息密度非常高。尤其是双栏排版、综述文章、方法论论文和医学/工程类实验论文,一页里可能同时包含:
* 两到三个独立段落
* 一个表格或图注
* 多个公式
* 实验设置、评价指标和结果解释
* 作者对局限性的限定说明
如果 AI 说“作者认为该方法提升了泛化能力”,然后只告诉你“见第 6 页”,你仍然得自己判断它指的是实验结果段落、消融实验段落,还是 Discussion 中的解释。
段落级引用不是要取代页码,而是在页码的基础上再进一步:让你直接看到 AI 引用的那一小块证据。它特别适合处理“同一页有多个可能证据”的情况。
## 为什么不是越细越好 [#为什么不是越细越好]
你可能觉得引用越细越好——最好每个句子、每个说法都能定位。但在真实的文献阅读中,证据很少是一个孤立的句子。作者通常会先定义概念,再描述实验设置,然后在下一句解释结果。单独抽出一句话,反而可能丢失必要的上下文。
段落级引用是一个自然的折中方案:
* 比整篇论文更精确
* 比整页 PDF 更容易核对
* 比单句引用保留更多上下文
* 比多段引用更少噪音
这和研究者实际阅读论文的方式也一致——你不是只盯着一个句子读,而是读一小段,理解前后的限定条件,再判断它是否支持某个观点。
## 它能帮你做什么 [#它能帮你做什么]
点击回答中的引用标记,直接回到 Zotero PDF 原文位置,不再需要手动翻页、搜索关键词或猜测 AI 参考了哪一段。
当 AI 总结方法、结果或研究限制时,你可以立刻检查原文,判断 AI 是否忠实于论文原意。
对于理论定义、实验设置、变量解释、图表结论和作者限定条件,段落级引用比页码更贴合研究者真实的查证动作。
回答、引用标记、PDF 页面和原文高亮串联在一起,让你的追问、笔记和判断都有清晰的出处可查。
## 典型使用场景 [#典型使用场景]
认真阅读一篇论文时,可以让 BibGenie 帮你梳理研究问题、方法、实验设计、主要发现和局限。过去你可能得到一段完整的总结,但仍要回去逐一找证据。现在回答自带可点击引用,你可以逐条回到原文核对。
```text
请精读这篇论文,按「问题、方法、实验、主要发现、局限」来总结。
```
AI 擅长把复杂内容整理成流畅的表达,但流畅有时会掩盖问题。比如论文只说“在某个数据集上效果更好”,AI 可能概括成“该方法全面优于现有方法”;论文只说“作者观察到一种趋势”,AI 可能写成“作者证明了某种机制”。段落级引用让你能快速回到原文,确认 AI 的表达是否超出了作者的原意范围。
```text
请列出这篇论文中最容易被误读或过度概括的 5 个结论。
```
好的文献笔记不仅要记录“这篇论文讲了什么”,还要记录“我为什么这样理解”。段落级引用可以帮助你把 AI 生成的结构化笔记与原文证据连接起来。日后回看笔记时,你随时可以跳回当时依据的 PDF 段落,而不必重新搜索整篇论文。
```text
请把这篇论文整理成 Zotero 笔记草稿,重点保留研究问题、方法、发现和局限。
```
文献综述最怕两件事:引用不准,观点来源不清。当你对比多篇论文时,段落级引用可以让每个对比点都有出处——A 论文如何定义问题,B 论文用了什么数据集,C 论文的局限是什么。每个比较点都能跳回原文,写综述时自然能清晰区分“作者说的”“AI 总结的”和“你自己的判断”。
```text
请比较这些论文在研究问题、方法假设、实验设置和局限性上的差异。
```
方法和实验细节最不能含糊。数据集大小、基线方法、评价指标、超参数、排除标准、统计检验、消融实验——任何一个细节读错,后面的理解都会偏。段落级引用让你可以快速跳到这些细节所在的段落,检查 AI 有没有遗漏关键的限定条件。
```text
请提取这篇论文的实验设置,包括数据集、基线方法、评价指标和主要对比结果。
```
## 工作方式 [#工作方式]
BibGenie 在阅读 PDF 时,会将页面解析为结构化的文本块,每个文本块保留页码、阅读顺序和在页面上的位置信息。
当 AI 在回答中引用某个文本块时,BibGenie 将其渲染为 `[1]`、`[2]` 这样的引用标记。点击标记后,BibGenie 会:
1. 打开对应的 Zotero PDF。
2. 跳转到引用所在的页面。
3. 在原文中高亮被引用的段落或文本块。
你看到的不是“这篇论文支持了这个回答”,而是“这段原文支持了这个回答”。
## 带证据的精读流程 [#带证据的精读流程]
段落级引用帮助你建立一种“有据可查”的 AI 精读习惯:
**添加 PDF 上下文**:把 Zotero 中的 PDF attachment 添加到 BibGenie 对话,或直接围绕当前阅读的 PDF 提问。
**提出阅读问题**:比如让 BibGenie 总结方法、解释实验设计、梳理局限性,或对比多篇论文的差异。
**浏览回答框架**:先看 AI 给出的整体结构,判断它是否抓住了论文的主线。
**点击引用核对原文**:对你准备采纳的结论,点击引用标记回到 Zotero PDF 中,检查高亮段落是否真的支持该结论。
**继续追问或修正**:如果发现 AI 过度概括或遗漏了限定条件,继续追问“请基于这段原文重新表述”。
这个流程的重点不是让 AI 替你读完论文,而是让 AI 帮你更快进入可验证的精读状态。
## 局限与注意事项 [#局限与注意事项]
段落级引用显著提升了可追溯性,但它不是“自动保证正确”的魔法。使用时需要注意以下几点:
* **引用位置相关,不代表 AI 解释一定正确**:AI 可能找到了相关段落,但对段落的理解仍然可能有偏差。
* **高亮范围用于辅助定位,不等于最终引用格式**:正式写作时,仍需按照 APA、MLA、Chicago、GB/T 7714 或目标期刊要求的格式处理引用。
* **PDF 文本层质量会影响效果**:扫描件、OCR 质量差、复杂排版或公式密集的页面,可能影响文本块的解析和定位精度。
* **图表和公式需要视觉阅读**:如果问题依赖图表、扫描页面或视觉布局,建议同时提供截图或页面图像。
* **AI 不能替代你的学术判断**:段落级引用让核对更方便,但最终判断仍应以原文、研究设计和你的专业理解为准。
让 BibGenie 帮你缩小查证范围,然后由你决定这段原文是否真的支持某个结论。
## 使用建议 [#使用建议]
* 对重要结论、数据、实验设置和作者观点,养成点击引用核对原文的习惯。
* 如果 AI 的表述过于概括,可以追问“请基于引用处的原文重新表述”。
* 遇到扫描件或文本层质量差的 PDF,引用定位效果会受影响,建议同时提供页面图像。
* 正式写作时,请将 AI 回答视为阅读辅助,以论文原文为最终依据。
* 多篇论文对比时,先逐一核对单篇论文的证据,再看 BibGenie 的综合分析。
* 遇到不熟悉的术语时,先点引用读原文,再让 BibGenie 解释上下文。
* 当回答涉及因果关系、机制解释或统计结论时,务必回到引用段落,确认作者是否确实那样表述。
AI 回答中的引用标记很容易被当作“可信度徽章”。看到 `[1]`、`[2]`,人自然会觉得这句话已经有据可查了。
但更有效的习惯是:把引用当作一个入口。
点开它,回到原文,确认三件事:
1. 原文是否真的讨论了这个问题。
2. 原文的语气——是强结论、弱观察,还是假设性讨论。
3. AI 的总结有没有遗漏条件、范围或反例。
这一步看似多花几秒钟,却能显著降低“读过但没核实”的风险。尤其是在写综述、做课题汇报、整理研究假设时,这种核对直接影响后续工作的可靠性。
# 价格与 Credit (/zh/docs/pricing-credits)
BibGenie 使用 Credit 来衡量官方模型的使用额度。Credit 不是请求次数,而是模型成本额度:同样一次提问,消耗多少取决于模型、上下文长度、输出长度和工具调用情况。
所有方案都可以使用 OpenAlex、Web Search 和 Web Extract。Free 用户每次成功调用外部工具消耗 1 Credit;付费方案调用这些工具时不额外消耗 Credit,并提供更多月度 Credit。Max 提供最高月度 Credit,适合重度阅读、对比和综述生成。
## 套餐对比 [#套餐对比]
| 套餐 | 价格 | 月度 Credit | 主要能力 |
| :---------- | :-------- | :---------------- | :---------------------------------------------------------- |
| Free | $0 | 200 Credit / 月 | 核心能力 + OpenAlex、Web Search 和 Web Extract(每次成功调用消耗 1 Credit) |
| Pro Monthly | $9.99 / 月 | 10,000 Credit / 月 | Free 全部能力 + 外部工具调用不额外消耗 Credit |
| Pro Yearly | $99 / 年 | 10,000 Credit / 月 | Pro Monthly 全部能力 |
| Max Monthly | $30 / 月 | 35,000 Credit / 月 | Pro 全部能力 + 更适合论文精读、多篇对比和综述生成 |
| Max Yearly | $295 / 年 | 35,000 Credit / 月 | Max Monthly 全部能力 |
| Lifetime | $199 一次性 | 10,000 Credit / 月 | 长期享受 Pro 权益 |
价格、折扣和活动可能调整。最终价格请以官网 Pricing 页面和 Stripe Checkout 页面显示为准。
## Credit Booster [#credit-booster]
Free 和付费用户都可以额外购买 Credit 包:
| Credit 包 | 数量 | 价格 | 有效期 |
| :------- | :----------- | :---- | :--- |
| Booster | 5,000 Credit | $6.99 | 6 个月 |
## Credit 会如何消耗? [#credit-会如何消耗]
Credit 消耗主要由以下因素决定:
* 选择的模型:高成本模型通常消耗更快。
* 输入长度:添加的 PDF、note、snapshot、图片描述和历史对话越多,输入 token 越多。
* 输出长度:要求生成长综述、长表格、完整笔记时会消耗更多。
* 工具调用:检索、读取附件、联网搜索、网页提取等多步任务可能产生更多模型调用。
* **外部工具**:Free 用户每次成功调用 OpenAlex、Web Search 或 Web Extract 消耗 **1 Credit**;付费方案调用这些工具时**不额外消耗 Credit**。对话中的模型使用量单独计算。
* 模型倍率:模型名称后的 `1.5x`、`2x` 是大致消耗速度提示。
使用自定义模型、Ollama 或 LM Studio 时,请求不会通过 BibGenie 官方模型服务,因此不消耗 BibGenie Credit。相关费用或算力消耗由你自己的 provider 或本地机器承担。
## 阅读一篇文献大概需要多少 Credit? [#阅读一篇文献大概需要多少-credit]
没有固定数值。实际消耗取决于所选模型、输入上下文、输出长度和模型当前价格。你可以在 Usage 页面查看每次请求实际记录的准确扣费。
## 余额不足会发生什么? [#余额不足会发生什么]
如果你的 Credit 余额不足,官方模型请求可能无法继续完成。你可以:
* 等待下一个月度刷新。
* 升级到 Pro、Max 或 Lifetime。
* 购买 Credit Booster。
* 使用 BYOK 或本地模型。
## 如何查看余额? [#如何查看余额]
登录后,BibGenie 会同步你的账户状态和 Credit 余额。你也可以在网站账户页面或插件用户页面查看当前余额。
# 快捷提示词 (/zh/docs/quick-prompts)
Quick Prompts 是常用任务的快捷入口。你可以把经常使用的提示词保存起来,在输入框中快速插入,并结合当前上下文继续编辑。
## Quick Prompts 适合什么? [#quick-prompts-适合什么]
总结研究问题、方法、贡献、局限和未来工作。
翻译选中文本、润色英文段落、调整学术语气。
提取文献观点、生成比较表、整理 related work。
分析假设、方法缺陷、证据强度和可复现性。
## 创建快捷提示词 [#创建快捷提示词]
打开 BibGenie,进入 **Prompts Settings**。
点击添加按钮创建新的 Quick Prompt。
填写名称、提示词内容、描述和标签。
使用开关控制它是否显示在聊天页面。
保存设置后回到聊天页面使用。
## 在输入框中使用 [#在输入框中使用]
在聊天页面点击快捷提示词,或通过提示词菜单搜索并插入。插入后,它会变成当前输入的一部分,你可以继续补充上下文、修改任务要求或指定输出格式。
示例:
```text
请基于当前添加的论文,按以下结构输出:
1. 研究问题
2. 方法和数据
3. 核心发现
4. 局限性
5. 我可以如何引用这篇文章
```
## Quick Prompts 与 Custom Instructions 的区别 [#quick-prompts-与-custom-instructions-的区别]
| 类型 | 作用范围 | 适合内容 |
| :------------------ | :--------- | :------------------ |
| Quick Prompts | 当前这一次输入 | 具体任务模板,如总结、翻译、对比、提取 |
| Custom Instructions | 更长期的对话行为偏好 | 回答语言、风格、角色设定、格式偏好 |
把稳定的个人偏好放进 Custom Instructions,把具体任务流程做成 Quick Prompts。
## 系统提示词 [#系统提示词]
System Prompt 用于设定 AI 在所有对话中的全局行为。它与 Quick Prompts 不同——Quick Prompts 只影响当前输入,而 System Prompt 会对**每一轮对话**生效。
例如,将 System Prompt 设为:
```text
始终用中文回答。使用学术写作规范。
```
那么每次对话都会自动遵循这个规则,不需要反复说明。
你可以在 **Prompts Settings** 页面顶部设置一个 System Prompt。默认内容是 `Always respond in English.`,你可以根据需求改为你偏好的语言、语气或角色设定。
## Quick Prompt 配置项 [#quick-prompt-配置项]
每个 Quick Prompt 包含以下字段:
必填。启用后会作为按钮标签显示在聊天输入框上方。
必填。将发送给 AI 模型的提示词正文。
选填。用于说明该提示词用途,鼠标悬停时展示。
选填。用于分类和筛选,方便管理大量提示词。
## 推荐模板 [#推荐模板]
```text
请阅读我添加的论文,并按以下结构总结:
- 研究问题
- 核心假设
- 方法和数据
- 主要发现
- 局限性
- 对我当前研究的启发
```
```text
请解释我添加的选中文字:
- 这段话在说什么
- 涉及哪些关键概念
- 它与论文主论点有什么关系
- 如果要引用它,应该注意什么
```
```text
请从这些文献中提取可用于 literature review 的内容:
- 每篇文章的核心观点
- 文章之间的共同点和分歧
- 可归纳出的研究主题
- 仍然存在的研究空白
```
# 保存为笔记 (/zh/docs/save-as-note)
Save as Note 可以把 AI 的回答沉淀到 Zotero 中,成为可长期保存、检索和引用的研究笔记。
## 两种保存方式 [#两种保存方式]
直接对 AI 说「把上面的总结保存成这篇论文的 note」。
点击最后一条 assistant 消息上的 **Save as Note** 按钮,保存最后一条 AI 文本消息。
## 支持的内容类型 [#支持的内容类型]
BibGenie 会把 Markdown / HTML 内容转换为 Zotero note。常见支持内容包括:
* 标题和段落
* 有序列表和无序列表
* 数学公式
* 代码块
* 表格
* 引用和链接
* 加粗、行内代码等基础格式
Zotero note 有自己的编辑器和 HTML 支持范围。大多数常见格式可以保存,但极复杂的 Markdown 或自定义 HTML 可能会被简化。
## Parent item 处理逻辑 [#parent-item-处理逻辑]
保存 note 时,BibGenie 会尽量把 note 放到最合理的位置。
| 输入情况 | 保存结果 |
| :----------------------- | :---------------------------------------------------- |
| 指定 regular item | 创建为该 item 的子笔记 |
| 指定 PDF attachment | 尽量找到 attachment 的 regular parent,并挂到 parent item 下 |
| 指定 child note | 尽量找到 child note 的 regular parent,并挂到 parent item 下 |
| 没有指定 parent | 创建 standalone note |
| 同时指定 parent 和 collection | collection 会被忽略,因为 Zotero 子笔记继承父 item 的 collection 关系 |
## 示例 [#示例]
```text
请把刚才的论文总结保存为这篇文献的 Zotero note,标题为「论文总结」。
```
```text
请把上面对这几篇文献的比较整理成一篇 literature review note,并保存到 Zotero。
```
```text
请把这篇论文的方法部分整理成可复现实验步骤,并保存为 note,保留代码块和表格。
```
## 使用建议 [#使用建议]
* 保存前先让 AI 按固定结构整理内容。
* 对长对话,先要求 AI 「重新整理成一篇 note」,再保存。
* 如果需要挂到特定文献下,请明确说出目标文献。
* 如果要保存 standalone note,请说明不需要挂到某篇文献。
# 语义索引 (/zh/docs/semantic-index)
Semantic Index 是 BibGenie 语义检索的基础。它会为 Zotero regular item 的标题和摘要建立本地索引,让你可以用自然语言描述研究主题,而不是只靠关键词搜索。
## 它索引什么? [#它索引什么]
当前语义索引主要面向 Zotero regular item:
* 标题
* 摘要
* 部分可用于检索的元信息
Semantic Search 不等于 PDF 全文检索。如果一篇文献没有摘要,或者标题信息不完整,语义匹配效果可能下降。
## 状态说明 [#状态说明]
| 状态 | 含义 |
| :------------ | :--------------- |
| bootstrapping | 正在初始化索引能力 |
| indexing | 正在建立索引 |
| updating | 正在更新已有索引 |
| idle | 索引空闲,可正常检索 |
| error | 索引出现错误,需要查看提示或重试 |
## 指标说明 [#指标说明]
| 指标 | 说明 |
| :------------ | :------------- |
| Indexed Count | 已成功索引的 item 数量 |
| Failed Count | 索引失败的 item 数量 |
| Message | 当前状态或错误提示 |
## 什么时候需要关注 Semantic Index? [#什么时候需要关注-semantic-index]
* 语义检索返回结果很少。
* AI 提示 semantic index unavailable。
* 新导入大量文献后,搜索不到新文献。
* Failed Count 持续增加。
* Zotero 刚启动,索引还在 bootstrapping 或 indexing。
## 排查建议 [#排查建议]
打开 Preferences,查看 Semantic Index 状态。
如果正在 indexing 或 updating,等待任务完成。
如果有失败项,尝试重试失败索引。
检查相关文献是否有标题和摘要。
如果持续失败,重启 Zotero 后再次检查。
## 使用建议 [#使用建议]
* 给文献补全摘要,可以提升语义检索质量。
* 检索主题时使用自然语言描述,不必只输入关键词。
* 可以结合年份、tag、collection 过滤,让结果更精准。
* 找到候选文献后,再添加 PDF 或 note 让 AI 精读。
# BibGenie 如何理解你的文献库 (/zh/docs/semantic-understanding)
## 为什么需要这篇说明 [#为什么需要这篇说明]
当你在 BibGenie 里搜索文献时,你很多时候并不只是想找“包含同样关键词的论文”,而是想找“讨论相近问题、方法或主题的论文”。
这就是 **embedding** 和 **indexing** 发挥作用的地方。
## 什么是 embedding? [#什么是-embedding]
可以把 embedding 理解成一种把文本转换为“可比较表示”的方式。
它不是简单提取关键词,而是尽量保留文本的语义信息。
你不需要关心背后的数学细节,只需要理解这几点:
* 语义相近的文本,embedding 通常也更接近
* 主题差异较大的文本,embedding 通常距离更远
* 这样 BibGenie 就可以比较“意思是否相近”,而不只是比较“字面是否一样”
比如,一篇论文写的是 *knowledge graphs for drug discovery*,另一篇写的是 *graph-based methods in biomedical research*。即使它们的用词不完全相同,BibGenie 仍然可能判断它们在主题上接近。
## BibGenie 是如何使用 embedding 的? [#bibgenie-是如何使用-embedding-的]
BibGenie 当前会基于 Zotero 中 regular item 的 **标题** 和 **摘要** 来建立语义检索能力。
大致流程是这样的:
1. BibGenie 读取一篇论文的标题和摘要
2. 把这些文本转换成 embedding
3. 将结果保存到你本地文献库对应的索引中
4. 当你输入一个研究主题或问题时,BibGenie 也会把你的查询转换成 embedding
5. 然后将查询与已索引论文进行比较,返回最接近的结果
因此,BibGenie 能做的不只是关键词匹配,而是更接近“按主题找论文”。
## 什么是 indexing? [#什么是-indexing]
indexing 可以理解为“为语义检索预先做好准备”。
如果每次搜索都重新处理整个文献库,速度会很慢,也不现实。
因此 BibGenie 会先为你的文献建立一个本地索引。建立好之后,语义检索就可以更快、更稳定地工作。
可以简单记成:
* **embedding**:让 BibGenie 能表示文本的语义
* **indexing**:让 BibGenie 能快速搜索这些语义表示
## 它能帮你做什么? [#它能帮你做什么]
有了这套机制之后,BibGenie 更适合做下面这些事情:
* 按研究主题查找相关论文
* 找到“用词不同但意思相近”的论文
* 围绕某个方法、理论或研究问题做探索
* 在文献较多时更自然地搜索 Zotero 文献库
如果你知道精确标题、作者名或固定术语,关键词搜索依然很好用。
但如果你想找“这个方向上还有哪些相关工作”,语义检索通常更有帮助。
## 当前会处理哪些内容? [#当前会处理哪些内容]
BibGenie 当前主要使用:
* 论文标题
* 论文摘要
当前不会把以下内容纳入这套语义索引:
* PDF 全文
* Notes
* Annotations
* Attachments
这样做可以让索引范围更清晰,也能保持速度和稳定性。
## 我需要经常手动重建索引吗? [#我需要经常手动重建索引吗]
通常 **不需要**。
大多数情况下,BibGenie 会在后台自动处理索引更新。
当你的文献库发生变化,例如新增文献、修改条目、删除条目时,BibGenie 一般会自动完成必要的更新。
你只在少数场景下可能需要手动重建:
* 第一次启用语义索引时
* 切换到不同的 embedding model 之后
* 大批量导入文献后,如果你感觉结果还不完整或不够新
* BibGenie 明确提示当前索引需要处理时
* 语义检索结果明显异常,你希望做一次完整刷新时
如果语义检索工作正常,就通常不需要做任何操作。只有当应用提示你,或者你发现结果明显不对时,再考虑重建索引即可。
## Indexing 页面上的按钮是什么意思? [#indexing-页面上的按钮是什么意思]
### Build / Rebuild [#build--rebuild]
用于首次建立索引,或者在需要时从头重建整个索引。
适合这些情况:
* 第一次使用 indexing
* 切换了 embedding model
* 你希望完整刷新索引
### Retry Failed Items [#retry-failed-items]
它不会重建全部索引,而是只重试之前处理失败的条目。
适合这些情况:
* Failed items 数量大于 0
* 你想先做一次较轻量的修复,再考虑全量重建
## 常见问题 [#常见问题]
关键词搜索更看重字面匹配;语义检索更看重意思是否接近。所以语义检索可能会返回一些词不完全一样、但主题上确实相关的论文。
如果没有 embedding,BibGenie 很大程度上只能依赖精确词汇匹配。embedding 让它可以围绕主题、概念和语义相似性来找论文。
可能是该论文还没有完成索引,也可能是标题/摘要信息不足,或者当前索引需要更新。如果这个问题持续存在,可以尝试重建索引。
不会。正常情况下,BibGenie 会自动处理大部分索引更新。手动重建主要用于首次建立、模型切换后,或出现异常时的恢复处理。
## 下一步 [#下一步]
* 查看索引状态和排错:[Semantic Index](/docs/semantic-index)
* 了解如何在实际场景中使用语义检索:[Literature Search](/docs/literature-search)
# 联网搜索与网页提取 (/zh/docs/web-search-extract)
默认情况下,BibGenie 会优先在你的 Zotero library 中搜索和阅读。所有用户都可以使用 Web Search / Web Extract,在公开网络上补充信息。
Free 用户每次成功调用 Web Search 或 Web Extract 消耗 **1 Credit**;付费方案调用这些外部工具时**不额外消耗 Credit**。对话中模型本身的使用量仍可能按正常规则消耗 Credit。
## 两个工具的区别 [#两个工具的区别]
在公开网页中检索相关信息,并返回适合 AI 阅读的结果摘要。
读取指定网页内容,把网页正文提取出来用于回答问题。
## 什么时候需要联网? [#什么时候需要联网]
Web Search / Web Extract 适合这些场景:
* 查找某篇论文的项目主页、代码仓库或数据集页面。
* 获取最新背景信息。
* 查看模型、工具、机构或产品的公开说明。
* 补充 Zotero library 中暂时没有的信息。
* 对网页内容做总结、提取和对比。
Web 内容可能变化,也可能不准确。正式引用时,建议回到论文、官网、文档或权威来源确认。
## 如何开启 [#如何开启]
登录你的 BibGenie 账户。
在聊天输入框下方找到 **Web Search** 按钮。
点击该按钮即可开启或关闭联网搜索能力。
开启后,在对话中明确要求 BibGenie 联网检索或读取网页。
## 示例 [#示例]
```text
请联网查找这篇论文是否有官方项目主页、代码仓库或数据集页面。
```
```text
请读取这个网页,并总结其中与我的论文主题相关的部分:
https://example.com
```
```text
请在 Zotero library 检索之后,再联网查看这个领域最近是否有重要进展。
```
## 隐私提醒 [#隐私提醒]
联网工具会访问公开网页。请避免在需要联网的请求中包含敏感、未发表或受保密约束的内容。如果你的任务涉及隐私材料,建议只使用 Zotero library、本地上下文或 BYOK / 本地模型。
# Zotero 标注 (/zh/docs/zotero-annotations)
BibGenie 可以直接处理已保存的 Zotero 标注,包括高亮、评论、图片标注、墨迹标注和下划线。它既可以获取指定附件中的标注,也可以在整个文库中搜索,并在对话中保留可返回 Zotero 的引用。
## 两个标注工具 [#两个标注工具]
| 工具 | 适用场景 | 范围与筛选条件 |
| :------------------- | :------------------------ | :--------------------------------------- |
| `get_annotations` | 已知 PDF、EPUB 或 snapshot 附件 | 按阅读顺序返回该附件中的标注 |
| `search_annotations` | 需要跨文库查找标注 | 高亮文本、评论、tag、颜色、类型、作者、附件、collection 和修改时间 |
两个工具都会分页返回结果。只有确实需要更多结果时,BibGenie 才会从下一个 offset 继续获取。
`get_annotations` 接收的是附件,而不是其父级文献 item。如果你从 regular item 开始,BibGenie 会先找到对应附件,再获取其中的标注。
## 示例请求 [#示例请求]
```text
列出这个 PDF 中的高亮和评论。
```
```text
在 Literature Review collection 中查找 tag 为 methods 的黄色高亮。
```
```text
搜索我最近的标注,找出关于 sampling bias 的评论。
```
## 将已保存的标注加入对话 [#将已保存的标注加入对话]
你也可以不经过搜索,直接加入标注:
* 在 Zotero Reader 中选中一个或多个已保存标注,右键选择 **Add to Chat**。
* 在文库视图中选中 annotation item,然后选择 **Add to Chat**。
* 在 [Add to Chat 设置](/zh/docs/add-to-chat-settings)中,使用 **Reader Annotations** 控制 Reader 右键入口;**Library Items** 控制文库入口。
标注上下文会包含高亮文本、评论、类型、颜色、tag、附件身份,以及可用时的稳定引用。
标注评论属于标注作者的解释,不应被视为原始文献内容。有关引用行为,请参阅 [BibGenie 引用](/zh/docs/bibgenie-citations)。
点击对话中的标注引用,可以打开其父级附件并跳转到已保存标注。跳转精度取决于 Zotero 保存的位置数据;损坏或结构特殊的文档可能无法精确定位。
## 当前限制 [#当前限制]
* BibGenie 可以读取和搜索现有标注,但不能编辑或删除标注。
* 图片和墨迹标注可能几乎没有可检索文本。
* 已删除的标注,以及父级附件不可用的标注,不会返回。
* 如果需要更强的原文证据或上下文,请让 BibGenie 继续读取对应 PDF 页面、EPUB section 或 snapshot 内容。
# Zotero Collections 与 Tags 整理指南 (/zh/docs/zotero-collections-tags-best-practices)
Zotero 的 collections 和 tags 都能用来组织文献,但它们解决的是不同问题。一个可长期维护的 Zotero 文献库,通常不是只用 collections,也不是只用 tags,而是把 collections 用作项目或主题入口,把 tags 用作跨集合的检索维度,再用 saved searches 处理会动态变化的工作流。
如果你使用 BibGenie,这篇指南不只是“应该怎样整理”的方法论,也可以直接变成可执行的整理流程。BibGenie 的文献库整理功能可以盘点你现有的 collections、tags 和 items,再按你的研究体系提出整理计划,最后在你确认后批量创建 collections、添加或移除 tags、移动 items、重命名或合并混乱标签。
Collections 适合回答“这批文献属于哪个项目、课程、综述或主题入口?”Tags 适合回答“这篇文献有什么特征、方法、状态、对象或用途?”
Zotero 提供 collections 和 tags 这些基础组织能力;BibGenie 的文献库整理功能更像一个文献库整理助理:先理解你已有的组织方式,再提出可审核的修改计划,最后由你批准后执行。
有关 BibGenie 文献库整理功能的完整能力介绍和示例提示词,请参阅[文献库整理文档](https://www.bibgenie.com/zh/docs/library-management)。
## 快速结论 [#快速结论]
如果你刚开始整理 Zotero,可以先按下面的规则执行:
| 场景 | 推荐使用 | BibGenie 可以怎么帮 |
| :-------------------------------------- | :------------------ | :------------------------------------------- |
| 论文、课程、课题、项目、毕业论文 | Collection | 根据选中文献生成项目 collection 结构,并把文献加入对应 collection |
| 文献主题、研究方法、数据类型、地区、理论框架 | Tag | 阅读标题、摘要和元数据,建议统一的 topic/method/status tags |
| `to-read`、`read`、`important`、`reviewed` | Colored tag 或普通 tag | 批量给当前阅读任务添加或移除状态 tag |
| 最近 7 天新增、未读、缺 DOI、某标签组合 | Saved search | 帮你设计搜索条件和后续整理规则 |
| 书评与被评论的书、同一作品的不同版本 | Related items | 帮你识别可能有关联的条目,但是否建立关系仍建议人工确认 |
| 大量细碎子文件夹 | 尽量避免 | 找出过深、过碎或重复的 collections,并建议合并方案 |
## BibGenie 的文献库整理功能可以做什么 [#bibgenie-的文献库整理功能可以做什么]
在 Zotero 里手动整理 collections 和 tags 时,真正耗时的不是点击按钮,而是判断:哪些标签是重复的,哪些文献该归入哪个 collection,哪些 metadata 缺失,哪些操作会影响太多条目。BibGenie 的文献库整理功能的价值就在这里。
| 任务 | BibGenie 可以执行的动作 |
| :------------- | :--------------------------------------------------------------------- |
| 盘点现有结构 | 列出 collections 层级、tag 词表、某个 collection 或 tag 下的 items |
| 找出整理对象 | 查找 unfiled items、最近新增文献、缺 DOI/abstract 的条目、某个 tag 或 collection 下的文献 |
| 设计整理方案 | 根据标题、摘要、metadata、现有 tags 和 collections 提出分类方案 |
| 批量整理 items | 给指定文献添加/移除 tags,加入/移出 collections |
| 创建 collections | 在合适的父 collection 下创建新 collection,并可同时放入候选文献 |
| 清理 tags | 重命名 tag、把旧 tag 合并到已有 tag、删除全库无用 tag |
| 整理 collections | 重命名 collection、移动 collection、删除空或无用 collection;删除 collection 不会删除其中的文献 |
| 检查 metadata | 读取完整 metadata,识别缺失字段,并在有可靠来源时辅助修正 |
修改 metadata、创建 collection、移动 items、批量改 tags、重命名或删除 collections/tags 都属于写入操作。BibGenie 会提出操作并等待用户批准,不应该在没有明确确认的情况下直接改动 Zotero library。
一个好的 BibGenie 整理请求应该包含范围、目标和限制:
```text
Please organize the currently selected items. First read the existing collections and tags, then propose an organization plan based on titles, abstracts, and metadata.
Prefer reusing existing collections and tags; only suggest creating new ones if there is genuinely no suitable place.
Do not modify Zotero yet. First output which items will be affected, which tags will be added, and which collections will be used.
```
这个提示词背后的原则,是 BibGenie 的文献库整理功能的核心工作流:先发现现状,再识别对象,然后提出计划,最后才执行。
## Collections 是什么 [#collections-是什么]
Collections 是 Zotero 左侧栏中的集合和子集合。Zotero 官方建议把 collections 理解成“播放列表”,而不是电脑文件系统里的文件夹:同一条文献可以同时出现在多个 collections 中,但这不会复制文献本身。真正的完整库仍然是 `My Library` 或对应的 group library。
Collections 适合做“入口”。例如:
* `PhD Thesis`
* `2026 Systematic Review`
* `Course - Research Methods`
* `Project - AI Literature Review`
* `Topic - Retrieval-Augmented Generation`
这种结构的好处是清楚、可见、适合项目推进。你打开一个 collection,就能看到这一项工作当前需要的核心文献。
使用 BibGenie 时,可以让它先按项目目标给出 collection 草案,而不是直接移动文献:
```text
Please list my existing collections first, then decide whether the selected items can fit into existing collections.
If the existing structure isn't sufficient, design a one-to-two-level collection draft for my "literature review writing project."
Output each collection's purpose and the proposed items it would contain. Do not modify Zotero.
```
删除普通 collection 只会删除这个组织入口,不会删除其中的文献。要真正删除文献,需要把 item 移到 Trash。这个差异对新用户很重要。
这也是 BibGenie 删除 collection 时会明确提醒你的原因:删除 collection 只是移除组织入口,items 仍然保留在 Zotero library 中。如果某个 collection 下面还有 subcollections,BibGenie 会拒绝直接删除父 collection,并要求你先决定子 collection 如何处理。
## Tags 是什么 [#tags-是什么]
Tags 是附加在 item、attachment、note 上的文本标签。它们没有层级,但可以从多个角度描述同一篇文献。Zotero 官方文档也强调,tags 可以用于 topic、method、status、rating 或个人工作流。
Tags 适合做“维度”。例如:
* 主题:`llm-agent`、`scientific-discovery`、`citation-network`
* 方法:`survey`、`experiment`、`meta-analysis`、`case-study`
* 对象:`clinical-trial`、`graduate-students`、`zotero-users`
* 状态:`to-read`、`read`、`skimmed`、`cited`
* 用途:`intro-section`、`related-work`、`method-baseline`
Tags 的优势在于组合查询。比如你可以在一个 collection 中筛选同时带有 `llm-agent` 和 `survey` 的文献,也可以在全库里找所有 `to-read` 且属于 `citation-network` 的文献。
BibGenie 的优势是可以基于文献内容批量建议 tags。比如你可以先让它只做分析:
```text
Please list my existing tags first, then review the titles, abstracts, and existing tags of items in this collection.
Prefer reusing existing tags; only suggest new tags when no suitable one exists.
Finally, present recommended tags to keep, merge, add, and delete in a table. Do not modify Zotero.
```
## Collections vs Tags [#collections-vs-tags]
| 比较维度 | Collections | Tags |
| :--------- | :--------------------- | :---------------- |
| 组织方式 | 可以层级化,有 subcollections | 扁平化,没有原生子标签 |
| 最适合表达 | 项目、课程、论文、主题入口 | 主题、方法、状态、质量、用途等属性 |
| 一篇文献能否多处出现 | 可以 | 可以 |
| 跨库复制时是否保留 | 通常不保留 collection 位置 | 通常会随 item 复制 |
| 适合浏览 | 强 | 中等 |
| 适合交叉筛选 | 中等 | 强 |
| 后期维护风险 | collection bloat | tag 同义词和拼写漂移 |
| 推荐粒度 | 少而稳定 | 可更细,但要命名一致 |
如果你已经有 `Topic - LLM Agents` collection,就不一定需要给其中每篇文献都打 `llm-agents` 标签,除非你希望跨其他 collections 检索这个主题。
用 BibGenie 整理时,也建议把这句话当作规则写进提示词。比如:
```text
Please avoid making tags and collections fully redundant. Don't mechanically add the same tag to every item when the collection already expresses the project membership. Only add topic tags when cross-collection search is needed.
```
## 推荐的组织模型 [#推荐的组织模型]
对大多数研究者,一个稳妥的 Zotero 结构可以分成三层。
### 1. 用少量顶层 collections 管住大方向 [#1-用少量顶层-collections-管住大方向]
顶层 collections 不要太多。建议把它们设计成你长期不会频繁改名的入口:
```text
My Library
Inbox
Thesis
Papers
Projects
Topics
Teaching
Archive
```
或者更贴近研究领域:
```text
My Library
Domain - AI for Science
Domain - Bibliometrics
Domain - Human-Computer Interaction
Project - BibGenie SEO
Project - Zotero Workflow Study
```
### 2. 用一到两层 subcollections 承载项目 [#2-用一到两层-subcollections-承载项目]
Subcollections 不建议无限下钻。两层通常已经足够:
```text
Project - Systematic Review
01 Search Results
02 Screening
03 Included Studies
04 Background Reading
05 Cited in Manuscript
```
这种结构比按主题细分十几层更适合实际写作,因为它对应研究流程。
### 3. 用 tags 做可组合的横向维度 [#3-用-tags-做可组合的横向维度]
Tags 不要替代所有 collections。它们更适合记录“这篇文献还有哪些可检索属性”:
```text
method:survey
method:experiment
topic:semantic-search
topic:zotero
status:to-read
status:read
use:background
use:key-citation
```
Zotero 没有原生层级标签,但你可以用前缀模拟命名空间,例如 `method:`、`topic:`、`status:`。这样能减少歧义,也更容易在 tag selector 里扫描。
## Tags 命名规范 [#tags-命名规范]
好的 tag 系统不是越多越好,而是越一致越好。
| 规则 | 推荐 | 不推荐 |
| :---------- | :------------------ | :------------------------------------ |
| 使用小写 | `semantic-search` | `Semantic Search`、`semantic Search` |
| 用连字符分词 | `citation-network` | `citation network`、`citation_network` |
| 给类别加前缀 | `method:survey` | `survey`、`surveys` 混用 |
| 状态标签保持单一 | `status:to-read` | `unread`、`to read`、`todo` 混用 |
| 避免过宽标签 | `topic:llm-agent` | `ai`、`paper`、`research` |
| 避免过临时标签污染全库 | `use:intro-section` | `maybe-use-in-chapter-2-later` |
如果已经有重复标签,可以在 tag selector 中重命名,把旧标签改成目标标签名,从而完成合并。例如把 `to read` 改成 `status:to-read`。
如果 tags 已经混乱,可以让 BibGenie 先做一次 tag audit:
```text
Please list the current library's tags and identify potentially duplicate or synonymous tags — for example, different casing, spaces vs hyphens, singular vs plural.
Give merge suggestions and note how many items each tag affects.
Do not execute any renaming or deletion yet.
```
确认后再执行:
```text
I confirm the merge plan. Please rename the tag `to read` to `status:to-read`.
If `status:to-read` already exists, merge the two tags. Before executing, confirm how many items will be affected.
```
BibGenie 的 tag 重命名和合并不是逐篇文献循环处理,而是使用 Zotero 的全库 tag 操作。把旧 tag 重命名为一个已存在 tag 时,Zotero 会把二者合并。这比手动逐篇添加新 tag、移除旧 tag 更稳,也更适合清理长期积累出的同义标签。
## Colored Tags 应该怎么用 [#colored-tags-应该怎么用]
Zotero 支持给少量 tags 设置颜色,并可用数字键快速添加或移除。官方当前文档说明最多可以设置 9 个 colored tags。
Colored tags 最适合放“高频状态”,而不是放全部主题:
| Colored tag | 用途 |
| :----------------- | :----- |
| `status:to-read` | 待读 |
| `status:reading` | 正在读 |
| `status:read` | 已读 |
| `use:key-citation` | 关键引用 |
| `use:write-next` | 近期写作要用 |
不建议把 `machine-learning`、`history`、`statistics` 这类普通主题都设成 colored tags。主题会越来越多,而 colored tags 的位置很宝贵。
BibGenie 不能替你决定哪些 tags 应该长期占用 colored tag 位置,但它可以帮你找出最常用的状态类 tags,并建议是否合并为更少的高频标签。
## 自动标签要不要保留 [#自动标签要不要保留]
Zotero 从数据库、网页或图书馆目录保存条目时,有时会自动带入 subject headings 或 keywords。这些 automatic tags 有时有用,但也经常制造噪音:大小写不一致、粒度混乱、过于宽泛、数量膨胀。
建议策略:
1. 新库或重度整理用户:关闭自动标签,手动维护核心 tags。
2. 医学、法律、图书馆学等依赖受控词表的用户:可以先保留自动标签,再定期清理。
3. 已经积累大量自动标签的用户:先隐藏 automatic tags,确认无用后再批量删除。
关闭路径通常是 Zotero Settings / Preferences 的 General 页面,取消 `Automatically tag items with keywords and subject headings`。
如果不确定哪些 automatic tags 有价值,可以让 BibGenie 先按频次和语义分组:
```text
Please check the current library's tags and list those that may be from automatic import, overly broad, or inconsistently cased. Do not delete anything, just give cleanup suggestions.
```
## Saved Searches 是被低估的组织工具 [#saved-searches-是被低估的组织工具]
Saved searches 类似“智能 collections”。它保存的是搜索条件,不是固定结果,所以会随着文献库变化自动更新。
适合 saved searches 的场景:
* `Unread`: tag 不是 `status:read`
* `Recent Additions`: 最近 7 天添加的文献
* `Missing DOI`: DOI 为空的文献
* `Need Review`: 带有 `status:to-read` 且属于某个 collection 的文献
* `Key RAG Papers`: 同时带有 `topic:rag` 和 `use:key-citation`
如果你发现自己反复用同一组条件筛选文献,就应该考虑创建 saved search,而不是新建一个静态 collection。
BibGenie 更适合帮你设计 saved search 的规则,而不是把所有动态任务都变成 collection。例如:
```text
I want to create a dynamic view of "unread RAG papers."
Please review my existing tags and collections first, then suggest Zotero saved search criteria.
If existing tags aren't suitable, explain which tags need to be standardized first.
```
BibGenie 也可以先用类似 saved search 的思路帮你找整理对象,例如“最近 30 天新增且还没有进入任何 collection 的文献”“缺 DOI 的 journal articles”“带有旧标签但没有新标签的文献”。这类任务适合先输出候选清单,再决定是否批量修改。
## Related Items 应该怎么用 [#related-items-应该怎么用]
Related items 不适合替代 tags 或 collections。论坛讨论中也有人指出,Related 的问题是它只能说明“两条文献有关”,但不能清楚表达“为什么有关”。因此它更适合明确的一对一或少量关系:
* 书评和被评论的书
* 会议论文和扩展后的期刊论文
* 数据集论文和使用该数据集的基准论文
* 同一研究项目的预印本、正式版和勘误
* 一篇综述中反复讨论的核心源文献
如果你只是想表达“这些文献都属于同一主题”,优先用 tag 或 collection。
## 三种常见工作流 [#三种常见工作流]
### 工作流 A:写论文或综述 [#工作流-a写论文或综述]
为写作项目创建一个 collection,例如 `Project - LLM Agent Review`。
把候选文献先放入 `01 Search Results` 或 `Inbox`。
用 tags 标记主题、方法和状态,例如 `topic:tool-use`、`method:benchmark`、`status:to-read`。
筛选后把核心文献移动或加入 `03 Included Studies`。
用 `use:key-citation`、`use:intro-section`、`use:method-section` 标记写作用途。
适合配合 BibGenie 的提示词:
```text
Please examine the `Project - LLM Agent Review` collection.
First list the existing subcollections and tags, then classify the papers into five categories following a review writing workflow: search results, screening, included, background, and cited.
Prefer using existing subcollections; justify any new ones needed.
First output a table, do not move any items yet.
```
确认后再说:
```text
I confirm this classification table. Please add these items to the corresponding collections per the table, and add the `use:key-citation` tag to core papers.
After completion, summarize how many items were modified, which collections were used, and which tags were added.
```
### 工作流 B:长期积累某个研究领域 [#工作流-b长期积累某个研究领域]
建立一个长期 collection,例如 `Domain - AI for Science`。
只在真正需要时创建少量 subcollections,例如 `Foundation Papers`、`Benchmarks`、`Applications`。
用细粒度 tags 记录主题、方法、数据集、实验对象。
定期检查 `Unfiled Items`,把游离文献加入合适 collection 或删除。
适合配合 BibGenie 的提示词:
```text
Please analyze the items in `Domain - AI for Science`.
First read the existing tags, identify 5 to 8 stable research topics, and suggest corresponding `topic:` tags.
Avoid creating too many subcollections; prefer tags unless a topic will be maintained separately long-term.
```
### 工作流 C:轻量用户 [#工作流-c轻量用户]
如果你不想维护复杂体系,可以只使用最小规则:
* Collections:按项目或课程建。
* Tags:只用 5 到 15 个高频状态或主题。
* Colored tags:只标 `to-read`、`read`、`important`。
* 每月清理一次 automatic tags、duplicates 和 unfiled items。
轻量系统比复杂但没人维护的系统更可靠。
轻量用户也可以使用 BibGenie,但重点应该是“减少维护成本”,不是生成更多标签:
```text
Please classify the currently selected items into only three statuses: `status:to-read`, `status:reading`, `status:read`. If you can't determine the status, put it in `status:to-read` and show a preview first.
```
## 定期维护清单 [#定期维护清单]
建议每月做一次 Zotero library housekeeping:
* 打开 `Unfiled Items`,处理没有进入任何 collection 的文献。
* 打开 `Duplicate Items`,合并重复条目,不要直接删除其中一个。
* 检查 tag selector,合并同义标签,例如 `methods` 和 `research-methods`。
* 隐藏或删除无用 automatic tags。
* 检查最近新增文献的 title、author、year、DOI、abstract 是否干净。
* 删除已经失去意义的临时 subcollections,避免 collection bloat。
可以让 BibGenie 先列出候选文献和拟修改内容,再执行批量添加 tags、创建 collections、移动 items 或检查元数据。对任何批量修改,都建议先预览,并限制范围,例如“只处理当前选中文献”或“只处理这个 collection”。
一个稳妥的 BibGenie 月度整理提示词:
```text
Please help me with Zotero library housekeeping:
1. First list existing collections and tags.
2. Check for unfiled items, duplicate or synonymous tags, overly deep collections, and recently added unorganized items.
3. When checking items missing DOI or abstract, consider the item type to determine whether a DOI is actually expected.
4. Only output the problem list, impact scope, and suggested actions. Do not modify Zotero.
```
如果你想把 unfiled items 放入合适位置,可以进一步让 BibGenie 执行一个更具体的任务:
```text
Please find the most recent 50 unfiled items and determine which collections they best fit into based on existing collections.
Do not create new collections unless the existing structure clearly has no suitable place.
First output each item, the suggested collection, the reason, and your confidence level.
```
## 常见错误 [#常见错误]
### 错误 1:把 collections 当成唯一组织系统 [#错误-1把-collections-当成唯一组织系统]
如果每个小主题都建一个 subcollection,几年后很容易出现几十甚至上百个 collections。文献会被埋在很深的树里,找起来反而更慢。
使用 BibGenie 时,也不要让它为每个小主题都创建 collection。更好的要求是:“只有长期项目、课程、论文或稳定主题才创建 collection;细粒度概念优先使用 tags。”
### 错误 2:tags 没有命名规则 [#错误-2tags-没有命名规则]
`to read`、`ToRead`、`unread`、`todo` 如果同时存在,检索会失效。Tag 系统最怕同义词漂移。
BibGenie 可以帮你发现这些漂移,并把旧 tag 重命名到统一 tag。重命名到已有 tag 时,本质上就是一次合并操作。
### 错误 3:用 Related 表达主题归属 [#错误-3用-related-表达主题归属]
Related 更适合明确关系,不适合把一批主题相近的文献串起来。主题归属应该用 tag 或 collection。
### 错误 4:忘记 subcollection 的显示设置 [#错误-4忘记-subcollection-的显示设置]
Zotero 中,子集合里的文献默认不一定显示在父集合中。可以通过 `View -> Show Items from Subcollections` 改变显示方式。这个设置会影响你如何理解父子 collection,因此团队协作时最好统一规则。
### 错误 5:长期不处理 automatic tags [#错误-5长期不处理-automatic-tags]
自动导入的 tags 会让 tag selector 变得嘈杂。除非你明确依赖这些关键词,否则应该定期隐藏、删除或关闭自动标签。
### 错误 6:把“整理整个 library”当成一个模糊命令 [#错误-6把整理整个-library当成一个模糊命令]
“帮我整理全部文献库”听起来方便,但它通常太宽泛。BibGenie 的文献库整理功能更适合从具体痛点开始,例如:
* 最近新增但未归档的文献。
* 某个 collection 下需要继续细分的文献。
* 重复或同义 tags。
* 缺 DOI、abstract 或 publication title 的条目。
* 某个项目写作中需要标记 `use:key-citation` 的核心文献。
更好的提示词是:
```text
Please don't organize the entire library yet. Help me diagnose the 3 most pressing categories of issues: unfiled items, duplicate tags, and missing metadata. Only output the problem scope and suggested next steps.
```
### 错误 7:让 AI 填写它无法验证的 metadata [#错误-7让-ai-填写它无法验证的-metadata]
BibGenie 可以检查 metadata,也可以在有可靠来源时辅助修正 metadata,但不应该让 AI 自己编写 DOI、摘要、期刊名、作者或页码。对 metadata 写入,可靠来源应该来自 Zotero 当前 metadata、用户提供的信息、已读取的文献内容,或 BibGenie 可验证的外部引用查询结果。
好的提示词是:
```text
Please check the metadata completeness of the most recent 20 items. For entries missing a DOI or abstract, only suggest corrections when verifiable through reliable sources. Mark unverifiable items as "unconfirmed" and do not generate or guess content.
```
## 推荐模板 [#推荐模板]
你可以直接从这个模板开始:
```text
Collections
Inbox
Project - [项目名]
01 Search Results
02 To Screen
03 Included
04 Background
05 Cited
Domain - [长期主题]
Foundation Papers
Methods
Applications
Archive
Tags
status:to-read
status:reading
status:read
use:key-citation
use:intro-section
use:method-section
method:survey
method:experiment
method:case-study
topic:[主题名]
```
## 用 BibGenie 执行时的安全流程 [#用-bibgenie-执行时的安全流程]
BibGenie 可以管理 tags、collections、item 归属和部分 metadata,但文献库整理属于会改变 Zotero 数据的操作。推荐始终使用“四步法”:
先让 BibGenie 读取现有结构:collections、tags,以及本次要整理的 item 范围。
要求 BibGenie 优先复用现有 collections 和 tags;只有确实没有合适位置时才建议新建。
要求 BibGenie 输出整理计划,包括新增 tags、删除 tags、移动到哪些 collections、影响哪些 items,以及哪些操作需要批准。
人工确认后,再明确授权 BibGenie 执行;执行后要求它总结修改数量、跳过项和未完成项。
推荐提示词模板:
```text
Please organize the currently selected items. The goal is to establish clear Zotero collections and tags:
1. First list existing collections and tags.
2. Prefer reusing existing collections and tags; don't create similar names unnecessarily.
3. Determine which items should go into the same collection.
4. Then suggest consistent `topic:`, `method:`, `status:` tags.
5. Output which tags and collections will be added or removed for each item.
6. Do not modify Zotero yet; wait for my confirmation.
```
确认后:
```text
I confirm the organization plan above. Please execute these changes, then summarize how many items were modified, which tags were added, and which collections were used.
```
对于 50 篇以上的大批量操作,建议把要求写得更明确:
```text
This is a large batch organization task. First give a brief plan including which existing collections/tags will be used, whether new ones are needed, how many items will be affected, and which write operations need my approval.
After I confirm, execute in focused batches by shared purpose. Do not run one operation per item.
```
如果只是重命名、合并或删除全库 tag,不要让 BibGenie 逐篇修改 item。应该直接描述 tag 级操作:
```text
Please merge the library-wide tag `methodology` into the existing tag `method:methods`.
First confirm that both tags exist and how many items are affected, then wait for my approval.
```
如果只是重命名或移动 collection,也应该让 BibGenie 操作 collection 本身,而不是新建 collection 后再搬运全部 items:
```text
Please rename the collection `Old Thesis Reading` to `Project - Dissertation Reading`.
First list the matching collection key and its item count, wait for my confirmation, then execute.
```
## 参考资料 [#参考资料]
* [Zotero 官方文档:Collections and Tags](https://www.zotero.org/support/collections_and_tags)
* [Zotero 官方知识库:Organizing a library](https://www.zotero.org/support/kb/organizing_a_library)
* [Zotero Forums: tags and collections best practice?](https://forums.zotero.org/discussion/115437/tags-and-collections-best-practice)
* [Zotero Forums: Collections vs tags](https://forums.zotero.org/discussion/116758/collections-vs-tags)
* [Zotero Forums: best use for related, tags, collections](https://forums.zotero.org/discussion/129569/best-use-for-related-tags-collections)
* [Mastering Zotero: Working with Tags](https://pressbooks.library.yorku.ca/masteringzotero/chapter/working-with-tags/)
* [Zotero Manual: Tags](https://zotero-manual.github.io/tags/)
* [Harvard Library: Organize Your Zotero Library](https://guides.library.harvard.edu/c.php?g=1245347\&p=9129454)
* [UMGC Library: Collections & Tags](https://libguides.umgc.edu/c.php?g=930616\&p=6753118)
* [Massachusetts General Hospital: Organizing Your Library](https://libguides.massgeneral.org/zotero/organizing-library)
* [Catherine Pope: Keeping Your Zotero Library Tidy](https://catherinepope.com/posts/keeping-your-zotero-library-tidy/)
* [Reddit: Collections and Tags](https://www.reddit.com/r/zotero/comments/1izhq0m/collections_and_tags/)
# Zotero WebDAV 同步 (/zh/docs/zotero-webdav)
Zotero 同步可以让你的文献库在多台设备之间保持一致。在 Zotero 中,同步分为两部分:**数据同步**和**文件同步**。WebDAV 主要用于文件同步,也就是同步 PDF、图片、网页快照和其他附件。
WebDAV 不直接影响 BibGenie 的官方模型、Credit 或聊天能力。但如果你在多台设备上使用 Zotero,WebDAV 可以帮助附件在不同设备之间保持可用,从而影响 BibGenie 是否能读取到对应 PDF 或 snapshot。
## 数据同步与文件同步 [#数据同步与文件同步]
| 类型 | 同步内容 | 说明 |
| :--- | :------------------------------------------ | :---------------------------------- |
| 数据同步 | 文献条目、标题、作者、出版年份、笔记、标签、collection 和 metadata | Zotero 官方免费提供无限数据同步 |
| 文件同步 | PDF、图片、网页快照、音频和其他附件文件 | Zotero 官方免费文件空间为 300MB,可用 WebDAV 替代 |
要使用 Zotero 同步,通常需要先登录 Zotero 账户并开启数据同步。WebDAV 只负责附件文件,不替代 Zotero 账户的数据同步。
请先在 Zotero 首选项中登录 Zotero 账户并设置好数据同步。WebDAV 只替代文件存储部分,不替代数据同步。
## 什么是 WebDAV? [#什么是-webdav]
WebDAV 是一种让应用像访问远程文件夹一样管理服务器文件的协议。Zotero 可以使用 WebDAV 作为官方文件存储的替代方案,把附件同步到第三方云存储服务。
如果你希望在多台设备上同步 PDF 和附件,但不想购买 Zotero 官方文件存储空间,WebDAV 会很有用。
## 常见 WebDAV 服务 [#常见-webdav-服务]
| 服务商 | 免费空间 / 限制 | 网址 | 说明 |
| :---- | :---------------------- | :--------------------------------------------------------- | :----------- |
| Koofr | 初始 2GB,完成账户任务后最高可达 10GB | [https://koofr.eu/](https://koofr.eu/) | 设置简单,服务器位于欧洲 |
| 坚果云 | 免费版每月 1GB 上传流量、3GB 下载流量 | [https://www.jianguoyun.com/](https://www.jianguoyun.com/) | 中国大陆访问速度较好 |
你也可以参考 Zotero 官方知识库中的 [WebDAV Providers](https://www.zotero.org/support/kb/webdav_services)。
## 配置 Koofr WebDAV [#配置-koofr-webdav]
Koofr 是一家总部位于欧洲的云存储服务商,设置比较简单,也有面向 Zotero 的 WebDAV 支持说明。
注册 [Koofr 账号](https://koofr.eu/) 并登录 Koofr 网页版。
点击右上角头像,选择 **Preferences**。
在左侧菜单选择 **Password**,向下滚动到 **App Passwords** 区域。
输入应用名称,例如 `Zotero`,点击 **Generate**,并保存生成的密码。这个密码只显示一次。
打开 Zotero,进入 **Edit -> Preferences -> Sync**。macOS 上是 **Zotero -> Settings -> Sync**。
在 **File Syncing** 区域开启附件同步,并选择 **WebDAV**。
填写:
* **URL**:`https://app.koofr.net/dav/Koofr`
* **Username**:你的 Koofr 注册邮箱
* **Password**:刚才生成的 Koofr App Password
点击 **Verify Server**。验证成功后,点击 **OK** 保存设置。
点击 Zotero 主界面右上角的同步按钮,开始同步附件文件。
Koofr URL 中的 `Koofr` 首字母需要大写。
## 配置坚果云 WebDAV [#配置坚果云-webdav]
登录 [坚果云网页版](https://www.jianguoyun.com/)。
点击右上角账户名,进入 **账户信息**。
打开 **安全选项**。
在 **第三方应用管理** 区域点击 **添加应用**。
输入名称,例如 `Zotero`,生成密码并保存。这个密码是应用专用密码,不是坚果云登录密码。
打开 Zotero,进入 **Edit -> Preferences -> Sync**。macOS 上是 **Zotero -> Settings -> Sync**。
在 **File Syncing** 区域勾选 **Sync attachment files in My Library**,并选择 **WebDAV**。
填写:
* **URL**:`https://dav.jianguoyun.com/dav/`
* **Username**:你的坚果云账号,通常是邮箱
* **Password**:坚果云中生成的应用专用密码
点击 **Verify Server**。如果 Zotero 提示在 WebDAV 服务器上创建名为 `zotero` 的文件夹,确认即可。
坚果云常用的 WebDAV 服务器地址是 `https://dav.jianguoyun.com/dav/`。
如果你在多台电脑上使用 Zotero,请在每台电脑上配置相同的 WebDAV 设置,并确保 Zotero 数据同步也已登录同一个账户。
# Kontext hinzufügen (/de/docs/add-context)
BibGenie zeigt der KI nicht nur einen Dateinamen. Add Context bringt Zotero-Forschungsobjekte, Dokumentinhalte und deine aktuelle Leseposition in die Unterhaltung. So weiß die KI, welche Quelle du untersuchst, welchen Abschnitt du liest und welche Passage für deine Frage zählt.
Du kannst mit einem vollständigen Zotero-Eintrag beginnen und den Kontext anschließend auf eine PDF-Seite, einen EPUB-Abschnitt oder eine markierte Passage in einem PDF, EPUB oder Snapshot eingrenzen. Je näher der Kontext an deiner Frage liegt, desto gezielter ist die Antwort und desto leichter kannst du sie an der Quelle prüfen.
Add Context erfasst sowohl „Welche Quelle ist das?“ als auch „Wo lese ich gerade?“. Du kannst Einträge, Anhänge, Notizen, Sammlungen und Tags hinzufügen, ebenso die aktuelle PDF-Seite, den aktuellen EPUB-Abschnitt oder markierten Text aus dem Reader.
## Möglichkeiten, Kontext hinzuzufügen [#möglichkeiten-kontext-hinzuzufügen]
Tippe ein Leerzeichen gefolgt von `@` in das Eingabefeld, um Zotero-Einträge, Anhänge, Notizen, Tags, Sammlungen und mehr zu suchen und einzufügen.
Klicke auf die Add Context-Schaltfläche neben dem Eingabefeld, um einen Auswahldialog zu öffnen.
Füge Kontext aus Zotero-Einträgen, Sammlungen, Tags, Reader-Tabs oder markiertem Text hinzu.
Füge Bilder in das Eingabefeld ein oder nutze Zotero-seitige Screenshots für Abbildungen, Formeln und Seitenbereiche.
## Unterstützte Kontexttypen [#unterstützte-kontexttypen]
| Typ | Am besten für |
| :---------------------------------------- | :-------------------------------------------------------------------------------- |
| Normaler Eintrag | Bibliografische Metadaten, Titel, Autoren, Jahr und zugehörige Anhänge |
| PDF-Anhang | Vollständige Paper-Lektüre, Abschnittszusammenfassungen, Methoden und Ergebnisse |
| EPUB-Anhang | Vollständige Buchlektüre mit Zugriff nach logischer Seite oder Abschnitt |
| Snapshot | Lesen von in Zotero gespeicherten Webseiten |
| Notiz | Zotero-Notizen, Auszüge und Forschungsnotizen als Kontext verwenden |
| Gespeicherte Annotation | Hervorhebung, Kommentar, Farbe, Tag und Quellposition als Kontext verwenden |
| Sammlung | Mit einem Set von Papers arbeiten |
| Tag | Mit Papers unter einem bestimmten Tag arbeiten |
| Markierter Text aus PDF / EPUB / Snapshot | Präzise Erklärung einer Passage |
| Aktueller PDF-Seitenkontext | Fragen zu der Seite stellen, die du gerade liest |
| Aktueller EPUB-Abschnitt | Die aktuelle EPUB-Inhaltseinheit lesen und aus der Nachricht dorthin zurückkehren |
| Bild / Screenshot | Abbildungen, Formeln, Diagramme und Seitenbereiche analysieren |
## Kontext mit `@` hinzufügen [#kontext-mit--hinzufügen]
Tippe ein Leerzeichen gefolgt von `@` in das Eingabefeld, um das Kontext-Suchmenü zu öffnen. Du kannst dann Titel, Autor, Schlüsselwort, Notizname, Tag-Name oder Sammlungsname eingeben, um Ergebnisse zu filtern.
Häufige Beispiele:
```text
@attention is all you need
@Smith 2023
@my research note
@systematic-review
@my project collection
```
Nach der Auswahl erscheint das Ergebnis als Kontextblock im Eingabefeld. Du kannst mehrere Kontextblöcke hinzufügen, bevor du eine Frage stellst.
## Kontext aus Zotero hinzufügen [#kontext-aus-zotero-hinzufügen]
Du kannst das aktuelle Zotero-Objekt direkt zu BibGenie hinzufügen:
* Rechtsklicke einen oder mehrere Bibliothekseinträge und wähle **Add to Chat**.
* Rechtsklicke eine Sammlung im Sammlungsbaum.
* Rechtsklicke einen Tag im Tag-Selektor.
* Rechtsklicke einen PDF-, Snapshot- oder Notiz-Tab.
* Markiere Text in einem PDF, EPUB oder Snapshot und füge ihn zum Chat hinzu.
* Füge im PDF Reader die aktuelle Seite hinzu oder wähle im EPUB Reader **Add Section to Chat**, um den aktuellen Abschnitt hinzuzufügen.
Diese Einstiegspunkte können in den [Add to Chat Settings](/docs/add-to-chat-settings) aktiviert oder deaktiviert werden.
## Präzisen Kontext aus dem Reader hinzufügen [#präzisen-kontext-aus-dem-reader-hinzufügen]
BibGenie verwendet für jedes Dokumentformat eine passende Leseeinheit:
| Reader | Präziser Kontext | Geeignet für |
| :------- | :--------------------------------------- | :---------------------------------------------------------------------------- |
| PDF | Aktuelle Seite oder markierter Text | Seitenbezogene Aussagen, Abbildungen oder Passagen prüfen |
| EPUB | Aktueller Abschnitt oder markierter Text | Eine Kapiteleinheit lesen oder eine bestimmte Passage erklären |
| Snapshot | Markierter Text | Eine bestimmte Passage aus einer in Zotero gespeicherten Webseite analysieren |
Der hinzugefügte Kontext erscheint in deiner Nachricht. Wenn gültige Positionsdaten vorliegen, kannst du die Kontextkomponente anklicken, den passenden Reader erneut öffnen und zur relevanten Stelle zurückkehren.
Inhaltsverzeichnis und Dateistruktur eines EPUBs sind nicht immer deckungsgleich. Der aktuelle Abschnitt entspricht normalerweise einer XHTML-Inhaltseinheit im EPUB-Spine. Wenn mehrere untergeordnete Inhaltsverzeichniseinträge dieselbe XHTML-Datei verwenden, fügt Add Section to Chat die vollständige Inhaltseinheit hinzu, nicht nur einen einzelnen durch einen Anker begrenzten Unterabschnitt.
## Beispiele [#beispiele]
Füge ein PDF hinzu und frage:
```text
Fasse dieses Paper nach Forschungsfrage, Methode, Daten, wichtigsten Ergebnissen und Einschränkungen zusammen.
```
Füge den aktuellen Abschnitt aus dem EPUB Reader hinzu und frage:
```text
Fasse die zentrale Argumentation dieses Abschnitts zusammen und erkläre, wie sie mit dem Gesamtthema des Buches zusammenhängt.
```
Füge mehrere verwandte Paper hinzu und frage:
```text
Vergleiche diese Paper nach Annahmen, Methoden und Schlussfolgerungen. Gib eine Vergleichstabelle zurück.
```
Füge eine markierte Passage hinzu und frage:
```text
Erkläre die Logik dieser Passage und identifiziere die zentralen Begriffe.
```
Füge einen Screenshot einer Abbildung hinzu und frage:
```text
Erkläre die Achsen, Kurven und die zentrale Aussage dieser Abbildung.
```
## Tipps [#tipps]
* Füge nur den Kontext hinzu, der für die aktuelle Frage relevant ist.
* Frage bei komplexen Aufgaben zuerst nach einer Zusammenfassung und anschließend nach Details.
* Bitte BibGenie bei Vergleichen mehrerer Paper zuerst jedes Paper aufzulisten, bevor synthetisiert wird.
* Screenshots sind nützlich für Abbildungen und Formeln; füge aber das Quell-PDF oder den Eintrag hinzu, wenn du zitierfähige Fundierung brauchst.
# Add to Chat-Einstellungen (/de/docs/add-to-chat-settings)
BibGenie platziert **Add to Chat** direkt in der Zotero-Bibliothek und im Reader, also dort, wo du ohnehin arbeitest. So kannst du eine relevante Quelle oder die gerade gelesene Passage an die KI übergeben, ohne zuerst Text zu kopieren, den Anhang zu suchen und zum Chat zurückzuwechseln.
Welche Einstiegspunkte sinnvoll sind, hängt von deiner Arbeitsweise ab. Behalte PDF-Markierungen und EPUB-Abschnitte, wenn du sie häufig nutzt, oder blende seltene Aktionen aus, damit Zotero-Kontextmenüs übersichtlich bleiben.
Das Deaktivieren eines Add to Chat-Einstiegspunkts blendet normalerweise diesen Menüeintrag oder Shortcut aus. Es bedeutet nicht unbedingt, dass BibGenie diesen Kontexttyp nicht auf andere Weise hinzufügen kann.
## Verfügbare Toggles [#verfügbare-toggles]
| Einstellung | Was sie steuert |
| :---------------------- | :------------------------------------------------------------------------------------------- |
| Library Items | Zeigt Add to Chat für unterstützte Zotero-Einträge einschließlich gespeicherter Annotationen |
| Collections | Zeigt Add to Chat im Sammlungsbaum |
| Tags | Zeigt Add to Chat im Tag-Selektor |
| Reader Tabs | Zeigt Add to Chat für geöffnete PDF-, Snapshot- und Notiz-Tabs |
| PDF Text Selection | Fügt markierten PDF-Text zum Chat hinzu |
| EPUB Text Selection | Fügt markierten EPUB-Text zum Chat hinzu |
| Snapshot Text Selection | Fügt markierten Snapshot-Text zum Chat hinzu |
| Reader Annotations | Fügt gespeicherte Annotationen aus dem Reader-Kontextmenü zum Chat hinzu |
| Reader Page Context | Zeigt Add Page to Chat im PDF Reader und fügt die aktuelle Seite hinzu |
| EPUB Section Context | Zeigt Add Section to Chat im EPUB Reader und fügt den aktuellen Abschnitt hinzu |
## Was diese Einstiegspunkte hinzufügen [#was-diese-einstiegspunkte-hinzufügen]
Add to Chat arbeitet auf drei Ebenen:
Einträge, Sammlungen und Tags zeigen BibGenie, mit welchen Quellen oder Quellengruppen du arbeitest.
Reader-Tabs fügen ein PDF, einen Snapshot oder eine Notiz als Ganzes hinzu. Das eignet sich für Zusammenfassungen und Synthesen.
PDF-Seiten, EPUB-Abschnitte und markierter Text richten die Frage auf das, was du gerade liest.
Wenn der Kontext gültige Positionsdaten enthält, kannst du die Komponente in deiner Nachricht anklicken, das Dokument erneut öffnen und zur relevanten Stelle zurückkehren.
## Empfohlene Defaults [#empfohlene-defaults]
Wenn du neu bei BibGenie bist, behalte die Standardkonfiguration. Häufige Präferenzen:
Lass Library Items, Reader Tabs und die Text Selection-Einträge für deine meistgenutzten Formate aktiviert.
Lass Collections und Tags aktiviert, wenn du häufig nach Projekt, Thema oder Literaturgruppe arbeitest.
Deaktiviere seltener genutzte Einstiegspunkte, wenn deine Zotero-Kontextmenüs überladen wirken.
## Tipps [#tipps]
* Wenn du intensiv PDFs liest, aktiviere PDF Text Selection und Reader Page Context.
* Wenn du E-Books liest, aktiviere EPUB Text Selection und EPUB Section Context.
* Wenn du gespeicherte Webseiten analysierst, aktiviere Snapshot Text Selection.
* Wenn du Literaturreviews schreibst, aktiviere Collections und Tags.
* Wenn du eine minimale Einrichtung bevorzugst, behalte Library Items und das `@`-Menü im Eingabefeld.
# BibGenie-Zitat (/de/docs/bibgenie-citations)
Das BibGenie-Zitat verbindet **KI-Antworten**, **Belege in den Quellen** und **Zotero-Forschungsobjekte** in einem nachvollziehbaren System.
Wenn BibGenie auf Basis deiner Zotero-Bibliothek, PDFs, Notizen, Snapshots, Webseiten oder OpenAlex-Ergebnisse antwortet, fügt es bei Bedarf automatisch Zitiermarken wie `[1]` und `[2]` ein. Du musst nichts manuell aktivieren und dir keine besonderen Prompts merken. Wenn du eine Zitiermarke siehst, klicke darauf, um zur Quelle zurückzukehren und zu prüfen, worauf die Antwort beruht.
BibGenie unterscheidet zwei Arten von Links, die ähnlich aussehen können, aber unterschiedliche Aufgaben haben:
* Ein **Zitat** verweist auf den Beleg für eine Antwort, etwa einen Textblock oder eine Markierung in einem PDF, EPUB oder Snapshot.
* Eine **anklickbare Entität** verweist auf ein in der Antwort genanntes Zotero-Objekt, etwa einen Eintrag, Anhang, eine Notiz, Sammlung oder einen Tag. Sie hilft dir, mit diesem Objekt weiterzuarbeiten, behauptet aber nicht, dass das Objekt selbst der Beleg für einen Satz ist.
Das Ziel ist nicht, Antworten akademischer aussehen zu lassen. Das Ziel ist, dir bei diesen Einschätzungen zu helfen:
* Woher stammt diese Schlussfolgerung?
* Hat die KI die Quelle falsch gelesen oder zu stark verallgemeinert?
* Ist diese Information sicher genug für Notizen, einen Literaturreview oder einen Forschungsentwurf?
* Wenn du nachfassen möchtest: Welche Quelle solltest du erneut lesen?
Zitate führen dich zum Beleg zurück, anklickbare Entitäten zurück nach Zotero, damit du weiterarbeiten kannst. Eine Antwort kann beides enthalten.
## Zwei Arten anklickbarer Links [#zwei-arten-anklickbarer-links]
| Typ | Beantwortete Frage | Typische Ziele | Stellt einen Beleg dar? |
| :------------- | :--------------------------------------------- | :------------------------------------------------------------------------------------------------- | :---------------------- |
| Zitat | „Worauf stützt sich diese Aussage?“ | Dokumentblöcke, markierter Text, gespeicherte Annotationen, Notizen, Web- oder OpenAlex-Ergebnisse | Ja |
| Zotero-Entität | „Auf welches Objekt bezieht sich die Antwort?“ | Eintrag, Anhang, Notiz, Annotation, Sammlung oder Tag | Nein |
BibGenie kann zum Beispiel einen bestimmten EPUB-Textblock als Beleg zitieren und gleichzeitig den in der Antwort erwähnten EPUB-Anhang als anklickbares Objekt anzeigen. Mit dem ersten prüfst du die Aussage, mit dem zweiten öffnest du das Material und arbeitest weiter.
## Was es löst [#was-es-löst]
Beim Einsatz von KI in der Forschung ist das größte Risiko oft nicht, zu wenige Antworten zu bekommen. Es ist, eine flüssige Antwort zu erhalten, ohne zu wissen, woher sie kommt.
In echter Literaturarbeit musst du häufig drei Dinge auseinanderhalten:
| Typ | Bedeutung | Warum es wichtig ist |
| :----------------- | :-------------------------------------------------------------------------- | :------------------------------------------------------- |
| Originalquelle | Ein PDF, eine Notiz, ein Snapshot, eine Webseite oder ein OpenAlex-Ergebnis | Das ist die Grundlage der Antwort |
| KI-Zusammenfassung | BibGenies Verdichtung, Ordnung oder Erklärung der Quelle | Nützlich, aber weiterhin prüfenswert |
| Dein Urteil | Deine Schlussfolgerung auf Basis der Quelle und des Forschungskontexts | Das sollte Schreiben und Forschungsentscheidungen leiten |
Das BibGenie-Zitat hält die Spur zwischen diesen Ebenen klar. Es hilft dir, von einer KI-Antwort zurück zur Quelle zu gehen und dann selbst zu entscheiden, ob die Antwort verlässlich ist.
## Unterstützte Quellen [#unterstützte-quellen]
BibGenie-Zitate sind nicht nur für PDFs gedacht. Wenn du mit verschiedenen Quellen in Zotero arbeitest, können Zitate unterschiedliche Arten von Forschungsmaterial abdecken.
Wenn BibGenie ein PDF liest, können Antworten Seiten, Textblöcke oder Absatzpositionen zitieren. Für PDF-spezifische Sprünge zu Absätzen siehe [Absatzgenaue Zitate](https://www.bibgenie.com/de/docs/paragraph-citations).
Wenn BibGenie ein EPUB oder den aktuellen Abschnitt liest, können Antworten konkrete Textblöcke zitieren und dich zum relevanten Inhalt im Zotero EPUB Reader zurückbringen.
Wenn eine Antwort auf Zotero-Notizen, Exzerpten oder Forschungsnotizen beruht, helfen dir Zitate zu erkennen, aus welchem Notizinhalt die Information stammt.
Wenn BibGenie in Zotero gespeicherte Web-Snapshots liest, können Antworten Textblöcke oder gültige Markierungen zitieren und dich zum gespeicherten Webseitenmaterial zurückbringen.
Wenn du Websuche oder Web-Extraktion verwendest, können Zitate markieren, welches Suchergebnis oder welcher Webseiteninhalt für die Antwort verwendet wurde.
Wenn BibGenie die akademische Suche von OpenAlex nutzt, können Zitate auf Paper, Autorinnen und Autoren, Publikationsorte, Institutionen, Zitiernetzwerke und andere externe wissenschaftliche Metadaten verweisen.
Einträge, Anhänge, Notizen, Sammlungen und Tags können in einer Antwort als anklickbare Entitäten erscheinen. Du kannst das Zotero-Objekt direkt öffnen, ohne es mit einem Quellenbeleg zu verwechseln.
## Auch markierter Text kann zitiert werden [#auch-markierter-text-kann-zitiert-werden]
Du kannst markierten Text aus einem PDF, EPUB oder Snapshot zur Unterhaltung hinzufügen. Neben der genauen Passage erhält BibGenie bei gültigen Reader-Positionsdaten auch einen Weg zurück zur Quelle:
Markiere im Reader die Passage, die du erklären oder prüfen möchtest, und wähle **Add to Chat**.
Stelle eine Frage zur Markierung. BibGenie priorisiert die Passage, die du ausdrücklich bereitgestellt hast.
Wenn die Antwort diese Markierung zitiert, klicke auf das Zitat, um das Dokument erneut zu öffnen und zur relevanten Stelle zurückzukehren. In unterstützten Fällen wie PDFs hilft eine temporäre Hervorhebung, die Quelle schnell zu finden.
Markierter Text kann weiterhin als Gesprächskontext verwendet werden. Wenn die gespeicherte Position jedoch fehlt, beschädigt ist oder sich nicht sicher auflösen lässt, erzeugt BibGenie kein Zitat, das anklickbar aussieht, aber nicht zur Quelle zurückführen kann.
## Wie Dokumentzitate präzise bleiben [#wie-dokumentzitate-präzise-bleiben]
Beim Lesen von PDFs, EPUBs und Snapshots ordnet BibGenie den Dokumentinhalt in Textblöcke mit stabilen Kennungen. Eine Antwort zitiert den Block, der eine Aussage tatsächlich stützt, statt pauschal den gesamten Anhang als Quelle anzugeben.
Das hat drei praktische Vorteile:
* Ein Klick auf das Zitat führt eher zur relevanten Seite, zum Abschnitt oder zur genauen Fundstelle.
* Wenn mehrere Anhänge gemeinsam analysiert werden, erkennst du, welches Material welche Aussage stützt.
* Wenn du eine Antwort kopierst oder als Zotero-Notiz speicherst, behalten die Zitate lesbare Quellenangaben.
## Wobei Zitate dir helfen [#wobei-zitate-dir-helfen]
Klicke bei wichtigen Schlussfolgerungen, Daten, Methodenbeschreibungen und Autorenaussagen auf ein Zitat, um zur Quelle zurückzukehren und zu bestätigen, dass das Material die Antwort wirklich stützt.
Wenn eine Antwort nützlich ist, bringen dich Zitate zurück zum relevantesten PDF, zur passenden Notiz, zum Snapshot oder zum Webinhalt, damit du weiterlesen kannst.
Wenn du Forschung in Notizen überführst, bewahren Zitate die Spur von der Zusammenfassung zurück zur Quelle, damit du den Beleg später nicht erneut suchen musst.
Wenn du lokale Zotero-Einträge, Webseiten und OpenAlex-Ergebnisse kombinierst, helfen dir Zitate, Belege aus deiner lokalen Bibliothek von externen Suchergebnissen zu unterscheiden.
## Typische Anwendungsfälle [#typische-anwendungsfälle]
Du kannst BibGenie bitten, Forschungsfrage, Methode, Versuchsdesign, Ergebnisse und Limitationen eines Papers zusammenzufassen. Zitate in der Antwort helfen dir, zum Paper zurückzukehren und zentrale Aussagen zu prüfen.
Wenn du mehr über PDF-Zitate erfahren möchtest, die zum genauen Quellabsatz springen, lies [Absatzgenaue Zitate](https://www.bibgenie.com/de/docs/paragraph-citations).
Füge den gesamten EPUB-Anhang oder den aktuellen Abschnitt hinzu und bitte BibGenie, eine Argumentation zusammenzufassen, einen Begriff zu erklären oder Kapitel zu vergleichen. Die Zitate in der Antwort verweisen auf die tatsächlich verwendeten EPUB-Textblöcke, während die Abschnittskomponente in deiner Nachricht zur hinzugefügten Leseposition zurückführt.
Markiere Text in einem PDF, EPUB oder Snapshot und füge ihn zur Unterhaltung hinzu, um die Frage auf eine Passage zu konzentrieren. Wenn die Markierung gültige Positionsdaten enthält, können dich Zitate in der Antwort zum ursprünglichen Kontext zurückbringen.
Wenn du Exzerpte, Lesenotizen oder Forschungsideen in Zotero gespeichert hast, kann BibGenie sie thematisch ordnen. Zitate helfen dir zu erkennen, aus welcher Notiz eine Zusammenfassung stammt, statt alles zu einer nicht nachvollziehbaren Antwort zu verschmelzen.
Wenn du eine Projekt-Homepage, Datensatzbeschreibung, Tool-Dokumentation oder Nachrichtenseite als Zotero-Snapshot speicherst, kann BibGenie sie lesen und Quellen mit Zitaten markieren. Wenn du Websuche oder Web-Extraktion nutzt, zeigen dir Zitate außerdem, welche Webseiten die Antwort beeinflusst haben.
OpenAlex liefert externe wissenschaftliche Metadaten wie Titel, Autorinnen und Autoren, DOI, Publikationsorte, Zitierzahlen und Zitierbeziehungen. Zitate helfen dir, eine Antwort zu einem konkreten OpenAlex-Ergebnis zurückzuverfolgen und externe Suchmetadaten nicht so zu behandeln, als hätte BibGenie das vollständige Paper gelesen.
Du kannst lokale PDFs, Zotero-Notizen, OpenAlex-Ergebnisse und Webmaterial in einem Workflow kombinieren. Zitate helfen dir zu unterscheiden, welche Teile einer synthetisierten Antwort aus gespeicherter Literatur stammen und welche aus externem unterstützendem Material.
## Wie du Zitate liest [#wie-du-zitate-liest]
BibGenie-Antworten enthalten oft Zitiermarken wie `[1]` und `[2]`. Behandle sie als Einstiegspunkte zur Quelle.
**Antwortstruktur lesen**: Prüfe zuerst, ob BibGenie den Hauptpunkt deiner Frage verstanden hat.
**Wichtige Aussagen finden**: Konzentriere dich auf Schlussfolgerungen, die du übernehmen, speichern, zitieren oder für Rückfragen verwenden könntest.
**Zitat anklicken**: Kehre zum relevanten PDF, zur Notiz, zum Snapshot, zur Webseite oder zur OpenAlex-Quelle zurück.
**Quellinhalt prüfen**: Bestätige, ob die Quelle die Aussage stützt, und achte dabei auf Reichweite, Wortlaut und Kontext.
**Nachfassen oder verfeinern**: Wenn die Antwort zu breit ist, bitte BibGenie, sie auf Basis der zitierten Quelle neu zu formulieren.
## Zitate vs. formale Referenzen [#zitate-vs-formale-referenzen]
Das BibGenie-Zitat ist vor allem für **Lesen, Prüfen und Quellenrückverfolgung** gedacht. Es ist nicht das endgültige Referenzformat für eine Arbeit.
| Element | BibGenie-Zitat | Formale Referenz |
| :-------------- | :----------------------------------------------- | :-------------------------------------------------------------------------- |
| Hauptzweck | Zur Quelle hinter einer KI-Antwort zurückkehren | Formatvorgaben einer Arbeit, eines Berichts oder einer Zeitschrift erfüllen |
| Wo es erscheint | In BibGenie-Chatantworten | Im Textkörper und Literaturverzeichnis eines Dokuments |
| Fokus | Quellenrückverfolgung, Belegprüfung, Weiterlesen | Zitierstil, Publikationsmetadaten, Formatierung |
| Abgabefertig | Nicht als formales Zitat empfohlen | Muss im erforderlichen Stil erzeugt und geprüft werden |
Wenn du eine wissenschaftliche Arbeit, Hausarbeit, Förderanfrage oder einen formalen Bericht schreibst, solltest du weiterhin Zotero-Zitierstile wie APA, MLA, Chicago, GB/T 7714 oder das von deiner Zielpublikation geforderte Format verwenden.
Das BibGenie-Zitat dient dazu zu prüfen, woher eine Antwort stammt. Für formales Schreiben gehe zurück zum Zotero-Eintrag und zur Originalquelle und verwende dann das erforderliche Referenzformat.
## Warum manche Antworten kein Zitat haben [#warum-manche-antworten-kein-zitat-haben]
Nicht jeder Satz bekommt ein Zitat. Häufige Gründe sind:
* **Die Frage ist operativ**: Zum Beispiel kann "hilf mir, diese Sammlung zu organisieren" eher nächste Schritte liefern als eine Quellenpassage zitieren.
* **Die Antwort ist synthetisiert**: Manche Zusammenfassungen kombinieren mehrere Quellen und lassen sich nicht sauber auf ein einzelnes Zitat abbilden.
* **Die Quelle ist nicht klar genug**: Wenn die Eingabe kein nachvollziehbares Material enthält, gibt BibGenie möglicherweise nur allgemeine Orientierung.
* **Externe Web- oder Metadaten sind begrenzt**: OpenAlex- und Webergebnisse sind oft Zusammenfassungen oder Metadaten, keine Volltextlektüre.
* **Dokumentstruktur oder Textqualität beeinflussen das Parsing**: Gescannte PDFs, schwache OCR, komplexe Layouts, Abweichungen zwischen Inhaltsverzeichnis und Spine eines EPUBs oder ungewöhnliche Snapshot-Strukturen können die Zitierpositionierung beeinflussen.
Wenn eine wichtige Aussage kein Zitat hat, kannst du einfach nachfragen, woher diese Schlussfolgerung stammt oder welches Paper, welche Notiz oder welche Webseite sie stützt. Das Zitat selbst wird weiterhin automatisch hinzugefügt, wann immer BibGenie die Quelle zurückverfolgen kann.
## Empfehlungen [#empfehlungen]
* Verlasse dich bei wichtigen Schlussfolgerungen nicht nur auf die KI-Zusammenfassung. Klicke auf Zitate und prüfe die Quelle.
* Wenn ein Zitat auf ein PDF, EPUB oder einen Snapshot verweist, lies den nahen Kontext statt nur den hervorgehobenen Text.
* Wenn ein Zitat aus OpenAlex stammt, denke daran, dass es meist wissenschaftliche Metadaten darstellt, keine Volltextlektüre.
* Wenn ein Zitat aus dem Web stammt, denke daran, dass Webinhalte sich ändern können. Für formale Nutzung bestätige sie auf der Originalseite oder in einer anderen autoritativen Quelle.
* Behalte beim Schreiben von Literaturnotizen die automatisch erzeugten Zitate, damit du die Quelle später erneut prüfen kannst.
* Kopiere das BibGenie-Zitat nicht direkt in formale Arbeiten. Verwende Zotero, um Standardreferenzen zu erzeugen.
* Wenn eine Antwort kein Zitat hat, frage: "Worauf basiert diese Schlussfolgerung?" oder "Aus welchem Paper, welcher Notiz oder welcher Webseite stammt sie?"
## Beziehung zu absatzgenauen Zitaten [#beziehung-zu-absatzgenauen-zitaten]
Das BibGenie-Zitat ist das umfassendere Konzept. Es deckt PDFs, Notizen, Snapshots, Webseiten, OpenAlex und andere nachvollziehbare Quellen ab. Es beantwortet:
**Woher stammt die Information in dieser KI-Antwort?**
[Absatzgenaue Zitate](https://www.bibgenie.com/de/docs/paragraph-citations) sind eine spezifischere und leistungsfähigere PDF-Lesefunktion. Sie beantworten:
**Kann diese PDF-basierte Schlussfolgerung zum genauen Absatz im Originalpaper springen?**
Wenn dir vor allem genaues PDF-Lesen, Originaltext-Hervorhebungen und das Springen aus Zitaten zurück in den Zotero PDF Reader wichtig sind, lies weiter bei [Absatzgenaue Zitate](https://www.bibgenie.com/de/docs/paragraph-citations).
Das BibGenie-Zitat ist der Überblick: Es gibt Antworten Quellen. Absatzgenaue Zitate sind die PDF-Nahlese-Hervorhebung: Sie lassen PDF-Antworten zurück zu Quellabsätzen springen.
# Eigene API-Schlüssel (BYOK) (/de/docs/byok)
BYOK bedeutet Bring Your Own Key. Damit kannst du deinen eigenen Modellanbieter, API-Schlüssel oder ein lokales Modell mit BibGenie verwenden.
## Warum BYOK verwenden? [#warum-byok-verwenden]
Anfragen an eigene Modelle gehen direkt vom lokalen Zotero-Plugin an den von dir konfigurierten Provider.
Führe Modelle mit Ollama oder LM Studio auf deinem eigenen Rechner aus.
BYOK-Anfragen nutzen nicht den offiziellen Modelldienst von BibGenie und verbrauchen daher keine BibGenie-Credits.
Verwende Modelle, die derzeit nicht in der offiziellen Liste enthalten sind.
## Laufen Daten durch den BibGenie-Dienst? [#laufen-daten-durch-den-bibgenie-dienst]
Wenn du ein eigenes Modell hinzufügst, laufen Anfragedaten nicht durch den Modelldienst von BibGenie. Das lokale Zotero-Plugin sendet Anfragen direkt an den von dir konfigurierten Provider.
Das bedeutet:
* OpenAI API key: Anfragen gehen direkt an OpenAI.
* Anthropic API key: Anfragen gehen direkt an Anthropic.
* OpenAI-kompatibler Proxy: Anfragen gehen an die von dir eingegebene Base URL.
* Ollama oder LM Studio: Anfragen können vollständig auf deinem Rechner bleiben.
BYOK umgeht den Modelldienst von BibGenie, aber Cloud-Provider erhalten weiterhin die Inhalte, die du an sie sendest. Wähle Provider entsprechend den Datenrichtlinien deiner Institution, deines Labs oder deines Projekts.
## Unterstützte Provider [#unterstützte-provider]
BibGenie unterstützt mehrere Provider-Typen:
| Provider | Hinweise |
| :---------------- | :------------------------------------ |
| OpenAI | OpenAI GPT-Modelle |
| Anthropic | Claude-Modelle |
| xAI | Grok-Modelle |
| DeepSeek | DeepSeek-Modelle |
| Google | Gemini-Modelle |
| Groq | Von Groq gehostete Modelle |
| Moonshot AI | Kimi-Modelle |
| OpenRouter | Einheitliche Modell-Routing-Plattform |
| Ollama | Lokaler Modelldienst |
| OpenAI Compatible | Jede OpenAI-kompatible API |
LM Studio wird normalerweise über **OpenAI Compatible** konfiguriert.
## Wann BYOK gut passt [#wann-byok-gut-passt]
* Du hast bereits einen Provider-API-Schlüssel.
* Du möchtest die Abrechnung des Providers über dein eigenes Konto laufen lassen.
* Du musst einen institutionellen Modelldienst verwenden.
* Du möchtest Anfragen am offiziellen Modelldienst von BibGenie vorbeileiten.
* Du möchtest sensibles Material mit einem lokalen Modell verarbeiten.
* Du brauchst ein Modell, das noch nicht in der offiziellen Liste ist.
## Nächster Schritt [#nächster-schritt]
Lies [Custom Models](/docs/custom-models), um einen Provider hinzuzufügen, Base URL und API-Schlüssel einzugeben und die Verbindung zu testen.
# Zitationsformat (/de/docs/citation-format)
Citation Format legt fest, wie BibGenie Zotero-Einträge im Chat-Kontext anzeigt. Besonders sichtbar ist das beim Eintragskontext, der erscheint, nachdem du `@` in das Eingabefeld eingibst.
## Was beeinflusst wird [#was-beeinflusst-wird]
* Die Anzeige von Einträgen in `@`-Suchergebnissen.
* Die Anzeige von Einträgen, nachdem sie zum Chat-Kontext hinzugefügt wurden.
* Die zitiationsähnliche Darstellung, die BibGenie als Kontext erhält.
Citation Format ändert nur die Anzeige. Titel, Autorinnen und Autoren, Jahr, Journal oder andere Zotero-Metadaten werden nicht bearbeitet.
## CSL-Stil auswählen [#csl-stil-auswählen]
BibGenie verwendet die in Zotero installierten CSL-Stile. Den Standard-CSL-Stil wählst du in den Einstellungen unter **Citation Format**.
Häufige Stile sind:
* APA
* Chicago
* MLA
* IEEE
* Nature
* Vancouver
## Wann du es ändern solltest [#wann-du-es-ändern-solltest]
Wähle den Stil, den dein Fachgebiet, Journal oder Manuskript verlangt.
Autor-Jahr-Stile lassen sich in Sozial- und Geisteswissenschaften oft leichter überfliegen.
Nummerierte Stile passen häufig gut zu Engineering, Informatik oder IEEE-orientierten Workflows.
## FAQ [#faq]
BibGenie liest die in Zotero installierten CSL-Stile. Installiere oder aktiviere den Stil zuerst in Zotero.
Nein. Diese Einstellung betrifft hauptsächlich die Chat-Kontextanzeige in BibGenie.
# Unterhaltungen verwalten (/de/docs/conversation-management)
BibGenie bewahrt jede Unterhaltung als Forschungspfad auf, den du korrigieren, fortsetzen oder verzweigen kannst. Du kannst deine letzte Frage überarbeiten, eine Antwort neu generieren, von einer früheren Antwort aus eine separate Unterhaltung beginnen und bei langen Verläufen älteren Kontext komprimieren.
Überarbeite die letzte Nutzernachricht, die sich sicher bearbeiten lässt, und sende sie erneut.
Lass BibGenie die letzte Antwort auf Grundlage desselben vorherigen Kontexts erneut erzeugen.
Beginne von einer abgeschlossenen Antwort aus eine separate Unterhaltung, ohne den ursprünglichen Pfad zu verlieren.
Fasse ältere Inhalte zusammen und behalte aktuelle Nachrichten für die nächste Modellanfrage bei.
## Letzte Frage bearbeiten [#letzte-frage-bearbeiten]
Bewege den Mauszeiger über die letzte bearbeitbare Nutzernachricht und wähle **Edit**. Nachdem du sie überarbeitet und erneut gesendet hast, setzt BibGenie die aktuelle Unterhaltung mit der aktualisierten Frage fort.
Beim Bearbeiten wird alles ersetzt, was im aktuellen Pfad auf die ausgewählte Nachricht folgt. Die vorherige Antwort und davon abhängige nachgelagerte Zustände gehören anschließend nicht mehr zu diesem Pfad. Wenn du die ursprüngliche Forschungsrichtung behalten möchtest, [verzweige die Unterhaltung zuerst](#unterhaltung-verzweigen).
Während die KI antwortet, ein Werkzeug ausgeführt wird oder eine Freigabe aussteht, kann die Bearbeitung vorübergehend nicht verfügbar sein.
## Antwort neu generieren [#antwort-neu-generieren]
Wenn die letzte Antwort nicht deinen Erwartungen entspricht, wähle darunter **Retry**. BibGenie behält den vorherigen Kontext bei und generiert diese Antwort erneut.
Retry ersetzt die ursprüngliche Antwort im aktuellen Pfad. Wenn ein nachgelagerter Komprimierungseintrag von dieser Antwort abhängt, wird auch dieser ungültig. Beim nächsten Senden bewertet BibGenie den Kontext erneut.
Wenn du beide Ergebnisse behalten möchtest, erstelle zuerst einen Zweig von der ursprünglichen Antwort und verwende Retry anschließend in einer der Unterhaltungen.
## Unterhaltung verzweigen [#unterhaltung-verzweigen]
Fork erstellt ausgehend von einer abgeschlossenen Antwort eine neue Unterhaltung. Bewege den Mauszeiger über eine geeignete Assistentenantwort, wähle **Fork** und bestätige den Vorgang. BibGenie erstellt und öffnet daraufhin die neue Unterhaltung.
```text
Ursprünglich: Frage 1 → Antwort 1 → Frage 2 → Antwort 2
│
Neuer Zweig: └→ Neue Frage → Neue Antwort
```
Der Zweig übernimmt die ausgewählte Antwort und den gesamten vorherigen Kontext. Ab diesem Punkt entwickeln sich beide Unterhaltungen unabhängig voneinander: Senden, Bearbeiten oder Retry in einer Unterhaltung überschreibt keine späteren Nachrichten in der anderen.
Fork eignet sich beispielsweise, um:
* Verschiedene Interpretationen oder Hypothesen zu demselben Artikel zu untersuchen.
* Prompts, Modelle oder Analyseansätze zu vergleichen.
* Ein Ergebnis zu sichern, bevor du einen Vorgang ausprobierst, der den weiteren Verlauf verändern könnte.
Nur stabile, vollständig abgeschlossene Assistentenantworten können als Ausgangspunkt für Fork dienen. Warte, bis die aktuelle Antwort, der Werkzeugaufruf oder die Freigabe abgeschlossen ist, und versuche es dann erneut.
## Lange Unterhaltungen komprimieren [#lange-unterhaltungen-komprimieren]
Jedes Modell verfügt nur über ein begrenztes Kontextfenster. Wenn sich Nachrichten, Artikel, Bilder und Werkzeugergebnisse ansammeln, nähert sich die Unterhaltung diesem Limit. BibGenie kann ältere Gesprächsteile zu einem kompakten Kontext zusammenfassen und zugleich aktuelle Nachrichten für die weitere Arbeit beibehalten.
Der BibGenie Agent komprimiert eine Unterhaltung in der Regel automatisch, sobald dies erforderlich ist. Sofern du älteren Kontext nicht ausdrücklich sofort komprimieren möchtest, kannst du einfach weiterfragen, ohne Compact selbst auszuwählen.
### Automatische Komprimierung [#automatische-komprimierung]
BibGenie prüft den verfügbaren Kontext zu folgenden Zeitpunkten:
* Vor dem Senden einer neuen Nachricht: Wenn die geplante Anfrage an das Modelllimit heranreicht, komprimiert BibGenie zunächst älteren Kontext und sendet deine Nachricht anschließend automatisch.
* Nach Abschluss eines Durchlaufs: Wenn die Kontextnutzung den Komprimierungsschwellenwert erreicht hat, komprimiert BibGenie ältere Inhalte im Hintergrund.
Automatische und manuelle Komprimierung verwenden dieselbe Fortschrittsanzeige. Löst das Senden einer Nachricht die Komprimierung aus, wird die wartende Nachricht nach erfolgreichem Abschluss automatisch gesendet. Du musst sie nicht erneut absenden.
### Manuelle Komprimierung [#manuelle-komprimierung]
Wenn du die aktuelle Unterhaltung ausdrücklich sofort komprimieren möchtest, bewege den Mauszeiger über die Anzeige **Context Window** unten rechts im Eingabebereich und wähle das Komprimierungssymbol oben rechts in der Karte. Während des Vorgangs erscheint in der Unterhaltung **Compacting earlier context…**. Du kannst den Text im Eingabebereich weiter bearbeiten oder vor Abschluss **Cancel** wählen.
### Komprimierte Zusammenfassung prüfen [#komprimierte-zusammenfassung-prüfen]
Nach der Komprimierung erscheint in der Unterhaltung der Trenner **Earlier context compacted**. Klappe ihn auf, um Folgendes einzusehen:
* Die Zusammenfassung früherer Gesprächsteile.
* Die Anzahl der Kontext-Tokens vor der Komprimierung.
* Das für die Komprimierung verwendete Modell und dessen Kontextfenster.
Der Trenner wird nicht wie eine normale Nutzerfrage behandelt, und spätere Antworten reagieren nicht direkt darauf. Vor jeder Modellanfrage kombiniert BibGenie die neueste Zusammenfassung mit den beibehaltenen aktuellen Nachrichten zum wirksamen Kontext.
## Zusammenspiel der Aktionen [#zusammenspiel-der-aktionen]
| Aktion | Auswirkung auf die aktuelle Unterhaltung | Erstellt eine Unterhaltung | Ruft das Modell auf |
| :------ | :------------------------------------------------------------------------------------ | :------------------------: | :------------------: |
| Edit | Ersetzt die ausgewählte Nutzernachricht und alles danach im aktuellen Pfad | Nein | Beim erneuten Senden |
| Retry | Ersetzt die letzte wiederholbare Antwort und ihren nachgelagerten Zustand | Nein | Ja |
| Fork | Bewahrt das Original und erstellt ab der ausgewählten Antwort einen unabhängigen Pfad | Ja | Nein |
| Compact | Fasst älteren Kontext zusammen und behält aktuelle Nachrichten bei | Nein | Ja |
Wenn ein Vorgang eine weiterhin benötigte Antwort ersetzen könnte, verzweige die Unterhaltung zuerst.
## Wenn eine Aktion nicht verfügbar ist [#wenn-eine-aktion-nicht-verfügbar-ist]
Edit, Retry, Fork oder Compact können vorübergehend nicht verfügbar sein, wenn:
* BibGenie eine Antwort generiert.
* Ein Werkzeugaufruf noch läuft oder auf deine Freigabe wartet.
* Die Unterhaltung gerade komprimiert wird oder eine gesendete Nachricht auf den Abschluss wartet.
* Die ausgewählte Nachricht nicht an einer Position liegt, die sich sicher bearbeiten oder verzweigen lässt.
* Der gespeicherte Verlauf beschädigt ist und die Unterhaltung schreibgeschützt geöffnet wurde.
Schließe den laufenden Vorgang ab oder brich ihn ab und versuche es danach erneut. Wird eine Unterhaltung schreibgeschützt geöffnet, bewahrt BibGenie den sicher darstellbaren Verlauf und verändert die ursprünglich gespeicherten Daten nicht.
# Eigene Modelle (Custom Models) (/de/docs/custom-models)
Custom Models ermöglichen dir, deinen eigenen API-Schlüssel, Drittanbieter-Provider, lokales Modell oder institutionellen Modelldienst zu verwenden. Nach der Konfiguration sendet BibGenie Anfragen direkt vom lokalen Zotero-Plugin an den von dir gewählten Provider.
## Modell hinzufügen [#modell-hinzufügen]
Öffne BibGenie und gehe zu
**Model Settings**
.
Klicke im Bereich Custom Models auf
**Add Model**
.
Wähle oder gib eine
**Provider ID**
ein. BibGenie lädt häufige Provider aus einem Modellkatalog und füllt Provider Name, Provider Type und Base URL nach Möglichkeit automatisch aus.
Wähle oder gib eine
**Model ID**
ein. Wenn das Modell im Katalog existiert, füllt BibGenie Model Name, Family, Model Types, Context Window, Max Tokens und Description automatisch aus.
Gib deinen API Key ein. Für lokale Dienste wie Ollama ist normalerweise kein API-Schlüssel erforderlich.
Klicke auf
**Test**
, um die Verbindung zu prüfen. Ein erfolgreicher Test zeigt
**Connected**
. Wenn der Test fehlschlägt, zeigt BibGenie die Provider-Fehlermeldung, damit du die Konfiguration korrigieren kannst.
Prüfe die automatisch ausgefüllten Felder und passe Model Types, Context Window oder Max Tokens bei Bedarf an.
Klicke auf
**Add Model**
. Das Modell wird gespeichert, aktiviert und ist anschließend im Chat-Modellauswahlschalter verfügbar.
## Auto-Fill-Verhalten [#auto-fill-verhalten]
Ein eigenes Modell hinzuzufügen ist nicht vollständig manuell. BibGenie lädt Provider- und Modellinformationen aus dem `models.dev`-Katalog, wenn verfügbar:
* Provider ID unterstützt das Suchen häufiger Provider und die manuelle Eingabe eigener Provider.
* Die Auswahl eines Providers kann Provider Name, Provider Type und Base URL automatisch ausfüllen.
* Model ID wird nach dem ausgewählten Provider gefiltert und unterstützt sowohl Katalogmodelle als auch eigene Modell-IDs.
* Die Auswahl eines Katalogmodells kann Model Name, Family, Model Types, Context Window, Max Tokens, Description und Preismetadaten automatisch ausfüllen.
* Wenn der Modellkatalog nicht geladen werden kann, verwendet BibGenie eine eingebaute Fallback-Providerliste; du kannst Modelle weiterhin manuell hinzufügen.
Wenn dein Provider und Modell in den Such-Dropdowns erscheinen, wähle sie aus, statt alles manuell einzugeben. Das reduziert Fehler bei Provider Type, Base URL, Modellfähigkeiten und Kontextlimits.
## Felder [#felder]
| Feld | Erforderlich | Beschreibung |
| :------------- | :----------- | :----------------------------------------------------------------------------------------------------------------------------------------- |
| Provider ID | Erforderlich | Eindeutige Providerkennung, etwa `openai`, `anthropic` oder `openrouter`; eigene IDs werden unterstützt |
| Provider Name | Erforderlich | Anzeigename des Providers; normalerweise aus dem Katalog automatisch ausgefüllt |
| Model ID | Erforderlich | Tatsächliche Modell-ID der Provider-API, etwa `gpt-4.1` oder `claude-sonnet-4-5` |
| Model Name | Erforderlich | In BibGenie angezeigter Name; normalerweise aus dem Katalog automatisch ausgefüllt |
| API Key | Optional | Dein Provider-API-Schlüssel; lokale Provider wie Ollama benötigen normalerweise keinen |
| Base URL | Optional | API-Endpunkt; für Katalogprovider oft automatisch ausgefüllt, kompatible oder lokale Dienste erfordern aber eventuell manuelle Bestätigung |
| Provider Type | Erforderlich | API-Integrationstyp, etwa OpenAI, Anthropic, Ollama oder OpenAI Compatible |
| Family | Optional | Modellfamilie, etwa `qwen`, `gpt` oder `claude`; oft automatisch ausgefüllt |
| Model Types | Erforderlich | Fähigkeiten wie Text, Vision, Reasoning, Function Calling oder Web Search |
| Context Window | Optional | Kontextfenster des Modells; bei Katalogmodellen oft automatisch ausgefüllt |
| Max Tokens | Optional | Maximale Ausgabetokens; bei Katalogmodellen oft automatisch ausgefüllt |
| Description | Optional | Modellbeschreibung; oft automatisch ausgefüllt |
## Provider Type-Leitfaden [#provider-type-leitfaden]
| Provider Type | Verwenden, wenn |
| :---------------- | :---------------------------------------------------------------------------------------- |
| OpenAI | Du die offizielle OpenAI API verwendest |
| Anthropic | Du die Anthropic Claude API verwendest |
| xAI | Du die xAI Grok API verwendest |
| DeepSeek | Du die offizielle DeepSeek API verwendest |
| Google | Du die Gemini API verwendest |
| Groq | Du die Groq API verwendest |
| Moonshot AI | Du Kimi / Moonshot-Modelle verwendest |
| OpenRouter | Du die OpenRouter API verwendest |
| Alibaba | Normalerweise über OpenAI Compatible |
| Z.AI / Zhipu AI | Normalerweise über OpenAI Compatible |
| Ollama | Du einen lokalen Ollama-Dienst verwendest |
| OpenAI Compatible | Du LM Studio, einen API-Proxy oder einen institutionellen kompatiblen Endpunkt verwendest |
## Base URL [#base-url]
Viele offizielle Provider haben eine Standard-Base URL. Du musst Base URL normalerweise nur ändern, wenn:
* Du OpenAI Compatible verwendest.
* Du einen API-Proxy verwendest.
* Du einen lokalen Modelldienst verwendest.
* Dein Provider einen eigenen Endpunkt verlangt.
Beispiele:
```text
https://api.openai.com/v1
https://openrouter.ai/api/v1
http://localhost:11434
http://localhost:1234/v1
```
Viele kompatible APIs benötigen eine Base URL, die auf `/v1` endet. Fehlt der Versionspfad, kann es zu NetworkError, 404 oder model-not-found-Fehlern kommen.
## Ollama-Beispiel [#ollama-beispiel]
Stelle sicher, dass Ollama installiert ist und läuft.
Führe
`ollama list`
in einem Terminal aus, um zu prüfen, ob ein lokales Modell verfügbar ist.
Falls Ollama noch nicht läuft, starte es mit
`ollama serve`
. Die Ausgabe bestätigt, dass es auf
`127.0.0.1:11434`
lauscht.
Füge in BibGenie ein Modell hinzu und wähle
**Ollama**
als Provider Type.
Verwende
`http://localhost:11434`
als Base URL.
Verwende den von
`ollama list`
angezeigten Modellnamen, etwa
`llama3.1:8b`
, als Model ID.
## LM Studio-Beispiel [#lm-studio-beispiel]
LM Studio wird normalerweise über OpenAI Compatible konfiguriert:
Starte den lokalen API-Server in LM Studio.
Füge in BibGenie ein Modell hinzu und wähle
**OpenAI Compatible**
als Provider Type.
Gib die LM Studio API-Adresse als Base URL ein, normalerweise ähnlich wie
`http://localhost:1234/v1`
.
Gib die ID des aktuell in LM Studio geladenen Modells als Model ID ein.
## Model Types [#model-types]
Wähle Fähigkeiten entsprechend dem, was das Modell tatsächlich unterstützt:
* **Text**: Textchat; normalerweise erforderlich.
* **Vision**: Eingabe von Bildern, Screenshots und Abbildungen.
* **Reasoning**: nützlich für komplexe Reasoning-Aufgaben.
* **Function Calling**: beeinflusst Suche, Lesen und Bibliotheksverwaltungs-Workflows.
* **Web Search**: nur aktivieren, wenn Provider und Modell dies unterstützen.
Falsche Fähigkeitseinstellungen können `ModelNotSupported` oder Tool-Calling-Fehler verursachen.
## FAQ [#faq]
Stelle sicher, dass das Modell gespeichert und aktiviert wurde. Wenn es weiterhin nicht erscheint, öffne Model Settings erneut oder starte Zotero neu.
Anfragen an eigene Modelle werden direkt vom lokalen Zotero-Plugin an den von dir konfigurierten Provider gesendet. Siehe [Bring Your Own Key](/docs/byok) für Details zum Datenfluss.
Stelle sicher, dass der lokale Dienst läuft, der Port korrekt ist, die Base URL erreichbar ist und keine Firewall oder kein Proxy die Anfrage blockiert.
Ja. Dein API-Schlüssel wird verschlüsselt und nur in deiner lokalen Zotero-Konfiguration gespeichert. Er wird direkt für Anfragen an den Modellanbieter verwendet und durchläuft **niemals** die Server von BibGenie.
Klicke im Custom-Models-Bereich auf **Reset**, um alle benutzerdefinierten Konfigurationen auf den Ausgangszustand zurückzusetzen. **Achtung: Dabei werden alle manuell hinzugefügten Modelle gelöscht.**
# Fehlerbehebung (/de/docs/error-in-bibgenie)
Diese Seite hilft dir, häufige BibGenie-Fehler zu diagnostizieren und den passenden nächsten Schritt zu wählen.
Stelle vor der Fehlerbehebung sicher, dass du die neueste Version von BibGenie verwendest. Viele Modell-, Zotero-Kompatibilitäts- und Netzwerkprobleme sind in neueren Versionen möglicherweise bereits behoben.
Fehlerdialoge enthalten oft nützliche Details wie Modellname, Request URL, Anbieterantwort und Fehlergrund. Lies sie sorgfältig, bevor du Einstellungen änderst.
## ModelNotSupported [#modelnotsupported]
Ein Dialog mit dem Titel "ModelNotSupported".
Das ausgewählte Modell unterstützt den aktuellen Eingabetyp nicht. Das passiert häufig, wenn du ein Bild an ein Modell sendest, das keine Vision-Eingaben unterstützt.
### So behebst du es [#so-behebst-du-es]
Wähle ein Modell, das die benötigte Fähigkeit unterstützt, zum Beispiel Vision für Bild- oder Screenshot-Eingaben.
Wenn du ein eigenes Modell verwendest und weißt, dass es Bilder unterstützt, prüfe, ob es in Custom Models als **Vision**-Modell markiert ist.
Wenn die Aufgabe Tool-Nutzung erfordert, stelle sicher, dass das Modell **Function Calling** unterstützt.
## AI\_APICallError [#ai_apicallerror]
Ein Dialog mit dem Titel "AI\_APICallError".
Die Modell-API-Anfrage ist fehlgeschlagen. Häufige Ursachen sind ein ungültiger API Key, eine falsche Model ID, eine fehlerhafte Base URL, ein Anbieter-Timeout oder ein Netzwerkfehler.
### Häufige Fehlertypen [#häufige-fehlertypen]
Ungültige oder abgelaufene Schlüssel können Meldungen wie diese erzeugen:
```text
Unauthorized Failure reason: Authentication Fails
(auth header format should be Bearer sk-...)
```
```text
Incorrect API key provided.
```
Prüfe, ob der API Key vollständig und aktiv ist und zum ausgewählten Anbieter gehört.
Falsche Model IDs können Meldungen wie diese erzeugen:
```text
Model Not Exist
```
Vergleiche die Model ID in BibGenie mit der exakten Modell-ID, die der Anbieter anzeigt.
Fehlerhafte Base URLs können Request- oder 404-Fehler auslösen.
Viele Anbieter verlangen eine Base URL, die auf `/v1` endet. Eine URL wie `/v/` statt `/v1/` schlägt fehl.
### So behebst du es [#so-behebst-du-es-1]
Aktualisiere die offizielle Modellliste in Model Settings. Wenn das Problem bestehen bleibt, aktualisiere BibGenie und kontaktiere den Support mit der vollständigen Fehlermeldung.
Prüfe Provider Type, Provider ID, Model ID, API Key und Base URL. Verwende den Test-Button in Custom Models, um die Verbindung zu verifizieren.
Stelle sicher, dass Ollama, LM Studio oder dein lokaler Server läuft, der Port korrekt ist und die Base URL aus Zotero-Browserumgebung erreichbar ist.
## NetworkError [#networkerror]
Einen Fehler wie `TypeError: NetworkError when attempting to fetch resource.`
BibGenie konnte den Anbieter-Endpunkt nicht erreichen.
Mögliche Ursachen:
* Der lokale Modellserver läuft nicht.
* Base URL oder Port ist falsch.
* Firewall, Proxy oder Netzwerkrichtlinie blockiert die Anfrage.
* Der Anbieter-Endpunkt ist vorübergehend nicht verfügbar.
* Der konfigurierte Anbieter unterstützt in deiner Umgebung keine browserseitigen Anfragen.
## Probleme mit Anhängen oder Kontext [#probleme-mit-anhängen-oder-kontext]
Wenn BibGenie ein PDF, einen Snapshot, eine Notiz oder ausgewählten Text nicht lesen kann:
* Stelle sicher, dass die Datei auf diesem Gerät vorhanden ist.
* Wenn du Zotero-Sync verwendest, prüfe, ob der Anhang lokal heruntergeladen wurde.
* Prüfe als WebDAV-Nutzer, ob Zotero-Dateisync funktioniert.
* Öffne den Anhang testweise direkt in Zotero.
* Starte Zotero neu, wenn der Reader-Zustand veraltet wirkt.
## MCP-Verbindungsprobleme [#mcp-verbindungsprobleme]
Wenn ein externer MCP-Client keine Verbindung herstellen kann:
* Bestätige, dass **Enable MCP Server** aktiviert ist.
* Kopiere die Server URL erneut.
* Klicke in MCP Settings auf **Test Connection**.
* Stelle sicher, dass Zotero noch läuft.
* Trenne Clients, denen du nicht vertraust.
## Hilfe erhalten [#hilfe-erhalten]
Wenn das Problem bestehen bleibt, sende bei deiner Support-Anfrage folgende Informationen:
* BibGenie-Version
* Zotero-Version
* Betriebssystem
* Ob du ein offizielles oder eigenes Modell verwendest
* Provider Type und Model ID
* Vollständige Fehlermeldung
* Ob das Problem bei einem bestimmten PDF, einer Notiz oder einem Kontexttyp auftritt
Du kannst der [BibGenie Discord-Community](https://discord.gg/kDXFAAYDNE) beitreten, um Support zu erhalten.
# Erste Schritte (/de/docs/getting-started)
Diese Anleitung führt dich auf dem schnellsten Weg zu einer funktionierenden Einrichtung: Plugin herunterladen, in Zotero installieren, Sidebar öffnen und die erste Frage zu einem Paper stellen.
BibGenie unterstützt Zotero 7, Zotero 8, Zotero 9 und Zotero 10. Für die stabilste Plugin- und Reader-Erfahrung empfehlen wir eine aktuelle Zotero-Version.
## Plugin herunterladen [#plugin-herunterladen]
Gehe zur [BibGenie-Downloadseite](https://www.bibgenie.com/download) und lade die neueste Plugin-Version herunter.
Die heruntergeladene Datei heißt normalerweise:
```text
bibgenie-.xpi
```
wobei `` die Versionsnummer ist.
## BibGenie in Zotero installieren [#bibgenie-in-zotero-installieren]
Öffne Zotero und wähle in der Menüleiste **Tools -> Plugins**.
Klicke im Plugin-Manager oben rechts auf das Zahnrad und wähle **Install Plugin From File...**.
Wähle die heruntergeladene Datei `bibgenie-.xpi` aus.
Starte Zotero nach der Installation neu.
Öffne BibGenie nach dem Neustart über die Zotero-Symbolleiste oder das Tools-Menü.
## BibGenie öffnen [#bibgenie-öffnen]
Du kannst BibGenie auf mehrere Arten öffnen:
* Klicke auf das BibGenie-Symbol in der Zotero-Symbolleiste.
* Wähle **Tools -> BibGenie** in der Menüleiste.
* Verwende das konfigurierte Tastenkürzel, um die BibGenie-Sidebar anzuzeigen oder zu wechseln.
Wenn das Kürzel mit Zotero oder deinem Betriebssystem kollidiert, kannst du es unter [Tastenkürzel](/docs/keyboard-shortcuts) ändern.
## Anmelden [#anmelden]
Kostenlose Nutzer können mit den Kernfunktionen für Chat und Kontext starten. Nach der Anmeldung kann BibGenie deinen Abonnementstatus, dein Credit-Guthaben und den Zugriff auf offizielle Modelle synchronisieren.
Enthält die Kernfunktionen, Paper-Lektüre und externe Recherche mit OpenAlex, Web Search und Web Extract.
Enthält mehr monatliche Credits für häufige Paper-Lektüre, Vergleiche und Forschungsworkflows.
## Erste Frage stellen [#erste-frage-stellen]
Ein guter Einstieg ist ein PDF-Paper:
Wähle einen Zotero-Eintrag mit PDF-Anhang aus.
Beim ersten Start verwendet BibGenie standardmäßig ein integriertes Modell. Du musst vor der ersten Frage keinen API-Schlüssel konfigurieren oder manuell ein Modell auswählen.
Gib im BibGenie-Eingabefeld ein Leerzeichen gefolgt von `@` ein, suche nach dem Paper und füge es hinzu. Du kannst den Zotero-Eintrag auch rechtsklicken und **Add to Chat** wählen.
Stelle eine konkrete Frage, zum Beispiel:
```text
Summarize this paper's research question, method, main findings, and limitations.
```
Wenn die Antwort nützlich ist, klicke bei der letzten Assistentenantwort auf **Save as Note**, um sie als Zotero-Notiz zu speichern.
Wenn du später deinen eigenen API-Schlüssel, ein lokales Modell oder einen institutionellen Modelldienst verwenden möchtest, lies [Bring Your Own Key](/docs/byok) und [Custom Models](/docs/custom-models).
Starke Prompts nennen sowohl das Ziel als auch das erwartete Format, etwa "in fünf Stichpunkten zusammenfassen", "Abschnitte für Methode, Ergebnisse und Einschränkungen verwenden" oder "in eine Literaturreview-Notiz umwandeln".
## Nächste Schritte [#nächste-schritte]
* Lerne, reichhaltigeren Kontext hinzuzufügen: [Kontext hinzufügen](/docs/add-context)
* Lerne, Unterhaltungen zu bearbeiten, neu zu generieren, zu verzweigen und zu komprimieren: [Unterhaltungen verwalten](/docs/conversation-management)
* Verstehe die Modellauswahl: [Modelle](/docs/models)
* Verstehe Pläne und Credits: [Preise & Credits](/docs/pricing-credits)
* Erstelle wiederverwendbare Prompts: [Quick Prompts](/docs/quick-prompts)
## BibGenie aktualisieren [#bibgenie-aktualisieren]
BibGenie prüft beim Start von Zotero automatisch auf Updates. Wenn eine neue Version erkannt wird, erscheint eine Update-Schaltfläche in der BibGenie-Menüleiste — klicke darauf, um die neueste Version zu installieren.
Du kannst auch automatische Updates über den Plugin-Manager von Zotero aktivieren:
Öffne Zotero und wähle **Werkzeuge -> Plugins**.
Wähle BibGenie in der Plugin-Liste aus.
Aktiviere **Allow automatic updates** (Automatische Updates erlauben). Zotero wird BibGenie dann automatisch aktualisieren, sobald neue Versionen verfügbar sind.
# Überblick (/de/docs)
BibGenie ist ein KI-Forschungsagent, der direkt in Zotero integriert ist. Statt wie ein separater Web-Chatbot zu funktionieren, arbeitet BibGenie in deinem Zotero-Arbeitsbereich mit deiner Bibliothek, PDFs, Web-Snapshots, Notizen und dem Material, das du gerade liest.
Füge Zotero-Einträge, PDF-Anhänge, Snapshots, Notizen, markierten Text, Seitenkontext, Bilder oder Screenshots zu einer Unterhaltung hinzu und bitte BibGenie anschließend, dein Forschungsmaterial zu lesen, zu erklären, zu suchen, zu organisieren und zu sichern.
Die Kernfunktionen von BibGenie laufen in deiner Zotero-Umgebung. Chatverlauf und viele Einstellungen werden lokal gespeichert. Wenn du ein eigenes oder lokales Modell verwendest, werden Anfragen direkt an den von dir konfigurierten Anbieter gesendet.
## Kern-Workflow [#kern-workflow]
Füge Zotero-Einträge, PDFs, Snapshots, Notizen, markierten Text oder Screenshots hinzu, damit BibGenie das Material versteht, mit dem du arbeitest.
Fasse Paper zusammen, erkläre Abbildungen, durchsuche deine Bibliothek, vergleiche Artikel, nutze OpenAlex für öffentliche wissenschaftliche Datensätze oder durchsuche das Web nach öffentlichen Informationen.
Gleiche Daten mit arXiv, Semantic Scholar, OpenAlex, DBLP und OpenReview ab, fülle fehlende Felder und werte Preprints sicher auf. Mehr erfahren: [Metadaten-Prüfung](/docs/metadata-review).
Speichere nützliche Antworten als Zotero-Notizen oder bitte BibGenie, Tags, Sammlungen und Metadaten zu organisieren.
## Was du mit BibGenie tun kannst [#was-du-mit-bibgenie-tun-kannst]
* Paper lesen: Forschungsfragen, Methoden, Beiträge, Einschränkungen und zukünftige Arbeiten zusammenfassen.
* Textstellen tief lesen: markierte Passagen, Formeln, Abbildungen oder experimentelle Ergebnisse erklären.
* Deine Bibliothek durchsuchen: relevante Paper per Schlüsselwort oder durch Beschreibung eines Forschungsthemas in natürlicher Sprache finden.
* Metadaten prüfen und aktualisieren: Paper-Einträge mit mehreren akademischen Datenbanken abgleichen, arXiv-Preprints zu formalen Publikationen aufwerten und Better BibTeX-Zitierschlüssel schützen. Mehr erfahren: [Metadaten-Prüfung](/docs/metadata-review).
* Deine Bibliothek organisieren: Tags, Sammlungen, Metadaten und das Verschieben von Einträgen verwalten.
* Notizen speichern: strukturierte KI-Antworten in Zotero-Notizen umwandeln.
* Unterhaltungen verwalten: die letzte Frage bearbeiten, Antworten neu generieren, Zweige erstellen und älteren Kontext komprimieren.
* Externe Tools verbinden: lokale Zotero-Tools über den MCP-Server von BibGenie bereitstellen.
## Empfohlener Lesepfad [#empfohlener-lesepfad]
**Ersteinrichtung**: Beginne mit [Erste Schritte](/docs/getting-started), um BibGenie zu installieren und deine erste Frage zu stellen.
**Modelle und Credits verstehen**: Lies [Modelle](/docs/models) und [Preise & Credits](/docs/pricing-credits).
**Kernfunktionen lernen**: Fahre mit [Kontext hinzufügen](/docs/add-context), [Unterhaltungen verwalten](/docs/conversation-management), [Literatursuche](/docs/literature-search), [Metadaten-Prüfung](/docs/metadata-review) und [Als Notiz speichern](/docs/save-as-note) fort.
**Fortgeschrittene Einrichtung**: Wenn du deinen eigenen API-Schlüssel oder ein lokales Modell hast, lies [Bring Your Own Key](/docs/byok) und [Custom Models](/docs/custom-models).
## Dokumentationsbereiche [#dokumentationsbereiche]
Installation, Modelle, Preise und Credits.
Kontext, Prompts, Suche, Webzugriff, Metadaten-Prüfung, Bibliotheksverwaltung, Notizen und MCP.
Eigene Modelle, MCP, Add to Chat, Tastenkürzel, Zitierformat und semantische Indexierung.
Häufige Fehler, Modellfehler, Netzwerkprobleme und Zotero-Kompatibilität.
# Tastenkürzel (/de/docs/keyboard-shortcuts)
BibGenie unterstützt ein Tastenkürzel zum Anzeigen oder Wechseln der Chat-Sidebar. Du kannst es an deinen Workflow anpassen.
## Kürzel ändern [#kürzel-ändern]
Öffne BibGenie Preferences.
Suche den Abschnitt **Keyboard Shortcuts**.
Wähle einen Modifier, etwa Ctrl + Shift oder Command + Shift.
Gib die Haupttaste ein, zum Beispiel `L`.
Prüfe Konfliktwarnungen und speichere.
## Konflikterkennung [#konflikterkennung]
BibGenie prüft Konflikte mit häufigen Zotero-Befehlen. Wenn ein Konflikt gefunden wird, zeigt die Einstellungsseite den kollidierenden Befehl an.
Wenn das Kürzel nicht funktioniert, können folgende Ursachen vorliegen:
* Konflikt mit einem eingebauten Zotero-Kürzel.
* Konflikt mit einem Betriebssystem-Kürzel.
* Konflikt mit einem anderen Zotero-Plugin.
* Der Fokus befindet sich gerade in einem Eingabefeld, Modal oder Systemsteuerelement.
* Deine Eingabemethode oder dein Betriebssystem hat die Tastenkombination abgefangen.
## Fehlerbehebung [#fehlerbehebung]
Probiere eine andere Kombination, zum Beispiel Ctrl / Command + Shift + L. Klicke außerdem zuerst in das Zotero-Hauptfenster, bevor du das Kürzel drückst.
Das bedeutet normalerweise, dass es einen Konflikt gibt. Wähle in Keyboard Shortcuts eine weniger häufig verwendete Haupttaste.
Command + Shift ist unter macOS normalerweise die passendere Konvention.
# Bibliotheksverwaltung (/de/docs/library-management)
BibGenie kann mehr als Paper lesen. Es kann helfen, deine Zotero-Bibliothek zu organisieren, indem es Tags verwaltet, Sammlungen erstellt, Einträge verschiebt und Metadaten bearbeitet.
Bibliotheksverwaltungsaktionen können deine Zotero-Bibliothek verändern. Bitte BibGenie bei Batch-Operationen, vor dem Anwenden von Änderungen einen Plan oder eine Vorschau zu zeigen.
## Unterstützte Organisationsaufgaben [#unterstützte-organisationsaufgaben]
| Aufgabe | Beispiele |
| :---------------------- | :---------------------------------------------------------------------- |
| Tag-Verwaltung | Tags hinzufügen, entfernen und auflisten |
| Sammlungsverwaltung | Sammlungen erstellen, Sammlungen auflisten, Einträge verschieben |
| Metadatenbearbeitung | Titel, Abstract, Publikationstitel, DOI und verwandte Felder bearbeiten |
| Metadaten lesen | Autoren, Jahr, Anhänge, Notizen und Tags prüfen |
| Literaturklassifikation | Paper nach Thema, Methode, Jahr oder Projekt gruppieren |
Wenn Sie arXiv, Semantic Scholar, OpenAlex, DBLP oder OpenReview abfragen möchten, um fehlende Zusammenfassungen, DOIs oder Zeitschriftenabkürzungen automatisch zu ergänzen oder Schreibweisen zu bereinigen, lesen Sie den Leitfaden [Metadaten-Überprüfung & Bereinigung](/docs/metadata-review).
## Häufige Workflows [#häufige-workflows]
Füge ausgewählten Einträgen `literature-review` oder einen Projekt-Tag hinzu.
Erstelle eine neue Sammlung zu einem Forschungsthema und verschiebe relevante Paper hinein.
Finde Paper, denen DOI, Abstract oder Publikationstitel fehlen.
Gruppiere Paper anhand von Forschungsthemen in eine klarere Bibliotheksstruktur.
## Beispiel-Prompts [#beispiel-prompts]
```text
Review the selected papers and propose a collection structure by research topic. Do not modify Zotero yet.
```
```text
Add the tags deep-research and llm-agent to the currently selected papers.
```
```text
Find papers in this collection that are missing a DOI or abstract, and return a table.
```
## Empfohlener Workflow [#empfohlener-workflow]
Bitte BibGenie, die Kandidaten-Paper zu suchen oder aufzulisten.
Bitte um einen Organisationsplan, einschließlich der Einträge, die verändert werden.
Prüfe den Plan.
Autorisiere BibGenie ausdrücklich, die Änderungen anzuwenden.
Bitte um eine Zusammenfassung der Änderungen.
Gib bei Batch-Arbeit den Umfang an: "only selected items", "only this collection" oder "do not edit metadata, only add tags".
## Besondere Vorsicht bei [#besondere-vorsicht-bei]
* Dem Verschieben vieler Paper auf einmal.
* Dem massenhaften Entfernen von Tags.
* Dem Überschreiben von Titeln, Abstracts, DOI oder anderen wichtigen Metadaten.
* Dem Erstellen oder Umorganisieren von Sammlungen über viele Einträge hinweg.
Arbeite bei solchen Vorgängen in kleineren Batches und bitte BibGenie, zuerst die betroffenen Einträge aufzulisten.
# Literatursuche (/de/docs/literature-search)
Standardmäßig sucht und liest BibGenie zuerst deine Zotero-Bibliothek, statt direkt ins öffentliche Web zu gehen. So bleiben Antworten in dem Material verankert, das du bereits gesammelt und organisiert hast.
## Drei Suchmodi [#drei-suchmodi]
Am besten, wenn du Titel, Autor, Jahr, DOI, Tag, Sammlung oder einen anderen expliziten Hinweis kennst.
Am besten, wenn du ein Forschungsthema, eine Theorie, Methode oder ein Problem in natürlicher Sprache beschreiben möchtest.
Am besten zum Auflisten von Kandidaten-Papers, Durchblättern von Ergebnissen oder Prüfen von Einträgen in einem definierten Bereich.
## Keyword Search [#keyword-search]
Keyword Search funktioniert gut, wenn du bereits einen Teil der Zielinformationen kennst:
* Wörter im Paper-Titel
* Autorenname
* Jahr
* DOI
* Sammlungsname
* Tag-Name
* Journal- oder Konferenzname
Beispiele:
```text
Find papers in my Zotero library about contrastive learning.
```
```text
Find causal inference papers after 2022 with the tag review.
```
Keyword Search ist präzise und gut kontrollierbar. Der Nachteil ist, dass relevante Paper übersehen werden können, wenn deine Formulierung nicht zu den Metadaten passt.
## Semantic Search [#semantic-search]
Semantic Search ist für konzeptuelle Abfragen gedacht. Du musst nicht die exakten Begriffe erraten, die in Titeln oder Abstracts verwendet werden; beschreibe stattdessen das Forschungsthema.
Beispiele:
```text
Find papers that discuss how large language models affect academic writing norms.
```
```text
My project is about how AI tools change researchers' knowledge work. Find related papers.
```
Semantic Search verwendet einen lokalen Index der Titel und Abstracts regulärer Zotero-Einträge. Beachte:
* Es ist keine PDF-Volltextsuche.
* Paper ohne Abstracts sind schwerer zu finden.
* Der erste Lauf kann Zeit benötigen, um den semantischen Index aufzubauen.
Siehe [Semantic Index](/docs/semantic-index) für Indexstatus und Fehlerbehebung.
## List Items [#list-items]
List Items wird verwendet, um passende Paper anzuzeigen oder weiter durch Ergebnisse zu browsen.
Beispielanfragen:
```text
List the 20 most recent papers in this collection.
```
```text
Show more results.
```
```text
List papers tagged systematic-review and sort them by year.
```
List Items ist besonders nützlich, wenn BibGenie zuerst eine Kandidatenmenge anzeigen soll, damit du anschließend entscheidest, welche PDFs oder Notizen gelesen werden sollen.
## Empfohlener Workflow [#empfohlener-workflow]
Nutze Semantic Search, um Paper zu einem breiten Thema zu finden.
Bitte BibGenie, Titel, Jahre, Autoren und Abstracts aufzulisten.
Wähle einige Paper aus und füge sie als Kontext hinzu.
Bitte BibGenie, PDFs zu lesen, Claims zu vergleichen, eine Tabelle zu erzeugen oder eine Notiz zu speichern.
Ergänze Jahr, Tag, Sammlung oder Ergebnislimits, um Suchen nützlicher zu machen. Zum Beispiel: "only after 2020", "within the Methods collection" oder "return at most 10 papers".
# MCP-Einstellungen (/de/docs/mcp-settings)
MCP Settings steuert den lokalen MCP-Server von BibGenie. Wenn er aktiviert ist, können externe MCP-Clients eine Verbindung zur Server URL herstellen und auf BibGenies Zotero-Tools zugreifen.
## Steuerelemente [#steuerelemente]
Startet oder stoppt den lokalen MCP-Server.
Die URL, mit der externe Clients eine Verbindung zu BibGenie herstellen. Sie sieht meist aus wie `http://127.0.0.1:23119/bibgenie/mcp`, der Port kann bei einer benutzerdefinierten Zotero-HTTP-Konfiguration aber abweichen.
Kopiert die Server URL in deine Zwischenablage.
Sendet eine MCP-Initialize-Anfrage per HTTP POST JSON-RPC, um zu prüfen, ob der Endpunkt erreichbar ist.
Die Server URL direkt im Browser zu öffnen ist nicht dasselbe wie eine MCP-Verbindung. MCP-Clients senden POST JSON-RPC, die Browser-Adresszeile sendet GET. Verwende **Test Connection** für die echte Prüfung.
## Statusübersicht [#statusübersicht]
| Status | Bedeutung |
| :------------------ | :------------------------------------------------ |
| Server is off | MCP Server ist deaktiviert |
| Starting | Server startet |
| Server running | Server ist für externe Clients bereit |
| Testing connection | Verbindungstest läuft |
| Connection verified | Test erfolgreich |
| Connection failed | Test fehlgeschlagen; URL oder Serverstatus prüfen |
## Wenn die Verbindung fehlschlägt [#wenn-die-verbindung-fehlschlägt]
* Stelle sicher, dass Zotero läuft.
* Stelle sicher, dass BibGenie in Zotero aktiviert ist.
* Stelle sicher, dass **Enable MCP Server** eingeschaltet ist.
* Kopiere die angezeigte Server URL, statt Port `23119` anzunehmen.
* Starte Zotero neu, wenn der Server gerade aktiviert oder das Plugin aktualisiert wurde.
## MCP aktivieren [#mcp-aktivieren]
Öffne BibGenie Preferences.
Suche den Abschnitt **MCP Server**.
Aktiviere **Enable MCP Server**.
Warte, bis die Server URL erscheint.
Klicke auf Copy und füge die URL in deinen externen MCP-Client ein.
Klicke auf Test Connection, um die Verbindung zu prüfen.
## MCP deaktivieren [#mcp-deaktivieren]
Wenn du keine externen Clients verwendest, schalte **Enable MCP Server** aus. Externe Clients können dann nicht mehr auf BibGenies MCP-Tools zugreifen.
MCP-Tools können deine Zotero-Bibliothek lesen oder verändern. Teile die Server URL nur mit Clients, denen du vertraust.
# MCP (/de/docs/mcp)
MCP steht für Model Context Protocol. BibGenie kann einen lokalen MCP-Server starten, über den MCP-kompatible Clients auf Zotero-bezogene Werkzeuge zugreifen können.
Wenn du nur innerhalb des BibGenie-Plugins chattest, musst du MCP nicht konfigurieren. MCP ist vor allem für fortgeschrittene Nutzer, externe Clients und automatisierte Workflows gedacht.
## Was kann MCP tun? [#was-kann-mcp-tun]
Externe Clients können BibGenies Zotero-Werkzeuge verwenden, um:
* Zotero-Einträge zu suchen
* semantische Literatursuchen auszuführen
* PDF-Anhänge zu lesen
* Snapshots zu lesen
* Zotero-Notizen zu lesen
* Tags und Sammlungen aufzulisten
* Zotero-Notizen zu erstellen
* Tags und Sammlungen zu verwalten
* Metadaten abzurufen oder zu bearbeiten
## Was ist Zotero MCP? [#was-ist-zotero-mcp]
Zotero MCP ist BibGenies lokale Brücke zwischen deiner Zotero-Bibliothek und externen KI-Clients. Statt Dateien zu exportieren oder Metadaten manuell zu kopieren, kann ein MCP-kompatibler Client BibGenie über ein lokales Protokoll nach Zotero-Kontext fragen.
Ein externer Client kann zum Beispiel deine Bibliothek durchsuchen, Sammlungen prüfen, einen PDF-Anhang lesen oder eine Zotero-Notiz über BibGenies MCP-Werkzeuge erstellen.
## Kernvorteile [#kernvorteile]
BibGenies MCP-Server läuft im Zotero-Plugin. Du brauchst keinen separaten Python-Dienst und kein eigenes lokales Backend.
Der MCP-Endpunkt läuft auf Zotero's lokalem HTTP-Server. Dein externer Client spricht auf deinem eigenen Gerät mit Zotero.
Die Werkzeuge sind für Zotero-Workflows gebaut: Paper, PDFs, Sammlungen, Tags, Notizen, Snapshots und Metadaten.
MCP lässt Werkzeuge wie Cursor, Claude Code, Claude Desktop und Cherry Studio Zotero-Kontext verwenden, ohne ihre eigene Oberfläche zu verlassen.
## Kernfunktionen [#kernfunktionen]
| Funktion | Wobei sie hilft |
| :----------------------- | :-------------------------------------------------------------------------------------------------------------------------------------------------- |
| Eintragssuche | Paper nach Titel, Autor, Publikation, Schlüsselwort oder Thema finden. |
| Semantische Suche | Verwandte Paper nach Bedeutung finden, nicht nur nach exakten Schlüsselwörtern. |
| Metadatenzugriff | Detaillierte Zotero-Metadaten lesen, bevor zitiert, organisiert oder bearbeitet wird. |
| PDF-Lesen | Text aus Zotero-PDF-Anhängen lesen, wenn ein Client Paper-Inhalt benötigt. |
| Visuelles PDF-Lesen | PDF-Seiten als Bilder rendern, wenn Abbildungen, Tabellen oder gescannte Seiten visuell geprüft werden müssen. |
| Notizen und Snapshots | Zotero-Notizen und Web-Snapshots aus deiner Bibliothek lesen. |
| Bibliotheksorganisation | Sammlungen und Tags auflisten, Sammlungen erstellen und Tags oder Sammlungszuordnung verwalten. |
| Metadaten-Überprüfung | Schreibgeschütztes `review_metadata` ausführen, um Fakten aus arXiv, Semantic Scholar, OpenAlex, DBLP und OpenReview mit Regeldiagnosen zu bündeln. |
| Kontrolliertes Schreiben | Vertrauenswürdige Clients können über explizite MCP-Tool-Aufrufe Notizen erstellen oder mit `edit_metadata` Metadaten prüfen und speichern. |
## Plugin-Chat vs. MCP [#plugin-chat-vs-mcp]
| Modus | Am besten für | Einrichtung erforderlich |
| :---------------------- | :--------------------------------------------------- | :----------------------- |
| BibGenie In-Plugin-Chat | Die meisten Nutzer | Nein |
| Lokaler MCP-Server | Nutzer, die Zotero mit externen KI-Clients verbinden | Ja |
## Servertyp und URL [#servertyp-und-url]
BibGenies MCP-Server verwendet **Streamable HTTP**. Die Server URL sieht normalerweise so aus:
```text
http://127.0.0.1:23119/bibgenie/mcp
```
Der Port kann abweichen, wenn dein Zotero-HTTP-Server einen benutzerdefinierten Port verwendet. Kopiere immer die Server URL aus den BibGenie-Einstellungen, anstatt sie von Hand einzugeben.
MCP-Clients verbinden sich über HTTP POST JSON-RPC. Die Browser-Adresszeile sendet einen GET-Request und ist kein zuverlässiger MCP-Verbindungstest. Verwende **Test Connection** in den BibGenie-Einstellungen oder einen MCP-Client.
## MCP-Server aktivieren [#mcp-server-aktivieren]
Öffne die BibGenie-Einstellungen.
Suche den Abschnitt **MCP Server**.
Aktiviere **Enable MCP Server**.
Kopiere die angezeigte Server URL.
Füge die URL in deinen externen MCP-Client ein.
Klicke auf **Test Connection**, um die Verbindung zu prüfen.
## Externe Clients verbinden [#externe-clients-verbinden]
Verwende die Server URL aus den BibGenie-Einstellungen in Clients, die Streamable HTTP MCP unterstützen.
### Cursor [#cursor]
Cursor kann sich direkt mit BibGenies Streamable-HTTP-Endpunkt verbinden.
Öffne Cursor Settings und gehe zu **Tools & MCP**.
Klicke auf **+ New MCP Server**.
Füge diese Konfiguration ein:
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"url": "http://127.0.0.1:23119/bibgenie/mcp"
}
}
}
```
Ersetze die URL, wenn BibGenie einen anderen Port anzeigt.
Speichere die Konfiguration. Sobald Cursor den MCP-Server als verbunden anzeigt, kannst du Zotero-Kontext im Cursor-Chat verwenden.
### Claude Code [#claude-code]
Claude Code unterstützt HTTP-MCP-Server direkt:
```bash
claude mcp add ZoteroBibGenie --transport http http://127.0.0.1:23119/bibgenie/mcp
```
Ersetze die URL, wenn BibGenie einen anderen Port anzeigt.
### Claude Desktop [#claude-desktop]
Einige Claude Desktop-Versionen verbinden stdio-MCP-Server zuverlässiger als lokale HTTP-Endpunkte. Verwende dann `mcp-remote` als Brücke von Claude Desktop zu BibGenies lokalem HTTP-Server.
Installiere Node.js, falls `node` und `npx` auf deinem System nicht verfügbar sind.
Öffne Claude Desktop.
Öffne **Settings** und gehe zum Bereich **Developer**.
Klicke auf **Edit Config**, um `claude_desktop_config.json` zu öffnen.
Füge diese Konfiguration hinzu:
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"command": "npx",
"args": ["mcp-remote", "http://127.0.0.1:23119/bibgenie/mcp"]
}
}
}
```
Ersetze die URL, wenn BibGenie einen anderen Port anzeigt.
Speichere die Datei und starte Claude Desktop neu.
### Cherry Studio [#cherry-studio]
Cherry Studio unterstützt Streamable HTTP MCP direkt.
Öffne Cherry Studio Settings und wechsle zum Tab **MCP**.
Klicke auf **Add** und wähle **Quick Create**.
Fülle aus:
* **Name**: `ZoteroBibGenie`
* **Type**: `Streamable HTTP`
* **URL**: die aus BibGenie kopierte Server URL

Optional: Öffne **Advanced Settings** und setze:
* **Provider URL**: `https://www.bibgenie.com/`
* **Logo URL**: `https://www.bibgenie.com/favicon.png`

Klicke auf **Save**, schalte den Dienst ein und nutze den Verify-Button von Cherry Studio, um die Verbindung zu prüfen.
## Beispiel-Prompts [#beispiel-prompts]
* "Finde Zotero-Paper zu Retrieval-Augmented Generation nach 2023."
* "Lies den PDF-Anhang dieses Zotero-Eintrags und fasse den Kernbeitrag zusammen."
* "Liste Einträge in meiner Machine-Learning-Sammlung auf und finde fehlende Jahresangaben."
## Sicherheitsempfehlungen [#sicherheitsempfehlungen]
* Teile die MCP Server URL nur mit Clients, denen du vertraust.
* Sei vorsichtig mit Werkzeugen, die in deine Zotero-Bibliothek schreiben, etwa Notizen erstellen, Metadaten bearbeiten oder Tags und Sammlungen verwalten.
* Schalte den Server aus, wenn du MCP nicht verwendest.
* Wenn sich ein externer Client unerwartet verhält, stoppe den MCP-Server und prüfe die Client-Konfiguration.
## FAQ [#faq]
Nein. Der In-Plugin-Chat kann BibGenies interne Funktionen direkt verwenden. MCP ist nur für externe Clients gedacht.
Nein. Es ist ein lokaler Dienst, der in deiner Zotero- und BibGenie-Umgebung läuft.
Stelle sicher, dass der MCP-Server aktiviert ist, die URL korrekt kopiert wurde, Zotero läuft und Test Connection erfolgreich ist. Wenn Zotero einen benutzerdefinierten HTTP-Port verwendet, nutzt die URL möglicherweise nicht `23119`.
Nein. Die Browser-Adresszeile sendet einen GET-Request, während MCP-Clients POST JSON-RPC verwenden. Verwende Test Connection oder konfiguriere einen MCP-Client.
MCP-Clients laden und cachen Werkzeuglisten. Starte den externen Client neu, stelle sicher, dass BibGenie aktualisiert ist, und verbinde den MCP-Server erneut.
Ja. Die von **BibGenie** bereitgestellte grundlegende Zotero-MCP-Verbindung ist kostenlos. Du kannst damit jeden Client verbinden, der MCP unterstützt.
# Metadaten-Überprüfung & Bereinigung (/de/docs/metadata-review)
Die Überprüfung und Bereinigung von Metadaten ist eine Kernfunktion von BibGenie. Aus wissenschaftlichen Webseiten, PDFs oder Standard-Extraktoren importierte Einträge weisen oft unvollständige Metadaten auf (fehlende Zusammenfassungen, DOIs, Seitenzahlen oder Journale), Titel in reinen Großbuchstaben, fehlende Journal-Standardabkürzungen, nicht aktualisierte Preprint-Veröffentlichungen und abgeschnittene Autorenlisten.
BibGenie kombiniert die **wissenschaftliche Urteilskraft von LLMs** mit **etablierten akademischen Datenbanken**. Durch eine strikt schreibgeschützte Überprüfung, transparente Belegnachweise und visuelle Differenzgenehmigungen pflegen Sie mühelos eine konsistente, hochwertige Zotero-Bibliothek.
Der Prüfprozess ist vollständig schreibgeschützt und ändert Ihre Bibliothek nicht heimlich im Hintergrund. Die KI erstellt eine **visuelle Differenzvorschau (Action Preview)**, in der aktuelle Werte und vorgeschlagene Änderungen gegenübergestellt werden. Daten werden erst sicher in Zotero gespeichert, wenn Sie explizit auf „Genehmigen“ klicken.
## Kernfunktionen [#kernfunktionen]
Bündelt arXiv, Semantic Scholar, OpenAlex, DBLP und OpenReview mit intelligentem Routing basierend auf DOI, arXiv-ID oder DBLP-Schlüsseln.
Wählen Sie zwischen `lint` (lokale Formatierung), `blank` (fehlende Felder ergänzen, Standard) und `all` (vollständige Synchronisierung).
Im Gegensatz zu starren Regex-Tools versteht BibGenie wissenschaftliche Begriffe und schützt Bezeichnungen wie `mRNA`, `CRISPR-Cas9`, `PyTorch` sowie römische Ziffern.
Vorher-Nachher-Vergleich, Warnhinweise bei Typkonvertierungen, Erhalt von Better BibTeX Citation Keys und atomarer Rollback bei Fehlern.
## Unterstützte akademische Datenquellen [#unterstützte-akademische-datenquellen]
BibGenie integriert spezialisierte Recherchekanäle für unterschiedliche Fachbereiche und Publikationsformen:
| Quelle | Abdeckung & Besonderheiten | Ideal für |
| :--------------------- | :------------------------------------------------------------------ | :--------------------------------------------------------------------------------------- |
| **OpenAlex** | Über 250 Mio. offene wissenschaftliche Datensätze aller Fachgebiete | Umfassende Recherche, Ergänzung fehlender Basis-Metadaten, Zitationskontexte |
| **arXiv** | Preprint-Repository für Physik, Informatik, Mathematik | Preprint-Metadaten, offizielle Versions-IDs, Verknüpfung zu Verlags-DOIs |
| **DBLP** | Bibliographie für Computer Science | Top-Konferenzen/Journale der Informatik, Autoren-Disambiguierung |
| **OpenReview** | ML- & KI-Konferenzen (ICLR, NeurIPS usw.) | Überprüfung von Konferenztiteln, Schutz anonymer Gutachterautoren, Camera-Ready-Tracking |
| **Semantic Scholar** | Hochpräziser Korpus für Informatik und Biomedizin | Exakte Paper-Identifikatoren, TLDR-Zusammenfassungen, Zitationsanalysen |
| **Zotero Translators** | Zotero-eigene Web- und Verlags-Übersetzer | Direkte Auflösung von Verlagsseiten (IEEE, ACM, Springer, Nature etc.) |
## Drei Überprüfungsmodi [#drei-überprüfungsmodi]
Je nach Anforderung können Sie BibGenie in verschiedenen Modi ausführen:
**Standardmodus**. Fragt wissenschaftliche Quellen ab und **schlägt ausschließlich Aktualisierungen für leere lokale Felder und Autorenlisten vor**:
* Behält vorhandene Titel, Autoren, Jahre und Zeitschriftentitel unverändert bei.
* Ergänzt fehlende Zusammenfassungen (Abstracts), Seitenzahlen (Pages), DOIs, Publikationstitel oder Proceedings-Titel.
* Ideal für den täglichen Bibliotheksausbau.
**Lokaler Standardisierungsmodus**. Überspringt die externe Faktenabfrage und prüft vorhandene Metadaten anhand akademischer Richtlinien:
* Titel-Groß-/Kleinschreibung (Sentence Case).
* Zeitschriftenabkürzungen gemäß LTWA-Standard.
* Präzise ISO-639-1 Sprachcode-Erkennung.
* Erkennt Verlags-Domains, die fälschlicherweise in Metadatenfeldern abgelegt wurden.
* Ideal, wenn alle Metadaten vorhanden sind und lediglich die Formatierung harmonisiert werden soll.
**Vollständiger Synchronisationsmodus**. Sucht externe Daten und **schlägt auch Aktualisierungen bereits ausgefüllter Felder sowie den kompletten Austausch von Autorenlisten vor**:
* Geeignet zur Korrektur fehlerhafter oder veralteter Einträge aus minderwertigen Web-Importen.
* Perfekt geeignet, um Preprints nach offizieller Veröffentlichung in Konferenzen oder Journalen zu aktualisieren und den Eintragstyp anzupassen.
* *Hinweis: Verwenden Sie `all` nicht, wenn lediglich Felder fehlen; nutzen Sie dafür den Modus `blank`.*
## Sicherheit & Ökosystem-Kompatibilität [#sicherheit--ökosystem-kompatibilität]
1. **Nahtlose Better BibTeX-Kompatibilität**:
* Viele Forscher nutzen Better BibTeX für LaTeX-Zitierstile. BibGenies Extra-Feld-Verarbeitung schützt strukturierte Schlüssel wie `Citation Key:`, `tex.*`, `bibtex:` sowie freien Text strikt vor Löschung oder Überschreibung.
2. **Schutz bei Änderung des Eintragstyps**:
* Wenn sich der Typ eines Eintrags ändert (z. B. von `preprint` zu `journalArticle`), warnt die Vorschaukarte ausdrücklich vor Feldern, die eventuell umgewandelt oder nicht unterstützt werden.
3. **Wissenschaftliche Intelligenz statt simpler Heuristik**:
* Starre Algorithmen zerstören häufig molekularbiologische Bezeichnungen oder Softwaredaten. BibGenie nutzt LLM-Fachwissen, um Fehlkorrekturen zu vermeiden.
## Typische Prompt-Beispiele [#typische-prompt-beispiele]
```text
Bitte prüfe das aktuell ausgewählte Paper und ergänze im blank-Modus fehlende Angaben zu Abstract, Seitenzahlen und DOI.
```
```text
Hilf mir, die Groß-/Kleinschreibung der Titel und die Zeitschriftenabkürzungen für die markierten Einträge zu standardisieren. Fachbegriffe bitte unverändert lassen.
```
```text
Dieses Dokument war bisher ein arXiv-Preprint. Prüfe bitte über DBLP oder Semantic Scholar, ob es inzwischen in einer Zeitschrift oder Konferenz erschienen ist, und schlage die Aktualisierung vor.
```
```text
Finde in dieser Sammlung alle Einträge ohne DOI oder Zusammenfassung und starte eine Überprüfung zur Vervollständigung.
```
## Empfohlener Arbeitsablauf [#empfohlener-arbeitsablauf]
**Einträge auswählen**: Markieren Sie in Zotero einen oder mehrere Einträge, fügen Sie diese im Chat mit `@` hinzu oder formulieren Sie Ihre Anfrage direkt.
**KI führt schreibgeschützte Prüfung durch**: BibGenie ruft Datenquellen ab, wendet Qualitätsregeln an und generiert strukturierte Vorschläge.
**Visuelle Differenzkarte prüfen**: Im Chat erscheint eine **Aktionsvorschau (Action Preview)** mit übersichtlicher Gegenüberstellung aller Änderungen.
**Genehmigen und atomar speichern**: Ein Klick auf „Genehmigen“ schreibt die Änderungen atomar in Zotero. Bei Ablehnung bleibt Ihre Bibliothek vollkommen unberührt.
# Modelle (/de/docs/models)
BibGenie unterstützt zwei Arten von Modellen: **offizielle Modelle** und **eigene Modelle**.
* Offizielle Modelle werden von BibGenie gepflegt und funktionieren sofort. Du musst keinen eigenen API-Schlüssel konfigurieren.
* Eigene Modelle werden von dir konfiguriert, einschließlich Provider, Base URL, API-Schlüssel und Modellfähigkeiten.
Beide verwaltest du in den **Model Settings**.
## Offizielle Modelle [#offizielle-modelle]
Es gibt viele KI-Modelle auf dem Markt, aber nur ein kleiner Teil eignet sich gut als Zotero-Agent. BibGenie wählt Modelle nicht nur anhand öffentlicher Benchmarks aus. Entscheidend ist, ob sie echte Forschungsworkflows zuverlässig bewältigen:
* Paper mit langem Kontext lesen
* Mehrere Paper vergleichen
* Komplexes Forschungsdenken unterstützen
* Tool Calling und strukturierte Ausgaben beherrschen
* Multimodale Eingaben wie Abbildungen, Formeln und Screenshots verarbeiten
* Genaue, im Zotero-Kontext verankerte Antworten liefern
Auch die Provider-Konfiguration ist wichtig. Dasselbe Modell kann sich je nach Provider stark unterscheiden, etwa wegen Kontextlimits, Tool-Calling-Unterstützung, Rate Limits, Parameter-Defaults und Netzwerkzuverlässigkeit.
Damit Nutzer weniger konfigurieren müssen, tut BibGenie mehrere Dinge:
Wir testen ausgewählte Modelle in Workflows für Paper-Lektüre, Literatursuche, Bibliotheksverwaltung und Notizen.
Wenn möglich, besprechen wir empfohlene Bereitstellungs- und Nutzungsmuster mit Modell- oder Provider-Teams.
Wir arbeiten mit ausgewählten Providern zusammen, damit Modelle so bereitgestellt werden, dass sie gut mit BibGenie funktionieren.
Wir benchmarken Modell-Provider-Kombinationen und pflegen eine Empfehlungsliste.
## Eigene Modelle [#eigene-modelle]
Wenn du einen eigenen API-Schlüssel hast oder ein lokales Modell nutzen möchtest, kannst du ein eigenes Modell hinzufügen.
Eigene Modelle sind nützlich, wenn:
* Du bereits für einen Provider wie OpenAI, Anthropic, DeepSeek oder OpenRouter zahlst.
* Deine Institution verlangt, dass Anfragen direkt an einen bestimmten Provider gesendet werden.
* Du Ollama oder LM Studio lokal verwenden möchtest.
* Du ein Modell brauchst, das derzeit nicht in der offiziellen Liste enthalten ist.
Siehe [Custom Models](/docs/custom-models) für die Einrichtung.
## Was bedeuten die Multiplikatoren? [#was-bedeuten-die-multiplikatoren]
Nach einem Modellnamen siehst du eventuell Labels wie `0x`, `1.5x` oder `2x`.
Diese Labels zeigen ungefähr an, wie schnell ein Modell Credits verbrauchen kann:
| Label | Bedeutung |
| :-------------- | :---------------------------------------------------------------------------------------------------------------- |
| `1x` | Standard-Verbrauchsgeschwindigkeit. |
| `1.5x` | Kann für eine ähnliche Aufgabe schneller Credits verbrauchen als ein Standardmodell. |
| `2x` oder höher | Weist normalerweise auf ein teureres Modell hin, das eher für anspruchsvollere Aufgaben reserviert werden sollte. |
Multiplikatoren sind ein nutzerorientierter Hinweis. Die tatsächliche Credit-Nutzung wird aus Eingabetokens, Ausgabetokens, Modellpreisen und Tool-Nutzung berechnet.
## Modellliste aktualisieren [#modellliste-aktualisieren]
Die offizielle Modellliste wird automatisch aktualisiert. Du kannst sie auch manuell aktualisieren:
Öffne BibGenie.
Gehe zu **Model Settings**.
Klicke im Bereich der offiziellen Modelle auf **Refresh**.
Wenn ein Modell fehlt, kann das folgende Gründe haben:
* Deine Plugin-Version ist veraltet.
* Die Modellliste wurde noch nicht aktualisiert.
* Das Modell ist vorübergehend nicht verfügbar oder wird angepasst.
* Dein Kontostatus wurde noch nicht synchronisiert.
## Ein Modell auswählen [#ein-modell-auswählen]
Beginne mit einem offiziellen Modell mit niedrigem Multiplikator.
Verwende ein offizielles Modell mit zuverlässigem Kontextmanagement und hoher Ausgabequalität.
Verwende ein Modell mit stärkerer Reasoning-Fähigkeit und längerem Kontextfenster.
Verwende BYOK, einen eigenen Provider, Ollama oder LM Studio.
# OpenAlex-Recherche (/de/docs/openalex-research)
OpenAlex Research ist in BibGenie v0.7.0 verfügbar und hilft dir, den öffentlichen wissenschaftlichen Katalog außerhalb deiner Zotero-Bibliothek zu durchsuchen. Nutze es, um neue Arbeiten zu entdecken, Autoren oder Institutionen zu finden, Forschungstrends zu analysieren oder Zitationen um eine bekannte Arbeit herum zu kartieren.
OpenAlex-Ergebnisse sind externe bibliografische Metadaten. Sie bedeuten nicht, dass eine Arbeit bereits in Zotero gespeichert ist, und sie ersetzen nicht das Lesen der Quelle.
OpenAlex Search steht allen Nutzern zur Verfügung. Im Free-Tarif kostet jeder erfolgreiche OpenAlex-Tool-Aufruf **1 Credit**; kostenpflichtige Tarife enthalten diese Aufrufe **ohne zusätzliche Credit-Kosten**.
## Was damit möglich ist [#was-damit-möglich-ist]
Suche in öffentlichen wissenschaftlichen Aufzeichnungen nach Thema, genauer Phrase, DOI, PMID, PMCID, OpenAlex ID und unterstützten Filtern oder Sortierfeldern.
Finde stabile OpenAlex-IDs für Autoren, Institutionen, Zeitschriften, Themen, Verlage und Fördergeber.
Finde Arbeiten, die eine Ausgangsarbeit zitieren, von ihr referenzierte Arbeiten oder verwandte Werke.
Gruppiere und zähle Ergebnisse nach Veröffentlichungsjahr, Open-Access-Status, Land, Quelle, Thema oder einem anderen unterstützten Feld.
## Wann OpenAlex verwenden [#wann-openalex-verwenden]
Verwende OpenAlex, wenn deine Frage öffentliche wissenschaftliche Aufzeichnungen außerhalb deiner aktuellen Zotero-Bibliothek betrifft:
* Finde aktuelle Arbeiten zu einem Forschungsthema.
* Entdecke einflussreiche ältere Arbeiten oder Übersichtsartikel.
* Verfolge Zitationen um eine DOI oder OpenAlex Work-ID.
* Ziehe eine Zufallsstichprobe passender Einträge, wenn du explorative Abdeckung statt reiner Relevanz- oder Zitationsanzahl-Ranking möchtest.
* Vergleiche Publikationsaktivität nach Jahr, Quelle, Institution, Land, Thema oder Fördergeber.
* Identifiziere Autoren, Zeitschriften, Institutionen, Verlage oder Fördergeber, bevor du Arbeiten nach ihnen filterst.
Verwende stattdessen die Zotero-Bibliothekssuche, wenn du nach gespeicherten Einträgen, ausgewählten Arbeiten, Sammlungen, Tags, Notizen oder angehängten PDFs fragst.
OpenAlex kann Arbeit identifizieren, die eine nähere Betrachtung wert ist, fügt sie aber nicht automatisch zu Zotero hinzu. Frage BibGenie ausdrücklich, bevor du Zotero-Einträge importierst, taggst, verschiebst oder bearbeitest.
## Beispiele zur Nutzung [#beispiele-zur-nutzung]
```text
Durchsuche OpenAlex nach aktuellen Übersichtsarbeiten zu Retrieval Augmented Generation nach 2023. Gib Titel, Jahr, Quelle, Autoren, Zitationsanzahl, DOI und eine Begründung zurück, warum jedes Ergebnis nützlich sein könnte.
```
```text
Nutze OpenAlex, um Arbeiten von Geoffrey Hinton über Deep Learning zu finden. Löse zuerst den Autor auf, liste dann die meistzitierten Werke mit Jahr, Quelle, DOI und Zitationsanzahl auf.
```
```text
Nutze OpenAlex, um Arbeiten zu erkunden, die 10.48550/arXiv.1706.03762 zitieren. Konzentriere dich auf Arbeiten nach 2021 und erkläre, welche für die LLM-Forschung am relevantesten erscheinen.
```
```text
Nutze OpenAlex, um Publikationstrends für Graph Neural Networks von 2018 bis 2025 zu analysieren. Gruppiere nach Veröffentlichungsjahr und fasse den Trend sorgfältig zusammen.
```
## Empfohlener Arbeitsablauf [#empfohlener-arbeitsablauf]
Beginne mit einer breiten OpenAlex-Suche mit einer kleinen Ergebnisanzahl.
Bitte BibGenie, nach Jahr, Arbeitstyp, Open-Access-Status, Quelle, Autor, Institution oder Thema zu verfeinern.
Frage bei einer vielversprechenden Ausgangsarbeit nach Zitationsnachbarn, Referenzen oder verwandten Werken.
Füge nur die relevantesten Kandidaten zu Zotero hinzu, nachdem du die Ergebnisse geprüft hast.
## Gute Prompt-Muster [#gute-prompt-muster]
```text
Durchsuche OpenAlex nach Arbeiten über KI-Tools im akademischen Schreiben. Bevorzuge Übersichtsartikel nach 2020 und gib maximal 10 Ergebnisse zurück.
```
```text
Finde den OpenAlex-Eintrag für diese DOI und zeige dann die zitierenden und verwandten Arbeiten an:
10.1038/nature12373
```
```text
Löse Stanford University in OpenAlex auf und finde dann hochzitierte Arbeiten über Human-Computer-Interaction von dieser Institution seit 2020.
```
```text
Durchsuche zuerst meine Zotero-Bibliothek nach Arbeiten über LLM-Agenten, dann nutze OpenAlex, um externe Arbeiten zu finden, die mir möglicherweise entgehen. Halte Zotero-Ergebnisse und externe OpenAlex-Ergebnisse getrennt.
```
## Wichtige Grenzen [#wichtige-grenzen]
* OpenAlex liefert Metadaten wie Titel, Autoren, Jahr, Quelle, DOI, Open-Access-Status und Zitationsanzahl.
* Behandle die Zitationsanzahl nicht als Qualitätsnachweis.
* Leite Methoden, Behauptungen oder Ergebnisse nicht allein aus Metadaten ab.
* Für genaues Lesen füge die Arbeit zu Zotero hinzu oder stelle lesbaren Volltext bereit und bitte BibGenie, den Quellinhalt zu lesen.
# Absatzgenaue Zitate (/de/docs/paragraph-citations)
Beim Lesen wissenschaftlicher Literatur reicht es nicht, wenn eine Antwort nur „richtig aussieht“. Ein wirklich verlässlicher KI-Leseassistent muss eine strengere Frage beantworten können:
**Wo genau steht diese Aussage im Paper?**
Dafür sind absatzgenaue Zitate in BibGenie gedacht. Sie führen zentrale Aussagen in KI-Antworten bis zu konkreten Textblöcken im PDF zurück. Klickst du auf eine Zitiermarke in der Antwort, springst du direkt zurück in den Zotero PDF Reader und siehst die passende Stelle im Original hervorgehoben.
Das soll Antworten nicht bloß „akademischer“ aussehen lassen. Der eigentliche Wert ist: Jede wichtige Einschätzung der KI kannst du noch einmal prüfen, nachlesen und selbst bestätigen.
Absatzgenaue Zitate machen aus einer KI-Antwort nicht nur „hier ist das Ergebnis“, sondern „hier ist der Beleg dafür“: Du klickst auf die Zitiermarke und landest direkt beim passenden Absatz im PDF.
## Was unterscheidet absatzgenaue Zitate von normalen Zitaten? [#was-unterscheidet-absatzgenaue-zitate-von-normalen-zitaten]
Zitate können unterschiedlich genau sein. Und je nach Genauigkeit kannst du ganz andere Dinge beurteilen:
| Zitiergenauigkeit | Was du erfährst | Geeignet für | Reicht das beim genauen Lesen? |
| :---------------- | :--------------------------------------------------- | :--------------------------------------------------------------------- | :------------------------------------------------------------ |
| Literaturgenau | Aus welchem Paper die Antwort ungefähr stammt | Überblickslesen, Literaturlisten, schneller Hintergrund | Zu grob; du kennst nur die Quelle |
| Seitengenau | Auf welcher PDF-Seite die Antwort ungefähr steht | Eine Seite schnell wiederfinden | Immer noch recht grob; eine Seite enthält zu viel Information |
| **Absatzgenau** | **Welcher Textblock im Original zur Antwort gehört** | **Genaues Lesen, Fakten prüfen, Notizen schreiben, Reviews erstellen** | **Du kannst den Beleg direkt prüfen** |
Literaturgenaue Zitate nennen dir die Quelle, seitengenaue Zitate bringen dich zur Seite, **absatzgenaue Zitate lassen dich den Beleg direkt prüfen**.
BibGenie will dir nicht nur sagen: „Dieses Paper stützt diese Antwort.“ Es zeigt dir: „Diese Originalstelle stützt diese Antwort.“ Für Forschende ist das viel wichtiger. Du brauchst nicht einfach ein fertiges Ergebnis, sondern die Möglichkeit, selbst zu beurteilen, ob das Ergebnis trägt.
## Von „Antwort geben“ zu „Belege zeigen“ [#von-antwort-geben-zu-belege-zeigen]
Früher bedeutete KI-gestütztes Paper-Lesen oft vor allem: „Fass mir das Paper zusammen.“
Das ist natürlich nützlich. Du bekommst schnell einen Eindruck von Inhalt, Methode und Ergebnissen. Aber bei ernsthafter Literaturarbeit kostet meist nicht das grobe Verstehen die meiste Zeit, sondern solche Prüfungen:
* Hat der Autor oder die Autorin diese Schlussfolgerung wirklich so formuliert?
* Hat die KI Aussagen aus verschiedenen Absätzen zu stark zusammengezogen?
* Stimmen Details zu Experimenten, Variablendefinitionen und Metriken?
* Ist dieser Satz eine zentrale Aussage der Autorinnen und Autoren oder eine Zusammenfassung der KI?
* Kann ich diesen Punkt guten Gewissens in meine Notizen, meinen Review oder einen Manuskriptentwurf übernehmen?
Wenn die KI nur eine flüssige Antwort liefert, musst du trotzdem zurück ins PDF, suchen, blättern, die Stelle finden und erneut lesen. Das unterbricht nicht nur den Gedankenfluss, sondern führt schnell dazu, dass man die Prüfung ganz sein lässt.
Absatzgenaue Zitate nehmen dir diesen Schritt ab.
Wenn BibGenie auf Basis des PDF-Originaltexts antwortet, fügt es automatisch Zitiermarken wie `[1]` und `[2]` in die Antwort ein. Klickst du auf eine Marke, öffnet BibGenie das passende PDF, springt zur relevanten Seite und hebt den zitierten Absatz im Original hervor.
Anders gesagt: BibGenie sagt dir nicht nur, „was die Antwort ist“, sondern bringt auch „woher die Antwort kommt“ direkt zurück an deinen Leseort.
## Warum absatzgenaue Zitate wichtig sind [#warum-absatzgenaue-zitate-wichtig-sind]
Wissenschaftliches Lesen ist kein Nachrichten-Scrollen. Du willst nicht nur ein Ergebnis bekommen, sondern verstehen, wie dieses Ergebnis durch das Paper gestützt wird.
Deshalb betonen immer mehr KI-Forschung und KI-Produkte Quellenrückverfolgung (source attribution), fundierte Antworten (grounded answers) und Zitierprüfung (citation verification). KI kann Erklärungen erzeugen, die sehr echt wirken. Sie kann auch Zitate erzeugen, die sehr echt wirken. Aber „wirkt echt“ heißt nicht „hält einer Prüfung stand“.
In der Literaturarbeit muss ein verlässliches Zitat drei Bedingungen erfüllen:
1. **Echte Quelle**: Das Zitat darf kein erfundener Literatureintrag sein.
2. **Genaue Stelle**: Das Zitat darf nicht nur auf ein ganzes Paper verweisen, sondern muss die konkrete Belegstelle zeigen.
3. **Passende Aussage**: Der Originaltext muss die gerade gemachte KI-Aussage tatsächlich stützen.
Du musst häufig beurteilen:
* Haben die Autorinnen und Autoren diese Schlussfolgerung wirklich gezogen?
* Hat die KI verschiedene Absätze, Experimente oder sogar verschiedene Paper vermischt?
* Kommen Methodendetails aus dem Haupttext, einer Bildunterschrift, dem Anhang oder aus einer KI-Zusammenfassung?
* Kann ich diese Aussage bedenkenlos in Notizen oder einen Manuskriptentwurf übernehmen?
* Ist dieses Zitat nur „irgendwie relevant“, oder stützt es die konkrete Aussage in der Antwort wirklich?
Klassische KI-Zitate sagen dir meist nur, „welches Paper verwendet wurde“ oder „von welcher Seite es stammt“. Fürs Überblickslesen kann das reichen, beim genauen Lesen aber nicht. Auf einer einzigen PDF-Seite können Forschungsfrage, Methode, Formel, Versuchsaufbau, Ergebnisinterpretation und Limitationen stehen. Eine Seitenangabe sagt nur: „ungefähr hier“. Ein absatzgenaues Zitat grenzt den Beleg auf die Stelle ein, die du wirklich prüfen musst.
## Warum nicht nur Seitenzahlen? [#warum-nicht-nur-seitenzahlen]
Viele KI-Literaturtools liefern Seitenzahlen. Seitenzahlen sind nützlich, aber sie sind nicht das Ziel.
Eine Seite in einem wissenschaftlichen PDF ist oft extrem dicht. Besonders bei zweispaltigem Satz, Review-Artikeln, Methodenpapieren und medizinischen oder technischen Experimenten kann eine Seite gleichzeitig enthalten:
* zwei bis drei eigenständige Absätze
* eine Tabelle oder Bildunterschrift
* mehrere Formeln
* Versuchsaufbau, Bewertungsmetriken und Ergebnisinterpretation
* einschränkende Hinweise der Autorinnen und Autoren zu Limitationen
Wenn die KI sagt: „Die Autorinnen und Autoren argumentieren, dass die Methode die Generalisierungsfähigkeit verbessert“, und dir nur „siehe Seite 6“ gibt, musst du immer noch selbst herausfinden, ob der Beleg im Ergebnisabschnitt, in einer Ablationsstudie oder in der Diskussion steht.
Absatzgenaue Zitate ersetzen Seitenzahlen nicht. Sie gehen einen Schritt weiter: Du siehst direkt den kleinen Belegbereich, auf den sich die KI bezieht. Das ist besonders hilfreich, wenn auf derselben Seite mehrere Stellen als Beleg infrage kommen.
## Warum nicht immer noch genauer? [#warum-nicht-immer-noch-genauer]
Vielleicht klingt es so, als müssten Zitate möglichst fein sein, am besten für jeden Satz und jede einzelne Behauptung. In echter Literaturarbeit ist ein Beleg aber selten ein isolierter Satz. Autorinnen und Autoren definieren oft erst einen Begriff, beschreiben dann den Versuchsaufbau und erklären im nächsten Satz das Ergebnis. Reißt man nur einen Satz heraus, geht wichtiger Kontext verloren.
Absatzgenaue Zitate sind ein natürlicher Kompromiss:
* genauer als ein ganzes Paper
* leichter zu prüfen als eine ganze PDF-Seite
* mit mehr Kontext als ein einzelner Satz
* mit weniger Rauschen als mehrere Absätze
Das entspricht auch der Art, wie Forschende Papers tatsächlich lesen: Du starrst nicht nur auf einen Satz, sondern liest einen kleinen Abschnitt, verstehst die Bedingungen davor und danach und entscheidest dann, ob er eine Aussage wirklich stützt.
## Wobei dir das hilft [#wobei-dir-das-hilft]
Klicke auf eine Zitiermarke in der Antwort und springe direkt zur Originalstelle im Zotero-PDF. Du musst nicht mehr manuell blättern, nach Stichwörtern suchen oder raten, welchen Absatz die KI verwendet hat.
Wenn die KI Methoden, Ergebnisse oder Limitationen zusammenfasst, kannst du sofort den Originaltext prüfen und beurteilen, ob die Antwort dem Paper treu bleibt.
Für theoretische Definitionen, Versuchsaufbauten, Variablenerklärungen, Aussagen zu Tabellen oder Abbildungen und einschränkende Formulierungen passen absatzgenaue Zitate besser zu echter Forschungsarbeit als reine Seitenzahlen.
Antwort, Zitiermarke, PDF-Seite und hervorgehobener Originaltext bleiben miteinander verbunden, damit deine Rückfragen, Notizen und Einschätzungen eine klare Herkunft haben.
## Typische Anwendungsfälle [#typische-anwendungsfälle]
Wenn du ein Paper gründlich liest, kann BibGenie dir helfen, Forschungsfrage, Methode, Versuchsdesign, wichtigste Ergebnisse und Limitationen zu strukturieren. Früher bekamst du vielleicht eine vollständige Zusammenfassung, musstest aber jeden Beleg einzeln suchen. Jetzt enthält die Antwort anklickbare Zitate, und du kannst Punkt für Punkt ins Original zurückspringen.
```text
Lies dieses Paper genau und fasse es nach „Problem, Methode, Experimente, wichtigste Ergebnisse, Limitationen“ zusammen.
```
KI kann komplexe Inhalte gut in flüssige Formulierungen bringen, aber genau diese Flüssigkeit kann Probleme verdecken. Vielleicht sagt ein Paper nur, dass eine Methode „auf einem bestimmten Datensatz besser abschneidet“, während die KI daraus macht, sie sei „bestehenden Methoden insgesamt überlegen“. Oder das Paper beschreibt „einen beobachteten Trend“, und die KI schreibt, die Autorinnen und Autoren hätten „einen Mechanismus bewiesen“. Absatzgenaue Zitate bringen dich schnell zurück zur Originalstelle, damit du prüfen kannst, ob die Formulierung der KI über das hinausgeht, was im Paper steht.
```text
Liste die 5 Schlussfolgerungen in diesem Paper auf, die am leichtesten missverstanden oder zu stark verallgemeinert werden könnten.
```
Gute Literaturnotizen halten nicht nur fest, „was dieses Paper sagt“, sondern auch, „warum ich es so verstehe“. Absatzgenaue Zitate helfen dir, KI-generierte strukturierte Notizen mit den Originalbelegen zu verbinden. Wenn du später zurückkommst, kannst du direkt zum damaligen PDF-Absatz springen, statt das ganze Paper neu zu durchsuchen.
```text
Erstelle aus diesem Paper einen Entwurf für eine Zotero-Notiz und behalte vor allem Forschungsfrage, Methode, Ergebnisse und Limitationen bei.
```
Bei Literaturreviews sind zwei Dinge besonders riskant: ungenaue Zitate und unklare Herkunft von Aussagen. Wenn du mehrere Paper vergleichst, können absatzgenaue Zitate jedem Vergleichspunkt eine überprüfbare Quelle geben: wie Paper A das Problem definiert, welchen Datensatz Paper B verwendet, welche Limitation Paper C nennt. Jeder Vergleichspunkt führt zurück zum Original. Dadurch kannst du beim Schreiben klar unterscheiden, was die Autorinnen und Autoren sagen, was die KI zusammenfasst und was deine eigene Einschätzung ist.
```text
Vergleiche diese Paper nach Forschungsfrage, methodischen Annahmen, Versuchsaufbau und Limitationen.
```
Methoden- und Experimentdetails dürfen nicht schwammig sein. Datensatzgröße, Baselines, Bewertungsmetriken, Hyperparameter, Ausschlusskriterien, statistische Tests, Ablationsstudien: Wenn du eines dieser Details falsch liest, verschiebt sich das ganze Verständnis danach. Absatzgenaue Zitate lassen dich schnell zu den Absätzen springen, in denen solche Details stehen, und prüfen, ob die KI wichtige Einschränkungen übersehen hat.
```text
Extrahiere den Versuchsaufbau dieses Papers, einschließlich Datensätzen, Baselines, Bewertungsmetriken und wichtigsten Vergleichsergebnissen.
```
## So funktioniert es [#so-funktioniert-es]
Beim Lesen eines PDFs zerlegt BibGenie die Seiten in strukturierte Textblöcke. Jeder Textblock behält Seitenzahl, Lesereihenfolge und Positionsinformationen auf der Seite.
Wenn die KI in einer Antwort einen Textblock zitiert, rendert BibGenie ihn als Zitiermarke wie `[1]` oder `[2]`. Nach dem Klick auf die Marke:
1. öffnet BibGenie das passende Zotero-PDF,
2. springt zur Seite, auf der das Zitat steht,
3. hebt den zitierten Absatz oder Textblock im Original hervor.
Du siehst also nicht „dieses Paper stützt diese Antwort“, sondern „diese Originalstelle stützt diese Antwort“.
## Genaues Lesen mit Belegen [#genaues-lesen-mit-belegen]
Absatzgenaue Zitate helfen dir, eine KI-gestützte Lesegewohnheit aufzubauen, bei der Belege immer greifbar bleiben:
**PDF-Kontext hinzufügen**: Füge den PDF-Anhang aus Zotero zur BibGenie-Unterhaltung hinzu oder stelle direkt Fragen zu dem PDF, das du gerade liest.
**Lesefrage stellen**: Bitte BibGenie zum Beispiel, die Methode zusammenzufassen, das Versuchsdesign zu erklären, Limitationen herauszuarbeiten oder mehrere Paper zu vergleichen.
**Antwortstruktur überfliegen**: Schau dir zuerst die Gesamtstruktur der KI-Antwort an und prüfe, ob sie den roten Faden des Papers erfasst.
**Zitate anklicken und Original prüfen**: Klicke bei Aussagen, die du übernehmen möchtest, auf die Zitiermarke und kontrolliere im Zotero-PDF, ob der hervorgehobene Absatz die Aussage wirklich stützt.
**Weiterfragen oder korrigieren**: Wenn du merkst, dass die KI zu stark verallgemeinert oder Einschränkungen ausgelassen hat, frage weiter: „Formuliere das bitte auf Basis dieser Originalstelle neu.“
Der Sinn dieses Ablaufs ist nicht, dass die KI das Paper für dich fertig liest. Sie soll dich schneller in einen überprüfbaren, genauen Lesemodus bringen.
## Grenzen und Hinweise [#grenzen-und-hinweise]
Absatzgenaue Zitate verbessern die Nachvollziehbarkeit deutlich, aber sie sind keine magische Garantie für Richtigkeit. Achte besonders auf diese Punkte:
* **Relevante Zitierstelle heißt nicht, dass die KI-Erklärung automatisch korrekt ist**: Die KI kann den passenden Absatz gefunden haben und ihn trotzdem falsch verstehen.
* **Die Hervorhebung hilft beim Finden, ersetzt aber kein offizielles Zitierformat**: Für formales Schreiben musst du Zitate weiterhin nach APA, MLA, Chicago, GB/T 7714 oder den Vorgaben deiner Zielzeitschrift formatieren.
* **Die Qualität der PDF-Textebene beeinflusst das Ergebnis**: Scans, schlechte OCR, komplexes Layout oder formellastige Seiten können die Erkennung und Positionierung von Textblöcken erschweren.
* **Abbildungen und Formeln brauchen visuelles Lesen**: Wenn deine Frage von Abbildungen, gescannten Seiten oder visueller Anordnung abhängt, gib am besten zusätzlich einen Screenshot oder ein Seitenbild mit.
* **KI ersetzt nicht dein wissenschaftliches Urteil**: Absatzgenaue Zitate machen das Prüfen bequemer, aber die endgültige Einschätzung sollte sich auf den Originaltext, das Studiendesign und dein Fachverständnis stützen.
Lass BibGenie den Suchbereich für dich eingrenzen. Danach entscheidest du selbst, ob die Originalstelle eine bestimmte Schlussfolgerung wirklich trägt.
## Empfehlungen [#empfehlungen]
* Gewöhne dir an, bei wichtigen Schlussfolgerungen, Daten, Versuchsanordnungen und Autorenaussagen die Zitiermarke anzuklicken und den Originaltext zu prüfen.
* Wenn die KI zu allgemein formuliert, frage nach: „Formuliere das bitte auf Basis des Originaltexts an der zitierten Stelle neu.“
* Bei gescannten PDFs oder schlechter Textebene kann die Zitierpositionierung leiden; gib dann am besten zusätzlich ein Seitenbild mit.
* Behandle KI-Antworten beim formalen Schreiben als Lesehilfe und nimm den Paper-Originaltext als endgültige Grundlage.
* Wenn du mehrere Paper vergleichst, prüfe zuerst die Belege der einzelnen Paper und lies danach BibGenies Synthese.
* Bei unbekannten Fachbegriffen: Klicke zuerst auf das Zitat, lies die Originalstelle und lass dir dann von BibGenie den Kontext erklären.
* Wenn eine Antwort Kausalität, Mechanismen oder statistische Schlussfolgerungen betrifft, geh unbedingt zurück zum zitierten Absatz und prüfe, ob die Autorinnen und Autoren es wirklich so sagen.
Zitiermarken in KI-Antworten werden leicht wie Vertrauensabzeichen gelesen. Wenn man `[1]` oder `[2]` sieht, fühlt sich die Aussage schnell belegt an.
Nützlicher ist eine andere Gewohnheit: Behandle das Zitat als Einstieg.
Öffne es, geh zurück zum Original und prüfe drei Dinge:
1. Spricht der Originaltext wirklich über diese Frage?
2. Welchen Ton hat der Originaltext: starke Schlussfolgerung, vorsichtige Beobachtung oder hypothetische Diskussion?
3. Hat die KI Bedingungen, Geltungsbereiche oder Gegenbeispiele ausgelassen?
Dieser Schritt kostet nur ein paar Sekunden, senkt aber deutlich das Risiko, etwas „gelesen, aber nicht geprüft“ zu haben. Besonders beim Schreiben von Reviews, bei Projektpräsentationen oder beim Entwickeln von Forschungshypothesen wirkt sich diese Prüfung direkt auf die Verlässlichkeit deiner weiteren Arbeit aus.
# Preise & Credits (/de/docs/pricing-credits)
BibGenie verwendet Credits, um die Nutzung offizieller Modelle zu messen. Credits sind nicht dasselbe wie die Anzahl der Anfragen: Die Kosten einer Anfrage hängen vom Modell, der Kontextlänge, der Ausgabelänge und der Tool-Nutzung ab.
Alle Tarife können OpenAlex, Web Search und Web Extract verwenden. Im Free-Tarif kostet jeder erfolgreiche externe Tool-Aufruf 1 Credit; kostenpflichtige Tarife enthalten diese Aufrufe ohne zusätzliche Credit-Kosten und bieten mehr monatliche Credits. Max bietet die meisten monatlichen Credits für intensive Lese-, Vergleichs- und Review-Workflows.
## Planvergleich [#planvergleich]
| Plan | Preis | Monatliche Credits | Hauptfunktionen |
| :---------- | :------------ | :--------------------- | :------------------------------------------------------------------------------------------ |
| Free | $0 | 200 Credits / Monat | Kernfunktionen + OpenAlex, Web Search und Web Extract für 1 Credit pro erfolgreichem Aufruf |
| Pro Monthly | $9.99 / Monat | 10.000 Credits / Monat | Alles aus Free + keine zusätzlichen Credits für externe Tool-Aufrufe |
| Pro Yearly | $99 / Jahr | 10.000 Credits / Monat | Alles aus Pro Monthly |
| Max Monthly | $30 / Monat | 35.000 Credits / Monat | Alles aus Pro + mehr Raum für Deep Reading, Vergleich und Review-Erstellung |
| Max Yearly | $295 / Jahr | 35.000 Credits / Monat | Alles aus Max Monthly |
| Lifetime | $199 einmalig | 10.000 Credits / Monat | Langfristige Pro-Vorteile |
Preise, Rabatte und Aktionen können sich ändern. Der endgültige Preis ist der Preis, der auf der Pricing-Seite und in Stripe Checkout angezeigt wird.
## Credit Booster [#credit-booster]
Kostenlose und zahlende Nutzer können ein zusätzliches Credit-Paket kaufen:
| Paket | Menge | Preis | Ablauf |
| :------ | :------------ | :---- | :------- |
| Booster | 5.000 Credits | $6.99 | 6 Monate |
## Wie Credits verbraucht werden [#wie-credits-verbraucht-werden]
Die Credit-Nutzung wird vor allem beeinflusst durch:
* Modellauswahl: teurere Modelle verbrauchen Credits normalerweise schneller.
* Eingabelänge: PDFs, Notizen, Snapshots, Bilder und Chatverlauf erhöhen die Eingabetokens.
* Ausgabelänge: lange Reviews, lange Tabellen und vollständige Notizen verbrauchen mehr Tokens.
* Tool-Nutzung: Suche, Lesen von Anhängen, Websuche und Web-Extraktion können mehrere Modellaufrufe auslösen.
* **Externe Tools**: Im Free-Tarif kostet jeder erfolgreiche OpenAlex-, Web-Search- oder Web-Extract-Aufruf **1 Credit**. Kostenpflichtige Tarife enthalten diese Aufrufe **ohne zusätzliche Credit-Kosten**. Die Modellnutzung im Gespräch wird separat abgerechnet.
* Modellmultiplikator: Labels wie `1.5x` oder `2x` geben einen ungefähren Nutzungshinweis.
Eigene Modelle, Ollama und LM Studio nutzen nicht den offiziellen Modelldienst von BibGenie und verbrauchen daher keine BibGenie-Credits. Kosten oder Rechenaufwand werden von deinem Provider oder deinem lokalen Rechner getragen.
## Wie viele Credits verbraucht das Lesen eines Papers? [#wie-viele-credits-verbraucht-das-lesen-eines-papers]
Es gibt keinen festen Wert. Der Credit-Verbrauch hängt vom gewählten Modell, Eingabekontext, der Ausgabelänge und den aktuellen Modellpreisen ab. Den genauen Betrag jeder Anfrage findest du auf der Usage-Seite.
## Was passiert, wenn Credits aufgebraucht sind? [#was-passiert-wenn-credits-aufgebraucht-sind]
Wenn dein Credit-Guthaben nicht ausreicht, können offizielle Modellanfragen möglicherweise nicht fortgesetzt werden. Du kannst:
* Auf die nächste monatliche Aktualisierung warten.
* Auf Pro, Max oder Lifetime upgraden.
* Einen Credit Booster kaufen.
* BYOK oder ein lokales Modell verwenden.
## Guthaben prüfen [#guthaben-prüfen]
Nach der Anmeldung synchronisiert BibGenie deinen Kontostatus und dein Credit-Guthaben. Du kannst dein Guthaben auch im Konto-Bereich der Website oder auf der Plugin-Nutzerseite prüfen.
# Schnell-Prompts (/de/docs/quick-prompts)
Quick Prompts sind wiederverwendbare Kürzel für wiederkehrende Forschungsaufgaben. Speichere Prompts, die du häufig nutzt, füge sie schnell in das Eingabefeld ein und passe sie an den aktuellen Kontext an.
## Wofür eignen sich Quick Prompts? [#wofür-eignen-sich-quick-prompts]
Forschungsfragen, Methoden, Beiträge, Einschränkungen und zukünftige Arbeiten zusammenfassen.
Markierten Text übersetzen, englische Absätze verbessern oder den akademischen Ton anpassen.
Claims extrahieren, Vergleichstabellen erzeugen und verwandte Arbeiten organisieren.
Annahmen, methodische Schwächen, Evidenzstärke und Reproduzierbarkeit analysieren.
## Quick Prompt erstellen [#quick-prompt-erstellen]
Öffne BibGenie und gehe zu **Prompts Settings**.
Klicke auf die Hinzufügen-Schaltfläche, um einen neuen Quick Prompt zu erstellen.
Gib Name, Prompt-Inhalt, Beschreibung und Tags ein.
Verwende den Toggle, um zu steuern, ob der Prompt auf der Chat-Seite erscheint.
Speichere deine Einstellungen und kehre zum Chat zurück.
## Quick Prompt verwenden [#quick-prompt-verwenden]
Klicke auf der Chat-Seite auf einen Quick Prompt oder suche ihn im Prompt-Menü. Nach dem Einfügen wird er Teil der aktuellen Eingabe, sodass du ihn weiter bearbeiten, Kontext hinzufügen oder ein Ausgabeformat angeben kannst.
Beispiel:
```text
Based on the paper I added, please use the following structure:
1. Research question
2. Method and data
3. Core findings
4. Limitations
5. How I might cite this paper
```
## Quick Prompts vs. Custom Instructions [#quick-prompts-vs-custom-instructions]
| Typ | Geltungsbereich | Am besten für |
| :------------------ | :----------------------------------- | :-------------------------------------------------------------------------- |
| Quick Prompts | Die aktuelle Eingabe | Aufgabenvorlagen wie Zusammenfassung, Übersetzung, Vergleich und Extraktion |
| Custom Instructions | Längerfristige Verhaltenspräferenzen | Antwortsprache, Ton, Rolle und Formatierungspräferenzen |
Lege stabile persönliche Präferenzen in Custom Instructions ab und aufgabenspezifische Workflows in Quick Prompts.
## System Prompt [#system-prompt]
System Prompts steuern das globale Verhalten der KI über alle Konversationen hinweg. Anders als Quick Prompts (die nur die aktuelle Eingabe betreffen) wirkt ein System Prompt **global** — jede Konversation folgt derselben Anweisung.
Beispiel für einen System Prompt:
```text
Always respond in English. Use academic writing conventions appropriate for computer science.
```
Damit folgt jede Antwort automatisch dieser Anweisung, ohne sie wiederholen zu müssen.
Du kannst einen System Prompt in den **Prompts Settings** festlegen. Der Standardwert ist `Always respond in English.` Du kannst ihn an deine bevorzugte Antwortsprache, deinen Ton, deine Rolle oder deinen Formatierungsstil anpassen.
## Quick Prompt-Konfiguration [#quick-prompt-konfiguration]
Jeder Quick Prompt hat folgende Felder:
Erforderlich. Wenn aktiviert, wird dieser Name als Schaltfläche über dem Chat-Eingabefeld angezeigt.
Erforderlich. Der Text, der als Kontext an das KI-Modell gesendet wird.
Optional. Beschreibt den Zweck des Prompts, wird beim Überfahren mit der Maus angezeigt.
Optional. Dient der Kategorisierung und Filterung bei der Verwaltung vieler Prompts.
## Beispielvorlagen [#beispielvorlagen]
```text
Read the paper I added and summarize it using this structure:
- Research question
- Core hypothesis
- Method and data
- Main findings
- Limitations
- Relevance to my current research
```
```text
Explain the selected text I added:
- What is the passage saying?
- What are the key concepts?
- How does it relate to the paper's main argument?
- What should I be careful about if I cite it?
```
```text
Extract material from these papers for a literature review:
- Core claim of each paper
- Agreements and disagreements between papers
- Themes that can be synthesized
- Remaining research gaps
```
# Als Notiz speichern (/de/docs/save-as-note)
Save as Note verwandelt nützliche BibGenie-Antworten in Zotero-Notizen, die du behalten, durchsuchen und in deinem Forschungsworkflow wiederverwenden kannst.
## Zwei Möglichkeiten zum Speichern [#zwei-möglichkeiten-zum-speichern]
Sag BibGenie: "Save the summary above as a note for this paper."
Klicke bei der letzten Assistentenantwort auf **Save as Note**, um die neueste Antwort zu speichern.
## Unterstützte Inhalte [#unterstützte-inhalte]
BibGenie konvertiert Markdown- / HTML-Inhalte in Zotero-Notizen. Häufig unterstützte Inhalte sind:
* Überschriften und Absätze
* Nummerierte und unnummerierte Listen
* Mathematische Formeln
* Codeblöcke
* Tabellen
* Zitate und Links
* Fettdruck und Inline-Code
Zotero-Notizen haben einen eigenen Editor und eigene HTML-Unterstützung. Die meisten gängigen Formate funktionieren gut, sehr komplexes Markdown oder eigenes HTML kann jedoch vereinfacht werden.
## Logik für übergeordnete Einträge [#logik-für-übergeordnete-einträge]
Beim Speichern einer Notiz legt BibGenie sie am passendsten Ort ab, den es bestimmen kann.
| Eingabe | Ergebnis |
| :-------------------------------------------- | :--------------------------------------------------------------------------------------------------------------- |
| Normaler Eintrag angegeben | Erstellt eine untergeordnete Notiz unter diesem Eintrag |
| PDF-Anhang angegeben | Findet nach Möglichkeit den regulären übergeordneten Eintrag des Anhangs und hängt die Notiz dort an |
| Untergeordnete Notiz angegeben | Findet nach Möglichkeit den regulären übergeordneten Eintrag der Notiz und hängt die Notiz dort an |
| Kein übergeordneter Eintrag angegeben | Erstellt eine eigenständige Notiz |
| Übergeordneter Eintrag und Sammlung angegeben | Die Sammlung wird ignoriert, weil Zotero-Kindnotizen die Sammlungszugehörigkeit vom übergeordneten Eintrag erben |
## Beispiele [#beispiele]
```text
Save the paper summary above as a Zotero note for this item, titled "Paper Summary".
```
```text
Turn the comparison above into a literature review note and save it to Zotero.
```
```text
Convert the method section into reproducible experimental steps and save it as a note. Preserve code blocks and tables.
```
## Tipps [#tipps]
* Bitte BibGenie, die Antwort vor dem Speichern zu strukturieren.
* Bitte BibGenie bei langen Unterhaltungen zuerst, "rewrite this as a note" auszuführen, und speichere danach.
* Wenn die Notiz zu einem bestimmten Paper gehören soll, nenne den Ziel-Eintrag ausdrücklich.
* Wenn du eine eigenständige Notiz möchtest, sage, dass sie nicht an ein Paper angehängt werden soll.
# Semantischer Index (/de/docs/semantic-index)
Der Semantic Index treibt die semantische Literatursuche von BibGenie an. Er indexiert Titel und Abstracts regulärer Zotero-Einträge lokal, sodass du ein Forschungsthema in natürlicher Sprache beschreiben kannst, statt nur auf Schlüsselwörter angewiesen zu sein.
## Was wird indexiert? [#was-wird-indexiert]
Der semantische Index konzentriert sich derzeit auf reguläre Zotero-Einträge:
* Titel
* Abstract
* Ausgewählte Metadaten, die für die Suche nützlich sind
Semantic Search ist nicht dasselbe wie PDF-Volltextsuche. Wenn ein Paper keinen Abstract oder unvollständige Metadaten hat, kann die semantische Trefferqualität geringer sein.
## Statusübersicht [#statusübersicht]
| Status | Bedeutung |
| :------------ | :------------------------------------------- |
| bootstrapping | Die Indexierungsfunktion wird initialisiert |
| indexing | Der Index wird aufgebaut |
| updating | Bestehende Indexeinträge werden aktualisiert |
| idle | Der Index ist bereit |
| error | Ein Indexierungsfehler ist aufgetreten |
## Metriken [#metriken]
| Metrik | Bedeutung |
| :------------ | :-------------------------------------------------------- |
| Indexed Count | Anzahl erfolgreich indexierter Einträge |
| Failed Count | Anzahl der Einträge, deren Indexierung fehlgeschlagen ist |
| Message | Aktueller Status oder Fehlermeldung |
## Wann du den Semantic Index prüfen solltest [#wann-du-den-semantic-index-prüfen-solltest]
* Die semantische Suche liefert sehr wenige Ergebnisse.
* BibGenie meldet, dass der semantische Index nicht verfügbar ist.
* Neu importierte Papers erscheinen nicht in der semantischen Suche.
* Failed Count steigt weiter an.
* Zotero wurde gerade gestartet und der Index befindet sich noch im Bootstrapping oder in der Indexierung.
## Fehlerbehebung [#fehlerbehebung]
Öffne die Einstellungen und prüfe den Status von Semantic Index.
Wenn der Index gerade indexing oder updating ist, warte, bis der Vorgang abgeschlossen ist.
Wenn es fehlgeschlagene Einträge gibt, starte die Indexierung für diese Einträge erneut.
Prüfe, ob die relevanten Papers Titel und Abstracts haben.
Wenn Fehler weiterhin auftreten, starte Zotero neu und prüfe erneut.
## Tipps [#tipps]
* Vollständige Abstracts verbessern die Qualität der semantischen Suche.
* Verwende Beschreibungen in natürlicher Sprache statt nur einzelner Schlüsselwörter.
* Kombiniere die semantische Suche mit Filtern nach Jahr, Tag oder Sammlung.
* Nachdem du Kandidaten gefunden hast, füge PDFs oder Notizen als Kontext für die vertiefte Lektüre hinzu.
# Wie BibGenie deine Bibliothek versteht (/de/docs/semantic-understanding)
## Warum es diese Seite gibt [#warum-es-diese-seite-gibt]
Wenn du in BibGenie suchst, geht es nicht nur darum, Papers zu finden, die exakt dieselben Wörter enthalten, die du eingegeben hast. Oft möchtest du, dass BibGenie Papers findet, die **dieselbe Idee behandeln**, auch wenn sie andere Begriffe verwenden.
Hier kommen **Embeddings** und **Indexierung** ins Spiel.
## Was ist ein Embedding? [#was-ist-ein-embedding]
Ein Embedding ist eine Methode, ein Textstück in eine numerische Darstellung umzuwandeln, die seine Bedeutung erfasst.
Du musst die Mathematik dahinter nicht kennen. Die praktische Idee ist einfach:
* Ähnliche Texte erzeugen tendenziell ähnliche Embeddings
* Unterschiedliche Themen erzeugen tendenziell weiter entfernte Embeddings
* So kann BibGenie Bedeutung vergleichen, nicht nur exakte Wörter
Ein Paper über *drug discovery with knowledge graphs* kann zum Beispiel gefunden werden, wenn du nach *graph methods for biomedical research* suchst, auch wenn der Wortlaut nicht identisch ist.
## Wie BibGenie Embeddings nutzt [#wie-bibgenie-embeddings-nutzt]
BibGenie baut die semantische Suche derzeit aus **Titel** und **Abstract** deiner regulären Zotero-Einträge auf.
Der Ablauf:
1. BibGenie liest Titel und Abstract eines Papers.
2. Es wandelt diesen Text in ein Embedding um.
3. Es speichert das Ergebnis in einem lokalen Suchindex für deine Zotero-Bibliothek.
4. Wenn du eine thematische Frage stellst, wandelt BibGenie auch deine Anfrage in ein Embedding um.
5. Es vergleicht deine Anfrage mit den indexierten Papers und gibt die ähnlichsten Treffer zurück.
Deshalb kann semantische Suche Papers finden, die inhaltlich relevant sind, nicht nur wörtlich übereinstimmen.
## Was ist Indexierung? [#was-ist-indexierung]
Indexierung ist der Vorbereitungsschritt, der semantische Suche schnell und praktikabel macht.
Statt bei jeder Suche alles neu zu berechnen, erstellt BibGenie zuerst einen lokalen Embedding-Index deiner Bibliothek. Sobald dieser Index vorhanden ist, kann BibGenie deine Papers deutlich effizienter durchsuchen.
Kurz gesagt:
* **Embedding** hilft BibGenie, Bedeutung darzustellen
* **Indexierung** hilft BibGenie, diese Bedeutung schnell zu durchsuchen
## Wobei hilft das? [#wobei-hilft-das]
Semantische Indexierung ist besonders nützlich, wenn du:
* Papers zu einem Forschungsthema finden möchtest
* Arbeiten entdecken willst, die andere Begriffe für eine ähnliche Idee verwenden
* eine Methode, Theorie oder Problemstellung erkunden möchtest
* eine große Zotero-Bibliothek natürlicher durchsuchen möchtest
Schlüsselwortsuche bleibt nützlich, wenn du Autor, Titel, Begriff oder Formulierung exakt kennst. Semantische Suche ist hilfreicher, wenn deine Frage konzeptionell ist.
## Welche Inhalte werden einbezogen? [#welche-inhalte-werden-einbezogen]
BibGenie verwendet derzeit:
* Paper-Titel
* Paper-Abstracts
BibGenie erstellt diesen semantischen Index derzeit **nicht** aus:
* PDF-Volltext
* Notizen
* Annotationen
* Anhängen
So bleibt die Indexierung fokussiert, vorhersehbar und schnell.
## Muss ich den Index oft neu aufbauen? [#muss-ich-den-index-oft-neu-aufbauen]
Normalerweise **nein**.
Meistens aktualisiert BibGenie den Index automatisch im Hintergrund, wenn sich deine Bibliothek ändert. Wenn du Papers hinzufügst, Einträge änderst oder Elemente entfernst, übernimmt BibGenie normalerweise die notwendigen Updates.
In einigen Situationen kann ein Neuaufbau sinnvoll sein:
* Beim ersten Einrichten der semantischen Indexierung
* Nach dem Wechsel zu einem anderen Embedding-Modell
* Nach einem großen Import, wenn Ergebnisse unvollständig oder veraltet wirken
* Wenn BibGenie meldet, dass der aktuelle Index Aufmerksamkeit benötigt
* Wenn semantische Ergebnisse offensichtlich falsch aussehen und du sauber neu aufbauen möchtest
Wenn die semantische Suche normal funktioniert, musst du meist nichts tun. Baue nur neu auf, wenn die App es vorschlägt oder die Ergebnisse nicht mehr deinen Erwartungen entsprechen.
## Was bedeuten die Buttons auf der Indexing-Seite? [#was-bedeuten-die-buttons-auf-der-indexing-seite]
### Build / Rebuild [#build--rebuild]
Erstellt den Index zum ersten Mal oder baut ihn bei Bedarf vollständig neu auf.
Verwende es, wenn:
* du die Indexierung zum ersten Mal einrichtest
* du das Embedding-Modell geändert hast
* du den gesamten Index aktualisieren möchtest
### Retry Failed Items [#retry-failed-items]
Versucht nur die Papers erneut zu indexieren, die bei früheren Indexierungsversuchen fehlgeschlagen sind.
Verwende es, wenn:
* die Anzahl fehlgeschlagener Einträge größer als null ist
* du vor einem vollständigen Neuaufbau einen leichteren Wiederherstellungsschritt versuchen möchtest
## Häufige Fragen [#häufige-fragen]
Schlüsselwortsuche sucht nach passenden Wörtern. Semantische Suche sucht nach verwandter Bedeutung. Dadurch kann sie relevante Papers finden, auch wenn die Formulierungen unterschiedlich sind.
Ohne Embeddings wäre BibGenie weitgehend von exakten Begriffen abhängig. Embeddings ermöglichen die Suche nach Thema, Konzept und semantischer Ähnlichkeit.
Ein Paper wurde möglicherweise noch nicht indexiert, enthält nicht genug Titel-/Abstract-Inhalt oder der Index benötigt Aufmerksamkeit. Wenn das Problem bestehen bleibt, versuche den Index neu aufzubauen.
Nein. Im normalen Gebrauch ist BibGenie darauf ausgelegt, den Index automatisch zu aktualisieren. Manueller Neuaufbau ist vor allem für Ersteinrichtung, Modellwechsel und Wiederherstellungsszenarien gedacht.
## Nächste Schritte [#nächste-schritte]
* Indexportstatus prüfen und Probleme beheben: [Semantic Index](/docs/semantic-index)
* Semantische Suche in der Praxis einsetzen: [Literature Search](/docs/literature-search)
# Websuche & Web Extract (/de/docs/web-search-extract)
Standardmäßig sucht und liest BibGenie zuerst deine Zotero-Bibliothek. Web Search / Web Extract stehen allen Nutzern zur Verfügung und ergänzen deine Bibliothek um Informationen aus dem öffentlichen Web.
Im Free-Tarif kostet jeder erfolgreiche Web-Search- oder Web-Extract-Aufruf **1 Credit**. Kostenpflichtige Tarife enthalten diese externen Tool-Aufrufe **ohne zusätzliche Credit-Kosten**. Die Modellnutzung im umgebenden Gespräch kann weiterhin regulär Credits verbrauchen.
## Web Search vs. Web Extract [#web-search-vs-web-extract]
Durchsucht das öffentliche Web und gibt gerankte, KI-lesbare Auszüge zurück.
Liest eine bestimmte Webseite und extrahiert ihren Hauptinhalt für die Unterhaltung.
## Wann Webzugriff sinnvoll ist [#wann-webzugriff-sinnvoll-ist]
Web Search / Web Extract ist nützlich, wenn du:
* Die Projektseite, das Code-Repository oder die Datensatzseite eines Papers finden musst.
* Aktuelle Hintergrundinformationen sammeln möchtest.
* Öffentliche Dokumentation zu einem Modell, Tool, einer Institution oder einem Produkt lesen musst.
* Informationen ergänzen möchtest, die noch nicht in deiner Zotero-Bibliothek sind.
* Webseiteninhalte zusammenfassen, extrahieren oder vergleichen möchtest.
Webinhalte können sich ändern und ungenau sein. Für formale Zitate solltest du Informationen gegen das Originalpaper, offizielle Dokumentation oder eine andere maßgebliche Quelle prüfen.
## Aktivieren [#aktivieren]
Melde dich bei deinem BibGenie-Konto an.
Suche die Schaltfläche **Web Search** unter dem Chat-Eingabefeld.
Klicke auf die Schaltfläche, um Web Search ein- oder auszuschalten.
Wenn sie aktiviert ist, bitte BibGenie ausdrücklich, das Web zu durchsuchen oder eine Webseite zu lesen.
## Beispiele [#beispiele]
```text
Search the web to see whether this paper has an official project page, code repository, or dataset page.
```
```text
Read this web page and summarize the parts relevant to my paper topic:
https://example.com
```
```text
First search my Zotero library, then search the web for recent developments in this area.
```
## Datenschutzhinweis [#datenschutzhinweis]
Web-Tools greifen auf öffentliche Webseiten zu. Vermeide es, sensible, unveröffentlichte oder vertrauliche Materialien in Anfragen einzubeziehen, die Webzugriff erfordern. Für private Arbeit nutze stattdessen Zotero-Bibliothekskontext, lokalen Kontext, BYOK oder lokale Modelle.
# Zotero-Annotationen (/de/docs/zotero-annotations)
BibGenie kann direkt mit gespeicherten Zotero-Annotationen arbeiten, darunter Hervorhebungen, Kommentare, Bilder, Freihandzeichnungen und Unterstreichungen. Annotationen lassen sich aus einem bekannten Anhang abrufen oder in der gesamten Bibliothek suchen, jeweils mit einem nachvollziehbaren Link zurück zu Zotero.
## Zwei Annotationswerkzeuge [#zwei-annotationswerkzeuge]
| Werkzeug | Wann verwenden | Umfang und Filter |
| :------------------- | :----------------------------------------------- | :------------------------------------------------------------------------------------------ |
| `get_annotations` | Der PDF-, EPUB- oder Snapshot-Anhang ist bekannt | Gibt seine Annotationen in Lesereihenfolge zurück |
| `search_annotations` | Bibliotheksweite Suche ist nötig | Hervorgehobener Text, Kommentar, Tag, Farbe, Typ, Autor, Anhang, Sammlung und Änderungszeit |
Die Ergebnisse sind seitenweise aufgeteilt. BibGenie lädt die nächste Seite nur bei Bedarf.
`get_annotations` arbeitet mit einem Anhang, nicht mit dem übergeordneten bibliografischen Item. Bei einem normalen Zotero-Item ermittelt BibGenie zuerst den zugehörigen Anhang.
## Zum Chat hinzufügen [#zum-chat-hinzufügen]
* Im Zotero Reader eine oder mehrere gespeicherte Annotationen auswählen, rechtsklicken und **Add to Chat** wählen.
* In der Bibliotheksansicht Annotations-Items auswählen und **Add to Chat** wählen.
* **Reader Annotations** und **Library Items** in den [Add-to-Chat-Einstellungen](/de/docs/add-to-chat-settings) steuern diese Einträge.
Kommentare sind Interpretationen ihrer Autoren und dürfen nicht dem Quelldokument zugeschrieben werden. Zur Funktionsweise von Zitaten siehe [BibGenie Citation](/de/docs/bibgenie-citations).
Ein Klick auf die Referenz öffnet den übergeordneten Anhang und versucht, zur gespeicherten Annotation zu navigieren. BibGenie bearbeitet oder löscht keine bestehenden Annotationen. Bild- und Freihandannotationen können nur wenig durchsuchbaren Text enthalten.
# Zotero Collections & Tags – Leitfaden (/de/docs/zotero-collections-tags-best-practices)
Zoteros Collections und Tags helfen beide bei der Literaturorganisation, lösen aber unterschiedliche Probleme. Eine langfristig wartbare Zotero-Bibliothek verlässt sich selten nur auf Collections oder nur auf Tags. Stattdessen dienen Collections als Projekt- oder Themeneinstieg, Tags als dimensionsübergreifende Suchmerkmale und Saved Searches für dynamische Workflows.
Wenn du BibGenie nutzt, ist dieser Leitfaden mehr als eine Methodik – er wird zu einem ausführbaren Workflow. BibGenies Bibliotheks-Organisationsfunktion kann deine vorhandenen Collections, Tags und Items erfassen, einen Organisationsplan basierend auf deinem Forschungsaufbau vorschlagen und dann (nach deiner Bestätigung) Collections erstellen, Tags hinzufügen oder entfernen, Items verschieben sowie chaotische Tags umbenennen oder zusammenführen.
Collections beantworten: „Zu welchem Projekt, Kurs, Review oder Themeneinstieg gehören diese Referenzen?" Tags beantworten: „Welche Merkmale, Methoden, Status, Objekte oder Verwendungszwecke hat diese Referenz?"
Zotero stellt die grundlegenden Organisationsmöglichkeiten bereit – Collections und Tags. BibGenies Bibliotheks-Organisationsfunktion fungiert als dein Bibliotheksassistent: Sie versteht zunächst deine bestehende Organisation, schlägt dann einen überprüfbaren Plan vor und führt ihn nach deiner Freigabe aus.
Eine vollständige Einführung in BibGenies Bibliotheksorganisationsfähigkeiten und Beispiel-Prompts findest du in der [Bibliotheksverwaltungs-Dokumentation](https://www.bibgenie.com/de/docs/library-management).
## Kurzübersicht [#kurzübersicht]
Wenn du gerade anfängst, deine Zotero-Bibliothek zu organisieren, folge diesen Regeln:
| Szenario | Empfohlen | Wie BibGenie hilft |
| :---------------------------------------------------------------------------- | :---------------------------- | :--------------------------------------------------------------------------------------------------------------------- |
| Aufsatz, Kurs, Projekt, Abschlussarbeit, Dissertation | Collection | Generiert eine Projekt-Collection-Struktur aus ausgewählten Items und fügt Referenzen zur passenden Collection hinzu |
| Forschungsthema, Methode, Datentyp, Region, theoretischer Rahmen | Tag | Liest Titel, Abstracts und Metadaten und schlägt konsistente topic/method/status-Tags vor |
| `to-read`, `read`, `important`, `reviewed` | Colored Tag oder normaler Tag | Fügt Status-Tags für deinen aktuellen Leseworkflow in Batches hinzu oder entfernt sie |
| Kürzlich hinzugefügt (7 Tage), ungelesen, fehlende DOI, Tag-Kombinationen | Saved Search | Hilft bei der Gestaltung von Suchkriterien und nachfolgenden Organisationsregeln |
| Buchbesprechung und besprochenes Buch, verschiedene Versionen desselben Werks | Related Items | Identifiziert möglicherweise verwandte Einträge, das Herstellen von Beziehungen sollte jedoch manuell bestätigt werden |
| Zu viele verschachtelte Untercollections | Vermeiden | Erkennt zu tiefe, zu fragmentierte oder doppelte Collections und schlägt Zusammenführungen vor |
## Was BibGenies Bibliotheks-Organisationsfunktion kann [#was-bibgenies-bibliotheks-organisationsfunktion-kann]
Beim manuellen Organisieren von Zotero-Collections und Tags ist nicht das Klicken der zeitaufwendige Teil – sondern die Entscheidungen: Welche Tags sind Duplikate? In welche Collection gehören welche Items? Welche Metadaten fehlen? Welche Operationen betreffen zu viele Einträge? Hier liegt der Wert von BibGenies Bibliotheks-Organisationsfunktion.
| Aufgabe | Was BibGenie tun kann |
| :---------------------------------------- | :----------------------------------------------------------------------------------------------------------------------------------- |
| Bestandsaufnahme der vorhandenen Struktur | Collection-Hierarchie, Tag-Vokabular, Items unter einer bestimmten Collection oder einem Tag auflisten |
| Zu organisierende Items finden | Unfiled Items, kürzlich hinzugefügte Referenzen, Einträge ohne DOI/Abstract, Items nach Tag oder Collection suchen |
| Organisationsschema entwerfen | Klassifikationssystem basierend auf Titeln, Abstracts, Metadaten, vorhandenen Tags und Collections vorschlagen |
| Items in Batches organisieren | Tags hinzufügen/entfernen, zu Collections hinzufügen oder daraus entfernen |
| Collections erstellen | Neue Collections unter dem richtigen Elternknoten erstellen, optional mit Kandidaten-Items |
| Tags bereinigen | Tags umbenennen, alte Tags in bestehende zusammenführen, bibliotheksweit ungenutzte Tags löschen |
| Collections organisieren | Collections umbenennen, verschieben, leere oder unnötige löschen (Löschen einer Collection löscht nicht die darin enthaltenen Items) |
| Metadaten prüfen | Vollständige Metadaten lesen, fehlende Felder identifizieren und bei zuverlässigen Quellen bei der Korrektur helfen |
Das Ändern von Metadaten, Erstellen von Collections, Verschieben von Items, batchweises Bearbeiten von Tags sowie Umbenennen oder Löschen von Collections/Tags sind Schreiboperationen. BibGenie schlägt Aktionen vor und wartet auf deine Freigabe. Es sollte deine Zotero-Bibliothek niemals ohne explizite Bestätigung verändern.
Eine gute BibGenie-Organisationsanfrage sollte Umfang, Ziel und Einschränkungen enthalten:
```text
Please organize the currently selected items. First read the existing collections and tags, then propose an organization plan based on titles, abstracts, and metadata.
Prefer reusing existing collections and tags; only suggest creating new ones if there is genuinely no suitable place.
Do not modify Zotero yet. First output which items will be affected, which tags will be added, and which collections will be used.
```
Das Prinzip hinter diesem Prompt ist der Kern-Workflow von BibGenies Bibliotheks-Organisationsfunktion: Erfasse den aktuellen Zustand, identifiziere zu organisierende Items, schlage einen Plan vor und führe schließlich aus.
## Was sind Collections [#was-sind-collections]
Collections sind die Ordner und Unterordner in Zoteros linker Seitenleiste. Die offizielle Zotero-Dokumentation empfiehlt, Collections als „Wiedergabelisten" zu betrachten – nicht als Dateisystemordner: Dasselbe Item kann in mehreren Collections erscheinen, ohne die Referenz zu duplizieren. Die vollständige Bibliothek bleibt `My Library` oder die entsprechende Gruppenbibliothek.
Collections eignen sich am besten als Einstiegspunkte. Zum Beispiel:
* `PhD Thesis`
* `2026 Systematic Review`
* `Course - Research Methods`
* `Project - AI Literature Review`
* `Topic - Retrieval-Augmented Generation`
Der Vorteil ist Klarheit, Sichtbarkeit und Projektbereitschaft. Öffne eine Collection und du siehst sofort die Kernreferenzen für diese Arbeit.
Wenn du BibGenie verwendest, bitte es, zuerst einen Collection-Entwurf zu erstellen, bevor Items verschoben werden:
```text
Please list my existing collections first, then decide whether the selected items can fit into existing collections.
If the existing structure isn't sufficient, design a one-to-two-level collection draft for my "literature review writing project."
Output each collection's purpose and the proposed items it would contain. Do not modify Zotero.
```
Das Löschen einer normalen Collection entfernt nur diesen Organisationseinstieg, nicht die darin enthaltenen Items. Um Items wirklich zu löschen, musst du sie in den Papierkorb verschieben. Dieser Unterschied ist für neue Benutzer wichtig.
Aus diesem Grund warnt BibGenie explizit beim Löschen einer Collection: Das Löschen einer Collection entfernt nur den Organisationseinstieg; Items bleiben in der Zotero-Bibliothek erhalten. Wenn eine Collection Untercollections hat, weigert sich BibGenie, die Eltern-Collection direkt zu löschen, und bittet dich, zuerst über die Untercollections zu entscheiden.
## Was sind Tags [#was-sind-tags]
Tags sind Textlabels, die an Items, Anhänge und Notizen angehängt werden. Sie haben keine Hierarchie, können aber dasselbe Paper aus mehreren Perspektiven beschreiben. Die offizielle Zotero-Dokumentation betont, dass Tags für Thema, Methode, Status, Bewertung oder persönliche Workflows verwendet werden können.
Tags eignen sich am besten als Dimensionen. Zum Beispiel:
* Thema: `llm-agent`, `scientific-discovery`, `citation-network`
* Methode: `survey`, `experiment`, `meta-analysis`, `case-study`
* Objekt: `clinical-trial`, `graduate-students`, `zotero-users`
* Status: `to-read`, `read`, `skimmed`, `cited`
* Einsatzzweck: `intro-section`, `related-work`, `method-baseline`
Die Stärke von Tags liegt in der kombinatorischen Suche. Du kannst innerhalb einer Collection nach Items filtern, die sowohl mit `llm-agent` als auch mit `survey` getaggt sind, oder in deiner gesamten Bibliothek nach allen mit `to-read` und `citation-network` getaggten Items suchen.
BibGenies Stärke liegt im batchweisen Vorschlagen von Tags basierend auf Item-Inhalten. Bitte es zunächst um eine reine Analyse:
```text
Please list my existing tags first, then review the titles, abstracts, and existing tags of items in this collection.
Prefer reusing existing tags; only suggest new tags when no suitable one exists.
Finally, present recommended tags to keep, merge, add, and delete in a table. Do not modify Zotero.
```
## Collections vs Tags [#collections-vs-tags]
| Dimension | Collections | Tags |
| :-------------------------------------------------- | :----------------------------------------- | :-------------------------------------------------- |
| Organisation | Hierarchisch mit Untercollections | Flach, keine nativen Untertags |
| Am besten geeignet für | Projekte, Kurse, Arbeiten, Themeneinstiege | Thema, Methode, Status, Qualität, Verwendungszweck |
| Kann ein Item in mehreren vorkommen? | Ja | Ja |
| Bleibt beim Kopieren zwischen Bibliotheken erhalten | Meistens nicht | Meistens mit dem Item |
| Zum Durchstöbern | Stark | Mittel |
| Zur Kreuzfilterung | Mittel | Stark |
| Wartungsrisiko | Collection-Aufblähung | Tag-Synonyme und Rechtschreibabweichungen |
| Empfohlene Granularität | Wenige, stabil | Feiner möglich, aber Benennung muss konsistent sein |
Wenn du bereits eine `Topic - LLM Agents`-Collection hast, musst du nicht jedes Item darin mit `llm-agents` taggen – es sei denn, du möchtest themenübergreifend danach suchen.
Wenn du BibGenie zum Organisieren verwendest, füge dieses Prinzip in deinen Prompt ein:
```text
Please avoid making tags and collections fully redundant. Don't mechanically add the same tag to every item when the collection already expresses the project membership. Only add topic tags when cross-collection search is needed.
```
## Empfohlenes Organisationsmodell [#empfohlenes-organisationsmodell]
Für die meisten Forscher hat eine solide Zotero-Struktur drei Ebenen.
### 1. Wenige Top-Level-Collections für große Richtungen [#1-wenige-top-level-collections-für-große-richtungen]
Erstelle nicht zu viele Collections auf oberster Ebene. Gestalte sie als Einstiegspunkte, die du nicht häufig umbenennen wirst:
```text
My Library
Inbox
Thesis
Papers
Projects
Topics
Teaching
Archive
```
Oder näher an deinem Forschungsbereich:
```text
My Library
Domain - AI for Science
Domain - Bibliometrics
Domain - Human-Computer Interaction
Project - BibGenie SEO
Project - Zotero Workflow Study
```
### 2. Ein bis zwei Ebenen Untercollections für Projekte [#2-ein-bis-zwei-ebenen-untercollections-für-projekte]
Bohre nicht unbegrenzt in die Tiefe. Zwei Ebenen sind normalerweise ausreichend:
```text
Project - Systematic Review
01 Search Results
02 Screening
03 Included Studies
04 Background Reading
05 Cited in Manuscript
```
Diese Struktur bildet den Forschungsworkflow ab und ist daher für das eigentliche Schreiben praktischer als ein Dutzend thematischer Unterteilungen.
### 3. Tags als kombinierbare querschnittliche Dimensionen [#3-tags-als-kombinierbare-querschnittliche-dimensionen]
Tags sollten nicht alle Collections ersetzen. Sie eignen sich besser, um festzuhalten: „Was ist sonst noch an diesem Paper durchsuchbar?":
```text
method:survey
method:experiment
topic:semantic-search
topic:zotero
status:to-read
status:read
use:background
use:key-citation
```
Zotero hat keine nativen hierarchischen Tags, aber du kannst Namensräume mit Präfixen wie `method:`, `topic:`, `status:` simulieren. Das reduziert Mehrdeutigkeiten und erleichtert das Scannen im Tag-Selector.
## Tag-Benennungskonventionen [#tag-benennungskonventionen]
Ein gutes Tag-System zeichnet sich nicht durch mehr Tags aus, sondern durch Konsistenz.
| Regel | Empfohlen | Nicht empfohlen |
| :--------------------------------------- | :------------------ | :------------------------------------- |
| Kleinbuchstaben verwenden | `semantic-search` | `Semantic Search`, `semantic Search` |
| Bindestriche für zusammengesetzte Wörter | `citation-network` | `citation network`, `citation_network` |
| Kategorien mit Präfix versehen | `method:survey` | Gemischt `survey`, `surveys` |
| Status-Tags einheitlich halten | `status:to-read` | Gemischt `unread`, `to read`, `todo` |
| Zu breite Tags vermeiden | `topic:llm-agent` | `ai`, `paper`, `research` |
| Zu temporäre Tags vermeiden | `use:intro-section` | `maybe-use-in-chapter-2-later` |
Wenn bereits doppelte Tags vorhanden sind, benenne den alten Tag im Tag-Selector in den Zielnamen um, um sie zusammenzuführen. Zum Beispiel `to read` in `status:to-read` umbenennen.
Wenn Tags bereits chaotisch sind, bitte BibGenie zuerst um ein Tag-Audit:
```text
Please list the current library's tags and identify potentially duplicate or synonymous tags — for example, different casing, spaces vs hyphens, singular vs plural.
Give merge suggestions and note how many items each tag affects.
Do not execute any renaming or deletion yet.
```
Dann bestätigen vor der Ausführung:
```text
I confirm the merge plan. Please rename the tag `to read` to `status:to-read`.
If `status:to-read` already exists, merge the two tags. Before executing, confirm how many items will be affected.
```
BibGenies Tag-Umbenennung und -Zusammenführung durchläuft nicht Items einzeln, sondern nutzt Zoteros bibliotheksweite Tag-Operationen. Wenn du einen alten Tag in einen bestehenden Tag-Namen umbenennst, führt Zotero sie zusammen. Das ist zuverlässiger und besser geeignet für die Bereinigung lang angesammelter Synonym-Tags als das manuelle Hinzufügen neuer und Entfernen alter Tags Item für Item.
## Wie man Colored Tags verwendet [#wie-man-colored-tags-verwendet]
Zotero unterstützt das Zuweisen von Farben zu einer kleinen Anzahl von Tags, die mit Zifferntasten schnell hinzugefügt oder entfernt werden können. Die aktuelle offizielle Dokumentation gibt ein Maximum von 9 Colored Tags an.
Colored Tags eignen sich am besten für „häufige Status", nicht für alle Themen:
| Colored Tag | Verwendung |
| :----------------- | :------------------------ |
| `status:to-read` | Ungelesen |
| `status:reading` | Wird gelesen |
| `status:read` | Gelesen |
| `use:key-citation` | Wichtige Referenz |
| `use:write-next` | Für anstehendes Schreiben |
Vermeide es, gewöhnlichen Themen-Tags wie `machine-learning`, `history` oder `statistics` Colored-Status zuzuweisen. Themen vermehren sich mit der Zeit, aber die Colored-Tag-Plätze sind begrenzt.
BibGenie kann nicht entscheiden, welche Tags dauerhaft deine Colored-Tag-Plätze belegen sollten, aber es kann helfen, deine am häufigsten verwendeten statusähnlichen Tags zu identifizieren und Vorschläge zu machen, ob sie zu weniger hochfrequenten Tags konsolidiert werden sollten.
## Sollte man automatische Tags behalten [#sollte-man-automatische-tags-behalten]
Wenn Zotero Items aus Datenbanken, Webseiten oder Bibliothekskatalogen speichert, importiert es manchmal automatisch Subject Headings oder Keywords. Diese automatischen Tags können nützlich sein, aber sie erzeugen oft Rauschen: inkonsistente Groß-/Kleinschreibung, ungleichmäßige Granularität, zu breite Begriffe und Tag-Aufblähung.
Empfohlene Strategien:
1. Neue Bibliotheken oder Nutzer mit starkem Ordnungsanspruch: Automatische Tags deaktivieren, Kern-Tags manuell pflegen.
2. Medizinische, juristische oder bibliothekswissenschaftliche Nutzer mit kontrollierten Vokabularen: Automatische Tags zunächst behalten, dann regelmäßig bereinigen.
3. Nutzer mit vielen angesammelten automatischen Tags: Automatische Tags zunächst ausblenden, dann nach Bestätigung der Nutzlosigkeit batchweise löschen.
Zum Deaktivieren: Gehe zu Zotero-Einstellungen > Allgemein und deaktiviere `Items automatisch mit Schlagwörtern und Subject Headings versehen`.
Wenn du unsicher bist, welche automatischen Tags wertvoll sind, bitte BibGenie, sie nach Häufigkeit und Semantik zu gruppieren:
```text
Please check the current library's tags and list those that may be from automatic import, overly broad, or inconsistently cased. Do not delete anything, just give cleanup suggestions.
```
## Saved Searches – ein unterschätztes Organisationstool [#saved-searches--ein-unterschätztes-organisationstool]
Saved Searches sind wie „intelligente Collections". Sie speichern Suchkriterien, keine festen Ergebnisse, und aktualisieren sich automatisch, wenn sich deine Bibliothek ändert.
Gute Anwendungsfälle für Saved Searches:
* `Unread`: Tag ist nicht `status:read`
* `Recent Additions`: In den letzten 7 Tagen hinzugefügte Items
* `Missing DOI`: Items, bei denen die DOI leer ist
* `Need Review`: Items mit Tag `status:to-read` in einer bestimmten Collection
* `Key RAG Papers`: Items mit sowohl `topic:rag` als auch `use:key-citation`
Wenn du feststellst, dass du wiederholt dieselben Filterkriterien verwendest, solltest du eine Saved Search erstellen, anstatt eine neue statische Collection anzulegen.
BibGenie eignet sich besser dafür, dir beim Entwerfen von Saved-Search-Regeln zu helfen, als jede dynamische Aufgabe in eine Collection zu verwandeln. Zum Beispiel:
```text
I want to create a dynamic view of "unread RAG papers."
Please review my existing tags and collections first, then suggest Zotero saved search criteria.
If existing tags aren't suitable, explain which tags need to be standardized first.
```
BibGenie kann auch einen ähnlichen Saved-Search-Ansatz verwenden, um zu organisierende Items zu finden, wie „Items, die in den letzten 30 Tagen hinzugefügt wurden und noch in keiner Collection sind", „Journal-Artikel ohne DOI" oder „Items mit alten Tags aber ohne neue Tags". Diese Aufgaben eignen sich am besten, indem zuerst eine Kandidatenliste ausgegeben wird, bevor über Batch-Änderungen entschieden wird.
## Wie man Related Items verwendet [#wie-man-related-items-verwendet]
Related Items sollten Tags oder Collections nicht ersetzen. Wie in Zotero-Foren diskutiert, ist das Problem bei Related, dass es nur ausdrückt „zwei Items sind verwandt", ohne zu klären „warum sie verwandt sind". Daher eignet es sich am besten für explizite Eins-zu-eins- oder kleinere Beziehungen:
* Eine Buchbesprechung und das besprochene Buch
* Ein Konferenzbeitrag und seine erweiterte Journal-Version
* Ein Datensatz-Paper und das Benchmark-Paper, das ihn verwendet
* Ein Preprint, die veröffentlichte Version und eine Korrektur derselben Studie
* Kernquellen, die in einem Übersichtsartikel wiederholt diskutiert werden
Wenn du einfach ausdrücken möchtest „diese Items gehören alle zum selben Thema", verwende Tags oder Collections.
## Drei häufige Workflows [#drei-häufige-workflows]
### Workflow A: Ein Paper oder Review schreiben [#workflow-a-ein-paper-oder-review-schreiben]
Erstelle eine Collection für dein Schreibprojekt, z. B. `Project - LLM Agent Review`.
Lege Kandidaten-Paper zunächst in `01 Search Results` oder `Inbox` ab.
Verwende Tags, um Themen, Methoden und Status zu markieren, z. B. `topic:tool-use`, `method:benchmark`, `status:to-read`.
Verschiebe oder füge Kern-Paper nach der Sichtung zu `03 Included Studies` hinzu.
Verwende `use:key-citation`, `use:intro-section`, `use:method-section`, um Schreibzwecke zu markieren.
Passender BibGenie-Prompt:
```text
Please examine the `Project - LLM Agent Review` collection.
First list the existing subcollections and tags, then classify the papers into five categories following a review writing workflow: search results, screening, included, background, and cited.
Prefer using existing subcollections; justify any new ones needed.
First output a table, do not move any items yet.
```
Nach Bestätigung:
```text
I confirm this classification table. Please add these items to the corresponding collections per the table, and add the `use:key-citation` tag to core papers.
After completion, summarize how many items were modified, which collections were used, and which tags were added.
```
### Workflow B: Ein langfristiges Forschungsfeld aufbauen [#workflow-b-ein-langfristiges-forschungsfeld-aufbauen]
Erstelle eine langfristige Collection, z. B. `Domain - AI for Science`.
Erstelle nur bei tatsächlichem Bedarf wenige Untercollections, z. B. `Foundation Papers`, `Benchmarks`, `Applications`.
Verwende feingranulare Tags für Themen, Methoden, Datensätze und Versuchsobjekte.
Überprüfe regelmäßig `Unfiled Items` und füge verwaiste Items zu passenden Collections hinzu oder lösche sie.
Passender BibGenie-Prompt:
```text
Please analyze the items in `Domain - AI for Science`.
First read the existing tags, identify 5 to 8 stable research topics, and suggest corresponding `topic:` tags.
Avoid creating too many subcollections; prefer tags unless a topic will be maintained separately long-term.
```
### Workflow C: Leichtgewichtige Nutzer [#workflow-c-leichtgewichtige-nutzer]
Wenn du kein komplexes System pflegen möchtest, folge diesen Minimalregeln:
* Collections: Nach Projekt oder Kurs anlegen.
* Tags: Nur 5 bis 15 hochfrequente Status oder Themen verwenden.
* Colored Tags: Nur `to-read`, `read`, `important` markieren.
* Monatliche Bereinigung: Automatische Tags, Duplikate und Unfiled Items.
Ein leichtgewichtiges System, das gepflegt wird, ist zuverlässiger als ein komplexes, das vernachlässigt wird.
Leichtgewichtige Nutzer können BibGenie weiterhin nutzen, aber der Fokus sollte auf der Reduzierung des Wartungsaufwands liegen, nicht auf der Generierung weiterer Tags:
```text
Please classify the currently selected items into only three statuses: `status:to-read`, `status:reading`, `status:read`. If you can't determine the status, put it in `status:to-read` and show a preview first.
```
## Monatliche Wartungscheckliste [#monatliche-wartungscheckliste]
Führe monatlich Zotero-Bibliothekspflege durch:
* Öffne `Unfiled Items` und bearbeite Items, die in keiner Collection sind.
* Öffne `Duplicate Items` und führe Duplikate zusammen, anstatt eines zu löschen.
* Überprüfe den Tag-Selector auf synonyme Tags, z. B. `methods` und `research-methods`.
* Blende nutzlose automatische Tags aus oder lösche sie.
* Überprüfe kürzlich hinzugefügte Items auf sauberen Titel, Autor, Jahr, DOI und Abstract.
* Lösche temporäre Untercollections, die ihren Zweck verloren haben, um Collection-Aufblähung zu vermeiden.
Bitte BibGenie, Kandidaten-Items und geplante Änderungen aufzulisten, bevor batchweise Tags hinzugefügt, Collections erstellt, Items verschoben oder Metadaten geprüft werden. Bei Batch-Operationen immer eine Vorschau anzeigen lassen und den Umfang eingrenzen, z. B. „nur die aktuell ausgewählten Items" oder „nur diese Collection".
Ein solider monatlicher BibGenie-Organisations-Prompt:
```text
Please help me with Zotero library housekeeping:
1. First list existing collections and tags.
2. Check for unfiled items, duplicate or synonymous tags, overly deep collections, and recently added unorganized items.
3. When checking items missing DOI or abstract, consider the item type to determine whether a DOI is actually expected.
4. Only output the problem list, impact scope, and suggested actions. Do not modify Zotero.
```
Wenn du Unfiled Items an geeignete Orte verschieben möchtest, bitte BibGenie um eine spezifischere Aufgabe:
```text
Please find the most recent 50 unfiled items and determine which collections they best fit into based on existing collections.
Do not create new collections unless the existing structure clearly has no suitable place.
First output each item, the suggested collection, the reason, and your confidence level.
```
## Häufige Fehler [#häufige-fehler]
### Fehler 1: Collections als einziges Organisationssystem [#fehler-1-collections-als-einziges-organisationssystem]
Wenn du für jedes kleine Thema eine Untercollection erstellst, hast du nach einigen Jahren Dutzende oder Hunderte von Collections. Items werden in tiefen Bäumen vergraben und sind schwerer zu finden.
Wenn du BibGenie verwendest, bitte es nicht, für jedes kleine Thema Collections zu erstellen. Eine bessere Anweisung: „Erstelle Collections nur für langfristige Projekte, Kurse, Arbeiten oder stabile Themen; verwende Tags für feingranulare Konzepte."
### Fehler 2: Tags ohne Benennungsregeln [#fehler-2-tags-ohne-benennungsregeln]
Wenn `to read`, `ToRead`, `unread` und `todo` nebeneinander existieren, funktioniert die Suche nicht mehr. Ein Tag-System fürchtet nichts mehr als Synonym-Drift.
BibGenie kann diese Abweichungen erkennen und alte Tags zu einheitlichen umbenennen. Das Umbenennen in einen bereits vorhandenen Tag führt effektiv zu einer Zusammenführung.
### Fehler 3: Related für Themenzugehörigkeit verwenden [#fehler-3-related-für-themenzugehörigkeit-verwenden]
Related eignet sich besser für explizite Beziehungen, nicht um eine Reihe thematisch ähnlicher Items zu verknüpfen. Themenzugehörigkeit sollte über Tags oder Collections ausgedrückt werden.
### Fehler 4: Die Anzeigeeinstellungen für Untercollections vergessen [#fehler-4-die-anzeigeeinstellungen-für-untercollections-vergessen]
In Zotero werden Items in Untercollections standardmäßig nicht unbedingt in der übergeordneten Collection angezeigt. Ändere dies über `View -> Show Items from Subcollections`. Diese Einstellung beeinflusst, wie du Eltern-Kind-Collection-Beziehungen verstehst, daher ist es in Team-Workflows am besten, sie zu standardisieren.
### Fehler 5: Automatische Tags zu lange ignorieren [#fehler-5-automatische-tags-zu-lange-ignorieren]
Automatisch importierte Tags überladen den Tag-Selector. Sofern du nicht explizit auf diese Keywords angewiesen bist, blende sie regelmäßig aus, lösche sie oder deaktiviere automatische Tags.
### Fehler 6: „Organisiere meine ganze Bibliothek" als vagen Befehl behandeln [#fehler-6-organisiere-meine-ganze-bibliothek-als-vagen-befehl-behandeln]
„Bitte organisiere meine gesamte Bibliothek" klingt praktisch, ist aber meist zu vage. BibGenies Bibliotheks-Organisationsfunktion eignet sich besser für spezifische Probleme, wie:
* Kürzlich hinzugefügte, aber noch nicht organisierte Items.
* Items in einer Collection, die weiter unterteilt werden müssen.
* Doppelte oder synonyme Tags.
* Einträge ohne DOI, Abstract oder Publikationstitel.
* Kern-Paper, die für ein anstehendes Schreibprojekt mit `use:key-citation` markiert werden sollen.
Ein besserer Prompt:
```text
Please don't organize the entire library yet. Help me diagnose the 3 most pressing categories of issues: unfiled items, duplicate tags, and missing metadata. Only output the problem scope and suggested next steps.
```
### Fehler 7: KI nicht verifizierbare Metadaten ausfüllen lassen [#fehler-7-ki-nicht-verifizierbare-metadaten-ausfüllen-lassen]
BibGenie kann Metadaten prüfen und bei zuverlässigen Quellen bei der Korrektur helfen, aber du solltest KI niemals bitten, eigene DOI, Abstracts, Journalnamen, Autoren oder Seitenzahlen zu schreiben. Bei Metadaten-Schreibvorgängen sollten zuverlässige Quellen aus Zoteros vorhandenen Metadaten, benutzerbereitgestellten Informationen, bereits gelesenem Item-Inhalt oder BibGenies verifizierbaren externen Referenzabfragen stammen.
Ein guter Prompt:
```text
Please check the metadata completeness of the most recent 20 items. For entries missing a DOI or abstract, only suggest corrections when verifiable through reliable sources. Mark unverifiable items as "unconfirmed" and do not generate or guess content.
```
## Empfohlene Vorlage [#empfohlene-vorlage]
Du kannst direkt mit dieser Vorlage beginnen:
```text
Collections
Inbox
Project - [Project Name]
01 Search Results
02 To Screen
03 Included
04 Background
05 Cited
Domain - [Long-term Topic]
Foundation Papers
Methods
Applications
Archive
Tags
status:to-read
status:reading
status:read
use:key-citation
use:intro-section
use:method-section
method:survey
method:experiment
method:case-study
topic:[Topic Name]
```
## Sicherheits-Workflow bei der Verwendung von BibGenie [#sicherheits-workflow-bei-der-verwendung-von-bibgenie]
BibGenie kann Tags, Collections, Item-Zugehörigkeit und einige Metadaten verwalten, aber Bibliotheksorganisation verändert Zotero-Daten. Befolge immer diesen Vier-Schritte-Prozess:
Bitte BibGenie, die vorhandene Struktur zu lesen: Collections, Tags und den Umfang der zu organisierenden Items.
Fordere BibGenie auf, vorhandene Collections und Tags bevorzugt wiederzuverwenden; neue nur anlegen, wenn es wirklich keine passende gibt.
Bitte BibGenie, den Organisationsplan auszugeben, einschließlich hinzuzufügender und zu entfernender Tags, Ziel-Collections, betroffener Items und genehmigungspflichtiger Operationen.
Autorisiere BibGenie nach manueller Bestätigung explizit zur Ausführung. Bitte nach der Ausführung um eine Zusammenfassung der Änderungen, übersprungenen Items und unerledigten Aufgaben.
Empfohlene Prompt-Vorlage:
```text
Please organize the currently selected items. The goal is to establish clear Zotero collections and tags:
1. First list existing collections and tags.
2. Prefer reusing existing collections and tags; don't create similar names unnecessarily.
3. Determine which items should go into the same collection.
4. Then suggest consistent `topic:`, `method:`, `status:` tags.
5. Output which tags and collections will be added or removed for each item.
6. Do not modify Zotero yet; wait for my confirmation.
```
Nach Bestätigung:
```text
I confirm the organization plan above. Please execute these changes, then summarize how many items were modified, which tags were added, and which collections were used.
```
Bei Batch-Operationen mit 50+ Items, formuliere spezifischer:
```text
This is a large batch organization task. First give a brief plan including which existing collections/tags will be used, whether new ones are needed, how many items will be affected, and which write operations need my approval.
After I confirm, execute in focused batches by shared purpose. Do not run one operation per item.
```
Wenn du nur ein bibliotheksweites Tag umbenennen, zusammenführen oder löschen möchtest, lass BibGenie nicht Items einzeln bearbeiten. Beschreibe die Tag-Operation direkt:
```text
Please merge the library-wide tag `methodology` into the existing tag `method:methods`.
First confirm that both tags exist and how many items are affected, then wait for my approval.
```
Wenn du nur eine Collection umbenennen oder verschieben möchtest, lass BibGenie die Collection selbst bearbeiten, anstatt eine neue Collection zu erstellen und alle Items zu verschieben:
```text
Please rename the collection `Old Thesis Reading` to `Project - Dissertation Reading`.
First list the matching collection key and its item count, wait for my confirmation, then execute.
```
## Referenzen [#referenzen]
* [Zotero Offizielle Dokumentation: Collections and Tags](https://www.zotero.org/support/collections_and_tags)
* [Zotero Offizielles KB: Organizing a library](https://www.zotero.org/support/kb/organizing_a_library)
* [Zotero Forums: tags and collections best practice?](https://forums.zotero.org/discussion/115437/tags-and-collections-best-practice)
* [Zotero Forums: Collections vs tags](https://forums.zotero.org/discussion/116758/collections-vs-tags)
* [Zotero Forums: best use for related, tags, collections](https://forums.zotero.org/discussion/129569/best-use-for-related-tags-collections)
* [Mastering Zotero: Working with Tags](https://pressbooks.library.yorku.ca/masteringzotero/chapter/working-with-tags/)
* [Zotero Manual: Tags](https://zotero-manual.github.io/tags/)
* [Harvard Library: Organize Your Zotero Library](https://guides.library.harvard.edu/c.php?g=1245347\&p=9129454)
* [UMGC Library: Collections & Tags](https://libguides.umgc.edu/c.php?g=930616\&p=6753118)
* [Massachusetts General Hospital: Organizing Your Library](https://libguides.massgeneral.org/zotero/organizing-library)
* [Catherine Pope: Keeping Your Zotero Library Tidy](https://catherinepope.com/posts/keeping-your-zotero-library-tidy/)
* [Reddit: Collections and Tags](https://www.reddit.com/r/zotero/comments/1izhq0m/collections_and_tags/)
# Zotero WebDAV (/de/docs/zotero-webdav)
Zotero-Synchronisierung hält deine Bibliothek auf mehreren Geräten verfügbar. In Zotero besteht Sync aus zwei getrennten Teilen: **Datensynchronisierung** und **Dateisynchronisierung**. WebDAV wird für die Dateisynchronisierung verwendet, also für PDFs, Bilder, Snapshots und andere Anhänge.
WebDAV beeinflusst BibGenies offizielle Modelle, Credits oder Chat-Funktionen nicht direkt. Wenn du Zotero jedoch auf mehreren Geräten verwendest, kann WebDAV dabei helfen, Anhänge lokal verfügbar zu machen. Das beeinflusst, ob BibGenie PDFs oder Snapshots auf einem bestimmten Gerät lesen kann.
## Datensynchronisierung vs. Dateisynchronisierung [#datensynchronisierung-vs-dateisynchronisierung]
| Typ | Was synchronisiert wird | Hinweise |
| :-------------------- | :----------------------------------------------------------------------------------- | :--------------------------------------------------------------------------------------- |
| Datensynchronisierung | Einträge, Titel, Autoren, Publikationsjahre, Notizen, Tags, Sammlungen und Metadaten | Zotero stellt unbegrenzte Datensynchronisierung kostenlos bereit |
| Dateisynchronisierung | PDFs, Bilder, Snapshots, Audio und andere Anhangsdateien | Zotero bietet kostenlos 300 MB Dateispeicher; WebDAV kann als Alternative genutzt werden |
Um Zotero-Sync zu verwenden, musst du dich normalerweise bei einem Zotero-Konto anmelden und die Datensynchronisierung aktivieren. WebDAV verwaltet nur Anhangsdateien; es ersetzt nicht die Zotero-Konto-Datensynchronisierung.
Richte zuerst die Zotero-Datensynchronisierung ein, indem du dich in den Zotero-Einstellungen bei deinem Zotero-Konto anmeldest. WebDAV ersetzt nur den Dateispeicherteil.
## Was ist WebDAV? [#was-ist-webdav]
WebDAV ist ein Protokoll, mit dem Anwendungen Dateien auf einem entfernten Server verwalten können. Zotero kann WebDAV als Alternative zu Zotero-eigenem Dateispeicher verwenden, sodass Anhänge über unterstützte Drittanbieter-Speicherdienste synchronisiert werden.
Das ist nützlich, wenn PDFs und Anhänge auf mehreren Geräten verfügbar sein sollen, ohne Zotero's offiziellen Dateispeicherplan zu kaufen.
## Häufige WebDAV-Anbieter [#häufige-webdav-anbieter]
| Anbieter | Kostenloser Speicher / Limits | Website | Hinweise |
| :--------- | :----------------------------------------------------------------------------- | :--------------------------------------------------------- | :------------------------------------- |
| Koofr | 2 GB initial; bis zu 10 GB nach Abschluss von Kontoaufgaben | [https://koofr.eu/](https://koofr.eu/) | Einfache Einrichtung; Server in Europa |
| Jianguoyun | 1 GB/Monat Upload-Traffic und 3 GB/Monat Download-Traffic im kostenlosen Tarif | [https://www.jianguoyun.com/](https://www.jianguoyun.com/) | Aus Festlandchina oft schneller |
Weitere Optionen findest du auf Zotero's offizieller Seite [WebDAV Providers](https://www.zotero.org/support/kb/webdav_services).
## Koofr WebDAV konfigurieren [#koofr-webdav-konfigurieren]
Koofr ist ein Cloud-Speicheranbieter aus Europa. Er wird oft empfohlen, weil die Einrichtung einfach ist und Koofr Zotero-spezifische WebDAV-Anleitungen anbietet.
Registriere ein [Koofr-Konto](https://koofr.eu/) und melde dich in der Koofr-Web-App an.
Klicke oben rechts auf deinen Avatar und öffne **Preferences**.
Wähle links **Password** und scrolle zu **App Passwords**.
Gib einen App-Namen wie `Zotero` ein, klicke auf **Generate** und speichere das generierte Passwort. Koofr zeigt dieses Passwort nur einmal an.
Öffne Zotero und gehe zu **Edit -> Preferences -> Sync**. Unter macOS: **Zotero -> Settings -> Sync**.
Aktiviere in **File Syncing** die Anhangssynchronisierung und wähle **WebDAV**.
Gib ein:
* **URL**: `https://app.koofr.net/dav/Koofr`
* **Username**: deine Koofr-Konto-E-Mail
* **Password**: das generierte Koofr-App-Passwort
Klicke auf **Verify Server**. Nach erfolgreicher Prüfung klicke auf **OK**, um die Einstellungen zu speichern.
Klicke in Zotero auf den Sync-Button, um die Anhangsdateien zu synchronisieren.
Der Abschnitt `Koofr` in der URL muss mit einem großen K beginnen.
## Jianguoyun WebDAV konfigurieren [#jianguoyun-webdav-konfigurieren]
Melde dich im Browser bei [Jianguoyun](https://www.jianguoyun.com/) an.
Klicke oben rechts auf deinen Kontonamen und öffne **Account Info**.
Öffne **Security Options**.
Klicke in **Third-party App Management** auf **Add Application**.
Gib einen Namen wie `Zotero` ein, generiere ein Passwort und speichere es. Das ist ein app-spezifisches Passwort, nicht dein Jianguoyun-Login-Passwort.
Öffne Zotero und gehe zu **Edit -> Preferences -> Sync**. Unter macOS: **Zotero -> Settings -> Sync**.
Aktiviere in **File Syncing** **Sync attachment files in My Library** und wähle **WebDAV**.
Gib ein:
* **URL**: `https://dav.jianguoyun.com/dav/`
* **Username**: dein Jianguoyun-Konto, meist deine E-Mail
* **Password**: das in Jianguoyun generierte app-spezifische Passwort
Klicke auf **Verify Server**. Wenn Zotero fragt, ob ein `zotero`-Ordner auf dem WebDAV-Server erstellt werden soll, bestätige dies.
Die übliche Jianguoyun-WebDAV-Serveradresse ist `https://dav.jianguoyun.com/dav/`.
Wenn du Zotero auf mehreren Computern nutzt, konfiguriere auf jedem Gerät dieselben WebDAV-Einstellungen und stelle sicher, dass Zotero-Datensync dasselbe Konto verwendet.
# Ajouter du contexte (/fr/docs/add-context)
BibGenie ne se contente pas de montrer un nom de fichier à l'IA. Add Context introduit dans la conversation les objets de recherche Zotero, le contenu des documents et votre position de lecture. L'IA sait ainsi quelle source vous étudiez, quelle section vous lisez et quel passage compte pour votre question.
Vous pouvez commencer par un élément Zotero complet, puis affiner le contexte jusqu'à une page PDF, une section EPUB ou un passage sélectionné dans un PDF, un EPUB ou un instantané. Plus le contexte est proche de votre question, plus la réponse est ciblée et facile à vérifier dans la source.
Add Context indique à la fois « de quelle source s'agit-il ? » et « où suis-je en train de lire ? ». Vous pouvez ajouter des éléments, pièces jointes, notes, collections et tags, mais aussi la page PDF actuelle, la section EPUB actuelle ou du texte sélectionné dans le Reader.
## Façons d'ajouter du contexte [#façons-dajouter-du-contexte]
Tapez un espace suivi de `@` dans le champ de saisie pour rechercher et insérer des éléments Zotero, pièces jointes, notes, tags, collections et plus encore.
Cliquez sur le bouton Add Context près du champ de saisie pour ouvrir une boîte de sélection.
Ajoutez du contexte depuis des éléments Zotero, collections, tags, onglets de lecture ou texte sélectionné.
Collez des images dans le champ de saisie ou utilisez les captures côté Zotero pour les figures, formules et zones de page.
## Types de contexte pris en charge [#types-de-contexte-pris-en-charge]
| Type | Idéal pour |
| :--------------------------------------------- | :------------------------------------------------------------------------------ |
| Élément standard | Métadonnées bibliographiques, titre, auteurs, année et pièces jointes associées |
| Pièce jointe PDF | Lecture complète d'article, résumés de sections, méthodes et résultats |
| Pièce jointe EPUB | Lecture d'un livre complet, par page logique ou par section |
| Instantané | Lecture de pages web enregistrées dans Zotero |
| Note | Utiliser notes Zotero, extraits et notes de recherche comme contexte |
| Annotation enregistrée | Utiliser un surlignage, commentaire, couleur, tag et son emplacement source |
| Collection | Travailler avec un ensemble d'articles |
| Tag | Travailler avec les articles d'un tag spécifique |
| Texte sélectionné depuis PDF / EPUB / Snapshot | Explication précise d'un passage |
| Contexte de la page PDF actuelle | Poser des questions sur la page que vous lisez |
| Section EPUB actuelle | Lire l'unité de contenu EPUB en cours et y revenir depuis le message |
| Image / capture d'écran | Analyser figures, formules, diagrammes et zones de page |
## Ajouter du contexte avec `@` [#ajouter-du-contexte-avec-]
Tapez un espace suivi de `@` dans le champ de saisie pour ouvrir le menu de recherche de contexte. Vous pouvez ensuite saisir un titre, auteur, mot-clé, nom de note, nom de tag ou nom de collection pour filtrer les résultats.
Exemples courants :
```text
@attention is all you need
@Smith 2023
@my research note
@systematic-review
@my project collection
```
Après sélection, le résultat apparaît comme bloc de contexte dans le champ de saisie. Vous pouvez ajouter plusieurs blocs de contexte avant de poser une question.
## Ajouter du contexte depuis Zotero [#ajouter-du-contexte-depuis-zotero]
Vous pouvez ajouter directement l'objet Zotero actuel à BibGenie :
* Faites un clic droit sur un ou plusieurs éléments de bibliothèque et choisissez **Add to Chat**.
* Faites un clic droit sur une collection dans l'arborescence des collections.
* Faites un clic droit sur un tag dans le sélecteur de tags.
* Faites un clic droit sur un onglet PDF, snapshot ou note.
* Sélectionnez du texte dans un PDF, EPUB ou snapshot et ajoutez-le au chat.
* Dans le Reader PDF, ajoutez la page actuelle ; dans le Reader EPUB, choisissez **Add Section to Chat** pour ajouter la section actuelle.
Ces points d'entrée peuvent être activés ou désactivés dans [Add to Chat Settings](/docs/add-to-chat-settings).
## Ajouter un contexte précis depuis le Reader [#ajouter-un-contexte-précis-depuis-le-reader]
BibGenie utilise une unité de lecture adaptée à chaque format de document :
| Reader | Contexte précis disponible | Idéal pour |
| :--------- | :------------------------------------ | :----------------------------------------------------------------- |
| PDF | Page actuelle ou texte sélectionné | Vérifier une affirmation liée à une page, une figure ou un passage |
| EPUB | Section actuelle ou texte sélectionné | Lire une unité de chapitre ou expliquer un passage précis |
| Instantané | Texte sélectionné | Analyser un passage d'une page web enregistrée dans Zotero |
Le contexte ajouté apparaît dans votre message. Lorsqu'il contient des données de position valides, cliquez sur son composant pour rouvrir le Reader correspondant et revenir à l'emplacement pertinent.
La table des matières et la structure des fichiers d'un EPUB ne coïncident pas toujours. La section actuelle correspond généralement à une unité XHTML du spine EPUB. Si plusieurs entrées imbriquées de la table des matières partagent le même fichier XHTML, Add Section to Chat ajoute cette unité de contenu complète plutôt qu'une seule sous-section délimitée par une ancre.
## Exemples [#exemples]
Ajoutez un PDF et demandez :
```text
Résumez cet article par question de recherche, méthode, données, principaux résultats et limites.
```
Ajoutez la section actuelle depuis le Reader EPUB, puis demandez :
```text
Résumez l'argument principal de cette section et expliquez son lien avec le thème général du livre.
```
Ajoutez plusieurs articles liés et demandez :
```text
Comparez ces articles selon leurs hypothèses, méthodes et conclusions. Retournez un tableau comparatif.
```
Ajoutez un passage sélectionné et demandez :
```text
Expliquez la logique de ce passage et identifiez les concepts clés.
```
Ajoutez une capture de figure et demandez :
```text
Expliquez les axes, les courbes et la conclusion principale de cette figure.
```
## Conseils [#conseils]
* N'ajoutez que le contexte pertinent pour la question actuelle.
* Pour les tâches complexes, demandez d'abord un résumé, puis approfondissez avec des questions de suivi.
* Pour les comparaisons multi-articles, demandez à BibGenie de lister chaque article avant de synthétiser.
* Les captures sont utiles pour les figures et formules, mais ajoutez le PDF ou l'élément source si vous avez besoin d'un ancrage citationnel.
# Paramètres Add to Chat (/fr/docs/add-to-chat-settings)
BibGenie place **Add to Chat** directement dans la bibliothèque Zotero et le Reader, là où vous travaillez déjà. Vous pouvez transmettre à l'IA une source pertinente ou le passage en cours de lecture sans copier le texte, rechercher la pièce jointe, puis revenir au chat.
Les points d'entrée utiles varient selon vos habitudes de recherche. Conservez les sélections PDF et les sections EPUB si vous les utilisez souvent, ou masquez les actions moins fréquentes pour alléger les menus contextuels de Zotero.
Désactiver un point d'entrée Add to Chat masque généralement cet élément de menu ou raccourci. Cela ne signifie pas nécessairement que BibGenie ne peut pas ajouter ce type de contexte par d'autres méthodes.
## Interrupteurs disponibles [#interrupteurs-disponibles]
| Paramètre | Ce qu'il contrôle |
| :---------------------- | :-------------------------------------------------------------------------------------------------- |
| Library Items | Affiche Add to Chat pour les éléments Zotero pris en charge, y compris les annotations enregistrées |
| Collections | Affiche Add to Chat dans l'arborescence des collections |
| Tags | Affiche Add to Chat dans le sélecteur de tags |
| Reader Tabs | Affiche Add to Chat pour les onglets PDF, snapshot et note ouverts |
| PDF Text Selection | Ajoute le texte PDF sélectionné au chat |
| EPUB Text Selection | Ajoute le texte EPUB sélectionné au chat |
| Snapshot Text Selection | Ajoute le texte snapshot sélectionné au chat |
| Reader Annotations | Ajoute une ou plusieurs annotations enregistrées depuis le menu contextuel du Reader |
| Reader Page Context | Affiche Add Page to Chat dans le Reader PDF et ajoute la page actuelle |
| EPUB Section Context | Affiche Add Section to Chat dans le Reader EPUB et ajoute la section actuelle |
## Ce que ces points d'entrée ajoutent [#ce-que-ces-points-dentrée-ajoutent]
Add to Chat fonctionne à trois niveaux :
Les éléments, collections et tags indiquent à BibGenie les sources ou groupes de sources sur lesquels vous travaillez.
Les onglets du Reader ajoutent un PDF, un instantané ou une note dans son ensemble, ce qui convient aux résumés et aux synthèses.
Les pages PDF, sections EPUB et sélections de texte ciblent la question sur ce que vous êtes en train de lire.
Lorsque le contexte contient des données de position valides, cliquez sur son composant dans votre message pour rouvrir le document et revenir à l'emplacement pertinent.
## Réglages recommandés [#réglages-recommandés]
Si vous débutez avec BibGenie, conservez la configuration par défaut. Préférences courantes :
Gardez Library Items, Reader Tabs et les options Text Selection correspondant aux formats que vous utilisez le plus.
Gardez Collections et Tags activés si vous travaillez souvent par projet, thème ou groupe de littérature.
Désactivez les entrées moins fréquentes si vos menus contextuels Zotero semblent trop chargés.
## Conseils [#conseils]
* Si vous lisez beaucoup de PDF, activez PDF Text Selection et Reader Page Context.
* Si vous lisez des livres numériques, activez EPUB Text Selection et EPUB Section Context.
* Si vous analysez des pages web enregistrées, activez Snapshot Text Selection.
* Si vous rédigez des revues de littérature, activez Collections et Tags.
* Si vous préférez une configuration minimale, gardez Library Items et le menu `@` dans le champ de saisie.
# Citation BibGenie (/fr/docs/bibgenie-citations)
La citation BibGenie relie les **réponses de l'IA**, les **preuves dans les sources** et les **objets de recherche Zotero** au sein d'un même système traçable.
Lorsque BibGenie répond à partir de votre bibliothèque Zotero, de PDF, de notes, d'instantanés, de pages web ou de résultats OpenAlex, il ajoute automatiquement, quand c'est pertinent, des marqueurs de citation comme `[1]` et `[2]`. Vous n'avez pas besoin de l'activer manuellement ni de retenir des prompts particuliers. Lorsque vous voyez un marqueur de citation, cliquez dessus pour revenir à la source et vérifier sur quoi repose la réponse.
BibGenie distingue deux types de liens qui se ressemblent, mais n'ont pas le même rôle :
* Une **citation** renvoie vers la preuve qui soutient une réponse, par exemple un bloc de texte ou une sélection dans un PDF, un EPUB ou un instantané.
* Une **entité cliquable** renvoie vers un objet Zotero mentionné dans la réponse, comme un élément, une pièce jointe, une note, une collection ou un tag. Elle permet de poursuivre le travail sur cet objet, sans prétendre que l'objet lui-même constitue la preuve d'une phrase.
Le but n'est pas de donner aux réponses une apparence plus académique. Le but est de vous aider à juger :
* D'où vient cette conclusion ?
* L'IA a-t-elle mal lu ou trop généralisé la source ?
* Cette information peut-elle être utilisée sans risque dans des notes, une revue de littérature ou un brouillon de recherche ?
* Si vous voulez poursuivre, quelle source devriez-vous relire ?
Les citations vous ramènent aux preuves ; les entités cliquables vous ramènent dans Zotero pour poursuivre votre travail. Une même réponse peut contenir les deux.
## Deux types de liens cliquables [#deux-types-de-liens-cliquables]
| Type | Question à laquelle il répond | Cibles courantes | Représente une preuve ? |
| :------------ | :------------------------------------------ | :----------------------------------------------------------------------------------------------- | :---------------------- |
| Citation | « Qu'est-ce qui étaye cette affirmation ? » | Blocs de document, texte sélectionné, annotations enregistrées, notes, résultats web ou OpenAlex | Oui |
| Entité Zotero | « De quel objet parle la réponse ? » | Élément, pièce jointe, note, annotation, collection ou tag | Non |
BibGenie peut, par exemple, citer un bloc précis d'un EPUB pour étayer une conclusion tout en affichant la pièce jointe EPUB mentionnée dans la réponse comme un objet cliquable. Le premier sert à vérifier l'affirmation ; le second à ouvrir le document et à poursuivre le travail.
## Ce que cela résout [#ce-que-cela-résout]
Quand on utilise l'IA pour la recherche, le plus grand risque n'est souvent pas le manque de réponses. C'est d'obtenir une réponse fluide sans savoir d'où elle vient.
Dans un vrai travail bibliographique, vous devez souvent distinguer trois éléments :
| Type | Signification | Pourquoi c'est important |
| :--------------- | :------------------------------------------------------------------------ | :---------------------------------------------------------------- |
| Source originale | Un PDF, une note, un instantané, une page web ou un résultat OpenAlex | C'est la base de la réponse |
| Résumé de l'IA | La compression, l'organisation ou l'explication de la source par BibGenie | Utile, mais à vérifier |
| Votre jugement | Votre conclusion à partir de la source et du contexte de recherche | C'est ce qui doit guider l'écriture et les décisions de recherche |
La citation BibGenie conserve une piste claire entre ces couches. Elle vous aide à passer d'une réponse IA à la source, puis à décider vous-même si la réponse est fiable.
## Sources prises en charge [#sources-prises-en-charge]
Les citations BibGenie ne concernent pas seulement les PDF. Lorsque vous travaillez avec différentes sources dans Zotero, les citations peuvent couvrir différents types de documents de recherche.
Lorsque BibGenie lit un PDF, les réponses peuvent citer des pages, des blocs de texte ou des emplacements de paragraphe. Pour les sauts vers un paragraphe précis dans un PDF, consultez les [citations au niveau du paragraphe](https://www.bibgenie.com/fr/docs/paragraph-citations).
Lorsque BibGenie lit un EPUB ou sa section actuelle, les réponses peuvent citer des blocs de texte précis et vous ramener au contenu pertinent dans le Reader EPUB de Zotero.
Quand une réponse repose sur des notes Zotero, des extraits ou des notes de recherche, les citations vous aident à voir de quel contenu de note vient l'information.
Lorsque BibGenie lit des instantanés web enregistrés dans Zotero, les réponses peuvent citer des blocs de texte ou des sélections valides et vous ramener au contenu de la page sauvegardée.
Quand vous utilisez la recherche web ou l'extraction web, les citations peuvent indiquer quel résultat de recherche ou quel corps de page web a été utilisé par la réponse.
Lorsque BibGenie utilise la recherche académique OpenAlex, les citations peuvent pointer vers des articles, auteurs, revues, conférences, institutions, réseaux de citations et autres métadonnées académiques externes.
Les éléments, pièces jointes, notes, collections et tags peuvent apparaître comme des entités cliquables dans une réponse. Vous pouvez ouvrir directement l'objet Zotero sans le confondre avec une preuve issue de la source.
## Le texte sélectionné peut lui aussi être cité [#le-texte-sélectionné-peut-lui-aussi-être-cité]
Vous pouvez ajouter à la conversation du texte sélectionné dans un PDF, un EPUB ou un instantané. En plus de fournir à BibGenie le passage exact à analyser, des données de position Reader valides créent un chemin de retour vers la source :
Sélectionnez dans le Reader le passage à expliquer ou à vérifier, puis choisissez **Add to Chat**.
Posez votre question sur la sélection. BibGenie donne la priorité au passage que vous avez explicitement fourni.
Lorsque la réponse cite cette sélection, cliquez sur la citation pour rouvrir le document et revenir à l'emplacement concerné. Dans les cas pris en charge, notamment les PDF, un surlignage temporaire vous aide à retrouver rapidement la source.
Le texte sélectionné reste utilisable comme contexte de conversation. En revanche, si sa position enregistrée est absente, endommagée ou impossible à résoudre de manière sûre, BibGenie ne crée pas une citation qui semble cliquable mais ne peut pas revenir à la source.
## Comment les citations restent précises dans les documents [#comment-les-citations-restent-précises-dans-les-documents]
Lorsqu'il lit des PDF, EPUB et instantanés, BibGenie organise le contenu en blocs de texte dotés d'identifiants stables. La réponse cite le bloc qui étaye réellement une affirmation, au lieu de désigner toute la pièce jointe comme source.
Trois avantages concrets :
* Un clic sur la citation ramène plus facilement à la page, à la section ou à l'emplacement pertinent.
* Lorsque plusieurs pièces jointes sont analysées ensemble, vous voyez quel document étaye chaque affirmation.
* Lorsque vous copiez une réponse ou l'enregistrez comme note Zotero, les citations conservent des informations de source lisibles.
## Ce que les citations vous aident à faire [#ce-que-les-citations-vous-aident-à-faire]
Pour les conclusions importantes, les données, les descriptions de méthode et les affirmations d'auteurs, cliquez sur une citation pour revenir à la source et confirmer que le document soutient réellement la réponse.
Lorsqu'une réponse est utile, les citations vous ramènent au PDF, à la note, à l'instantané ou au contenu web le plus pertinent afin que vous puissiez continuer à lire.
Lorsque vous transformez votre recherche en notes, les citations conservent le lien entre le résumé et la source, afin que vous n'ayez pas à retrouver les éléments de preuve plus tard.
Lorsque vous combinez des éléments Zotero locaux, des pages web et des résultats OpenAlex, les citations vous aident à distinguer les sources de votre bibliothèque locale des résultats de recherche externes.
## Cas d'usage courants [#cas-dusage-courants]
Vous pouvez demander à BibGenie de résumer la question de recherche, la méthode, le protocole expérimental, les résultats et les limites d'un article. Les citations dans la réponse vous aident à revenir à l'article et à vérifier les affirmations clés.
Si vous voulez comprendre les citations PDF qui reviennent directement au paragraphe source exact, lisez les [citations au niveau du paragraphe](https://www.bibgenie.com/fr/docs/paragraph-citations).
Ajoutez la pièce jointe EPUB complète ou la section actuelle, puis demandez à BibGenie de résumer un argument, d'expliquer un concept ou de comparer plusieurs chapitres. Les citations renvoient aux blocs de texte EPUB réellement utilisés, tandis que le composant de section dans votre message permet de revenir à la position de lecture ajoutée.
Sélectionnez du texte dans un PDF, un EPUB ou un instantané et ajoutez-le à la conversation pour concentrer la question sur un passage. Lorsque la sélection contient des données de position valides, les citations de la réponse peuvent vous ramener au contexte source.
Si vous avez enregistré dans Zotero des extraits, notes de lecture ou idées de recherche, BibGenie peut les organiser par thème. Les citations vous aident à voir de quelle note vient un résumé, au lieu de tout fusionner dans une réponse impossible à retracer.
Lorsque vous enregistrez comme instantané Zotero la page d'un projet, la description d'un jeu de données, une documentation d'outil ou une page d'actualité, BibGenie peut la lire et marquer les sources par des citations. Si vous utilisez la recherche web ou l'extraction web, les citations vous aident aussi à voir quelles pages ont nourri la réponse.
OpenAlex renvoie des métadonnées académiques externes comme les titres, auteurs, DOI, revues, conférences, nombres de citations et relations de citation. Les citations vous aident à rattacher une réponse à un résultat OpenAlex précis et à éviter de traiter des métadonnées externes comme si BibGenie avait lu l'article complet.
Vous pouvez combiner des PDF locaux, des notes Zotero, des résultats OpenAlex et du contenu web dans un même flux de travail. Les citations vous aident à distinguer quelles parties d'une réponse synthétisée viennent de la littérature enregistrée et lesquelles viennent de documents externes de soutien.
## Comment lire les citations [#comment-lire-les-citations]
Les réponses BibGenie incluent souvent des marqueurs de citation comme `[1]` et `[2]`. Traitez-les comme des points d'entrée vers les sources.
**Lisez la structure de la réponse** : vérifiez d'abord si BibGenie a compris le point principal de votre question.
**Repérez les affirmations importantes** : concentrez-vous sur les conclusions que vous pourriez adopter, enregistrer, citer ou utiliser pour une question de suivi.
**Cliquez sur la citation** : revenez au PDF, à la note, à l'instantané, à la page web ou à la source OpenAlex pertinente.
**Vérifiez le contenu source** : confirmez que la source soutient bien l'affirmation, en prêtant attention à la portée, aux formulations et au contexte.
**Poursuivez ou affinez** : si la réponse est trop large, demandez à BibGenie de la reformuler à partir de la source citée.
## Citations et références formelles [#citations-et-références-formelles]
La citation BibGenie sert principalement à la **lecture, la vérification et la traçabilité des sources**. Ce n'est pas le format final de référence pour un article.
| Élément | Citation BibGenie | Référence formelle |
| :-------------------- | :------------------------------------------------------------------------------------ | :------------------------------------------------------------------------ |
| Objectif principal | Revenir à la source derrière une réponse IA | Respecter les exigences de mise en forme d'un article, rapport ou journal |
| Où elle apparaît | Dans les réponses du chat BibGenie | Dans le corps du document et la bibliographie |
| Ce qu'elle privilégie | Traçabilité des sources, vérification des éléments de preuve, poursuite de la lecture | Style de citation, métadonnées de publication, formatage |
| Prête à soumettre | Déconseillée comme citation formelle | Doit être générée et vérifiée dans le style requis |
Si vous rédigez un article, un devoir, une demande de financement ou un rapport formel, vous devez toujours utiliser les styles de citation Zotero, comme APA, MLA, Chicago, GB/T 7714 ou le format demandé par votre revue ou institution.
La citation BibGenie sert à vérifier d'où vient une réponse. Pour une rédaction formelle, revenez à l'élément Zotero et à la source originale, puis utilisez le format de référence requis.
## Pourquoi certaines réponses n'ont pas de citation [#pourquoi-certaines-réponses-nont-pas-de-citation]
Toutes les phrases n'auront pas une citation. Les raisons courantes incluent :
* **La question est opérationnelle** : par exemple, « aide-moi à organiser cette collection » peut produire des étapes de travail plutôt que citer un passage source.
* **La réponse est synthétique** : certains résumés combinent plusieurs sources et ne correspondent pas toujours proprement à une seule citation.
* **La source n'est pas assez claire** : si l'entrée ne contient pas assez de documents traçables, BibGenie peut seulement fournir des conseils généraux.
* **Le web externe ou les métadonnées sont limités** : OpenAlex et les résultats web sont souvent des résumés ou des métadonnées, pas une lecture intégrale.
* **La structure ou la qualité du texte affecte l'analyse** : PDF scannés, OCR peu fiable, mises en page complexes, décalage entre la table des matières et le spine d'un EPUB, ou structure inhabituelle d'un instantané peuvent affecter le positionnement des citations.
Si une affirmation importante n'a pas de citation, vous pouvez naturellement demander d'où vient cette conclusion, ou quel article, quelle note ou quelle page web la soutient. La citation elle-même est toujours ajoutée automatiquement lorsque BibGenie peut tracer la source.
## Conseils d'utilisation [#conseils-dutilisation]
* Ne vous fiez pas seulement au résumé de l'IA pour les conclusions importantes. Cliquez sur les citations et vérifiez la source.
* Quand une citation pointe vers un PDF, un EPUB ou un instantané, lisez le contexte autour plutôt que seulement le texte surligné.
* Quand une citation vient d'OpenAlex, gardez en tête qu'elle représente généralement des métadonnées académiques, pas une lecture complète de l'article.
* Quand une citation vient du web, souvenez-vous que le contenu web peut changer. Pour un usage formel, confirmez-le sur la page originale ou auprès d'une autre source autorisée.
* Lorsque vous rédigez des notes de lecture, conservez les citations générées automatiquement afin de pouvoir revoir la source plus tard.
* Pour les articles formels, ne copiez pas directement la citation BibGenie. Utilisez Zotero pour générer des références standard.
* Si une réponse n'a pas de citation, demandez « sur quoi cette conclusion repose-t-elle ? » ou « de quel article, note ou page web vient-elle ? ».
## Relation avec les citations au niveau du paragraphe [#relation-avec-les-citations-au-niveau-du-paragraphe]
La citation BibGenie est le concept plus large. Elle couvre les PDF, notes, instantanés, pages web, OpenAlex et autres sources traçables. Elle répond à la question :
**D'où viennent les informations de cette réponse IA ?**
Les [citations au niveau du paragraphe](https://www.bibgenie.com/fr/docs/paragraph-citations) sont une fonctionnalité de lecture PDF plus spécifique et plus puissante. Elles répondent à la question :
**Cette conclusion fondée sur un PDF peut-elle revenir au paragraphe exact dans l'article original ?**
Si vous vous intéressez surtout à la lecture approfondie de PDF, aux surlignages du texte original et aux citations qui reviennent dans le Zotero PDF Reader, poursuivez avec les [citations au niveau du paragraphe](https://www.bibgenie.com/fr/docs/paragraph-citations).
La citation BibGenie donne la vue d'ensemble : elle donne des sources aux réponses. Les citations au niveau du paragraphe sont le point fort de la lecture rapprochée des PDF : elles permettent aux réponses PDF de revenir aux paragraphes sources.
# Vos propres clés API (BYOK) (/fr/docs/byok)
BYOK signifie Bring Your Own Key. Cela vous permet d'utiliser votre propre fournisseur de modèles, clé API ou modèle local avec BibGenie.
## Pourquoi utiliser BYOK ? [#pourquoi-utiliser-byok-]
Les requêtes de modèles personnalisés vont directement du plugin Zotero local vers le fournisseur que vous configurez.
Exécutez des modèles sur votre propre machine avec Ollama ou LM Studio.
Les requêtes BYOK n'utilisent pas le service de modèles officiel de BibGenie et ne consomment donc pas de crédits BibGenie.
Utilisez des modèles qui ne sont pas encore inclus dans la liste officielle.
## Les données passent-elles par le service BibGenie ? [#les-données-passent-elles-par-le-service-bibgenie-]
Si vous ajoutez un modèle personnalisé, les données de requête ne passent pas par le service de modèles de BibGenie. Le plugin Zotero local envoie les requêtes directement au fournisseur que vous configurez.
Cela signifie :
* OpenAI API key : les requêtes vont directement à OpenAI.
* Anthropic API key : les requêtes vont directement à Anthropic.
* Proxy compatible OpenAI : les requêtes vont vers la Base URL que vous saisissez.
* Ollama ou LM Studio : les requêtes peuvent rester entièrement sur votre machine.
BYOK contourne le service de modèles de BibGenie, mais les fournisseurs cloud reçoivent toujours le contenu que vous leur envoyez. Choisissez vos fournisseurs selon la politique de données de votre institution, laboratoire ou projet.
## Fournisseurs pris en charge [#fournisseurs-pris-en-charge]
BibGenie prend en charge plusieurs types de fournisseurs :
| Fournisseur | Notes |
| :---------------- | :--------------------------------------- |
| OpenAI | Modèles OpenAI GPT |
| Anthropic | Modèles Claude |
| xAI | Modèles Grok |
| DeepSeek | Modèles DeepSeek |
| Google | Modèles Gemini |
| Groq | Modèles hébergés par Groq |
| Moonshot AI | Modèles Kimi |
| OpenRouter | Plateforme unifiée de routage de modèles |
| Ollama | Service de modèles local |
| OpenAI Compatible | Toute API compatible OpenAI |
LM Studio est généralement configuré via **OpenAI Compatible**.
## Quand BYOK est adapté [#quand-byok-est-adapté]
* Vous avez déjà une clé API fournisseur.
* Vous voulez que la facturation fournisseur passe par votre propre compte.
* Vous devez utiliser un service de modèles institutionnel.
* Vous voulez que les requêtes contournent le service de modèles officiel de BibGenie.
* Vous voulez traiter du contenu sensible avec un modèle local.
* Vous avez besoin d'un modèle qui n'est pas encore dans la liste officielle.
## Étape suivante [#étape-suivante]
Lisez [Modèles personnalisés](/docs/custom-models) pour ajouter un fournisseur, saisir la Base URL et la clé API, puis tester la connexion.
# Format de citation (/fr/docs/citation-format)
Citation Format contrôle la façon dont BibGenie affiche les éléments Zotero dans le contexte du chat. Cela affecte notamment le style du contexte d'élément affiché après avoir saisi `@` dans le champ de saisie.
## Ce que cela affecte [#ce-que-cela-affecte]
* L'affichage des éléments dans les résultats de recherche `@`.
* L'affichage des éléments après leur ajout au contexte du chat.
* La représentation de type citation que BibGenie reçoit comme contexte.
Citation Format ne change que l'affichage. Le titre, les auteurs, l'année, la revue et les autres métadonnées Zotero ne sont pas modifiés.
## Choisir un style CSL [#choisir-un-style-csl]
BibGenie utilise les styles CSL installés dans Zotero. Vous pouvez choisir le style CSL par défaut dans **Citation Format**, dans les préférences.
Styles courants :
* APA
* Chicago
* MLA
* IEEE
* Nature
* Vancouver
## Quand le modifier [#quand-le-modifier]
Choisissez le style requis par votre discipline, votre revue ou votre manuscrit.
Les styles auteur-année sont souvent plus faciles à parcourir en sciences sociales et humaines.
Les styles numérotés conviennent souvent aux flux de travail en ingénierie, informatique ou de type IEEE.
## FAQ [#faq]
BibGenie lit les styles CSL installés dans Zotero. Installez ou activez d'abord le style dans Zotero.
Non. Ce réglage affecte principalement l'affichage du contexte de chat dans BibGenie.
# Gérer les conversations (/fr/docs/conversation-management)
BibGenie conserve chaque conversation comme un parcours de recherche que vous pouvez corriger, prolonger ou ramifier. Vous pouvez modifier votre dernière question, régénérer une réponse, ouvrir une conversation distincte depuis une réponse antérieure et compacter le contexte ancien lorsqu'un échange devient long.
Corrigez le dernier message utilisateur pouvant être modifié en toute sécurité, puis envoyez-le de nouveau.
Demandez à BibGenie de produire de nouveau la dernière réponse à partir du même contexte antérieur.
Démarrez une conversation distincte depuis une réponse terminée sans perdre le parcours d'origine.
Résumez les échanges anciens tout en conservant les messages récents pour la prochaine requête au modèle.
## Modifier la dernière question [#modifier-la-dernière-question]
Placez le pointeur sur le dernier message utilisateur modifiable, puis sélectionnez **Edit**. Après correction et nouvel envoi, BibGenie poursuit la conversation actuelle à partir de la question mise à jour.
La modification remplace tout ce qui suit le message sélectionné dans le parcours actuel. L'ancienne réponse et les états ultérieurs qui en dépendent ne font plus partie de ce parcours. Si vous souhaitez conserver la piste de recherche d'origine, [créez d'abord une branche](#créer-une-branche).
La modification peut être temporairement indisponible pendant que l'IA répond, qu'un outil est en cours d'exécution ou qu'une approbation est attendue.
## Régénérer une réponse [#régénérer-une-réponse]
Si la dernière réponse ne convient pas, sélectionnez **Retry** sous celle-ci. BibGenie conserve le contexte antérieur et génère de nouveau cette réponse.
Retry remplace la réponse d'origine dans le parcours actuel. Si un enregistrement de compaction ultérieur dépend de cette réponse, il devient lui aussi caduc. BibGenie réévalue le contexte lors de l'envoi suivant.
Pour conserver les deux résultats, créez une branche depuis la réponse d'origine avant d'utiliser Retry dans l'une des conversations.
## Créer une branche [#créer-une-branche]
Fork crée une nouvelle conversation à partir d'une réponse terminée. Placez le pointeur sur une réponse de l'assistant pouvant servir de point de départ, sélectionnez **Fork**, puis confirmez. BibGenie crée et ouvre alors la nouvelle conversation.
```text
Conversation d'origine : Question 1 → Réponse 1 → Question 2 → Réponse 2
│
Nouvelle branche : └→ Nouvelle question → Nouvelle réponse
```
La branche reprend la réponse sélectionnée et tout le contexte qui la précède. À partir de ce point, les deux conversations évoluent indépendamment : envoyer, modifier ou régénérer dans l'une ne réécrit pas les messages ultérieurs de l'autre.
Fork est notamment utile pour :
* Explorer plusieurs interprétations ou hypothèses à partir du même article.
* Comparer des prompts, des modèles ou des méthodes d'analyse.
* Préserver un résultat avant une opération susceptible de modifier la suite.
Seules les réponses de l'assistant entièrement terminées et stables peuvent servir de point de Fork. Attendez la fin de la réponse, de l'appel d'outil ou de l'approbation en cours avant de réessayer.
## Compacter une conversation longue [#compacter-une-conversation-longue]
Chaque modèle dispose d'une fenêtre de contexte limitée. À mesure que les messages, articles, images et résultats d'outils s'accumulent, la conversation se rapproche de cette limite. BibGenie peut résumer les échanges anciens sous une forme compacte tout en conservant les messages récents nécessaires à la poursuite du travail.
L'agent BibGenie compacte normalement la conversation automatiquement lorsque cela devient nécessaire. Sauf si vous souhaitez compacter immédiatement le contexte ancien, continuez à poser vos questions sans sélectionner vous-même Compact.
### Compaction automatique [#compaction-automatique]
BibGenie vérifie le contexte disponible aux moments suivants :
* Avant l'envoi d'un nouveau message : si la requête prévue approche de la limite du modèle, BibGenie compacte d'abord le contexte ancien, puis envoie automatiquement votre message.
* Après la fin d'un tour : si l'utilisation du contexte a atteint le seuil prévu, BibGenie compacte les échanges anciens en arrière-plan.
La compaction automatique et la compaction manuelle utilisent le même indicateur de progression. Si l'envoi d'un message déclenche une compaction, le message en attente est envoyé automatiquement dès que celle-ci réussit ; vous n'avez pas à l'envoyer une seconde fois.
### Compaction manuelle [#compaction-manuelle]
Pour compacter immédiatement la conversation actuelle, placez le pointeur sur l'indicateur **Context Window** en bas à droite de la zone de saisie, puis sélectionnez l'icône de compaction en haut à droite de la carte. Pendant l'opération, la conversation affiche **Compacting earlier context…**. Vous pouvez continuer à modifier votre saisie ou sélectionner **Cancel** tant que la compaction n'est pas terminée.
### Consulter le résumé compacté [#consulter-le-résumé-compacté]
Une fois la compaction terminée, un séparateur **Earlier context compacted** apparaît dans la conversation. Développez-le pour consulter :
* Le résumé des échanges antérieurs.
* Le nombre de tokens de contexte avant la compaction.
* Le modèle et les informations de fenêtre de contexte utilisés pour la compaction.
Ce séparateur n'est pas traité comme une question utilisateur ordinaire et les réponses suivantes ne lui répondent pas directement. Avant chaque requête au modèle, BibGenie associe le résumé le plus récent aux messages récents conservés afin de constituer le contexte effectif.
## Articulation entre les actions [#articulation-entre-les-actions]
| Action | Effet sur la conversation actuelle | Crée une conversation | Appelle le modèle |
| :------ | :--------------------------------------------------------------------------------- | :-------------------: | :------------------: |
| Edit | Remplace le message utilisateur sélectionné et la suite du parcours actuel | Non | Lors du nouvel envoi |
| Retry | Remplace la dernière réponse pouvant être régénérée et son état ultérieur | Non | Oui |
| Fork | Conserve l'original et crée un parcours indépendant depuis la réponse sélectionnée | Oui | Non |
| Compact | Résume le contexte ancien tout en conservant les messages récents | Non | Oui |
Si une opération risque de remplacer une réponse que vous souhaitez conserver, créez d'abord une branche.
## Lorsqu'une action est indisponible [#lorsquune-action-est-indisponible]
Edit, Retry, Fork ou Compact peuvent être temporairement indisponibles lorsque :
* BibGenie génère une réponse.
* Un appel d'outil est encore en cours ou attend votre approbation.
* La conversation est en cours de compaction, ou un message envoyé attend la fin de celle-ci.
* Le message sélectionné ne se trouve pas à un emplacement pouvant être modifié ou ramifié en toute sécurité.
* L'historique enregistré est endommagé et la conversation s'est ouverte en lecture seule.
Terminez ou annulez l'opération en cours, puis réessayez. Lorsqu'une conversation s'ouvre en lecture seule, BibGenie conserve l'historique qu'il peut afficher en toute sécurité et ne modifie pas les données enregistrées d'origine.
# Modèles personnalisés (/fr/docs/custom-models)
Les modèles personnalisés vous permettent d'utiliser votre propre clé API, fournisseur tiers, modèle local ou service de modèles institutionnel. Une fois configuré, BibGenie envoie les requêtes directement du plugin Zotero local vers le fournisseur choisi.
## Ajouter un modèle [#ajouter-un-modèle]
Ouvrez BibGenie et allez dans
**Model Settings**
.
Cliquez sur
**Add Model**
dans la section Custom Models.
Sélectionnez ou saisissez un
**Provider ID**
. BibGenie charge les fournisseurs courants depuis un catalogue de modèles et remplit automatiquement Provider Name, Provider Type et Base URL lorsque c'est possible.
Sélectionnez ou saisissez un
**Model ID**
. Si le modèle existe dans le catalogue, BibGenie remplit automatiquement Model Name, Family, Model Types, Context Window, Max Tokens et Description.
Saisissez votre API Key. Pour les services locaux comme Ollama, une clé API n'est généralement pas requise.
Cliquez sur
**Test**
pour vérifier la connexion. Un test réussi affiche
**Connected**
. Si le test échoue, BibGenie affiche le message d'erreur du fournisseur pour vous aider à corriger la configuration.
Vérifiez les champs remplis automatiquement et ajustez Model Types, Context Window ou Max Tokens si nécessaire.
Cliquez sur
**Add Model**
. Le modèle est enregistré, activé et devient disponible dans le sélecteur de modèle du chat.
## Comportement d'auto-remplissage [#comportement-dauto-remplissage]
Ajouter un modèle personnalisé n'est pas entièrement manuel. BibGenie charge les informations de fournisseur et de modèle depuis le catalogue `models.dev` lorsqu'elles sont disponibles :
* Provider ID permet de rechercher des fournisseurs courants et de saisir manuellement un fournisseur personnalisé.
* La sélection d'un fournisseur peut remplir automatiquement Provider Name, Provider Type et Base URL.
* Model ID est filtré selon le fournisseur sélectionné et prend en charge les modèles du catalogue comme les IDs personnalisés.
* La sélection d'un modèle du catalogue peut remplir automatiquement Model Name, Family, Model Types, Context Window, Max Tokens, Description et les métadonnées de prix.
* Si le catalogue de modèles ne peut pas être chargé, BibGenie utilise une liste de fournisseurs de secours intégrée, et vous pouvez toujours ajouter des modèles manuellement.
Si votre fournisseur et votre modèle apparaissent dans les listes de recherche, sélectionnez-les au lieu de tout saisir manuellement. Cela réduit les erreurs de Provider Type, Base URL, capacités du modèle et limites de contexte.
## Champs [#champs]
| Champ | Requis | Description |
| :------------- | :-------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Provider ID | Requis | Identifiant unique du fournisseur, comme `openai`, `anthropic` ou `openrouter` ; les IDs personnalisés sont pris en charge |
| Provider Name | Requis | Nom affiché du fournisseur ; généralement auto-rempli depuis le catalogue |
| Model ID | Requis | ID réel du modèle utilisé par l'API du fournisseur, comme `gpt-4.1` ou `claude-sonnet-4-5` |
| Model Name | Requis | Nom affiché dans BibGenie ; généralement auto-rempli depuis le catalogue |
| API Key | Optionnel | Votre clé API fournisseur ; les fournisseurs locaux comme Ollama n'en demandent généralement pas |
| Base URL | Optionnel | Point d'accès API ; souvent auto-rempli pour les fournisseurs du catalogue, mais les services compatibles ou locaux peuvent nécessiter une confirmation manuelle |
| Provider Type | Requis | Type d'intégration API, comme OpenAI, Anthropic, Ollama ou OpenAI Compatible |
| Family | Optionnel | Famille de modèle, comme `qwen`, `gpt` ou `claude` ; souvent auto-remplie |
| Model Types | Requis | Capacités comme Text, Vision, Reasoning, Function Calling ou Web Search |
| Context Window | Optionnel | Fenêtre de contexte du modèle ; souvent auto-remplie pour les modèles du catalogue |
| Max Tokens | Optionnel | Nombre maximal de tokens de sortie ; souvent auto-rempli pour les modèles du catalogue |
| Description | Optionnel | Description du modèle ; souvent auto-remplie |
## Guide Provider Type [#guide-provider-type]
| Provider Type | À utiliser lorsque |
| :---------------- | :----------------------------------------------------------------------------- |
| OpenAI | Vous utilisez l'API officielle OpenAI |
| Anthropic | Vous utilisez l'API Anthropic Claude |
| xAI | Vous utilisez l'API xAI Grok |
| DeepSeek | Vous utilisez l'API officielle DeepSeek |
| Google | Vous utilisez l'API Gemini |
| Groq | Vous utilisez l'API Groq |
| Moonshot AI | Vous utilisez les modèles Kimi / Moonshot |
| OpenRouter | Vous utilisez l'API OpenRouter |
| Alibaba | Généralement via OpenAI Compatible |
| Z.AI / Zhipu AI | Généralement via OpenAI Compatible |
| Ollama | Vous utilisez un service local Ollama |
| OpenAI Compatible | Vous utilisez LM Studio, un proxy API ou un endpoint institutionnel compatible |
## Base URL [#base-url]
De nombreux fournisseurs officiels ont une Base URL par défaut. Vous devez généralement modifier Base URL uniquement lorsque :
* Vous utilisez OpenAI Compatible.
* Vous utilisez un proxy API.
* Vous utilisez un service de modèle local.
* Votre fournisseur exige un endpoint personnalisé.
Exemples :
```text
https://api.openai.com/v1
https://openrouter.ai/api/v1
http://localhost:11434
http://localhost:1234/v1
```
De nombreuses API compatibles nécessitent une Base URL se terminant par `/v1`. L'absence du chemin de version peut provoquer des erreurs NetworkError, 404 ou model-not-found.
## Exemple Ollama [#exemple-ollama]
Assurez-vous qu'Ollama est installé et en cours d'exécution.
Exécutez
`ollama list`
dans un terminal pour confirmer qu'un modèle local est disponible.
Si Ollama n'est pas encore lancé, démarrez-le avec
`ollama serve`
. Vous verrez une confirmation indiquant qu'il écoute sur
`127.0.0.1:11434`
.
Ajoutez un modèle dans BibGenie et choisissez
**Ollama**
comme Provider Type.
Utilisez
`http://localhost:11434`
comme Base URL.
Utilisez le nom de modèle affiché par
`ollama list`
, comme
`llama3.1:8b`
, comme Model ID.
## Exemple LM Studio [#exemple-lm-studio]
LM Studio est généralement configuré via OpenAI Compatible :
Démarrez le serveur API local dans LM Studio.
Ajoutez un modèle dans BibGenie et choisissez
**OpenAI Compatible**
comme Provider Type.
Saisissez l'adresse API de LM Studio comme Base URL, généralement proche de
`http://localhost:1234/v1`
.
Saisissez comme Model ID l'ID du modèle actuellement chargé dans LM Studio.
## Model Types [#model-types]
Sélectionnez les capacités selon ce que le modèle prend réellement en charge :
* **Text** : chat texte ; généralement requis.
* **Vision** : entrée image, capture d'écran et figure.
* **Reasoning** : utile pour les tâches de raisonnement complexe.
* **Function Calling** : influence les flux de recherche, lecture et gestion de bibliothèque.
* **Web Search** : à activer uniquement si le fournisseur et le modèle le prennent en charge.
Des capacités mal configurées peuvent provoquer `ModelNotSupported` ou des échecs d'appel d'outils.
## FAQ [#faq]
Vérifiez que le modèle a été enregistré et activé. S'il n'apparaît toujours pas, rouvrez Model Settings ou redémarrez Zotero.
Les requêtes de modèles personnalisés sont envoyées directement du plugin Zotero local au fournisseur que vous configurez. Consultez [Bring Your Own Key](/docs/byok) pour les détails du flux de données.
Vérifiez que le service local tourne, que le port est correct, que la Base URL est joignable et qu'aucun pare-feu ou proxy ne bloque la requête.
Oui. Votre clé API est chiffrée et stockée uniquement dans votre configuration Zotero locale. Elle est utilisée directement pour les requêtes vers le fournisseur et ne passe **jamais** par les serveurs de BibGenie.
Cliquez sur le bouton **Reset** dans la zone Custom Models pour restaurer toutes les configurations personnalisées à leur état initial. **Attention : cela supprimera tous les modèles que vous avez ajoutés manuellement.**
# Dépannage (/fr/docs/error-in-bibgenie)
Cette page vous aide à diagnostiquer les erreurs courantes de BibGenie et à choisir la bonne étape suivante.
Avant de dépanner, assurez-vous d'utiliser la dernière version de BibGenie. De nombreux problèmes de modèles, de compatibilité Zotero ou de réseau peuvent déjà être corrigés dans une version plus récente.
Les boîtes de dialogue d'erreur contiennent souvent des informations utiles comme le nom du modèle, la Request URL, la réponse du fournisseur et la raison de l'échec. Lisez-les attentivement avant de modifier les paramètres.
## ModelNotSupported [#modelnotsupported]
Une boîte de dialogue intitulée "ModelNotSupported".
Le modèle sélectionné ne prend pas en charge le type d'entrée actuel. Cela arrive souvent lorsque vous envoyez une image à un modèle qui ne prend pas en charge les entrées Vision.
### Comment corriger [#comment-corriger]
Choisissez un modèle qui prend en charge la capacité requise, par exemple Vision pour les images ou captures d'écran.
Si vous utilisez un modèle personnalisé et savez qu'il prend en charge les images, vérifiez qu'il est marqué comme modèle **Vision** dans Custom Models.
Si la tâche nécessite l'utilisation d'outils, assurez-vous que le modèle prend en charge **Function Calling**.
## AI\_APICallError [#ai_apicallerror]
Une boîte de dialogue intitulée "AI\_APICallError".
La requête vers l'API du modèle a échoué. Les causes fréquentes incluent une API Key invalide, un mauvais Model ID, une Base URL incorrecte, un délai d'attente fournisseur ou une panne réseau.
### Types d'erreurs courants [#types-derreurs-courants]
Les clés invalides ou expirées peuvent produire des messages comme :
```text
Unauthorized Failure reason: Authentication Fails
(auth header format should be Bearer sk-...)
```
```text
Incorrect API key provided.
```
Vérifiez que l'API Key est complète, active et qu'elle appartient au fournisseur sélectionné.
De mauvais Model IDs peuvent produire des messages comme :
```text
Model Not Exist
```
Comparez le Model ID dans BibGenie avec l'identifiant exact affiché par le fournisseur.
Des Base URLs incorrectes peuvent provoquer des erreurs de requête ou des 404.
De nombreux fournisseurs exigent une Base URL se terminant par `/v1`. Une URL comme `/v/` au lieu de `/v1/` échouera.
### Comment corriger [#comment-corriger-1]
Actualisez la liste des modèles officiels dans Model Settings. Si le problème persiste, mettez BibGenie à jour et contactez le support avec le message d'erreur complet.
Vérifiez Provider Type, Provider ID, Model ID, API Key et Base URL. Utilisez le bouton Test dans Custom Models pour vérifier la connexion.
Assurez-vous qu'Ollama, LM Studio ou votre serveur local est en cours d'exécution, que le port est correct et que la Base URL est accessible depuis l'environnement navigateur de Zotero.
## NetworkError [#networkerror]
Une erreur comme `TypeError: NetworkError when attempting to fetch resource.`
BibGenie n'a pas pu atteindre le point de terminaison du fournisseur.
Causes possibles :
* Le serveur de modèle local n'est pas lancé.
* La Base URL ou le port est incorrect.
* Un pare-feu, un proxy ou une politique réseau bloque la requête.
* Le point de terminaison du fournisseur est temporairement indisponible.
* Le fournisseur configuré ne prend pas en charge les requêtes côté navigateur dans votre environnement.
## Problèmes de pièces jointes ou de contexte [#problèmes-de-pièces-jointes-ou-de-contexte]
Si BibGenie ne peut pas lire un PDF, un instantané, une note ou un texte sélectionné :
* Assurez-vous que le fichier existe sur cet appareil.
* Si vous utilisez la synchronisation Zotero, vérifiez que la pièce jointe a été téléchargée localement.
* Pour les utilisateurs WebDAV, vérifiez que la synchronisation des fichiers Zotero fonctionne.
* Essayez d'ouvrir directement la pièce jointe dans Zotero.
* Redémarrez Zotero si l'état du lecteur semble obsolète.
## Problèmes de connexion MCP [#problèmes-de-connexion-mcp]
Si un client MCP externe ne parvient pas à se connecter :
* Confirmez que **Enable MCP Server** est activé.
* Copiez à nouveau la Server URL.
* Cliquez sur **Test Connection** dans MCP Settings.
* Assurez-vous que Zotero est toujours en cours d'exécution.
* Déconnectez les clients auxquels vous ne faites pas confiance.
## Obtenir de l'aide [#obtenir-de-laide]
Si le problème persiste, envoyez les informations suivantes lorsque vous demandez de l'aide :
* Version de BibGenie
* Version de Zotero
* Système d'exploitation
* Utilisation d'un modèle officiel ou personnalisé
* Provider Type et Model ID
* Message d'erreur complet
* Indiquez si le problème survient avec un PDF, une note ou un type de contexte particulier
Vous pouvez rejoindre la [communauté Discord BibGenie](https://discord.gg/kDXFAAYDNE) pour obtenir de l'aide.
# Bien démarrer (/fr/docs/getting-started)
Ce guide vous mène au plus vite vers une configuration fonctionnelle : télécharger le plugin, l'installer dans Zotero, ouvrir la barre latérale et poser votre première question sur un article.
BibGenie prend en charge Zotero 7, Zotero 8, Zotero 9 et Zotero 10. Nous recommandons d'utiliser une version récente de Zotero pour profiter de l'expérience plugin et lecteur la plus stable.
## Télécharger le plugin [#télécharger-le-plugin]
Rendez-vous sur la [page de téléchargement BibGenie](https://www.bibgenie.com/download) et téléchargez la dernière version du plugin.
Le fichier téléchargé s'appelle généralement :
```text
bibgenie-.xpi
```
où `` correspond au numéro de version.
## Installer BibGenie dans Zotero [#installer-bibgenie-dans-zotero]
Ouvrez Zotero et choisissez **Tools -> Plugins** dans la barre de menus.
Dans la fenêtre Plugin Manager, cliquez sur l'icône d'engrenage en haut à droite et choisissez **Install Plugin From File...**.
Sélectionnez le fichier `bibgenie-.xpi` que vous avez téléchargé.
Redémarrez Zotero après l'installation.
Après le redémarrage, ouvrez BibGenie depuis la barre d'outils Zotero ou le menu Tools.
## Ouvrir BibGenie [#ouvrir-bibgenie]
Vous pouvez ouvrir BibGenie de plusieurs façons :
* Cliquez sur l'icône BibGenie dans la barre d'outils Zotero.
* Choisissez **Tools -> BibGenie** dans la barre de menus.
* Utilisez le raccourci clavier configuré pour afficher ou basculer vers la barre latérale BibGenie.
Si le raccourci entre en conflit avec Zotero ou votre système d'exploitation, vous pouvez le modifier dans [Raccourcis clavier](/docs/keyboard-shortcuts).
## Se connecter [#se-connecter]
Les utilisateurs gratuits peuvent commencer avec les fonctionnalités principales de chat et de contexte. Une fois connecté, BibGenie peut synchroniser votre statut d'abonnement, votre solde de crédits et l'accès aux modèles officiels.
Inclut les fonctions principales, la lecture d'articles et la recherche externe avec OpenAlex, Web Search et Web Extract.
Inclut davantage de crédits mensuels pour la lecture fréquente d'articles, les comparaisons et les workflows de recherche.
## Poser votre première question [#poser-votre-première-question]
Une bonne première tâche consiste à commencer avec un article PDF :
Sélectionnez un élément Zotero qui possède une pièce jointe PDF.
Au premier lancement, BibGenie utilise par défaut un modèle intégré. Vous n'avez pas besoin de configurer une clé API ni de choisir manuellement un modèle avant de poser votre première question.
Dans le champ de saisie BibGenie, tapez un espace suivi de `@`, puis recherchez et ajoutez l'article. Vous pouvez aussi faire un clic droit sur l'élément Zotero et choisir **Add to Chat**.
Posez une question concrète, par exemple :
```text
Summarize this paper's research question, method, main findings, and limitations.
```
Si la réponse est utile, cliquez sur **Save as Note** sur le dernier message de l'assistant pour l'enregistrer comme note Zotero.
Si vous souhaitez utiliser plus tard votre propre clé API, un modèle local ou un service de modèles institutionnel, lisez [Bring Your Own Key](/docs/byok) et [Modèles personnalisés](/docs/custom-models).
Les bons prompts précisent à la fois l'objectif et le format attendu, par exemple "résumer en cinq points", "utiliser des sections méthode, résultats et limites" ou "transformer cela en note de revue de littérature".
## Étapes suivantes [#étapes-suivantes]
* Apprendre à ajouter un contexte plus riche : [Ajouter du contexte](/docs/add-context)
* Apprendre à modifier, régénérer, ramifier et compacter une conversation : [Gérer les conversations](/docs/conversation-management)
* Comprendre les choix de modèles : [Modèles](/docs/models)
* Comprendre les offres et crédits : [Tarifs & crédits](/docs/pricing-credits)
* Créer des prompts réutilisables : [Quick Prompts](/docs/quick-prompts)
## Mettre à jour BibGenie [#mettre-à-jour-bibgenie]
BibGenie vérifie automatiquement les mises à jour au démarrage de Zotero. Lorsqu'une nouvelle version est détectée, un bouton de mise à jour apparaît dans la barre de menu de BibGenie — cliquez dessus pour installer la dernière version.
Vous pouvez également activer les mises à jour automatiques via le gestionnaire de plugins de Zotero :
Ouvrez Zotero et choisissez **Outils -> Plugins**.
Sélectionnez BibGenie dans la liste des plugins.
Activez **Allow automatic updates** en position On. Zotero mettra alors automatiquement à jour BibGenie lorsque de nouvelles versions seront disponibles.
# Vue d'ensemble (/fr/docs)
BibGenie est un agent de recherche IA intégré directement à Zotero. Au lieu de fonctionner comme un chatbot web séparé, il travaille dans votre espace Zotero avec votre bibliothèque, vos PDF, instantanés web, notes et documents en cours de lecture.
Ajoutez des éléments Zotero, pièces jointes PDF, instantanés, notes, texte sélectionné, contexte de page, images ou captures d'écran à une conversation, puis demandez à BibGenie de lire, expliquer, rechercher, organiser et préserver votre matériel de recherche.
L'expérience centrale de BibGenie s'exécute dans votre environnement Zotero. L'historique de chat et de nombreux paramètres sont stockés localement. Lorsque vous utilisez un modèle personnalisé ou local, les requêtes sont envoyées directement au fournisseur que vous configurez.
## Flux de travail principal [#flux-de-travail-principal]
Ajoutez des éléments Zotero, PDF, instantanés, notes, texte sélectionné ou captures d'écran afin que BibGenie comprenne le matériau sur lequel vous travaillez.
Résumez des articles, expliquez des figures, recherchez dans votre bibliothèque, comparez des articles, utilisez OpenAlex pour les données académiques publiques ou recherchez des informations sur le web public.
Vérifiez les données avec arXiv, Semantic Scholar, OpenAlex, DBLP et OpenReview, comblez les lacunes et mettez à niveau les prépublications en toute sécurité. En savoir plus : [Révision des métadonnées](/docs/metadata-review).
Enregistrez les réponses utiles sous forme de notes Zotero, ou demandez à BibGenie d'aider à organiser tags, collections et métadonnées.
## Ce que vous pouvez faire avec BibGenie [#ce-que-vous-pouvez-faire-avec-bibgenie]
* Lire des articles : résumer les questions de recherche, méthodes, contributions, limites et pistes futures.
* Lire en profondeur des extraits : expliquer des passages sélectionnés, formules, figures ou résultats expérimentaux.
* Rechercher dans votre bibliothèque : trouver des articles pertinents par mots-clés ou en décrivant un sujet de recherche en langage naturel.
* Réviser et mettre à niveau les métadonnées : vérifier les informations avec plusieurs bases académiques, convertir les prépublications arXiv en versions de revue/conférence et sécuriser les clés Better BibTeX. En savoir plus : [Révision des métadonnées](/docs/metadata-review).
* Organiser votre bibliothèque : gérer tags, collections, métadonnées et déplacement d'éléments.
* Enregistrer des notes : transformer des réponses IA structurées en notes Zotero.
* Gérer les conversations : modifier la dernière question, régénérer des réponses, créer des branches et compacter le contexte ancien.
* Connecter des outils externes : exposer les outils Zotero locaux via le serveur MCP de BibGenie.
## Parcours de lecture recommandé [#parcours-de-lecture-recommandé]
**Première configuration** : commencez par [Bien démarrer](/docs/getting-started) pour installer BibGenie et poser votre première question.
**Comprendre les modèles et crédits** : lisez [Modèles](/docs/models) et [Tarifs & crédits](/docs/pricing-credits).
**Apprendre les fonctionnalités clés** : continuez avec [Ajouter du contexte](/docs/add-context), [Gérer les conversations](/docs/conversation-management), [Recherche bibliographique](/docs/literature-search), [Révision des métadonnées](/docs/metadata-review) et [Enregistrer comme note](/docs/save-as-note).
**Configuration avancée** : si vous avez votre propre clé API ou un modèle local, lisez [Bring Your Own Key](/docs/byok) et [Modèles personnalisés](/docs/custom-models).
## Sections de la documentation [#sections-de-la-documentation]
Installation, modèles, tarifs et crédits.
Contexte, prompts, recherche, accès web, révision des métadonnées, gestion de bibliothèque, notes et MCP.
Modèles personnalisés, MCP, Add to Chat, raccourcis, format de citation et indexation sémantique.
Erreurs fréquentes, échecs de modèles, problèmes réseau et compatibilité Zotero.
# Raccourcis clavier (/fr/docs/keyboard-shortcuts)
BibGenie prend en charge un raccourci clavier pour afficher ou basculer vers la barre latérale de chat. Vous pouvez le personnaliser selon votre flux de travail.
## Modifier le raccourci [#modifier-le-raccourci]
Ouvrez BibGenie Preferences.
Trouvez la section **Keyboard Shortcuts**.
Choisissez un modificateur, comme Ctrl + Shift ou Command + Shift.
Saisissez la touche principale, par exemple `L`.
Vérifiez les avertissements de conflit et enregistrez.
## Détection des conflits [#détection-des-conflits]
BibGenie vérifie les conflits avec les commandes Zotero courantes. Si un conflit est détecté, la page de paramètres affiche la commande concernée.
Si le raccourci ne fonctionne pas, les causes possibles incluent :
* Conflit avec un raccourci Zotero intégré.
* Conflit avec un raccourci du système d'exploitation.
* Conflit avec un autre plugin Zotero.
* Le focus se trouve actuellement dans un champ de saisie, une fenêtre modale ou un contrôle système.
* Votre méthode de saisie ou système d'exploitation a intercepté la combinaison de touches.
## Dépannage [#dépannage]
Essayez une autre combinaison, comme Ctrl / Command + Shift + L. Cliquez aussi dans la fenêtre principale de Zotero avant d'utiliser le raccourci.
Cela signifie généralement qu'il y a un conflit. Choisissez une touche principale moins courante dans Keyboard Shortcuts.
Command + Shift est généralement la convention la plus adaptée sur macOS.
# Gestion de bibliothèque (/fr/docs/library-management)
BibGenie peut faire plus que lire des articles. Il peut vous aider à organiser votre bibliothèque Zotero en gérant les tags, en créant des collections, en déplaçant des éléments et en modifiant les métadonnées.
Les actions de gestion de bibliothèque peuvent modifier votre bibliothèque Zotero. Pour les opérations par lot, demandez à BibGenie d'afficher un plan ou un aperçu avant d'appliquer des changements.
## Tâches d'organisation prises en charge [#tâches-dorganisation-prises-en-charge]
| Tâche | Exemples |
| :----------------------------- | :--------------------------------------------------------------------- |
| Gestion des tags | Ajouter, supprimer et lister des tags |
| Gestion des collections | Créer des collections, lister les collections, déplacer des éléments |
| Édition des métadonnées | Modifier titre, abstract, titre de publication, DOI et champs associés |
| Lecture des métadonnées | Inspecter auteurs, année, pièces jointes, notes et tags |
| Classification bibliographique | Grouper les articles par sujet, méthode, année ou projet |
Si vous devez interroger arXiv, Semantic Scholar, OpenAlex, DBLP ou OpenReview pour compléter automatiquement les résumés, DOI, abréviations de revues ou normaliser la casse, consultez le guide dédié [Révision et nettoyage des métadonnées](/docs/metadata-review).
## Flux courants [#flux-courants]
Ajoutez `literature-review` ou un tag de projet aux éléments sélectionnés.
Créez une nouvelle collection autour d'un sujet de recherche et déplacez-y les articles pertinents.
Trouvez les articles sans DOI, abstract ou titre de publication.
Groupez les articles dans une structure de bibliothèque plus claire selon les thèmes de recherche.
## Exemples de prompts [#exemples-de-prompts]
```text
Review the selected papers and propose a collection structure by research topic. Do not modify Zotero yet.
```
```text
Add the tags deep-research and llm-agent to the currently selected papers.
```
```text
Find papers in this collection that are missing a DOI or abstract, and return a table.
```
## Flux recommandé [#flux-recommandé]
Demandez à BibGenie de rechercher ou lister les articles candidats.
Demandez un plan d'organisation, incluant les éléments qui seront modifiés.
Examinez le plan.
Autorisez explicitement BibGenie à appliquer les changements.
Demandez un résumé de ce qui a été modifié.
Pour le travail par lot, précisez le périmètre : "only selected items", "only this collection" ou "do not edit metadata, only add tags".
## À manipuler avec prudence [#à-manipuler-avec-prudence]
* Déplacer beaucoup d'articles en une fois.
* Supprimer des tags en masse.
* Écraser titres, abstracts, DOI ou autres métadonnées clés.
* Créer ou réorganiser des collections sur de nombreux éléments.
Pour ces opérations, travaillez par lots plus petits et demandez d'abord à BibGenie de lister les éléments concernés.
# Recherche bibliographique (/fr/docs/literature-search)
Par défaut, BibGenie recherche et lit d'abord votre bibliothèque Zotero au lieu d'aller directement sur le web public. Les réponses restent ainsi ancrées dans les documents que vous avez déjà collectés et organisés.
## Trois modes de recherche [#trois-modes-de-recherche]
Idéal lorsque vous connaissez un titre, auteur, année, DOI, tag, collection ou autre indice explicite.
Idéal lorsque vous voulez décrire un sujet, une théorie, une méthode ou un problème de recherche en langage naturel.
Idéal pour lister des articles candidats, parcourir les résultats ou inspecter les éléments dans un périmètre défini.
## Keyword Search [#keyword-search]
Keyword Search fonctionne bien lorsque vous connaissez déjà une partie de l'information recherchée :
* Mots dans le titre de l'article
* Nom d'auteur
* Année
* DOI
* Nom de collection
* Nom de tag
* Nom de revue ou conférence
Exemples :
```text
Find papers in my Zotero library about contrastive learning.
```
```text
Find causal inference papers after 2022 with the tag review.
```
Keyword Search est précis et facile à contrôler. En contrepartie, il peut manquer des articles pertinents si votre formulation ne correspond pas aux métadonnées.
## Semantic Search [#semantic-search]
Semantic Search est conçu pour les requêtes conceptuelles. Vous n'avez pas besoin de deviner les termes exacts utilisés dans les titres ou abstracts ; décrivez plutôt le sujet de recherche.
Exemples :
```text
Find papers that discuss how large language models affect academic writing norms.
```
```text
My project is about how AI tools change researchers' knowledge work. Find related papers.
```
Semantic Search utilise un index local des titres et abstracts des éléments Zotero standards. Gardez en tête :
* Ce n'est pas une recherche plein texte dans les PDF.
* Les articles sans abstract peuvent être plus difficiles à trouver.
* La première exécution peut demander du temps pour construire l'index sémantique.
Consultez [Semantic Index](/docs/semantic-index) pour l'état de l'index et le dépannage.
## List Items [#list-items]
List Items sert à afficher les articles correspondants ou à poursuivre la navigation dans les résultats.
Exemples de demandes :
```text
List the 20 most recent papers in this collection.
```
```text
Show more results.
```
```text
List papers tagged systematic-review and sort them by year.
```
List Items est particulièrement utile lorsque vous voulez que BibGenie affiche d'abord un ensemble candidat, puis décider quels PDF ou notes lire ensuite.
## Flux recommandé [#flux-recommandé]
Utilisez Semantic Search pour trouver des articles liés à un sujet large.
Demandez à BibGenie de lister titres, années, auteurs et abstracts.
Sélectionnez quelques articles et ajoutez-les comme contexte.
Demandez à BibGenie de lire les PDF, comparer les claims, générer un tableau ou enregistrer une note.
Ajoutez une année, un tag, une collection ou une limite de résultats pour rendre les recherches plus utiles. Par exemple : "only after 2020", "within the Methods collection" ou "return at most 10 papers".
# Paramètres MCP (/fr/docs/mcp-settings)
MCP Settings contrôle le serveur MCP local de BibGenie. Lorsqu'il est activé, des clients MCP externes peuvent se connecter à la Server URL et accéder aux outils Zotero de BibGenie.
## Contrôles [#contrôles]
Démarre ou arrête le serveur MCP local.
L'URL utilisée par les clients externes pour se connecter à BibGenie. Elle ressemble souvent à `http://127.0.0.1:23119/bibgenie/mcp`, mais le port peut changer si Zotero utilise un port HTTP personnalisé.
Copie la Server URL dans votre presse-papiers.
Envoie une requête MCP initialize via HTTP POST JSON-RPC pour vérifier que le point d'accès est joignable.
Ouvrir directement la Server URL dans un navigateur n'est pas une connexion MCP. Les clients MCP envoient des requêtes POST JSON-RPC, tandis que la barre d'adresse du navigateur envoie une requête GET. Utilisez **Test Connection** pour le vrai test.
## Référence des statuts [#référence-des-statuts]
| Statut | Signification |
| :------------------ | :----------------------------------------------------- |
| Server is off | MCP Server est désactivé |
| Starting | Le serveur démarre |
| Server running | Le serveur est prêt pour les clients externes |
| Testing connection | Le test de connexion est en cours |
| Connection verified | Le test a réussi |
| Connection failed | Le test a échoué ; vérifiez l'URL ou l'état du serveur |
## Si la connexion échoue [#si-la-connexion-échoue]
* Vérifiez que Zotero est en cours d'exécution.
* Vérifiez que BibGenie est activé dans Zotero.
* Vérifiez que **Enable MCP Server** est activé.
* Copiez la Server URL affichée au lieu de supposer que le port est `23119`.
* Redémarrez Zotero si le serveur vient d'être activé ou si le plugin vient d'être mis à jour.
## Activer MCP [#activer-mcp]
Ouvrez BibGenie Preferences.
Trouvez la section **MCP Server**.
Activez **Enable MCP Server**.
Attendez que la Server URL apparaisse.
Cliquez sur Copy et collez l'URL dans votre client MCP externe.
Cliquez sur Test Connection pour vérifier que cela fonctionne.
## Désactiver MCP [#désactiver-mcp]
Lorsque vous n'utilisez pas de clients externes, désactivez **Enable MCP Server**. Les clients externes ne pourront alors plus accéder aux outils MCP de BibGenie.
Les outils MCP peuvent lire ou modifier votre bibliothèque Zotero. Ne partagez la Server URL qu'avec des clients de confiance.
# MCP (/fr/docs/mcp)
MCP signifie Model Context Protocol. BibGenie peut démarrer un serveur MCP local qui permet aux clients compatibles MCP d'accéder à des outils liés à Zotero.
Si vous discutez uniquement dans le plugin BibGenie, vous n'avez pas besoin de configurer MCP. MCP s'adresse surtout aux utilisateurs avancés, aux clients externes et aux flux automatisés.
## Que peut faire MCP ? [#que-peut-faire-mcp-]
Les clients externes peuvent utiliser les outils Zotero de BibGenie pour :
* rechercher des éléments Zotero ;
* lancer une recherche bibliographique sémantique ;
* lire les pièces jointes PDF ;
* lire les instantanés ;
* lire les notes Zotero ;
* lister les tags et collections ;
* créer des notes Zotero ;
* gérer les tags et collections ;
* obtenir ou modifier des métadonnées.
## Qu'est-ce que Zotero MCP ? [#quest-ce-que-zotero-mcp-]
Zotero MCP est le pont local de BibGenie entre votre bibliothèque Zotero et des clients IA externes. Au lieu d'exporter des fichiers ou de copier manuellement des métadonnées, un client compatible MCP peut demander du contexte Zotero à BibGenie via un protocole local.
Par exemple, un client externe peut rechercher dans votre bibliothèque, inspecter des collections, lire une pièce jointe PDF ou créer une note Zotero avec les outils MCP de BibGenie.
## Avantages principaux [#avantages-principaux]
Le serveur MCP de BibGenie s'exécute dans le plugin Zotero. Vous n'avez pas besoin d'un service Python séparé ni d'un backend local personnalisé.
Le point d'accès MCP s'exécute sur le serveur HTTP local de Zotero. Votre client externe communique avec Zotero sur votre propre appareil.
Les outils sont conçus pour les flux Zotero : articles, PDF, collections, tags, notes, instantanés et métadonnées.
MCP permet à Cursor, Claude Code, Claude Desktop et Cherry Studio d'utiliser le contexte Zotero sans quitter leur propre interface.
## Fonctionnalités principales [#fonctionnalités-principales]
| Fonctionnalité | Utilité |
| :--------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------- |
| Recherche d'éléments | Trouver des articles par titre, auteur, publication, mot-clé ou sujet. |
| Recherche sémantique | Découvrir des articles liés par le sens, pas seulement par des mots exacts. |
| Accès aux métadonnées | Lire les métadonnées Zotero détaillées avant de citer, organiser ou modifier. |
| Lecture de PDF | Lire le texte des pièces jointes PDF Zotero lorsque le client a besoin du contenu de l'article. |
| Lecture visuelle de PDF | Rendre des pages PDF en images lorsque des figures, tableaux ou pages scannées doivent être inspectés visuellement. |
| Notes et instantanés | Lire les notes Zotero et les instantanés web de votre bibliothèque. |
| Organisation de bibliothèque | Lister les collections et tags, créer des collections, gérer les tags ou l'appartenance aux collections. |
| Révision des métadonnées | Exécuter `review_metadata` en lecture seule pour agréger les faits d'arXiv, Semantic Scholar, OpenAlex, DBLP et OpenReview avec diagnostics. |
| Écriture contrôlée | Les clients de confiance peuvent créer des notes ou valider et appliquer des modifications de métadonnées via `edit_metadata`. |
## Chat du plugin ou MCP [#chat-du-plugin-ou-mcp]
| Mode | Idéal pour | Configuration requise |
| :--------------------------- | :----------------------------------------------------------- | :-------------------- |
| Chat BibGenie dans le plugin | La plupart des utilisateurs | Non |
| Serveur MCP local | Utilisateurs qui connectent Zotero à des clients IA externes | Oui |
## Type de serveur et URL [#type-de-serveur-et-url]
Le serveur MCP de BibGenie utilise **Streamable HTTP**. La Server URL ressemble généralement à ceci :
```text
http://127.0.0.1:23119/bibgenie/mcp
```
Le port peut être différent si le serveur HTTP de Zotero utilise un port personnalisé. Copiez toujours la Server URL affichée dans les paramètres BibGenie au lieu de la saisir manuellement.
Les clients MCP se connectent avec des requêtes HTTP POST JSON-RPC. La barre d'adresse du navigateur envoie une requête GET et ne constitue pas un test fiable. Utilisez **Test Connection** dans BibGenie ou un client MCP.
## Activer le serveur MCP [#activer-le-serveur-mcp]
Ouvrez les paramètres de BibGenie.
Repérez la section **MCP Server**.
Activez **Enable MCP Server**.
Copiez la Server URL affichée.
Collez l'URL dans votre client MCP externe.
Cliquez sur **Test Connection** pour vérifier que tout fonctionne.
## Connecter des clients externes [#connecter-des-clients-externes]
Utilisez la Server URL des paramètres BibGenie dans les clients compatibles Streamable HTTP MCP.
### Cursor [#cursor]
Cursor peut se connecter directement au point d'accès Streamable HTTP de BibGenie.
Ouvrez Cursor Settings et allez dans **Tools & MCP**.
Cliquez sur **+ New MCP Server**.
Collez cette configuration :
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"url": "http://127.0.0.1:23119/bibgenie/mcp"
}
}
}
```
Remplacez l'URL si BibGenie affiche un autre port.
Enregistrez la configuration. Lorsque Cursor indique que le serveur MCP est connecté, vous pouvez utiliser le contexte Zotero dans le chat Cursor.
### Claude Code [#claude-code]
Claude Code prend directement en charge les serveurs MCP HTTP :
```bash
claude mcp add ZoteroBibGenie --transport http http://127.0.0.1:23119/bibgenie/mcp
```
Remplacez l'URL si BibGenie affiche un autre port.
### Claude Desktop [#claude-desktop]
Certaines versions de Claude Desktop se connectent plus facilement aux serveurs MCP stdio qu'aux points d'accès HTTP locaux. Dans ce cas, utilisez `mcp-remote` comme pont vers le serveur HTTP local de BibGenie.
Installez Node.js si `node` et `npx` ne sont pas disponibles sur votre système.
Ouvrez Claude Desktop.
Ouvrez **Settings**, puis la section **Developer**.
Cliquez sur **Edit Config** pour ouvrir `claude_desktop_config.json`.
Ajoutez cette configuration :
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"command": "npx",
"args": ["mcp-remote", "http://127.0.0.1:23119/bibgenie/mcp"]
}
}
}
```
Remplacez l'URL si BibGenie affiche un autre port.
Enregistrez le fichier et redémarrez Claude Desktop.
### Cherry Studio [#cherry-studio]
Cherry Studio prend directement en charge Streamable HTTP MCP.
Ouvrez Cherry Studio Settings et passez à l'onglet **MCP**.
Cliquez sur **Add** et choisissez **Quick Create**.
Renseignez :
* **Name**: `ZoteroBibGenie`
* **Type**: `Streamable HTTP`
* **URL**: la Server URL copiée depuis les paramètres BibGenie

Facultatif : ouvrez **Advanced Settings** et définissez :
* **Provider URL**: `https://www.bibgenie.com/`
* **Logo URL**: `https://www.bibgenie.com/favicon.png`

Cliquez sur **Save**, activez le service et utilisez le bouton de vérification de Cherry Studio pour tester la connexion.
## Exemples de prompts [#exemples-de-prompts]
* « Trouve dans Zotero des articles sur la génération augmentée par récupération publiés après 2023. »
* « Lis la pièce jointe PDF de cet élément Zotero et résume la contribution principale de l'article. »
* « Liste les éléments de ma collection machine learning et trouve ceux auxquels il manque l'année. »
## Recommandations de sécurité [#recommandations-de-sécurité]
* Ne partagez la MCP Server URL qu'avec des clients de confiance.
* Soyez prudent avec les outils qui écrivent dans votre bibliothèque Zotero, par exemple la création de notes, la modification de métadonnées ou la gestion des tags et collections.
* Désactivez le serveur lorsque vous n'utilisez pas MCP.
* Si un client externe se comporte de manière inattendue, arrêtez le serveur MCP et vérifiez la configuration du client.
## FAQ [#faq]
Non. Le chat intégré au plugin peut utiliser directement les capacités internes de BibGenie. MCP est réservé aux clients externes.
Non. C'est un service local exécuté dans votre environnement Zotero et BibGenie.
Vérifiez que le serveur MCP est activé, que l'URL a été copiée correctement, que Zotero est en cours d'exécution et que Test Connection réussit. Si Zotero utilise un port HTTP personnalisé, l'URL peut ne pas utiliser `23119`.
Non. La barre d'adresse du navigateur envoie une requête GET, alors que les clients MCP utilisent POST JSON-RPC. Utilisez Test Connection ou configurez un client MCP.
Les clients MCP chargent et mettent parfois en cache la liste des outils. Redémarrez le client externe, vérifiez que BibGenie est à jour et reconnectez le serveur MCP.
Oui. La connexion Zotero MCP de base fournie par **BibGenie** est gratuite. Vous pouvez l'utiliser pour connecter n'importe quel client compatible MCP.
# Révision et nettoyage des métadonnées (/fr/docs/metadata-review)
La révision et le nettoyage des métadonnées constituent l'une des fonctionnalités clés de BibGenie. Les documents importés depuis des pages web académiques, des fichiers PDF ou des extracteurs généralistes souffrent fréquemment de métadonnées incomplètes (résumés, DOI, pagination ou revues manquants), de titres entièrement en majuscules, d'abréviations de revues absentes, de prépublications non actualisées et de listes d'auteurs tronquées.
BibGenie associe **l'intelligence scientifique des grands modèles de langage** à des **bases de données académiques de référence**. Grâce à un moteur d'examen strictement en lecture seule, des preuves transparentes et une approbation par comparaison visuelle, vous maintenez facilement une bibliothèque Zotero rigoureuse et standardisée.
La phase d'examen fonctionne exclusivement en lecture seule et ne modifie jamais votre bibliothèque en arrière-plan. L'IA produit une **carte de prévisualisation visuelle (Action Preview)** comparant les anciennes et les nouvelles valeurs. Les modifications ne sont appliquées dans Zotero que si vous cliquez expressément sur « Approuver ».
## Capacités principales [#capacités-principales]
Interroge arXiv, Semantic Scholar, OpenAlex, DBLP et OpenReview en routant intelligemment selon le DOI, l'identifiant arXiv ou la clé DBLP.
Choisissez entre `lint` (règles et mise en forme locale), `blank` (complétion des champs vides, par défaut) et `all` (synchronisation complète).
Contrairement aux expressions régulières aveugles, BibGenie comprend le contexte scientifique et préserve la casse de termes tels que `mRNA`, `CRISPR-Cas9` ou `PyTorch`.
Mise en évidence avant/après, avertissements lors du changement de type de document, préservation des clés Better BibTeX et rollback atomique.
## Sources de données académiques prises en charge [#sources-de-données-académiques-prises-en-charge]
BibGenie intègre des canaux de recherche académique spécialisés par discipline et stade de publication :
| Source | Couverture et spécificités | Idéal pour |
| :--------------------- | :------------------------------------------------------------- | :-------------------------------------------------------------------------------------------- |
| **OpenAlex** | Plus de 250 millions d'entités scientifiques ouvertes | Recherche interdisciplinaire, complétion des métadonnées de base, contextes de citation |
| **arXiv** | Référentiel de prépublications (physique, informatique, maths) | Métadonnées de preprints, identification des versions officielles, liens vers DOI publiés |
| **DBLP** | Bibliographie d'informatique de référence | Conférences et revues majeures en informatique, désambiguïsation d'auteurs |
| **OpenReview** | Conférences de premier plan en IA et ML (ICLR, NeurIPS, etc.) | Vérification des pistes de soumission, protection des auteurs anonymes, versions camera-ready |
| **Semantic Scholar** | Corpus de haute précision en informatique et biomédecine | Résolution exacte des identifiants, résumés TLDR, analyse des citations |
| **Zotero Translators** | Traducteurs web et éditeurs intégrés de Zotero | Résolution directe depuis les portails d'éditeurs (IEEE, ACM, Springer, Nature) |
## Trois modes d'examen [#trois-modes-dexamen]
Selon votre objectif d'organisation, vous pouvez exécuter BibGenie sous trois modes distincts :
**Mode par défaut**. Interroge les bases académiques et **ne propose de mises à jour que pour les champs locaux et créateurs vides** :
* Conserve intacts les titres, auteurs, années et noms de revues déjà présents.
* Renseigne les résumés (Abstract), paginations (Pages), DOI, titres de revue ou actes de colloque manquants.
* Idéal pour la quasi-totalité des travaux d'enrichissement réguliers.
**Mode de normalisation locale**. Ignore la recherche de faits externes et applique des règles typographiques éprouvées :
* Casse de phrase (Sentence Case) pour les titres.
* Abréviations de revues normalisées selon le standard LTWA.
* Détection précise du code de langue (ISO-639-1).
* Détection des noms de domaine d'éditeurs mal placés dans les champs de métadonnées.
* Idéal lorsque les métadonnées sont complètes et qu'une harmonisation typographique suffit.
**Mode de synchronisation complète**. Interroge les sources externes et **compare les valeurs existantes pour proposer des mises à jour, avec remplacement possible de la liste d'auteurs** :
* Adapté à la correction d'entrées corrompues ou imprécises issues de scraping web médiocre.
* Idéal pour actualiser une prépublication après son acceptation formelle en conférence ou en revue et adapter son type d'élément.
* *Remarque : n'utilisez pas `all` pour de simples champs manquants ; privilégiez le mode `blank`.*
## Sécurité et préservation de l'écosystème [#sécurité-et-préservation-de-lécosystème]
1. **Compatibilité totale avec Better BibTeX** :
* De nombreux chercheurs s'appuient sur Better BibTeX pour la gestion des clés LaTeX. Le processeur du champ Extra de BibGenie préserve rigoureusement `Citation Key:`, `tex.*`, `bibtex:` et les notes libres sans jamais les altérer.
2. **Précautions lors du changement de type de document** :
* Lorsqu'une conversion de type est proposée (ex. de `preprint` vers `journalArticle`), la carte d'approbation signale clairement les champs susceptibles d'être réaffectés ou omis.
3. **Intelligence académique contextuelle** :
* Les corrections aveugles altèrent souvent les acronymes ou termes techniques. BibGenie s'appuie sur le contexte du modèle pour préserver les orthographes scientifiques rigoureuses.
## Exemples d'invites (Prompts) [#exemples-dinvites-prompts]
```text
Examine l'article actuellement sélectionné et utilise le mode blank pour compléter son résumé, sa pagination et son DOI.
```
```text
Normalise la casse du titre et les abréviations de revue des documents sélectionnés, tout en conservant intacts les termes techniques.
```
```text
Cet article était auparavant une prépublication arXiv. Vérifie via DBLP ou Semantic Scholar s'il a été publié dans une revue ou conférence officielle, et propose la mise à jour correspondante.
```
```text
Parcours cette collection pour identifier les documents dépourvus de résumé ou de DOI, puis effectue une révision par lot pour les enrichir.
```
## Déroulement recommandé [#déroulement-recommandé]
**Sélectionner les éléments** : Choisissez un ou plusieurs documents dans Zotero, intégrez-les avec `@` dans la discussion ou formulez directement votre demande.
**Examen en lecture seule par l'IA** : BibGenie interroge les bases académiques et vérifie les règles pour générer des propositions structurées.
**Consulter la carte de comparaison visuelle** : Une **Action Preview** met en relief les différences avant/après avec un code couleur précis.
**Approuver et enregistrer** : Cliquez sur « Approuver » pour appliquer les modifications de manière atomique dans Zotero. En cas de refus, votre bibliothèque reste inchangée.
# Modèles (/fr/docs/models)
BibGenie prend en charge deux types de modèles : les **modèles officiels** et les **modèles personnalisés**.
* Les modèles officiels sont maintenus par BibGenie et fonctionnent immédiatement. Vous n'avez pas besoin de configurer votre propre clé API.
* Les modèles personnalisés sont configurés par vous, avec le fournisseur, la Base URL, la clé API et les capacités du modèle.
Vous pouvez gérer les deux depuis **Model Settings**.
## Modèles officiels [#modèles-officiels]
Il existe de nombreux modèles IA sur le marché, mais seule une petite partie fonctionne bien comme agent Zotero. BibGenie ne choisit pas les modèles uniquement selon des benchmarks publics. Nous cherchons surtout à savoir s'ils gèrent de façon fiable de vrais flux de recherche :
* Lecture d'articles avec long contexte
* Comparaison de plusieurs articles
* Raisonnement de recherche complexe
* Appels d'outils et sortie structurée
* Entrées multimodales comme figures, formules et captures d'écran
* Réponses exactes ancrées dans le contexte Zotero
La configuration du fournisseur compte aussi. Le même modèle peut se comporter très différemment selon les fournisseurs, à cause des limites de contexte, de la prise en charge des appels d'outils, des limites de débit, des paramètres par défaut et de la fiabilité réseau.
Pour réduire le travail de configuration, BibGenie fait plusieurs choses :
Nous testons une sélection de modèles sur des flux de lecture d'articles, de recherche bibliographique, de gestion de bibliothèque et de prise de notes.
Lorsque c'est possible, nous discutons des modes de déploiement et d'utilisation recommandés avec les équipes modèle ou fournisseur.
Nous travaillons avec certains fournisseurs pour que les modèles soient servis d'une façon adaptée à BibGenie.
Nous évaluons les combinaisons modèle-fournisseur et maintenons une liste de recommandations.
## Modèles personnalisés [#modèles-personnalisés]
Si vous avez votre propre clé API ou souhaitez utiliser un modèle local, vous pouvez ajouter un modèle personnalisé.
Les modèles personnalisés sont utiles lorsque :
* Vous payez déjà un fournisseur comme OpenAI, Anthropic, DeepSeek ou OpenRouter.
* Votre institution exige que les requêtes soient envoyées directement à un fournisseur précis.
* Vous souhaitez utiliser Ollama ou LM Studio localement.
* Vous avez besoin d'un modèle qui n'est pas encore inclus dans la liste officielle.
Consultez [Modèles personnalisés](/docs/custom-models) pour les instructions de configuration.
## Que signifient les multiplicateurs ? [#que-signifient-les-multiplicateurs-]
Vous pouvez voir des labels comme `0x`, `1.5x` ou `2x` après un nom de modèle.
Ces labels indiquent la vitesse approximative à laquelle le modèle peut consommer des crédits :
| Label | Signification |
| :----------- | :----------------------------------------------------------------------------------------- |
| `1x` | Vitesse de consommation standard. |
| `1.5x` | Peut consommer des crédits plus rapidement qu'un modèle standard pour une tâche similaire. |
| `2x` ou plus | Indique généralement un modèle plus coûteux, à réserver aux tâches plus exigeantes. |
Les multiplicateurs sont affichés comme indication pour l'utilisateur. La consommation réelle est calculée à partir des tokens d'entrée, des tokens de sortie, du prix du modèle et de l'utilisation des outils.
## Actualiser la liste des modèles [#actualiser-la-liste-des-modèles]
La liste officielle des modèles s'actualise automatiquement. Vous pouvez aussi l'actualiser manuellement :
Ouvrez BibGenie.
Allez dans **Model Settings**.
Cliquez sur **Refresh** dans la section des modèles officiels.
Si un modèle manque, les raisons possibles sont :
* Votre version du plugin est obsolète.
* La liste des modèles n'a pas encore été actualisée.
* Le modèle est temporairement indisponible ou en cours d'ajustement.
* Le statut de votre compte n'a pas encore été synchronisé.
## Choisir un modèle [#choisir-un-modèle]
Commencez avec un modèle officiel à faible multiplicateur.
Utilisez un modèle officiel avec une gestion fiable du contexte et une forte qualité de sortie.
Utilisez un modèle doté d'un meilleur raisonnement et d'une fenêtre de contexte plus longue.
Utilisez BYOK, un fournisseur personnalisé, Ollama ou LM Studio.
# Recherche académique OpenAlex (/fr/docs/openalex-research)
OpenAlex Research est disponible dans BibGenie v0.7.0 et vous aide à explorer le catalogue scientifique public au-delà de votre bibliothèque Zotero. Utilisez-le pour découvrir de nouveaux articles, trouver des auteurs ou institutions, analyser des tendances de recherche ou cartographier les citations autour d'un travail connu.
Les résultats OpenAlex sont des métadonnées bibliographiques externes. Ils ne signifient pas qu'un article est déjà enregistré dans votre bibliothèque Zotero et ne remplacent pas la lecture de l'article lui-même.
OpenAlex Search est accessible à tous les utilisateurs. Avec Free, chaque appel d'outil OpenAlex réussi coûte **1 crédit** ; les offres payantes incluent ces appels **sans crédit supplémentaire**.
## Ce que vous pouvez faire [#ce-que-vous-pouvez-faire]
Recherchez dans les enregistrements scientifiques publics par sujet, expression exacte, DOI, PMID, PMCID, OpenAlex ID, et filtres ou champs de tri pris en charge.
Trouvez des identifiants OpenAlex stables pour les auteurs, institutions, revues, sujets, éditeurs et financeurs.
Trouvez les articles qui citent un article source, les articles référencés par un article source, ou les travaux connexes.
Regroupez et comptez les résultats par année de publication, statut d'accès ouvert, pays, source, sujet ou autre champ pris en charge.
## Quand utiliser OpenAlex [#quand-utiliser-openalex]
Utilisez OpenAlex lorsque votre question porte sur des enregistrements scientifiques publics en dehors de votre bibliothèque Zotero actuelle :
* Trouvez des articles récents sur un sujet de recherche.
* Découvrez des travaux antérieurs influents ou des articles de synthèse.
* Suivez les citations autour d'un DOI ou d'un identifiant OpenAlex.
* Échantillonnez aléatoirement des enregistrements correspondants pour une couverture exploratoire plutôt qu'un simple classement par pertinence ou nombre de citations.
* Comparez l'activité de publication par année, source, institution, pays, sujet ou organisme de financement.
* Identifiez des auteurs, revues, institutions, éditeurs ou financeurs avant de filtrer les articles par ceux-ci.
Utilisez plutôt la recherche dans la bibliothèque Zotero lorsque vous interrogez des éléments enregistrés, des articles sélectionnés, des collections, des tags, des notes ou des PDF attachés.
OpenAlex peut identifier des articles dignes d'intérêt, mais ne les ajoute pas automatiquement à Zotero. Demandez explicitement à BibGenie avant d'importer, taguer, déplacer ou modifier des éléments Zotero.
## Comment demander [#comment-demander]
```text
Recherche dans OpenAlex les articles de synthèse récents sur le Retrieval Augmented Generation après 2023. Retourne le titre, l'année, la source, les auteurs, le nombre de citations, le DOI et pourquoi chaque résultat peut être utile.
```
```text
Utilise OpenAlex pour trouver les articles de Geoffrey Hinton sur le Deep Learning. Résous d'abord l'auteur, puis liste les œuvres les plus citées avec l'année, la source, le DOI et le nombre de citations.
```
```text
Utilise OpenAlex pour explorer les articles qui citent 10.48550/arXiv.1706.03762. Concentre-toi sur les articles après 2021 et explique lesquels semblent les plus pertinents pour la recherche sur les LLM.
```
```text
Utilise OpenAlex pour analyser les tendances de publication des Graph Neural Networks de 2018 à 2025. Regroupe par année de publication et résume soigneusement la tendance.
```
## Flux de travail recommandé [#flux-de-travail-recommandé]
Commencez par une recherche OpenAlex large avec un petit nombre de résultats.
Demandez à BibGenie d'affiner par année, type de travail, statut d'accès ouvert, source, auteur, institution ou sujet.
Pour un article source prometteur, demandez les voisins de citation, références ou travaux connexes.
N'ajoutez que les candidats les plus pertinents à Zotero après avoir examiné les résultats.
## Exemples de prompts [#exemples-de-prompts]
```text
Recherche dans OpenAlex des articles sur les outils d'IA dans l'écriture académique. Privilégie les articles de synthèse après 2020 et retourne au maximum 10 résultats.
```
```text
Trouve l'enregistrement OpenAlex pour ce DOI, puis montre ses articles citants et ses travaux connexes :
10.1038/nature12373
```
```text
Résous Stanford University dans OpenAlex, puis trouve les travaux très cités sur l'interaction homme-machine de cette institution depuis 2020.
```
```text
Recherche d'abord dans ma bibliothèque Zotero les articles sur les agents LLM, puis utilise OpenAlex pour trouver les articles externes qui pourraient m'échapper. Garde les résultats Zotero et les résultats OpenAlex externes séparés.
```
## Limites importantes [#limites-importantes]
* OpenAlex fournit des métadonnées telles que titre, auteurs, année, source, DOI, statut d'accès ouvert et nombre de citations.
* Ne considérez pas le nombre de citations comme une preuve de qualité.
* Ne déduisez pas les méthodes, affirmations ou résultats d'un article à partir des seules métadonnées.
* Pour une lecture approfondie, ajoutez l'article à Zotero ou fournissez le texte intégral lisible, puis demandez à BibGenie de lire le contenu source.
# Citations au niveau du paragraphe (/fr/docs/paragraph-citations)
Dans la lecture d'articles, une réponse qui « semble correcte » ne suffit pas. Un véritable assistant de lecture IA fiable doit pouvoir répondre à une question plus exigeante :
**D'où vient exactement cette affirmation dans l'article ?**
Les citations au niveau du paragraphe de BibGenie sont conçues pour cela. Elles relient les conclusions importantes d'une réponse IA à des blocs de texte précis dans le PDF : vous cliquez sur un marqueur de citation dans la réponse, et vous revenez directement au Zotero PDF Reader, à l'endroit correspondant, avec le passage source surligné.
Ce n'est pas une façon de rendre la réponse plus « académique » en apparence. Sa valeur essentielle est ailleurs : chaque jugement important produit par l'IA peut être revérifié, relu et confirmé par vous-même.
Les citations au niveau du paragraphe font passer la réponse IA de « voici la conclusion » à « voici la preuve » : cliquez sur un marqueur de citation pour revenir directement au paragraphe correspondant dans le PDF.
## En quoi diffèrent-elles des citations classiques ? [#en-quoi-diffèrent-elles-des-citations-classiques-]
Toutes les citations ne donnent pas le même niveau de précision, et elles ne permettent donc pas les mêmes vérifications :
| Granularité | Ce que vous pouvez savoir | Cas d'usage | Suffisant pour une lecture approfondie ? |
| :----------------------------------- | :---------------------------------------------------- | :------------------------------------------------------------------------------------ | :-------------------------------------------------------- |
| Citation au niveau de l'article | De quel article vient globalement la réponse | Survol, bibliographie, compréhension rapide du contexte | Trop large : vous connaissez seulement la source |
| Citation au niveau de la page | De quelle page du PDF vient globalement la réponse | Repérer rapidement le contenu d'une page | Encore trop large : une page contient trop d'informations |
| **Citation au niveau du paragraphe** | **Quel bloc de texte source correspond à la réponse** | **Lecture approfondie, vérification des faits, prise de notes, revue de littérature** | **Vous pouvez vérifier directement la preuve** |
La citation au niveau de l'article indique la source, la citation au niveau de la page vous aide à trouver la page, et **la citation au niveau du paragraphe vous permet de vérifier directement la preuve**.
BibGenie ne cherche pas seulement à vous dire « cet article appuie cette réponse ». Il vous permet de voir de vos propres yeux « ce passage de l'article appuie cette réponse ». Pour un chercheur, la seconde formulation compte beaucoup plus que la première : vous n'avez pas seulement besoin d'une conclusion toute faite, mais d'un moyen de juger si cette conclusion tient vraiment.
## De la réponse à la preuve [#de-la-réponse-à-la-preuve]
Pendant longtemps, lire un article avec l'IA revenait surtout à demander : « résume-moi cet article ».
C'est utile, bien sûr : vous pouvez comprendre rapidement le contenu général, la méthode et les conclusions d'un article. Mais dans un travail bibliographique sérieux, ce qui prend vraiment du temps n'est pas de « comprendre en gros ». Ce sont plutôt ces vérifications :
* Les auteurs formulent-ils vraiment cette conclusion ?
* L'IA a-t-elle trop fusionné le sens de plusieurs paragraphes ?
* Les détails sur les résultats expérimentaux, les définitions de variables ou les métriques d'évaluation sont-ils exacts ?
* Cette phrase est-elle une affirmation centrale des auteurs, ou une synthèse produite par l'IA ?
* Cette idée peut-elle être reprise sans risque dans vos notes, votre revue ou un brouillon d'article ?
Si l'IA vous donne seulement une réponse fluide, vous devez quand même retourner dans le PDF, chercher, feuilleter, localiser, relire. Ce processus interrompt le raisonnement et peut même vous pousser à renoncer à la vérification.
Les citations au niveau du paragraphe suppriment cette étape.
Quand BibGenie répond à partir du texte d'un PDF, la réponse inclut automatiquement des marqueurs de citation comme `[1]` et `[2]`. Cliquez sur un marqueur : BibGenie ouvre le PDF correspondant, va à la page pertinente et surligne dans le texte original le paragraphe cité.
Autrement dit, BibGenie ne vous dit pas seulement « quelle est la réponse » : il replace directement « d'où vient la réponse » dans votre espace de lecture.
## Pourquoi c'est important [#pourquoi-cest-important]
La lecture académique n'est pas la lecture d'un fil d'actualité. Vous ne cherchez pas seulement une conclusion ; vous devez aussi comprendre comment cette conclusion est soutenue par l'article.
C'est aussi pour cela que de plus en plus de recherches et de produits IA insistent sur la traçabilité des sources (source attribution), les réponses fondées sur des preuves (grounded answers) et la vérification des citations (citation verification). L'IA peut générer des explications qui semblent vraies, comme elle peut générer des citations qui semblent vraies. Mais « sembler vrai » ne signifie pas « résister à la vérification ».
Dans un contexte bibliographique, une citation fiable doit satisfaire trois conditions :
1. **Source réelle** : la citation ne doit pas être une référence inventée.
2. **Position précise** : la citation ne doit pas seulement pointer vers un article entier ; elle doit indiquer l'emplacement concret de la preuve.
3. **Contenu correspondant** : le texte cité doit réellement soutenir ce que l'IA vient d'affirmer.
Vous devez souvent juger :
* Les auteurs ont-ils vraiment dit cela ?
* L'IA a-t-elle mélangé plusieurs paragraphes, plusieurs expériences, voire plusieurs articles ?
* Les détails de méthode viennent-ils du corps du texte, d'une légende de figure, d'une annexe ou d'une reformulation de l'IA ?
* Cette phrase peut-elle être reprise dans vos notes ou dans un brouillon d'article ?
* Cette citation est-elle seulement « proche du sujet », ou soutient-elle vraiment l'affirmation précise de la réponse ?
Les citations IA classiques indiquent souvent seulement « quel article a été consulté » ou « de quelle page cela vient ». C'est suffisant pour un survol, mais largement insuffisant pour une lecture approfondie : une seule page de PDF peut contenir en même temps la question de recherche, la méthode, des formules, le protocole expérimental, l'interprétation des résultats et les limites. La citation au niveau de la page vous dit seulement « c'est à peu près ici ». La citation au niveau du paragraphe réduit la zone de preuve à l'endroit que vous avez réellement besoin de vérifier.
## Pourquoi ne pas donner seulement le numéro de page ? [#pourquoi-ne-pas-donner-seulement-le-numéro-de-page-]
Beaucoup d'outils IA pour la littérature fournissent des numéros de page. Les numéros de page sont utiles, mais ce n'est pas le point d'arrivée.
Une page de PDF académique est très dense. C'est particulièrement vrai pour les articles en deux colonnes, les revues de littérature, les articles de méthodologie ou les articles expérimentaux en médecine et en ingénierie. Une seule page peut contenir :
* deux ou trois paragraphes distincts ;
* un tableau ou une légende de figure ;
* plusieurs formules ;
* un protocole expérimental, des métriques d'évaluation et une interprétation des résultats ;
* des précisions des auteurs sur les limites.
Si l'IA affirme que « les auteurs estiment que la méthode améliore la généralisation » et vous indique seulement « voir page 6 », vous devez encore déterminer si elle renvoie au paragraphe sur les résultats, à une ablation, ou à l'interprétation dans la discussion.
La citation au niveau du paragraphe ne remplace pas le numéro de page. Elle va plus loin : elle vous montre directement le petit bloc de preuve cité par l'IA. Elle est particulièrement adaptée aux cas où une même page contient plusieurs preuves possibles.
## Pourquoi ne pas être encore plus précis ? [#pourquoi-ne-pas-être-encore-plus-précis-]
Vous pourriez penser que plus une citation est précise, mieux c'est : idéalement, chaque phrase ou chaque affirmation devrait pouvoir être localisée. Mais dans une lecture réelle d'article, la preuve est rarement une phrase isolée. Les auteurs définissent souvent d'abord un concept, décrivent ensuite le protocole, puis interprètent le résultat dans la phrase suivante. Extraire une seule phrase peut au contraire faire perdre le contexte nécessaire.
La citation au niveau du paragraphe est un compromis naturel :
* plus précise que l'article entier ;
* plus facile à vérifier qu'une page entière de PDF ;
* plus riche en contexte qu'une citation d'une seule phrase ;
* moins bruyante qu'une citation sur plusieurs paragraphes.
Cela correspond aussi à la manière dont les chercheurs lisent réellement les articles : vous ne fixez pas une seule phrase, vous lisez un petit passage, vous comprenez les conditions et les nuances autour, puis vous décidez s'il soutient un point donné.
## Ce que cela vous permet de faire [#ce-que-cela-vous-permet-de-faire]
Cliquez sur un marqueur de citation dans la réponse pour revenir directement à l'emplacement source dans le Zotero PDF Reader, sans feuilleter manuellement, chercher des mots-clés ou deviner quel passage l'IA a utilisé.
Quand l'IA résume une méthode, des résultats ou des limites, vous pouvez immédiatement vérifier le texte original et juger si l'IA reste fidèle au sens de l'article.
Pour les définitions théoriques, protocoles expérimentaux, explications de variables, conclusions de figures ou tableaux et nuances formulées par les auteurs, la citation au niveau du paragraphe correspond mieux au geste réel de vérification qu'un simple numéro de page.
La réponse, les marqueurs de citation, la page PDF et le surlignage du texte source restent reliés, afin que vos questions de suivi, vos notes et vos jugements aient une origine claire et vérifiable.
## Cas d'usage typiques [#cas-dusage-typiques]
Pendant la lecture attentive d'un article, vous pouvez demander à BibGenie de structurer la question de recherche, la méthode, le protocole expérimental, les principaux résultats et les limites. Auparavant, vous obteniez peut-être un résumé complet, mais vous deviez encore retrouver chaque preuve. Désormais, la réponse contient des citations cliquables, et vous pouvez revenir au texte source point par point.
```text
Lisez attentivement cet article et résumez-le selon : question, méthode, expérience, principaux résultats, limites.
```
L'IA sait transformer un contenu complexe en formulation fluide, mais cette fluidité peut masquer des problèmes. Par exemple, si l'article dit seulement « les performances sont meilleures sur tel jeu de données », l'IA peut résumer par « cette méthode surpasse globalement les méthodes existantes » ; si l'article dit seulement « les auteurs observent une tendance », l'IA peut écrire « les auteurs démontrent un mécanisme ». Les citations au niveau du paragraphe vous permettent de revenir rapidement au texte original pour vérifier si la formulation de l'IA dépasse l'intention des auteurs.
```text
Listez les 5 conclusions de cet article les plus susceptibles d'être mal interprétées ou trop généralisées.
```
De bonnes notes bibliographiques ne consignent pas seulement « ce que dit cet article », mais aussi « pourquoi je le comprends ainsi ». Les citations au niveau du paragraphe vous aident à relier les notes structurées produites par l'IA aux preuves du texte original. Plus tard, en relisant vos notes, vous pouvez revenir à tout moment au paragraphe PDF qui les soutenait, sans rechercher à nouveau dans tout l'article.
```text
Transformez cet article en brouillon de note Zotero, en gardant surtout la question de recherche, la méthode, les résultats et les limites.
```
Dans une revue de littérature, deux risques sont particulièrement coûteux : des citations imprécises et une origine des idées mal établie. Lorsque vous comparez plusieurs articles, les citations au niveau du paragraphe donnent une source à chaque point de comparaison : comment l'article A définit le problème, quel jeu de données l'article B utilise, quelles limites l'article C reconnaît. Chaque point peut vous ramener au texte source, ce qui aide à distinguer clairement « ce que les auteurs disent », « ce que l'IA synthétise » et « votre propre jugement ».
```text
Comparez ces articles selon leurs questions de recherche, hypothèses méthodologiques, protocoles expérimentaux et limites.
```
Les méthodes et détails expérimentaux ne supportent pas l'approximation. Taille des jeux de données, méthodes de référence, métriques d'évaluation, hyperparamètres, critères d'exclusion, tests statistiques, ablations : une seule erreur de lecture peut fausser toute la compréhension qui suit. Les citations au niveau du paragraphe vous permettent d'aller vite aux passages où se trouvent ces détails et de vérifier si l'IA a omis des conditions importantes.
```text
Extrayez le protocole expérimental de cet article, notamment les jeux de données, méthodes de référence, métriques d'évaluation et principaux résultats comparatifs.
```
## Fonctionnement [#fonctionnement]
Quand BibGenie lit un PDF, il découpe les pages en blocs de texte structurés. Chaque bloc conserve le numéro de page, l'ordre de lecture et les informations de position sur la page.
Quand l'IA cite un bloc de texte dans sa réponse, BibGenie l'affiche sous forme de marqueur comme `[1]` ou `[2]`. Après un clic sur le marqueur, BibGenie :
1. ouvre le PDF Zotero correspondant ;
2. va à la page où se trouve la citation ;
3. surligne dans le texte original le paragraphe ou bloc de texte cité.
Vous ne voyez pas seulement « cet article soutient cette réponse », mais « ce passage de l'article soutient cette réponse ».
## Un flux de lecture approfondie fondé sur les preuves [#un-flux-de-lecture-approfondie-fondé-sur-les-preuves]
Les citations au niveau du paragraphe vous aident à installer une habitude de lecture IA « vérifiable » :
**Ajoutez le contexte PDF** : ajoutez la pièce jointe PDF Zotero à la conversation BibGenie, ou posez directement une question sur le PDF que vous êtes en train de lire.
**Posez une question de lecture** : demandez par exemple à BibGenie de résumer la méthode, d'expliquer le protocole expérimental, de dégager les limites ou de comparer plusieurs articles.
**Parcourez la structure de la réponse** : commencez par regarder l'organisation générale produite par l'IA et vérifiez si elle saisit le fil principal de l'article.
**Cliquez sur les citations pour vérifier le texte source** : pour les conclusions que vous envisagez de retenir, cliquez sur les marqueurs de citation afin de revenir au PDF Zotero et de vérifier si le passage surligné soutient vraiment la conclusion.
**Poursuivez ou corrigez** : si vous repérez une généralisation excessive ou l'oubli d'une condition, posez une question de suivi comme « reformule à partir de ce passage original ».
L'objectif de ce flux n'est pas de laisser l'IA lire l'article à votre place, mais de vous aider à entrer plus vite dans une lecture approfondie vérifiable.
## Limites et points d'attention [#limites-et-points-dattention]
Les citations au niveau du paragraphe améliorent nettement la traçabilité, mais elles ne sont pas une magie qui garantit automatiquement l'exactitude. Gardez ces points en tête :
* **Une position de citation pertinente ne garantit pas que l'interprétation de l'IA soit correcte** : l'IA peut avoir trouvé un paragraphe lié au sujet, tout en l'interprétant de travers.
* **Le surlignage sert à localiser, pas à produire le format final de citation** : pour une rédaction formelle, appliquez toujours le style demandé, par exemple APA, MLA, Chicago, GB/T 7714 ou les consignes de la revue cible.
* **La qualité de la couche texte du PDF influence le résultat** : fichiers scannés, OCR médiocre, mise en page complexe ou pages très riches en formules peuvent affecter l'analyse des blocs de texte et la précision du repérage.
* **Les figures et formules demandent une lecture visuelle** : si votre question dépend d'une figure, d'une page scannée ou de la mise en page, ajoutez aussi une capture ou une image de la page.
* **L'IA ne remplace pas votre jugement académique** : les citations au niveau du paragraphe rendent la vérification plus pratique, mais votre décision finale doit s'appuyer sur le texte original, le design de recherche et votre compréhension experte.
Laissez BibGenie réduire la zone à vérifier, puis décidez vous-même si ce passage original soutient réellement une conclusion.
## Conseils d'utilisation [#conseils-dutilisation]
* Pour les conclusions importantes, données, protocoles expérimentaux et positions des auteurs, prenez l'habitude de cliquer sur les citations pour vérifier le texte source.
* Si la formulation de l'IA est trop générale, demandez : « reformule à partir du texte original cité ».
* Avec un PDF scanné ou une couche texte de mauvaise qualité, le repérage des citations peut être moins précis ; ajoutez aussi une image de la page si nécessaire.
* Pour une rédaction formelle, considérez les réponses IA comme une aide à la lecture, et le texte original de l'article comme l'autorité finale.
* Pour comparer plusieurs articles, vérifiez d'abord les preuves de chaque article séparément, puis examinez la synthèse de BibGenie.
* Lorsque vous rencontrez un terme inconnu, cliquez d'abord sur la citation pour lire le passage original, puis demandez à BibGenie d'expliquer le contexte.
* Quand une réponse porte sur une relation causale, une explication de mécanisme ou une conclusion statistique, revenez impérativement au paragraphe cité pour confirmer que les auteurs l'expriment bien ainsi.
Les marqueurs de citation dans les réponses IA peuvent facilement être pris pour des « badges de fiabilité ». Quand on voit `[1]` ou `[2]`, on a naturellement tendance à penser que l'affirmation est déjà vérifiable.
Mais l'habitude la plus utile consiste à traiter la citation comme une porte d'entrée.
Ouvrez-la, revenez au texte original et confirmez trois choses :
1. Le texte original discute-t-il vraiment de cette question ?
2. Quel est le ton du texte original : conclusion forte, observation prudente ou hypothèse ?
3. Le résumé de l'IA omet-il une condition, une portée ou un contre-exemple ?
Cette étape ne prend souvent que quelques secondes, mais elle réduit fortement le risque de « l'avoir lu sans l'avoir vérifié ». C'est particulièrement important lorsque vous rédigez une revue de littérature, préparez une présentation de recherche ou organisez des hypothèses : cette vérification influence directement la fiabilité du travail qui suit.
# Tarifs & crédits (/fr/docs/pricing-credits)
BibGenie utilise des crédits pour mesurer l'utilisation des modèles officiels. Les crédits ne correspondent pas au nombre de requêtes : le coût d'une requête dépend du modèle, de la longueur du contexte, de la longueur de la sortie et de l'utilisation des outils.
Toutes les offres permettent d'utiliser OpenAlex, Web Search et Web Extract. Avec Free, chaque appel d'outil externe réussi coûte 1 crédit ; les offres payantes incluent ces appels sans crédit supplémentaire et davantage de crédits mensuels. Max offre le plus grand nombre de crédits mensuels pour les flux intensifs de lecture, comparaison et revue.
## Comparaison des offres [#comparaison-des-offres]
| Offre | Prix | Crédits mensuels | Capacités principales |
| :---------- | :---------------------- | :-------------------- | :--------------------------------------------------------------------------------------------------------------------- |
| Free | $0 | 200 crédits / mois | Fonctions de base + OpenAlex, Web Search et Web Extract à 1 crédit par appel réussi |
| Pro Monthly | $9.99 / mois | 10 000 crédits / mois | Tout ce qui est inclus dans Free + aucun crédit supplémentaire pour les appels externes |
| Pro Yearly | $99 / an | 10 000 crédits / mois | Tout ce qui est inclus dans Pro Monthly |
| Max Monthly | $30 / mois | 35 000 crédits / mois | Tout ce qui est inclus dans Pro + plus de marge pour la lecture approfondie, la comparaison et la génération de revues |
| Max Yearly | $295 / an | 35 000 crédits / mois | Tout ce qui est inclus dans Max Monthly |
| Lifetime | Paiement unique de $199 | 10 000 crédits / mois | Avantages Pro à long terme |
Les prix, remises et promotions peuvent changer. Le prix final est celui affiché sur la page Pricing et dans Stripe Checkout.
## Credit Booster [#credit-booster]
Les utilisateurs gratuits et payants peuvent acheter un paquet de crédits supplémentaire :
| Paquet | Quantité | Prix | Expiration |
| :------ | :------------ | :---- | :--------- |
| Booster | 5 000 crédits | $6.99 | 6 mois |
## Comment les crédits sont consommés [#comment-les-crédits-sont-consommés]
La consommation de crédits dépend principalement de :
* Choix du modèle : les modèles plus coûteux consomment généralement les crédits plus vite.
* Longueur d'entrée : PDF, notes, instantanés, images et historique de chat augmentent les tokens d'entrée.
* Longueur de sortie : longues revues, longs tableaux et notes complètes utilisent plus de tokens.
* Utilisation des outils : recherche, lecture de pièces jointes, recherche web et extraction web peuvent impliquer plusieurs appels modèle.
* **Outils externes** : avec Free, chaque appel OpenAlex, Web Search ou Web Extract réussi coûte **1 crédit**. Les offres payantes incluent ces appels **sans crédit supplémentaire**. L'utilisation du modèle dans la conversation est mesurée séparément.
* Multiplicateur du modèle : des labels comme `1.5x` ou `2x` donnent une indication approximative.
Les modèles personnalisés, Ollama et LM Studio n'utilisent pas le service de modèles officiel de BibGenie et ne consomment donc pas de crédits BibGenie. Les coûts ou calculs éventuels sont gérés par votre fournisseur ou votre machine locale.
## Combien de crédits faut-il pour lire un article ? [#combien-de-crédits-faut-il-pour-lire-un-article-]
Il n’existe pas de montant fixe. La consommation dépend du modèle choisi, du contexte d’entrée, de la longueur de sortie et du tarif actuel du modèle. Consultez la page Usage pour connaître le débit exact enregistré pour chaque requête.
## Que se passe-t-il lorsque les crédits sont épuisés ? [#que-se-passe-t-il-lorsque-les-crédits-sont-épuisés-]
Si votre solde de crédits est insuffisant, les requêtes vers les modèles officiels peuvent ne pas continuer. Vous pouvez :
* Attendre le prochain renouvellement mensuel.
* Passer à Pro, Max ou Lifetime.
* Acheter un Credit Booster.
* Utiliser BYOK ou un modèle local.
## Vérifier votre solde [#vérifier-votre-solde]
Après connexion, BibGenie synchronise le statut de votre compte et votre solde de crédits. Vous pouvez aussi consulter votre solde dans l'espace compte du site web ou sur la page utilisateur du plugin.
# Prompts rapides (/fr/docs/quick-prompts)
Les Quick Prompts sont des raccourcis réutilisables pour les tâches de recherche récurrentes. Enregistrez les prompts que vous utilisez souvent, insérez-les rapidement dans le champ de saisie et adaptez-les au contexte actuel.
## À quoi servent les Quick Prompts ? [#à-quoi-servent-les-quick-prompts-]
Résumer questions de recherche, méthodes, contributions, limites et travaux futurs.
Traduire du texte sélectionné, améliorer des paragraphes en anglais ou ajuster le ton académique.
Extraire des affirmations, générer des tableaux de comparaison et organiser les travaux associés.
Analyser les hypothèses, faiblesses méthodologiques, force des preuves et reproductibilité.
## Créer un Quick Prompt [#créer-un-quick-prompt]
Ouvrez BibGenie et allez dans **Prompts Settings**.
Cliquez sur le bouton d'ajout pour créer un nouveau quick prompt.
Saisissez un nom, le contenu du prompt, une description et des tags.
Utilisez l'interrupteur pour contrôler s'il apparaît sur la page de chat.
Enregistrez vos paramètres et revenez au chat.
## Utiliser un Quick Prompt [#utiliser-un-quick-prompt]
Sur la page de chat, cliquez sur un Quick Prompt ou recherchez-le depuis le menu des prompts. Une fois inséré, il devient une partie de la saisie actuelle ; vous pouvez donc continuer à le modifier, ajouter du contexte ou préciser un format de sortie.
Exemple :
```text
Based on the paper I added, please use the following structure:
1. Research question
2. Method and data
3. Core findings
4. Limitations
5. How I might cite this paper
```
## Quick Prompts vs Custom Instructions [#quick-prompts-vs-custom-instructions]
| Type | Portée | Idéal pour |
| :------------------ | :-------------------------------------------- | :-------------------------------------------------------------------- |
| Quick Prompts | La saisie actuelle | Modèles de tâches comme résumé, traduction, comparaison et extraction |
| Custom Instructions | Préférences de comportement à plus long terme | Langue de réponse, ton, rôle et préférences de format |
Placez les préférences personnelles stables dans Custom Instructions et les flux de travail spécifiques à une tâche dans Quick Prompts.
## System Prompt [#system-prompt]
Le System Prompt guide le comportement global de l'IA dans toutes les conversations. Contrairement aux Quick Prompts (qui s'appliquent à la saisie actuelle), un System Prompt prend effet **globalement** — chaque conversation suit la même instruction.
Par exemple, en définissant le system prompt ainsi :
```text
Always respond in English. Use academic writing conventions appropriate for computer science.
```
chaque réponse suivra cette instruction sans que vous ayez à la répéter.
Vous pouvez définir un seul System Prompt dans **Prompts Settings**. La valeur par défaut est `Always respond in English.` Vous pouvez la modifier selon votre langue, ton, rôle ou style de formatage préféré.
## Configuration des Quick Prompts [#configuration-des-quick-prompts]
Chaque Quick Prompt possède les champs suivants :
Obligatoire. Lorsqu'il est activé, ce nom s'affiche comme bouton au-dessus de la zone de saisie.
Obligatoire. Le texte qui sera envoyé au modèle IA comme contexte.
Optionnel. Décrit l'objectif du prompt, affiché au survol.
Optionnel. Utilisé pour la catégorisation et le filtrage lors de la gestion de nombreux prompts.
## Modèles d'exemple [#modèles-dexemple]
```text
Read the paper I added and summarize it using this structure:
- Research question
- Core hypothesis
- Method and data
- Main findings
- Limitations
- Relevance to my current research
```
```text
Explain the selected text I added:
- What is the passage saying?
- What are the key concepts?
- How does it relate to the paper's main argument?
- What should I be careful about if I cite it?
```
```text
Extract material from these papers for a literature review:
- Core claim of each paper
- Agreements and disagreements between papers
- Themes that can be synthesized
- Remaining research gaps
```
# Enregistrer comme note (/fr/docs/save-as-note)
Save as Note transforme les réponses utiles de BibGenie en notes Zotero que vous pouvez conserver, rechercher et réutiliser dans votre flux de recherche.
## Deux façons d'enregistrer [#deux-façons-denregistrer]
Dites à BibGenie : "Save the summary above as a note for this paper."
Cliquez sur **Save as Note** sur le dernier message de l'assistant pour enregistrer la réponse la plus récente.
## Contenu pris en charge [#contenu-pris-en-charge]
BibGenie convertit le contenu Markdown / HTML en notes Zotero. Les contenus couramment pris en charge incluent :
* Titres et paragraphes
* Listes ordonnées et non ordonnées
* Formules mathématiques
* Blocs de code
* Tableaux
* Citations et liens
* Texte en gras et code inline
Les notes Zotero ont leur propre éditeur et leur propre prise en charge HTML. La plupart des formats courants fonctionnent bien, mais un Markdown très complexe ou du HTML personnalisé peut être simplifié.
## Logique de l'élément parent [#logique-de-lélément-parent]
Lors de l'enregistrement d'une note, BibGenie la place à l'emplacement le plus approprié qu'il peut déterminer.
| Entrée | Résultat |
| :--------------------------------------- | :------------------------------------------------------------------------------------------------------------------------ |
| Élément standard spécifié | Crée une note enfant sous cet élément |
| Pièce jointe PDF spécifiée | Trouve si possible l'élément parent standard de la pièce jointe et y attache la note |
| Note enfant spécifiée | Trouve si possible l'élément parent standard de la note enfant et y attache la note |
| Aucun parent spécifié | Crée une note autonome |
| Parent et collection tous deux spécifiés | La collection est ignorée, car les notes enfants Zotero héritent de l'appartenance aux collections de leur élément parent |
## Exemples [#exemples]
```text
Save the paper summary above as a Zotero note for this item, titled "Paper Summary".
```
```text
Turn the comparison above into a literature review note and save it to Zotero.
```
```text
Convert the method section into reproducible experimental steps and save it as a note. Preserve code blocks and tables.
```
## Conseils [#conseils]
* Demandez à BibGenie de structurer la réponse avant de l'enregistrer.
* Pour les longues conversations, demandez d'abord à BibGenie de "rewrite this as a note", puis enregistrez.
* Si la note doit appartenir à un article précis, nommez explicitement l'élément cible.
* Si vous voulez une note autonome, dites qu'elle ne doit pas être attachée à un article.
# Index sémantique (/fr/docs/semantic-index)
Semantic Index alimente la recherche bibliographique sémantique de BibGenie. Il indexe localement les titres et résumés des éléments Zotero classiques, afin que vous puissiez décrire un sujet de recherche en langage naturel plutôt que de dépendre uniquement de mots-clés.
## Que contient l'index ? [#que-contient-lindex-]
L'index sémantique se concentre actuellement sur les éléments Zotero classiques :
* Titre
* Résumé
* Certaines métadonnées utiles à la recherche
Semantic Search n'est pas équivalente à une recherche plein texte dans les PDF. Si un article n'a pas de résumé ou possède des métadonnées incomplètes, la correspondance sémantique peut être moins précise.
## Référence des statuts [#référence-des-statuts]
| Statut | Signification |
| :------------ | :----------------------------------------------------- |
| bootstrapping | La capacité d'indexation est en cours d'initialisation |
| indexing | L'index est en cours de création |
| updating | Les entrées existantes de l'index sont mises à jour |
| idle | L'index est prêt |
| error | Une erreur d'indexation est survenue |
## Métriques [#métriques]
| Métrique | Signification |
| :------------ | :------------------------------------------- |
| Indexed Count | Nombre d'éléments indexés avec succès |
| Failed Count | Nombre d'éléments dont l'indexation a échoué |
| Message | Statut actuel ou message d'erreur |
## Quand vérifier Semantic Index [#quand-vérifier-semantic-index]
* La recherche sémantique renvoie très peu de résultats.
* BibGenie indique que l'index sémantique est indisponible.
* Les articles récemment importés n'apparaissent pas dans la recherche sémantique.
* Failed Count continue d'augmenter.
* Zotero vient de démarrer et l'index est encore en phase de bootstrapping ou d'indexation.
## Dépannage [#dépannage]
Ouvrez les préférences et vérifiez le statut de Semantic Index.
S'il est en cours d'indexing ou d'updating, attendez la fin de l'opération.
Si certains éléments ont échoué, relancez l'indexation des éléments concernés.
Vérifiez que les articles pertinents disposent de titres et de résumés.
Si les échecs persistent, redémarrez Zotero puis vérifiez à nouveau.
## Conseils [#conseils]
* Des résumés complets améliorent la qualité de la recherche sémantique.
* Utilisez des descriptions en langage naturel plutôt que de simples mots-clés.
* Combinez la recherche sémantique avec des filtres par année, tag ou collection.
* Après avoir trouvé des articles candidats, ajoutez les PDF ou les notes comme contexte pour une lecture approfondie.
# Comment BibGenie comprend votre bibliothèque (/fr/docs/semantic-understanding)
## Pourquoi cette page existe [#pourquoi-cette-page-existe]
Lorsque vous recherchez dans BibGenie, l'objectif n'est pas seulement de trouver des articles contenant exactement les mêmes mots que ceux que vous avez saisis. Dans de nombreux cas, vous voulez que BibGenie trouve des articles portant sur **la même idée**, même s'ils utilisent une terminologie différente.
C'est là qu'interviennent les **embeddings** et l'**indexation**.
## Qu'est-ce qu'un embedding ? [#quest-ce-quun-embedding-]
Un embedding est une façon de transformer un morceau de texte en représentation numérique qui capture son sens.
Vous n'avez pas besoin de comprendre les mathématiques sous-jacentes. L'idée pratique est simple :
* Les textes similaires ont tendance à produire des embeddings similaires
* Les sujets différents ont tendance à produire des embeddings plus éloignés
* Cela permet à BibGenie de comparer le sens, pas seulement les mots exacts
Par exemple, un article sur *drug discovery with knowledge graphs* peut tout de même être trouvé lorsque vous recherchez *graph methods for biomedical research*, même si les formulations ne sont pas identiques.
## Comment BibGenie utilise les embeddings [#comment-bibgenie-utilise-les-embeddings]
BibGenie construit actuellement la recherche sémantique à partir du **titre** et du **résumé** de vos éléments Zotero classiques.
Le processus est le suivant :
1. BibGenie lit le titre et le résumé d'un article.
2. Il convertit ce texte en embedding.
3. Il stocke le résultat dans un index de recherche local pour votre bibliothèque Zotero.
4. Lorsque vous posez une question de type thématique, BibGenie convertit aussi votre requête en embedding.
5. Il compare votre requête aux articles indexés et renvoie les correspondances les plus proches.
C'est pourquoi la recherche sémantique peut faire remonter des articles pertinents par leur sens, et pas seulement par leur formulation.
## Qu'est-ce que l'indexation ? [#quest-ce-que-lindexation-]
L'indexation est l'étape de préparation qui rend la recherche sémantique rapide et pratique.
Au lieu de tout recalculer à chaque recherche, BibGenie prépare d'abord un index local d'embeddings pour votre bibliothèque. Une fois cet index créé, BibGenie peut chercher dans vos articles beaucoup plus efficacement.
En résumé :
* **Embedding** aide BibGenie à représenter le sens
* **Indexation** aide BibGenie à chercher rapidement dans ce sens
## À quoi cela sert-il ? [#à-quoi-cela-sert-il-]
L'indexation sémantique est particulièrement utile lorsque vous voulez :
* trouver des articles liés à un sujet de recherche ;
* découvrir des travaux qui emploient des termes différents pour une idée similaire ;
* explorer une méthode, une théorie ou un domaine problématique ;
* rechercher plus naturellement dans une grande bibliothèque Zotero.
La recherche par mots-clés reste utile lorsque vous connaissez l'auteur, le titre, le terme ou l'expression exacts. La recherche sémantique est plus utile lorsque votre question est conceptuelle.
## Quel contenu est inclus ? [#quel-contenu-est-inclus-]
BibGenie utilise actuellement :
* les titres des articles ;
* les résumés des articles.
BibGenie ne construit **pas** actuellement cet index sémantique à partir de :
* texte intégral des PDF ;
* notes ;
* annotations ;
* pièces jointes.
Cela permet de garder l'indexation ciblée, prévisible et rapide.
## Dois-je reconstruire souvent l'index ? [#dois-je-reconstruire-souvent-lindex-]
En général, **non**.
La plupart du temps, BibGenie gère automatiquement les mises à jour d'index en arrière-plan lorsque votre bibliothèque change. Si vous ajoutez des articles, modifiez des notices ou supprimez des éléments, BibGenie effectue généralement les mises à jour nécessaires.
Vous pouvez vouloir reconstruire l'index dans quelques situations :
* lors de la première configuration de l'indexation sémantique ;
* après le passage à un autre modèle d'embedding ;
* après une importation volumineuse, si les résultats semblent incomplets ou obsolètes ;
* si BibGenie indique que l'index actuel nécessite votre attention ;
* si les résultats sémantiques semblent clairement erronés et que vous voulez repartir d'une base propre.
Si la recherche sémantique fonctionne normalement, vous n'avez généralement rien à faire. Ne reconstruisez l'index que lorsque l'application le suggère ou lorsque les résultats ne correspondent plus à vos attentes.
## Que signifient les boutons de la page Indexing ? [#que-signifient-les-boutons-de-la-page-indexing-]
### Build / Rebuild [#build--rebuild]
Crée l'index pour la première fois ou le reconstruit entièrement si nécessaire.
À utiliser lorsque :
* vous configurez l'indexation pour la première fois ;
* vous avez changé de modèle d'embedding ;
* vous voulez rafraîchir l'ensemble de l'index.
### Retry Failed Items [#retry-failed-items]
Relance uniquement les articles qui ont échoué lors de précédentes tentatives d'indexation.
À utiliser lorsque :
* le nombre d'éléments en échec est supérieur à zéro ;
* vous voulez tenter une récupération légère avant une reconstruction complète.
## Questions fréquentes [#questions-fréquentes]
La recherche par mots-clés cherche des mots correspondants. La recherche sémantique cherche un sens lié. Elle peut donc renvoyer des articles pertinents même lorsque la formulation diffère.
Sans embeddings, BibGenie dépendrait surtout de termes exacts. Les embeddings rendent possible la recherche par sujet, concept et similarité sémantique.
L'article n'a peut-être pas encore été indexé, il ne contient peut-être pas assez de titre ou de résumé, ou l'index nécessite une intervention. Si le problème persiste, essayez de reconstruire l'index.
Non. En usage normal, BibGenie est conçu pour mettre l'index à jour automatiquement. La reconstruction manuelle sert surtout à la première configuration, aux changements de modèle et aux scénarios de récupération.
## Prochaines étapes [#prochaines-étapes]
* Vérifier l'état de l'index et résoudre les problèmes : [Semantic Index](/docs/semantic-index)
* Apprendre à utiliser la recherche sémantique en pratique : [Literature Search](/docs/literature-search)
# Recherche web & Web Extract (/fr/docs/web-search-extract)
Par défaut, BibGenie recherche et lit d'abord votre bibliothèque Zotero. Web Search / Web Extract sont accessibles à tous les utilisateurs et permettent de compléter votre bibliothèque avec des informations issues du web public.
Avec Free, chaque appel Web Search ou Web Extract réussi coûte **1 crédit**. Les offres payantes incluent ces appels d'outils externes **sans crédit supplémentaire**. L'utilisation du modèle dans la conversation peut toujours consommer des crédits normalement.
## Web Search vs Web Extract [#web-search-vs-web-extract]
Recherche sur le web public et renvoie des extraits classés, lisibles par l'IA.
Lit une page web spécifique et extrait son contenu principal pour la conversation.
## Quand utiliser l'accès web [#quand-utiliser-laccès-web]
Web Search / Web Extract est utile lorsque vous devez :
* Trouver la page projet, le dépôt de code ou la page de dataset d'un article.
* Rassembler des informations contextuelles récentes.
* Lire la documentation publique d'un modèle, outil, institution ou produit.
* Compléter des informations qui ne sont pas encore dans votre bibliothèque Zotero.
* Résumer, extraire ou comparer le contenu de pages web.
Le contenu web peut changer et être inexact. Pour des citations formelles, vérifiez les informations dans l'article original, la documentation officielle ou une autre source faisant autorité.
## Comment l'activer [#comment-lactiver]
Connectez-vous à votre compte BibGenie.
Repérez le bouton **Web Search** sous le champ de saisie du chat.
Cliquez sur le bouton pour activer ou désactiver la recherche web.
Une fois activée, demandez explicitement à BibGenie de rechercher sur le web ou de lire une page web.
## Exemples [#exemples]
```text
Search the web to see whether this paper has an official project page, code repository, or dataset page.
```
```text
Read this web page and summarize the parts relevant to my paper topic:
https://example.com
```
```text
First search my Zotero library, then search the web for recent developments in this area.
```
## Note de confidentialité [#note-de-confidentialité]
Les outils web accèdent à des pages publiques. Évitez d'inclure des documents sensibles, non publiés ou confidentiels dans les requêtes nécessitant un accès web. Pour un travail privé, utilisez plutôt le contexte de la bibliothèque Zotero, le contexte local, BYOK ou des modèles locaux.
# Annotations Zotero (/fr/docs/zotero-annotations)
BibGenie peut utiliser directement les annotations Zotero enregistrées : surlignages, commentaires, images, tracés et soulignements. Il peut récupérer les annotations d’une pièce jointe connue ou effectuer une recherche dans toute la bibliothèque, avec un lien traçable vers Zotero.
## Deux outils d’annotation [#deux-outils-dannotation]
| Outil | Quand l’utiliser | Portée et filtres |
| :------------------- | :------------------------------------------------- | :-------------------------------------------------------------------------------------------------------------- |
| `get_annotations` | La pièce jointe PDF, EPUB ou instantané est connue | Renvoie ses annotations dans l’ordre de lecture |
| `search_annotations` | Vous cherchez dans toute la bibliothèque | Texte surligné, commentaire, étiquette, couleur, type, auteur, pièce jointe, collection et date de modification |
Les résultats sont paginés et BibGenie ne charge la page suivante que si nécessaire.
`get_annotations` cible une pièce jointe, pas sa référence bibliographique parente. BibGenie identifie d’abord la pièce jointe si vous partez d’un item Zotero ordinaire.
## Ajouter au chat [#ajouter-au-chat]
* Dans le lecteur Zotero, sélectionnez une ou plusieurs annotations, faites un clic droit et choisissez **Add to Chat**.
* Dans la bibliothèque, sélectionnez les items d’annotation et choisissez **Add to Chat**.
* Les options **Reader Annotations** et **Library Items** dans les [paramètres Add to Chat](/fr/docs/add-to-chat-settings) contrôlent ces entrées.
Un commentaire est l’interprétation de son auteur et ne doit pas être attribué au document source. Pour le fonctionnement des citations, consultez [BibGenie Citation](/fr/docs/bibgenie-citations).
Cliquer sur une référence d’annotation ouvre la pièce jointe parente et tente d’atteindre l’annotation enregistrée. BibGenie ne modifie ni ne supprime les annotations existantes. Les annotations d’image ou de tracé peuvent contenir peu de texte interrogeable.
# Guide des collections et tags Zotero (/fr/docs/zotero-collections-tags-best-practices)
Les collections et les tags de Zotero permettent tous deux d'organiser les références, mais ils résolvent des problèmes différents. Une bibliothèque Zotero maintenable à long terme repose rarement uniquement sur les collections ou uniquement sur les tags. Utilisez plutôt les collections comme points d'entrée par projet ou thème, les tags comme dimensions de recherche transversales, et les saved searches pour les workflows dynamiques.
Si vous utilisez BibGenie, ce guide est plus qu'une méthodologie — il devient un workflow exécutable. La fonction d'organisation de bibliothèque de BibGenie peut inventorier vos collections, tags et items existants, proposer un plan d'organisation basé sur votre système de recherche, puis (après votre confirmation) créer des collections par lots, ajouter ou supprimer des tags, déplacer des items, et renommer ou fusionner les tags désorganisés.
Les collections répondent : « À quel projet, cours, synthèse ou point d'entrée thématique ces références appartiennent-elles ? » Les tags répondent : « Quelles caractéristiques, méthodes, statuts, objets ou usages cette référence possède-t-elle ? »
Zotero fournit les capacités d'organisation de base — collections et tags. La fonction d'organisation de bibliothèque de BibGenie agit comme votre assistant d'organisation : elle comprend d'abord votre organisation existante, propose ensuite un plan vérifiable, puis exécute après votre approbation.
Pour une introduction complète aux capacités d'organisation de bibliothèque de BibGenie et des exemples de prompts, consultez la [documentation sur la gestion de bibliothèque](https://www.bibgenie.com/fr/docs/library-management).
## Référence rapide [#référence-rapide]
Si vous commencez tout juste à organiser votre Zotero, suivez ces règles :
| Scénario | Recommandé | Comment BibGenie aide |
| :------------------------------------------------------------------------- | :------------------------ | :------------------------------------------------------------------------------------------------------------------------------- |
| Article, cours, projet, mémoire, thèse | Collection | Génère une structure de collection de projet à partir des items sélectionnés et ajoute les références à la collection appropriée |
| Sujet de recherche, méthode, type de données, région, cadre théorique | Tag | Lit les titres, résumés et métadonnées, et suggère des tags topic/method/status cohérents |
| `to-read`, `read`, `important`, `reviewed` | Colored tag ou tag normal | Ajoute ou supprime en lot des tags de statut pour votre workflow de lecture en cours |
| Ajout récent (7 jours), non lu, DOI manquant, combinaisons de tags | Saved search | Aide à concevoir des critères de recherche et des règles d'organisation ultérieures |
| Critique de livre et livre critiqué, différentes versions d'une même œuvre | Related items | Identifie les entrées potentiellement liées, mais l'établissement des relations est préférable manuellement |
| Trop de sous-collections imbriquées | À éviter | Identifie les collections trop profondes, fragmentées ou en double et suggère des fusions |
## Ce que la fonction d'organisation de bibliothèque de BibGenie peut faire [#ce-que-la-fonction-dorganisation-de-bibliothèque-de-bibgenie-peut-faire]
Lors de l'organisation manuelle des collections et tags Zotero, la partie chronophage n'est pas de cliquer sur des boutons — c'est de décider : quels tags sont en double, quels items appartiennent à quelle collection, quelles métadonnées manquent, et quelles opérations affectent trop d'éléments. C'est là que la fonction d'organisation de bibliothèque de BibGenie excelle.
| Tâche | Ce que BibGenie peut faire |
| :--------------------------------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Auditer la structure existante | Lister la hiérarchie des collections, le vocabulaire des tags, les items sous une collection ou un tag spécifique |
| Trouver des items à organiser | Localiser les items non classés, les références récemment ajoutées, les entrées sans DOI/résumé, les items par tag ou collection |
| Concevoir un schéma d'organisation | Proposer un système de classification basé sur les titres, résumés, métadonnées, tags et collections existants |
| Organiser des items par lots | Ajouter ou supprimer des tags, ajouter à des collections ou en retirer pour des items spécifiés |
| Créer des collections | Créer de nouvelles collections sous le bon parent, en plaçant éventuellement des items candidats à l'intérieur |
| Nettoyer les tags | Renommer des tags, fusionner d'anciens tags dans des tags existants, supprimer les tags inutilisés dans toute la bibliothèque |
| Organiser les collections | Renommer des collections, déplacer des collections, supprimer les collections vides ou inutiles (la suppression d'une collection ne supprime pas ses items) |
| Vérifier les métadonnées | Lire les métadonnées complètes, identifier les champs manquants et aider à les corriger lorsque des sources fiables sont disponibles |
La modification des métadonnées, la création de collections, le déplacement d'items, la modification par lots des tags, le renommage ou la suppression de collections/tags sont des opérations d'écriture. BibGenie proposera des actions et attendra votre approbation. Il ne doit jamais modifier votre bibliothèque Zotero sans confirmation explicite.
Une bonne demande d'organisation à BibGenie doit inclure le périmètre, l'objectif et les contraintes :
```text
Please organize the currently selected items. First read the existing collections and tags, then propose an organization plan based on titles, abstracts, and metadata.
Prefer reusing existing collections and tags; only suggest creating new ones if there is genuinely no suitable place.
Do not modify Zotero yet. First output which items will be affected, which tags will be added, and which collections will be used.
```
Le principe derrière ce prompt est le workflow central de la fonction d'organisation de bibliothèque de BibGenie : d'abord découvrir l'état actuel, puis identifier les items à organiser, ensuite proposer un plan, et enfin exécuter.
## Que sont les collections [#que-sont-les-collections]
Les collections sont les dossiers et sous-dossiers dans la barre latérale gauche de Zotero. La documentation officielle de Zotero recommande de considérer les collections comme des « listes de lecture » plutôt que comme des dossiers de système de fichiers : un même item peut apparaître dans plusieurs collections sans dupliquer la référence. La véritable bibliothèque complète reste `My Library` ou la bibliothèque de groupe correspondante.
Les collections fonctionnent mieux comme points d'entrée. Par exemple :
* `PhD Thesis`
* `2026 Systematic Review`
* `Course - Research Methods`
* `Project - AI Literature Review`
* `Topic - Retrieval-Augmented Generation`
L'avantage est la clarté, la visibilité et la disponibilité pour les projets. Ouvrez une collection et vous voyez immédiatement les références essentielles pour ce travail.
Lorsque vous utilisez BibGenie, demandez-lui d'ébaucher une structure de collection avant de déplacer des items :
```text
Please list my existing collections first, then decide whether the selected items can fit into existing collections.
If the existing structure isn't sufficient, design a one-to-two-level collection draft for my "literature review writing project."
Output each collection's purpose and the proposed items it would contain. Do not modify Zotero.
```
La suppression d'une collection normale supprime uniquement ce point d'entrée organisationnel, pas les items qu'elle contient. Pour vraiment supprimer des items, vous devez les déplacer dans la Corbeille. Cette distinction est importante pour les nouveaux utilisateurs.
C'est aussi pourquoi BibGenie vous avertit explicitement lors de la suppression d'une collection : supprimer une collection ne fait que retirer le point d'entrée organisationnel ; les items restent dans la bibliothèque Zotero. Si une collection a des sous-collections, BibGenie refusera de supprimer directement la collection parente et vous demandera d'abord de décider du sort des sous-collections.
## Que sont les tags [#que-sont-les-tags]
Les tags sont des étiquettes textuelles attachées aux items, pièces jointes et notes. Ils n'ont pas de hiérarchie mais peuvent décrire un même article sous plusieurs angles. La documentation officielle de Zotero souligne que les tags peuvent être utilisés pour le sujet, la méthode, le statut, l'évaluation ou le workflow personnel.
Les tags fonctionnent mieux comme dimensions. Par exemple :
* Sujet : `llm-agent`, `scientific-discovery`, `citation-network`
* Méthode : `survey`, `experiment`, `meta-analysis`, `case-study`
* Objet : `clinical-trial`, `graduate-students`, `zotero-users`
* Statut : `to-read`, `read`, `skimmed`, `cited`
* Usage : `intro-section`, `related-work`, `method-baseline`
La puissance des tags réside dans la recherche combinatoire. Vous pouvez filtrer au sein d'une collection pour les items tagués à la fois avec `llm-agent` et `survey`, ou rechercher dans toute votre bibliothèque tout ce qui est tagué `to-read` et `citation-network`.
La force de BibGenie est de suggérer des tags par lots en fonction du contenu des items. Commencez par lui demander de seulement analyser :
```text
Please list my existing tags first, then review the titles, abstracts, and existing tags of items in this collection.
Prefer reusing existing tags; only suggest new tags when no suitable one exists.
Finally, present recommended tags to keep, merge, add, and delete in a table. Do not modify Zotero.
```
## Collections vs Tags [#collections-vs-tags]
| Dimension | Collections | Tags |
| :-------------------------------------------- | :---------------------------------------------------- | :------------------------------------------------- |
| Organisation | Hiérarchique avec sous-collections | Plate, pas de sous-tags natifs |
| Meilleur pour exprimer | Projets, cours, articles, points d'entrée thématiques | Sujet, méthode, statut, qualité, attributs d'usage |
| Un item peut-il apparaître dans plusieurs ? | Oui | Oui |
| Préservé lors de la copie entre bibliothèques | Généralement non | Généralement oui avec l'item |
| Navigation | Forte | Modérée |
| Filtrage croisé | Modéré | Fort |
| Risque de maintenance | Gonflement des collections | Synonymes et dérive orthographique des tags |
| Granularité recommandée | Peu, stable | Plus fine possible, mais nommage cohérent |
Si vous avez déjà une collection `Topic - LLM Agents`, vous n'avez pas nécessairement besoin de taguer chaque item avec `llm-agents`, sauf si vous souhaitez rechercher ce sujet dans d'autres collections.
Lorsque vous utilisez BibGenie pour organiser, ajoutez ce principe à votre prompt :
```text
Please avoid making tags and collections fully redundant. Don't mechanically add the same tag to every item when the collection already expresses the project membership. Only add topic tags when cross-collection search is needed.
```
## Modèle d'organisation recommandé [#modèle-dorganisation-recommandé]
Pour la plupart des chercheurs, une structure Zotero solide comporte trois niveaux.
### 1. Quelques collections de haut niveau pour les grandes directions [#1-quelques-collections-de-haut-niveau-pour-les-grandes-directions]
Ne créez pas trop de collections de premier niveau. Concevez-les comme des points d'entrée que vous ne renommergez pas fréquemment :
```text
My Library
Inbox
Thesis
Papers
Projects
Topics
Teaching
Archive
```
Ou plus proches de votre domaine de recherche :
```text
My Library
Domain - AI for Science
Domain - Bibliometrics
Domain - Human-Computer Interaction
Project - BibGenie SEO
Project - Zotero Workflow Study
```
### 2. Un à deux niveaux de sous-collections pour les projets [#2-un-à-deux-niveaux-de-sous-collections-pour-les-projets]
Ne descendez pas indéfiniment. Deux niveaux suffisent généralement :
```text
Project - Systematic Review
01 Search Results
02 Screening
03 Included Studies
04 Background Reading
05 Cited in Manuscript
```
Cette structure correspond au flux de travail de recherche, ce qui la rend plus pratique pour l'écriture réelle que des douzaines de subdivisions thématiques.
### 3. Les tags comme dimensions transversales composables [#3-les-tags-comme-dimensions-transversales-composables]
Les tags ne doivent pas remplacer toutes les collections. Ils sont meilleurs pour enregistrer « ce qui est autrement recherchable dans cet article » :
```text
method:survey
method:experiment
topic:semantic-search
topic:zotero
status:to-read
status:read
use:background
use:key-citation
```
Zotero n'a pas de tags hiérarchiques natifs, mais vous pouvez simuler des espaces de noms avec des préfixes comme `method:`, `topic:`, `status:`. Cela réduit l'ambiguïté et facilite le balayage dans le sélecteur de tags.
## Conventions de nommage des tags [#conventions-de-nommage-des-tags]
Un bon système de tags ne consiste pas à avoir plus de tags, mais à être cohérent.
| Règle | Recommandé | Non recommandé |
| :------------------------------------------------- | :------------------ | :------------------------------------- |
| Utiliser des minuscules | `semantic-search` | `Semantic Search`, `semantic Search` |
| Utiliser des traits d'union pour les mots composés | `citation-network` | `citation network`, `citation_network` |
| Préfixer les catégories | `method:survey` | Mélange `survey`, `surveys` |
| Garder les tags de statut cohérents | `status:to-read` | Mélange `unread`, `to read`, `todo` |
| Éviter les tags trop larges | `topic:llm-agent` | `ai`, `paper`, `research` |
| Éviter les tags trop temporaires | `use:intro-section` | `maybe-use-in-chapter-2-later` |
Si vous avez déjà des tags en double, renommez l'ancien tag vers le nom cible dans le sélecteur de tags pour les fusionner. Par exemple, renommez `to read` en `status:to-read`.
Si les tags sont déjà désordonnés, demandez d'abord à BibGenie de faire un audit :
```text
Please list the current library's tags and identify potentially duplicate or synonymous tags — for example, different casing, spaces vs hyphens, singular vs plural.
Give merge suggestions and note how many items each tag affects.
Do not execute any renaming or deletion yet.
```
Confirmez ensuite avant d'exécuter :
```text
I confirm the merge plan. Please rename the tag `to read` to `status:to-read`.
If `status:to-read` already exists, merge the two tags. Before executing, confirm how many items will be affected.
```
Le renommage et la fusion de tags par BibGenie ne parcourent pas les items un par un ; ils utilisent les opérations de tags à l'échelle de la bibliothèque de Zotero. Lorsque vous renommez un ancien tag vers un nom de tag existant, Zotero les fusionne. C'est plus fiable et mieux adapté au nettoyage de tags synonymes accumulés depuis longtemps que d'ajouter manuellement de nouveaux tags et de supprimer les anciens item par item.
## Comment utiliser les colored tags [#comment-utiliser-les-colored-tags]
Zotero permet d'attribuer des couleurs à un petit nombre de tags, qui peuvent être rapidement ajoutés ou supprimés avec des touches numériques. La documentation officielle actuelle indique un maximum de 9 colored tags.
Les colored tags sont meilleurs pour les « statuts à haute fréquence », pas pour tous les sujets :
| Colored tag | Usage |
| :----------------- | :--------------------------------- |
| `status:to-read` | À lire |
| `status:reading` | En cours de lecture |
| `status:read` | Lu |
| `use:key-citation` | Citation clé |
| `use:write-next` | Pour un travail d'écriture à venir |
Évitez d'attribuer un statut colored tag à des tags de sujet ordinaires comme `machine-learning`, `history` ou `statistics`. Les sujets se multiplient avec le temps, mais les emplacements de colored tags sont limités.
BibGenie ne peut pas décider quels tags devraient occuper en permanence vos emplacements de colored tags, mais il peut identifier vos tags de type statut les plus fréquemment utilisés et suggérer s'il faut les consolider en moins de tags à haute fréquence.
## Faut-il conserver les tags automatiques [#faut-il-conserver-les-tags-automatiques]
Lorsque Zotero enregistre des items depuis des bases de données, des sites web ou des catalogues de bibliothèque, il importe parfois automatiquement des vedettes-matière ou des mots-clés. Ces tags automatiques peuvent parfois être utiles, mais ils créent souvent du bruit : casse incohérente, granularité désordonnée, termes trop larges et gonflement des tags.
Stratégies recommandées :
1. Nouvelles bibliothèques ou organisateurs intensifs : Désactivez les tags automatiques, gérez les tags principaux manuellement.
2. Utilisateurs médicaux, juridiques ou en bibliothéconomie utilisant des vocabulaires contrôlés : Conservez d'abord les tags automatiques, puis nettoyez périodiquement.
3. Utilisateurs avec un arriéré important de tags automatiques : Masquez d'abord les tags automatiques, puis supprimez par lots après avoir confirmé qu'ils sont inutiles.
Pour désactiver : allez dans Paramètres / Préférences Zotero > Général et décochez `Ajouter automatiquement aux documents des marqueurs grâce aux mots-clés et aux sujets`.
Si vous n'êtes pas sûr de la valeur des tags automatiques, demandez à BibGenie de les regrouper par fréquence et sémantique :
```text
Please check the current library's tags and list those that may be from automatic import, overly broad, or inconsistently cased. Do not delete anything, just give cleanup suggestions.
```
## Les saved searches — un outil d'organisation sous-estimé [#les-saved-searches--un-outil-dorganisation-sous-estimé]
Les saved searches sont comme des « collections intelligentes ». Elles stockent des critères de recherche, pas des résultats fixes, donc elles se mettent à jour automatiquement lorsque votre bibliothèque change.
Bons cas d'usage pour les saved searches :
* `Unread` : le tag n'est pas `status:read`
* `Recent Additions` : items ajoutés dans les 7 derniers jours
* `Missing DOI` : items dont le DOI est vide
* `Need Review` : items tagués `status:to-read` dans une collection spécifique
* `Key RAG Papers` : items avec à la fois `topic:rag` et `use:key-citation`
Si vous vous surprenez à utiliser les mêmes critères de filtre à plusieurs reprises, envisagez de créer une saved search plutôt qu'une nouvelle collection statique.
BibGenie est mieux adapté pour vous aider à concevoir des règles de saved search que pour convertir chaque tâche dynamique en collection. Par exemple :
```text
I want to create a dynamic view of "unread RAG papers."
Please review my existing tags and collections first, then suggest Zotero saved search criteria.
If existing tags aren't suitable, explain which tags need to be standardized first.
```
BibGenie peut également utiliser une approche similaire aux saved searches pour trouver des items à organiser, comme « items ajoutés dans les 30 derniers jours qui n'ont été placés dans aucune collection », « articles de revue sans DOI », ou « items avec d'anciens tags mais sans nouveaux tags ». Ces tâches sont mieux traitées en produisant d'abord une liste de candidats, puis en décidant des modifications par lots.
## Comment utiliser les related items [#comment-utiliser-les-related-items]
Les related items ne devraient pas remplacer les tags ou les collections. Comme discuté sur les forums Zotero, le problème avec Related est qu'il exprime seulement « deux items sont liés » sans préciser « pourquoi ils sont liés ». Il est donc meilleur pour les relations explicites en petit nombre :
* Une critique de livre et le livre critiqué
* Un article de conférence et sa version étendue dans une revue
* Un article de jeu de données et l'article de référence qui l'utilise
* Une prépublication, la version publiée et un erratum de la même étude
* Les sources clés discutées à plusieurs reprises dans un article de synthèse
Si vous voulez simplement exprimer « ces items appartiennent tous au même sujet », utilisez des tags ou des collections.
## Trois workflows courants [#trois-workflows-courants]
### Workflow A : Rédiger un article ou une synthèse [#workflow-a--rédiger-un-article-ou-une-synthèse]
Créez une collection pour votre projet d'écriture, par ex. `Project - LLM Agent Review`.
Placez d'abord les articles candidats dans `01 Search Results` ou `Inbox`.
Utilisez des tags pour marquer les sujets, méthodes et statuts, par ex. `topic:tool-use`, `method:benchmark`, `status:to-read`.
Après le tri, déplacez ou ajoutez les articles clés dans `03 Included Studies`.
Utilisez `use:key-citation`, `use:intro-section`, `use:method-section` pour marquer les usages rédactionnels.
Prompt BibGenie adapté :
```text
Please examine the `Project - LLM Agent Review` collection.
First list the existing subcollections and tags, then classify the papers into five categories following a review writing workflow: search results, screening, included, background, and cited.
Prefer using existing subcollections; justify any new ones needed.
First output a table, do not move any items yet.
```
Après confirmation :
```text
I confirm this classification table. Please add these items to the corresponding collections per the table, and add the `use:key-citation` tag to core papers.
After completion, summarize how many items were modified, which collections were used, and which tags were added.
```
### Workflow B : Constituer un domaine de recherche à long terme [#workflow-b--constituer-un-domaine-de-recherche-à-long-terme]
Créez une collection à long terme, par ex. `Domain - AI for Science`.
Créez un nombre limité de sous-collections seulement lorsque c'est vraiment nécessaire, par ex. `Foundation Papers`, `Benchmarks`, `Applications`.
Utilisez des tags à grain fin pour enregistrer les sujets, méthodes, jeux de données et sujets expérimentaux.
Vérifiez périodiquement `Unfiled Items` et ajoutez les items orphelins aux collections appropriées ou supprimez-les.
Prompt BibGenie adapté :
```text
Please analyze the items in `Domain - AI for Science`.
First read the existing tags, identify 5 to 8 stable research topics, and suggest corresponding `topic:` tags.
Avoid creating too many subcollections; prefer tags unless a topic will be maintained separately long-term.
```
### Workflow C : Utilisateurs légers [#workflow-c--utilisateurs-légers]
Si vous ne souhaitez pas maintenir un système complexe, suivez ces règles minimales :
* Collections : Créer par projet ou cours.
* Tags : Utiliser seulement 5 à 15 statuts ou sujets à haute fréquence.
* Colored tags : Marquer seulement `to-read`, `read`, `important`.
* Nettoyage mensuel : Tags automatiques, doublons et items non classés.
Un système léger qui est maintenu est plus fiable qu'un système complexe qui ne l'est pas.
Les utilisateurs légers peuvent toujours utiliser BibGenie, mais l'accent devrait être mis sur la réduction des coûts de maintenance, pas sur la génération de plus de tags :
```text
Please classify the currently selected items into only three statuses: `status:to-read`, `status:reading`, `status:read`. If you can't determine the status, put it in `status:to-read` and show a preview first.
```
## Liste de contrôle d'entretien mensuel [#liste-de-contrôle-dentretien-mensuel]
Effectuez un ménage mensuel de votre bibliothèque Zotero :
* Ouvrez `Unfiled Items` et traitez les items qui ne sont dans aucune collection.
* Ouvrez `Duplicate Items` et fusionnez les doublons plutôt que d'en supprimer un.
* Vérifiez le sélecteur de tags pour les tags synonymes, par ex. `methods` et `research-methods`.
* Masquez ou supprimez les tags automatiques inutiles.
* Vérifiez que les items récemment ajoutés ont un titre, auteur, année, DOI et résumé propres.
* Supprimez les sous-collections temporaires qui ont perdu leur utilité pour éviter le gonflement des collections.
Demandez à BibGenie de lister les items candidats et les modifications proposées avant d'exécuter des ajouts de tags par lots, des créations de collections, des déplacements d'items ou des vérifications de métadonnées. Pour toute opération par lot, prévisualisez d'abord et limitez le périmètre, par exemple « ne traiter que les items actuellement sélectionnés » ou « ne traiter que cette collection ».
Un prompt mensuel d'organisation BibGenie solide :
```text
Please help me with Zotero library housekeeping:
1. First list existing collections and tags.
2. Check for unfiled items, duplicate or synonymous tags, overly deep collections, and recently added unorganized items.
3. When checking items missing DOI or abstract, consider the item type to determine whether a DOI is actually expected.
4. Only output the problem list, impact scope, and suggested actions. Do not modify Zotero.
```
Si vous souhaitez placer les items non classés dans des emplacements appropriés, demandez à BibGenie d'exécuter une tâche plus spécifique :
```text
Please find the most recent 50 unfiled items and determine which collections they best fit into based on existing collections.
Do not create new collections unless the existing structure clearly has no suitable place.
First output each item, the suggested collection, the reason, and your confidence level.
```
## Erreurs courantes [#erreurs-courantes]
### Erreur 1 : Utiliser les collections comme seul système d'organisation [#erreur-1--utiliser-les-collections-comme-seul-système-dorganisation]
Si vous créez une sous-collection pour chaque petit sujet, vous vous retrouverez avec des dizaines ou des centaines de collections après quelques années. Les items sont enterrés dans des arborescences profondes, ce qui les rend plus difficiles à trouver.
Lorsque vous utilisez BibGenie, ne lui demandez pas de créer des collections pour chaque petit sujet. Une meilleure instruction : « Créez des collections seulement pour les projets, cours, articles ou sujets stables à long terme ; utilisez des tags pour les concepts à grain fin. »
### Erreur 2 : Des tags sans règles de nommage [#erreur-2--des-tags-sans-règles-de-nommage]
Si `to read`, `ToRead`, `unread`, `todo` coexistent tous, la recherche échoue. Un système de tags craint par-dessus tout la dérive des synonymes.
BibGenie peut détecter cette dérive et renommer les anciens tags vers des tags unifiés. Renommer vers un tag existant les fusionne effectivement.
### Erreur 3 : Utiliser Related pour exprimer l'appartenance thématique [#erreur-3--utiliser-related-pour-exprimer-lappartenance-thématique]
Related est meilleur pour les relations explicites, pas pour lier un ensemble d'items thématiquement similaires. L'appartenance thématique devrait utiliser des tags ou des collections.
### Erreur 4 : Oublier les paramètres d'affichage des sous-collections [#erreur-4--oublier-les-paramètres-daffichage-des-sous-collections]
Dans Zotero, les items des sous-collections n'apparaissent pas nécessairement dans la collection parente par défaut. Modifiez ceci via `View -> Show Items from Subcollections`. Ce paramètre affecte votre compréhension des relations parent-enfant entre collections, il est donc préférable de le standardiser dans les workflows d'équipe.
### Erreur 5 : Ignorer les tags automatiques trop longtemps [#erreur-5--ignorer-les-tags-automatiques-trop-longtemps]
Les tags importés automatiquement encombrent le sélecteur de tags. Sauf si vous dépendez explicitement de ces mots-clés, masquez, supprimez ou désactivez périodiquement les tags automatiques.
### Erreur 6 : Traiter « Organiser toute ma bibliothèque » comme une commande vague [#erreur-6--traiter--organiser-toute-ma-bibliothèque--comme-une-commande-vague]
« Veuillez organiser toute ma bibliothèque » semble pratique mais est généralement trop large. La fonction d'organisation de bibliothèque de BibGenie est mieux adaptée pour commencer par des problèmes spécifiques, comme :
* Items récemment ajoutés mais non organisés.
* Items dans une collection qui nécessitent une subdivision supplémentaire.
* Tags en double ou synonymes.
* Entrées sans DOI, résumé ou titre de publication.
* Articles clés à marquer avec `use:key-citation` pour un projet d'écriture à venir.
Un meilleur prompt :
```text
Please don't organize the entire library yet. Help me diagnose the 3 most pressing categories of issues: unfiled items, duplicate tags, and missing metadata. Only output the problem scope and suggested next steps.
```
### Erreur 7 : Laisser l'IA remplir des métadonnées non vérifiables [#erreur-7--laisser-lia-remplir-des-métadonnées-non-vérifiables]
BibGenie peut vérifier les métadonnées et aider à les corriger lorsque des sources fiables sont disponibles, mais vous ne devriez jamais demander à l'IA d'écrire son propre DOI, résumé, nom de revue, auteur ou numéro de page. Pour les écritures de métadonnées, les sources fiables doivent provenir des métadonnées existantes de Zotero, des informations fournies par l'utilisateur, du contenu d'item déjà lu, ou des requêtes de référence externes vérifiables de BibGenie.
Un bon prompt :
```text
Please check the metadata completeness of the most recent 20 items. For entries missing a DOI or abstract, only suggest corrections when verifiable through reliable sources. Mark unverifiable items as "unconfirmed" and do not generate or guess content.
```
## Modèle recommandé [#modèle-recommandé]
Vous pouvez partir directement de ce modèle :
```text
Collections
Inbox
Project - [Project Name]
01 Search Results
02 To Screen
03 Included
04 Background
05 Cited
Domain - [Long-term Topic]
Foundation Papers
Methods
Applications
Archive
Tags
status:to-read
status:reading
status:read
use:key-citation
use:intro-section
use:method-section
method:survey
method:experiment
method:case-study
topic:[Topic Name]
```
## Workflow de sécurité avec BibGenie [#workflow-de-sécurité-avec-bibgenie]
BibGenie peut gérer les tags, collections, appartenance des items et certaines métadonnées, mais l'organisation de bibliothèque implique de modifier les données Zotero. Suivez toujours ce processus en quatre étapes :
Demandez à BibGenie de lire la structure existante : collections, tags et le périmètre des items à organiser.
Exigez que BibGenie privilégie la réutilisation des collections et tags existants ; n'en créez de nouveaux que s'il n'y a vraiment pas d'endroit approprié.
Demandez à BibGenie de produire le plan d'organisation, incluant les tags à ajouter, les tags à supprimer, les collections de destination, les items affectés et les opérations nécessitant une approbation.
Après confirmation manuelle, autorisez explicitement BibGenie à exécuter. Après l'exécution, demandez un résumé des modifications, des items ignorés et des tâches incomplètes.
Modèle de prompt recommandé :
```text
Please organize the currently selected items. The goal is to establish clear Zotero collections and tags:
1. First list existing collections and tags.
2. Prefer reusing existing collections and tags; don't create similar names unnecessarily.
3. Determine which items should go into the same collection.
4. Then suggest consistent `topic:`, `method:`, `status:` tags.
5. Output which tags and collections will be added or removed for each item.
6. Do not modify Zotero yet; wait for my confirmation.
```
Après confirmation :
```text
I confirm the organization plan above. Please execute these changes, then summarize how many items were modified, which tags were added, and which collections were used.
```
Pour les opérations par lots de 50+ items, soyez plus précis :
```text
This is a large batch organization task. First give a brief plan including which existing collections/tags will be used, whether new ones are needed, how many items will be affected, and which write operations need my approval.
After I confirm, execute in focused batches by shared purpose. Do not run one operation per item.
```
Si vous avez seulement besoin de renommer, fusionner ou supprimer un tag dans toute la bibliothèque, ne faites pas modifier les items un par un par BibGenie. Décrivez directement l'opération au niveau du tag :
```text
Please merge the library-wide tag `methodology` into the existing tag `method:methods`.
First confirm that both tags exist and how many items are affected, then wait for my approval.
```
Si vous avez seulement besoin de renommer ou déplacer une collection, faites opérer BibGenie sur la collection elle-même plutôt que de créer une nouvelle collection et de déplacer tous les items :
```text
Please rename the collection `Old Thesis Reading` to `Project - Dissertation Reading`.
First list the matching collection key and its item count, wait for my confirmation, then execute.
```
## Références [#références]
* [Documentation officielle Zotero : Collections and Tags](https://www.zotero.org/support/collections_and_tags)
* [Base de connaissances officielle Zotero : Organizing a library](https://www.zotero.org/support/kb/organizing_a_library)
* [Forums Zotero : tags and collections best practice?](https://forums.zotero.org/discussion/115437/tags-and-collections-best-practice)
* [Forums Zotero : Collections vs tags](https://forums.zotero.org/discussion/116758/collections-vs-tags)
* [Forums Zotero : best use for related, tags, collections](https://forums.zotero.org/discussion/129569/best-use-for-related-tags-collections)
* [Mastering Zotero: Working with Tags](https://pressbooks.library.yorku.ca/masteringzotero/chapter/working-with-tags/)
* [Zotero Manual: Tags](https://zotero-manual.github.io/tags/)
* [Harvard Library: Organize Your Zotero Library](https://guides.library.harvard.edu/c.php?g=1245347\&p=9129454)
* [UMGC Library: Collections & Tags](https://libguides.umgc.edu/c.php?g=930616\&p=6753118)
* [Massachusetts General Hospital: Organizing Your Library](https://libguides.massgeneral.org/zotero/organizing-library)
* [Catherine Pope: Keeping Your Zotero Library Tidy](https://catherinepope.com/posts/keeping-your-zotero-library-tidy/)
* [Reddit: Collections and Tags](https://www.reddit.com/r/zotero/comments/1izhq0m/collections_and_tags/)
# Zotero WebDAV (/fr/docs/zotero-webdav)
La synchronisation Zotero permet de garder votre bibliothèque disponible sur plusieurs appareils. Dans Zotero, elle comporte deux volets séparés : **synchronisation des données** et **synchronisation des fichiers**. WebDAV sert à la synchronisation des fichiers, notamment les PDF, images, instantanés et autres pièces jointes.
WebDAV n'affecte pas directement les modèles officiels, les crédits ou les fonctions de chat de BibGenie. Toutefois, si vous utilisez Zotero sur plusieurs appareils, WebDAV peut aider à rendre les pièces jointes disponibles localement, ce qui détermine si BibGenie peut lire des PDF ou des instantanés sur un appareil donné.
## Synchronisation des données ou des fichiers [#synchronisation-des-données-ou-des-fichiers]
| Type | Ce qui est synchronisé | Notes |
| :--------------------------- | :---------------------------------------------------------------------------------------- | :-------------------------------------------------------------------------------------------- |
| Synchronisation des données | Éléments, titres, auteurs, années de publication, notes, tags, collections et métadonnées | Zotero fournit une synchronisation des données illimitée gratuitement |
| Synchronisation des fichiers | PDF, images, instantanés, audio et autres fichiers joints | Le stockage gratuit de fichiers Zotero est limité à 300 Mo ; WebDAV peut servir d'alternative |
Pour utiliser la synchronisation Zotero, vous devez généralement vous connecter à un compte Zotero et activer la synchronisation des données. WebDAV ne gère que les fichiers joints ; il ne remplace pas la synchronisation des données du compte Zotero.
Configurez d'abord la synchronisation des données Zotero en vous connectant à votre compte Zotero dans les préférences. WebDAV remplace uniquement la partie stockage de fichiers.
## Qu'est-ce que WebDAV ? [#quest-ce-que-webdav-]
WebDAV est un protocole qui permet aux applications de gérer des fichiers sur un serveur distant. Zotero peut utiliser WebDAV comme alternative au stockage de fichiers de Zotero, ce qui permet aux pièces jointes d'être synchronisées via des fournisseurs de stockage tiers compatibles.
C'est utile si vous voulez retrouver vos PDF et pièces jointes sur plusieurs appareils sans acheter l'offre de stockage de fichiers officielle de Zotero.
## Fournisseurs WebDAV courants [#fournisseurs-webdav-courants]
| Fournisseur | Espace gratuit / limites | Site web | Notes |
| :---------- | :-------------------------------------------------------------------------------- | :--------------------------------------------------------- | :----------------------------------------------- |
| Koofr | 2 Go au départ ; jusqu'à 10 Go après certaines actions de compte | [https://koofr.eu/](https://koofr.eu/) | Facile à configurer ; serveurs en Europe |
| Jianguoyun | 1 Go/mois de trafic en envoi et 3 Go/mois en téléchargement avec l'offre gratuite | [https://www.jianguoyun.com/](https://www.jianguoyun.com/) | Souvent plus rapide depuis la Chine continentale |
Consultez la page officielle Zotero [WebDAV Providers](https://www.zotero.org/support/kb/webdav_services) pour d'autres options.
## Configurer Koofr WebDAV [#configurer-koofr-webdav]
Koofr est un fournisseur de stockage cloud basé en Europe. Il est souvent recommandé car la configuration est simple et Koofr propose des indications WebDAV spécifiques à Zotero.
Créez un [compte Koofr](https://koofr.eu/) et connectez-vous à l'application web Koofr.
Cliquez sur votre avatar en haut à droite et ouvrez **Preferences**.
Sélectionnez **Password** dans le menu de gauche, puis faites défiler jusqu'à **App Passwords**.
Entrez un nom d'application comme `Zotero`, cliquez sur **Generate** et enregistrez le mot de passe généré. Koofr ne l'affiche qu'une seule fois.
Ouvrez Zotero et allez dans **Edit -> Preferences -> Sync**. Sur macOS, utilisez **Zotero -> Settings -> Sync**.
Dans **File Syncing**, activez la synchronisation des pièces jointes et choisissez **WebDAV**.
Saisissez :
* **URL** : `https://app.koofr.net/dav/Koofr`
* **Username** : l'adresse e-mail de votre compte Koofr
* **Password** : le mot de passe d'application Koofr généré
Cliquez sur **Verify Server**. Une fois la vérification réussie, cliquez sur **OK** pour enregistrer les paramètres.
Cliquez sur le bouton de synchronisation de Zotero pour commencer la synchronisation des pièces jointes.
Le segment `Koofr` de l'URL doit commencer par un K majuscule.
## Configurer Jianguoyun WebDAV [#configurer-jianguoyun-webdav]
Connectez-vous à [Jianguoyun](https://www.jianguoyun.com/) dans votre navigateur.
Cliquez sur votre nom de compte en haut à droite et ouvrez **Account Info**.
Ouvrez **Security Options**.
Dans **Third-party App Management**, cliquez sur **Add Application**.
Entrez un nom comme `Zotero`, générez un mot de passe et enregistrez-le. C'est un mot de passe spécifique à l'application, pas votre mot de passe Jianguoyun.
Ouvrez Zotero et allez dans **Edit -> Preferences -> Sync**. Sur macOS, utilisez **Zotero -> Settings -> Sync**.
Dans **File Syncing**, activez **Sync attachment files in My Library** et choisissez **WebDAV**.
Saisissez :
* **URL** : `https://dav.jianguoyun.com/dav/`
* **Username** : votre compte Jianguoyun, généralement votre e-mail
* **Password** : le mot de passe spécifique à l'application généré dans Jianguoyun
Cliquez sur **Verify Server**. Si Zotero demande de créer un dossier `zotero` sur le serveur WebDAV, confirmez.
L'adresse habituelle du serveur WebDAV Jianguoyun est `https://dav.jianguoyun.com/dav/`.
Si vous utilisez Zotero sur plusieurs ordinateurs, configurez les mêmes paramètres WebDAV sur chaque appareil et assurez-vous que la synchronisation des données Zotero utilise le même compte.
# Agregar contexto (/es/docs/add-context)
BibGenie no se limita a mostrarle a la IA un nombre de archivo. Agregar contexto incorpora a la conversación los objetos de investigación de Zotero, el contenido de los documentos y su ubicación de lectura actual. Así, la IA sabe qué fuente está estudiando, qué sección está leyendo y qué pasaje es relevante.
Puede comenzar con un elemento completo de Zotero y acotar después el contexto a una página PDF, una sección EPUB o un pasaje seleccionado en un PDF, EPUB o instantánea. Cuanto más se ajuste el contexto a la pregunta, más precisa será la respuesta y más fácil resultará contrastarla con la fuente.
Agregar contexto responde tanto a «¿qué fuente es?» como a «¿qué parte estoy leyendo?». Puede añadir elementos, archivos adjuntos, notas, colecciones y etiquetas, además de la página PDF actual, la sección EPUB actual o texto seleccionado en el lector.
## Formas de agregar contexto [#formas-de-agregar-contexto]
Escriba un espacio seguido de `@` en el cuadro de entrada para buscar e insertar elementos, archivos adjuntos, notas, etiquetas, colecciones y más de Zotero.
Haga clic en el botón Agregar contexto cerca del cuadro de entrada para abrir un cuadro de diálogo de selección.
Agregue contexto de elementos Zotero, colecciones, etiquetas, pestañas de lectura o texto seleccionado.
Pegue imágenes en el cuadro de entrada o use capturas de pantalla del lado Zotero para figuras, fórmulas y regiones de página.
## Tipos de contexto admitidos [#tipos-de-contexto-admitidos]
| Tipo | Lo mejor para |
| :--------------------------------------------- | :------------------------------------------------------------------------------- |
| Elemento normal | Metadatos bibliográficos, título, autores, año y archivos adjuntos relacionados. |
| Archivo adjunto PDF | Lectura del trabajo completo, resúmenes de secciones, métodos y resultados. |
| Archivo adjunto EPUB | Lectura completa de libros, por página lógica o por sección. |
| Instantánea | Leyendo páginas web guardadas en Zotero |
| Nota | Uso de notas, extractos y notas de investigación de Zotero como contexto |
| Anotación guardada | Uso de un resaltado, comentario, color, etiqueta y su ubicación de origen. |
| Colección | Trabajar con un conjunto de trabajos. |
| Etiqueta | Trabajar con artículos bajo una etiqueta específica |
| Texto seleccionado de PDF / EPUB / Instantánea | Explicación precisa de un pasaje. |
| Contexto actual de la página PDF | Preguntar sobre la página que está leyendo |
| Sección EPUB actual | Leer la unidad de contenido EPUB actual y volver a ella desde el mensaje. |
| Imagen/captura de pantalla | Análisis de figuras, fórmulas, diagramas y regiones de páginas. |
## Agregar contexto con `@` [#agregar-contexto-con-]
Escriba un espacio seguido de `@` en el cuadro de entrada para abrir el menú de búsqueda contextual. Luego puede escribir un título, autor, palabra clave, nombre de nota, nombre de etiqueta o nombre de colección para filtrar los resultados.
Ejemplos comunes:
```text
@attention is all you need
@Smith 2023
@my research note
@systematic-review
@my project collection
```
Después de seleccionar un resultado, aparece como un bloque de contexto en el cuadro de entrada. Puede agregar varios bloques de contexto antes de hacer una pregunta.
## Agregar contexto desde Zotero [#agregar-contexto-desde-zotero]
Puede agregar el objeto Zotero actual directamente a BibGenie:
* Haga clic derecho en uno o más elementos de la biblioteca y elija **Agregar al chat**.
* Haga clic derecho en una colección en el árbol de colecciones.
* Haga clic derecho en una etiqueta en el selector de etiquetas.
* Haga clic con el botón derecho en una pestaña de PDF, instantánea o nota.
* Seleccione texto en un PDF, EPUB o instantánea y agréguelo al chat.
* En el lector de PDF, añada la página actual; en el lector de EPUB, elija **Add Section to Chat** para añadir la sección actual.
Estos puntos de entrada se pueden habilitar o deshabilitar en [Add to Chat Settings](/docs/add-to-chat-settings).
## Añadir contexto preciso desde el lector [#añadir-contexto-preciso-desde-el-lector]
BibGenie utiliza una unidad de lectura adecuada para cada formato de documento:
| Lector | Contexto preciso que puede añadir | Ideal para |
| :---------- | :---------------------------------- | :------------------------------------------------------------- |
| PDF | Página actual o texto seleccionado | Comprobar afirmaciones ligadas a una página, figuras o pasajes |
| EPUB | Sección actual o texto seleccionado | Leer una unidad de capítulo o explicar un pasaje concreto |
| Instantánea | Texto seleccionado | Analizar un pasaje de una página web guardada en Zotero |
El contexto añadido aparece en su mensaje. Cuando incluye datos de ubicación válidos, puede hacer clic en el componente de contexto para volver a abrir el lector correspondiente y regresar al punto relevante.
El índice y la estructura de archivos de un EPUB no siempre se corresponden uno a uno. La sección actual suele ser una unidad XHTML del spine del EPUB. Si varias entradas anidadas del índice comparten el mismo archivo XHTML, Add Section to Chat añade esa unidad de contenido completa, no solo un subapartado delimitado por un ancla.
## Ejemplos [#ejemplos]
Añade un PDF y pregunta:
```text
Resume este trabajo por pregunta de investigación, método, datos, hallazgos principales y limitaciones.
```
Añada la sección actual desde el lector de EPUB y pregunte:
```text
Resume el argumento principal de esta sección y explica cómo se relaciona con el tema general del libro.
```
Agregue varios trabajos relacionados y pregunte:
```text
Compara estos artículos por suposiciones, métodos y conclusiones. Devuelve una tabla comparativa.
```
Agregue un pasaje seleccionado y pregunte:
```text
Explica la lógica de este pasaje e identifica los conceptos clave.
```
Agregue una captura de pantalla de la figura y pregunte:
```text
Explica los ejes, las curvas y la conclusión principal de esta figura.
```
## Consejos [#consejos]
* Agregue solo el contexto que sea relevante para la pregunta actual.
* Para tareas complejas, solicite primero un resumen y luego continúe con los detalles.
* Para comparaciones de varios papers, pídale a BibGenie que enumere cada artículo antes de sintetizarlo.
* Las capturas de pantalla son útiles para figuras y fórmulas, pero agregue el PDF o elemento de origen si necesita una base a nivel de cita.
# Configuración de Add to Chat (/es/docs/add-to-chat-settings)
BibGenie sitúa **Add to Chat** en la biblioteca de Zotero y en el lector, justo donde ya trabaja. Puede enviar a la IA una fuente relevante o el pasaje que está leyendo sin copiar texto, buscar el archivo adjunto y volver primero al chat.
Los accesos útiles dependen de sus hábitos de investigación. Mantenga las selecciones de PDF y las secciones EPUB si las usa a menudo, u oculte las acciones menos frecuentes para mantener despejados los menús contextuales de Zotero.
Deshabilitar un punto de entrada Agregar al chat generalmente oculta ese elemento de menú o acceso directo. No significa necesariamente que BibGenie no pueda agregar ese tipo de contexto mediante otros métodos.
## Alternadores disponibles [#alternadores-disponibles]
| Configuración | lo que controla |
| :-------------------------------- | :--------------------------------------------------------------------------------------------- |
| Artículos de la biblioteca | Muestra Add to Chat para elementos compatibles de Zotero, incluidas las anotaciones guardadas. |
| Colecciones | Muestra Agregar al chat en el árbol de colección. |
| Etiquetas | Muestra Agregar al chat en el selector de etiquetas. |
| Pestañas del lector | Muestra Agregar al chat para pestañas abiertas de PDF, instantáneas y notas. |
| Selección de texto PDF | Agrega texto PDF seleccionado al chat |
| Selección de texto EPUB | Agrega texto EPUB seleccionado al chat |
| Selección de texto de instantánea | Agrega texto de instantánea seleccionado al chat |
| Reader Annotations | Añade una o varias anotaciones guardadas desde el menú contextual del lector. |
| Contexto de la página del lector | Muestra Add Page to Chat en el lector de PDF y añade la página actual. |
| Contexto de sección EPUB | Muestra Add Section to Chat en el lector de EPUB y añade la sección actual. |
## Qué añaden estos accesos [#qué-añaden-estos-accesos]
Add to Chat funciona en tres niveles:
Los elementos, las colecciones y las etiquetas indican a BibGenie con qué fuentes o grupos de fuentes está trabajando.
Las pestañas del lector añaden un PDF, una instantánea o una nota completos, algo útil para resumir y sintetizar.
Las páginas PDF, las secciones EPUB y el texto seleccionado centran la pregunta en lo que está leyendo en ese momento.
Cuando el contexto incluye datos de ubicación válidos, puede hacer clic en su componente dentro del mensaje para volver a abrir el documento y regresar al punto relevante.
## Valores predeterminados recomendados [#valores-predeterminados-recomendados]
Si es nuevo en BibGenie, mantenga la configuración predeterminada. Preferencias comunes:
Mantenga habilitados los elementos de la biblioteca, las pestañas del lector y las opciones de selección de texto de los formatos que más utiliza.
Mantenga habilitadas las Colecciones y Etiquetas si trabaja con frecuencia por proyecto, tema o grupo de literatura.
Deshabilite las entradas de baja frecuencia si sus menús contextuales Zotero se sienten abarrotados.
## Consejos [#consejos]
* Si lee mucho archivos PDF, habilite la Selección de texto PDF y el Contexto de la página del lector.
* Si lee libros electrónicos, habilite la Selección de texto EPUB y el Contexto de sección EPUB.
* Si analiza páginas web guardadas, habilite la Selección de texto de instantánea.
* Si escribe reseñas de literatura, habilite Colecciones y Etiquetas.
* Si prefiere una configuración mínima, conserve Elementos de biblioteca y el menú del cuadro de entrada `@`.
# Cita de BibGenie (/es/docs/bibgenie-citations)
La Cita de BibGenie conecta las **respuestas de IA**, la **evidencia en las fuentes** y los **objetos de investigación de Zotero** en un mismo sistema trazable.
Cuando BibGenie responde basándose en su biblioteca de Zotero, PDF, notas, snapshots, páginas web o resultados de OpenAlex, agrega automáticamente marcadores de cita como `[1]` y `[2]` cuando corresponde. No necesita activarlo manualmente ni recordar prompts especiales. Cuando vea un marcador de cita, haga clic en él para volver a la fuente y comprobar en qué se basa la respuesta.
BibGenie distingue dos tipos de enlaces que pueden parecer similares, pero cumplen funciones diferentes:
* Una **cita** apunta a la evidencia que respalda una respuesta, como un bloque de texto o una selección en un PDF, EPUB o instantánea.
* Una **entidad en la que se puede hacer clic** apunta a un objeto de Zotero mencionado en la respuesta, como un elemento, archivo adjunto, nota, colección o etiqueta. Sirve para seguir trabajando con el objeto, pero no afirma que el objeto en sí sea la evidencia de una frase.
El objetivo no es hacer que las respuestas parezcan más académicas. El objetivo es ayudarle a juzgar:
* ¿De dónde salió esta conclusión?
* ¿La IA leyó mal la fuente o la generalizó en exceso?
* ¿Es seguro usar esta información en notas, una revisión bibliográfica o un borrador de investigación?
* Si quiere profundizar, ¿qué fuente debería releer?
Las citas le llevan a la evidencia; las entidades en las que se puede hacer clic le llevan a Zotero para continuar el trabajo. Una misma respuesta puede incluir ambas.
## Dos tipos de enlaces interactivos [#dos-tipos-de-enlaces-interactivos]
| Tipo | Pregunta que responde | Destinos habituales | ¿Representa evidencia? |
| :---------------- | :--------------------------------------- | :-------------------------------------------------------------------------------------------------- | :--------------------- |
| Cita | «¿Qué respalda esta afirmación?» | Bloques de documentos, texto seleccionado, anotaciones guardadas, notas y resultados web u OpenAlex | Sí |
| Entidad de Zotero | «¿A qué objeto se refiere la respuesta?» | Elemento, adjunto, nota, anotación, colección o etiqueta | No |
Por ejemplo, BibGenie puede citar un bloque de texto concreto de un EPUB como evidencia y, a la vez, mostrar el archivo EPUB mencionado como un objeto en el que se puede hacer clic. El primero permite verificar la afirmación; el segundo, abrir el material y seguir trabajando con él.
## Qué problema resuelve [#qué-problema-resuelve]
Al usar IA para investigar, el mayor riesgo a menudo no es la falta de respuestas. Es obtener una respuesta fluida sin saber de dónde viene.
En el trabajo real con literatura, a menudo necesita separar tres cosas:
| Tipo | Significado | Por qué importa |
| :-------------- | :----------------------------------------------------------------------- | :----------------------------------------------------------------------- |
| Fuente original | Un PDF, nota, snapshot, página web o resultado de OpenAlex | Es la base de la respuesta |
| Resumen de IA | La compresión, organización o explicación que BibGenie hace de la fuente | Es útil, pero sigue siendo recomendable comprobarlo |
| Su juicio | Su conclusión basada en la fuente y el contexto de investigación | Esto es lo que debe guiar la escritura y las decisiones de investigación |
La Cita de BibGenie mantiene una ruta clara entre estas capas. Le ayuda a pasar de una respuesta de IA a la fuente, y luego decidir por sí mismo si la respuesta es fiable.
## Fuentes compatibles [#fuentes-compatibles]
Las citas de BibGenie no son solo para PDF. A medida que trabaja con distintas fuentes en Zotero, las citas pueden cubrir diferentes tipos de material de investigación.
Cuando BibGenie lee un PDF, las respuestas pueden citar páginas, bloques de texto o ubicaciones de párrafo. Para saltos a párrafos específicos en PDF, consulte [Citas a nivel de párrafo](https://www.bibgenie.com/es/docs/paragraph-citations).
Cuando BibGenie lee un EPUB o su sección actual, las respuestas pueden citar bloques de texto concretos y devolverle al contenido correspondiente en el lector EPUB de Zotero.
Cuando una respuesta se basa en notas, extractos o apuntes de investigación de Zotero, las citas le ayudan a ver de qué contenido de nota procede la información.
Cuando BibGenie lee instantáneas web guardadas en Zotero, las respuestas pueden citar bloques de texto o selecciones válidas y devolverle al contenido de la página guardada.
Cuando usa búsqueda web o extracción web, las citas pueden indicar qué resultado de búsqueda o cuerpo de página web utilizó la respuesta.
Cuando BibGenie usa la búsqueda académica de OpenAlex, las citas pueden apuntar a artículos, autores, revistas o congresos, instituciones, redes de citación y otros metadatos académicos externos.
Los elementos, archivos adjuntos, notas, colecciones y etiquetas pueden aparecer como entidades interactivas en una respuesta. Puede abrir directamente el objeto de Zotero sin confundirlo con evidencia procedente de la fuente.
## El texto seleccionado también se puede citar [#el-texto-seleccionado-también-se-puede-citar]
Puede añadir a la conversación texto seleccionado en un PDF, EPUB o instantánea. Además de ofrecer a BibGenie el pasaje exacto con el que debe trabajar, los datos de ubicación válidos del lector crean una ruta de vuelta a la fuente:
Seleccione en el lector el pasaje que desea explicar o comprobar y elija **Add to Chat**.
Formule una pregunta sobre la selección. BibGenie da prioridad al pasaje que usted ha proporcionado expresamente.
Cuando la respuesta cite esa selección, haga clic en la cita para volver a abrir el documento y regresar a la ubicación correspondiente. En casos compatibles, como los PDF, un resaltado temporal ayuda a localizar rápidamente la fuente.
El texto seleccionado puede seguir utilizándose como contexto de la conversación. Sin embargo, si la posición guardada falta, está dañada o no puede resolverse de forma segura, BibGenie no crea una cita que parezca interactiva pero no pueda volver a la fuente.
## Cómo se mantiene la precisión de las citas [#cómo-se-mantiene-la-precisión-de-las-citas]
Cuando BibGenie lee PDF, EPUB e instantáneas, organiza el contenido en bloques de texto con identificadores estables. La respuesta cita el bloque que realmente respalda una afirmación, en lugar de señalar todo el archivo adjunto como fuente.
Esto aporta tres ventajas prácticas:
* Al hacer clic en una cita, es más probable volver a la página, sección o ubicación de origen pertinente.
* Si se analizan varios archivos adjuntos a la vez, puede distinguir qué material respalda cada afirmación.
* Al copiar una respuesta o guardarla como nota de Zotero, las citas conservan información legible sobre la fuente.
## Qué le ayudan a hacer las citas [#qué-le-ayudan-a-hacer-las-citas]
Para conclusiones importantes, datos, descripciones de métodos y afirmaciones de autores, haga clic en una cita para volver a la fuente y confirmar que el material realmente respalda la respuesta.
Cuando una respuesta es útil, las citas le llevan de vuelta al PDF, nota, snapshot o contenido web más relevante para que pueda seguir leyendo.
Cuando convierte investigación en notas, las citas conservan el rastro desde el resumen hasta la fuente, para que no tenga que redescubrir la evidencia más tarde.
Cuando combina elementos locales de Zotero, páginas web y resultados de OpenAlex, las citas le ayudan a distinguir la evidencia de su biblioteca local de los resultados de búsqueda externos.
## Casos de uso habituales [#casos-de-uso-habituales]
Puede pedir a BibGenie que resuma la pregunta de investigación, el método, el diseño experimental, los hallazgos y las limitaciones de un artículo. Las citas en la respuesta le ayudan a volver al artículo y comprobar las afirmaciones clave.
Si quiere conocer las citas de PDF que saltan al párrafo exacto de la fuente, lea [Citas a nivel de párrafo](https://www.bibgenie.com/es/docs/paragraph-citations).
Añada el archivo EPUB completo o la sección actual y pida a BibGenie que resuma un argumento, explique un concepto o compare capítulos. Las citas de la respuesta apuntan a los bloques de texto EPUB realmente utilizados, mientras que el componente de sección del mensaje permite volver a la ubicación de lectura que añadió.
Seleccione texto en un PDF, EPUB o instantánea y añádalo a la conversación para centrar la pregunta en un pasaje. Cuando la selección contiene datos de ubicación válidos, las citas de la respuesta pueden devolverle al contexto original.
Si tiene extractos, notas de lectura o ideas de investigación guardadas en Zotero, BibGenie puede organizarlas por tema. Las citas le ayudan a ver de qué nota procede un resumen, en lugar de fusionarlo todo en una respuesta imposible de rastrear.
Cuando guarda la página de inicio de un proyecto, la descripción de un conjunto de datos, documentación de herramientas o una noticia como snapshot de Zotero, BibGenie puede leerlo y marcar las fuentes con citas. Si usa búsqueda web o extracción web, las citas también le ayudan a ver qué páginas sirvieron de base para la respuesta.
OpenAlex devuelve metadatos académicos externos como títulos, autores, DOI, sedes de publicación, conteos de citas y relaciones de citación. Las citas le ayudan a rastrear una respuesta hasta un resultado concreto de OpenAlex y evitar tratar metadatos de búsqueda externa como si BibGenie hubiera leído el artículo completo.
Puede combinar PDF locales, notas de Zotero, resultados de OpenAlex y material web en un solo flujo de trabajo. Las citas le ayudan a distinguir qué partes de una respuesta sintetizada proceden de literatura guardada y cuáles de material externo de apoyo.
## Cómo leer las citas [#cómo-leer-las-citas]
Las respuestas de BibGenie suelen incluir marcadores de cita como `[1]` y `[2]`. Trátelos como puntos de entrada a la fuente.
**Lea la estructura de la respuesta**: primero compruebe si BibGenie entendió el punto principal de su pregunta.
**Encuentre las afirmaciones que importan**: concéntrese en conclusiones que quizá adopte, guarde, cite o use para continuar.
**Haga clic en la cita**: vuelva al PDF, nota, snapshot, página web o fuente de OpenAlex correspondiente.
**Compruebe el contenido de la fuente**: confirme si la fuente respalda la afirmación, prestando atención al alcance, la formulación y el contexto.
**Profundice o refine**: si la respuesta es demasiado amplia, pida a BibGenie que la reformule basándose en la fuente citada.
## Citas frente a referencias formales [#citas-frente-a-referencias-formales]
La Cita de BibGenie sirve principalmente para **lectura, verificación y rastreo de fuentes**. No es el formato final de referencia para un artículo.
| Elemento | Cita de BibGenie | Referencia formal |
| :------------------ | :---------------------------------------------------------------- | :------------------------------------------------------------------ |
| Propósito principal | Volver a la fuente detrás de una respuesta de IA | Cumplir los requisitos de formato de un artículo, informe o revista |
| Dónde aparece | En respuestas del chat de BibGenie | En el cuerpo y la bibliografía de un documento |
| En qué se centra | Rastreo de fuentes, comprobación de evidencia, lectura continuada | Estilo de cita, metadatos de publicación, formato |
| Lista para entregar | No se recomienda como cita formal | Debe generarse y comprobarse en el estilo requerido |
Si está escribiendo un artículo, tarea, propuesta de financiación o informe formal, debe seguir usando los estilos de cita de Zotero, como APA, MLA, Chicago, GB/T 7714 o el formato requerido por su destino de publicación.
La Cita de BibGenie sirve para comprobar de dónde viene una respuesta. Para escritura formal, vuelva al elemento de Zotero y a la fuente original, y luego use el formato de referencia requerido.
## Por qué algunas respuestas no tienen cita [#por-qué-algunas-respuestas-no-tienen-cita]
No todas las frases tendrán una cita. Las razones habituales incluyen:
* **La pregunta es operativa**: por ejemplo, "ayúdeme a organizar esta colección" puede producir orientación sobre próximos pasos en lugar de citar un pasaje fuente.
* **La respuesta está sintetizada**: algunos resúmenes combinan varias fuentes y puede que no se asignen limpiamente a una sola cita.
* **La fuente no es lo bastante clara**: si la entrada no contiene material trazable, BibGenie quizá solo proporcione orientación general.
* **La web externa o los metadatos son limitados**: los resultados de OpenAlex y de la web suelen ser resúmenes o metadatos, no lectura de texto completo.
* **La estructura o la calidad del texto afecta el análisis**: PDF escaneados, OCR deficiente, diseños complejos, discrepancias entre el índice y el spine de un EPUB o una estructura inusual de la instantánea pueden afectar la ubicación de las citas.
Si una afirmación importante no tiene cita, puede preguntar de forma natural de dónde salió esa conclusión, o qué artículo, nota o página web la respalda. La cita se sigue agregando automáticamente siempre que BibGenie puede rastrear la fuente.
## Recomendaciones de uso [#recomendaciones-de-uso]
* No dependa solo del resumen de IA para conclusiones importantes. Haga clic en las citas y compruebe la fuente.
* Cuando una cita apunta a un PDF, EPUB o instantánea, lea el contexto cercano en lugar de solo el texto resaltado.
* Cuando una cita procede de OpenAlex, recuerde que normalmente representa metadatos académicos, no lectura del artículo completo.
* Cuando una cita procede de la web, recuerde que el contenido web puede cambiar. Para uso formal, confírmelo en la página original o en otra fuente autorizada.
* Al escribir notas de literatura, conserve las citas generadas automáticamente para poder revisar la fuente más tarde.
* Para artículos formales, no copie directamente la Cita de BibGenie. Use Zotero para generar referencias estándar.
* Si una respuesta no tiene cita, pregunte "¿en qué se basa esta conclusión?" o "¿de qué artículo, nota o página web procede?"
## Relación con las citas a nivel de párrafo [#relación-con-las-citas-a-nivel-de-párrafo]
La Cita de BibGenie es el concepto más amplio. Cubre PDF, notas, snapshots, páginas web, OpenAlex y otras fuentes trazables. Responde:
**¿De dónde vino la información de esta respuesta de IA?**
[Citas a nivel de párrafo](https://www.bibgenie.com/es/docs/paragraph-citations) es una función de lectura de PDF más específica y más potente. Responde:
**¿Puede esta conclusión basada en PDF saltar al párrafo exacto del artículo original?**
Si lo que más le importa es la lectura detallada de PDF, los resaltados del texto original y hacer clic en citas para volver al Zotero PDF Reader, continúe con [Citas a nivel de párrafo](https://www.bibgenie.com/es/docs/paragraph-citations).
La Cita de BibGenie es la visión general: da fuentes a las respuestas. Las citas a nivel de párrafo son el resaltado de lectura detallada de PDF: permiten que las respuestas sobre PDF salten a los párrafos fuente.
# Traiga su propia clave (/es/docs/byok)
BYOK significa Traiga su propia clave. Le permite utilizar su propio proveedor de modelo, clave API o modelo local con BibGenie.
## ¿Por qué utilizar BYOK? [#por-qué-utilizar-byok]
Las solicitudes de modelos personalizados van directamente desde el complemento Zotero local al proveedor que configure.
Ejecute modelos en su propia máquina con Ollama o LM Studio.
Las solicitudes de BYOK no utilizan el servicio de modelo oficial de BibGenie, por lo que no consumen Credits de BibGenie.
Utilice modelos que actualmente no estén incluidos en la lista oficial.
## ¿Los datos pasan a través del servicio de BibGenie? [#los-datos-pasan-a-través-del-servicio-de-bibgenie]
Si agrega un modelo personalizado, los datos de la solicitud no pasan por el servicio de modelo de BibGenie. El complemento local Zotero envía solicitudes directamente al proveedor que configure.
Eso significa:
* OpenAI Clave API: las solicitudes van directamente a OpenAI.
* Anthropic Clave API: las solicitudes van directamente a Anthropic.
* Proxy compatible con OpenAI: las solicitudes van a la URL base que ingresa.
* Ollama o LM Studio: las solicitudes pueden permanecer completamente en su máquina.
BYOK pasa por alto el servicio modelo de BibGenie, pero los proveedores de la nube aún reciben el contenido que les envía. Elija proveedores según la política de datos de su institución, laboratorio o proyecto.
## proveedores compatibles [#proveedores-compatibles]
BibGenie admite múltiples tipos de proveedores:
| proveedor | Notas |
| :--------------- | :--------------------------------------------- |
| OpenAI | OpenAI Modelos GPT |
| Anthropic | Modelos Claude |
| xAI | Modelos Grok |
| DeepSeek | Modelos DeepSeek |
| Google | Modelos Gemini |
| Groq | Modelos alojados en Groq |
| Moonshot AI | modelos kimi |
| OpenRouter | Plataforma de enrutamiento de modelo unificado |
| Ollama | Servicio de modelo local |
| OpenAICompatible | Cualquier API compatible con OpenAI |
LM Studio generalmente se configura a través de **OpenAI Compatible**.
## Cuando BYOK es una buena opción [#cuando-byok-es-una-buena-opción]
* Ya tiene una clave API de proveedor.
* Quiere que la facturación del proveedor se realice a través de su propia cuenta.
* Necesita utilizar un servicio de modelo institucional.
* Quiere que las solicitudes omitan el servicio de modelo oficial de BibGenie.
* Quiere procesar material sensible con un modelo local.
* necesita un modelo que aún no esté en la lista oficial.
## Siguiente paso [#siguiente-paso]
Lea [Custom Models](/docs/custom-models) para agregar un proveedor, ingrese la URL base y la clave API y pruebe la conexión.
# Formato de cita (/es/docs/citation-format)
El formato de cita controla cómo BibGenie muestra los elementos de Zotero en el contexto del chat. Afecta especialmente al estilo de contexto del elemento que se muestra después de escribir `@` en el cuadro de entrada.
## Qué afecta [#qué-afecta]
* Visualización del artículo en los resultados de búsqueda `@`.
* Visualización del elemento después de agregarlo al contexto del chat.
* La representación de estilo de cita que BibGenie recibe como contexto.
El formato de cita solo cambia la visualización. No edita el título del artículo, los autores, el año, la revista u otros metadatos Zotero.
## Elija un estilo CSL [#elija-un-estilo-csl]
BibGenie usa estilos CSL instalados en Zotero. Puede elegir el estilo CSL predeterminado en **Formato de cita** en Preferencias.
Los estilos comunes incluyen:
* apa
* chicago
* MLA
* IEEE
* Naturaleza
* vancouver
## Cuando cambiarlo [#cuando-cambiarlo]
Elija el estilo requerido por su campo, revista o manuscrito.
Los estilos de año de autor suelen ser más fáciles de analizar en ciencias sociales y humanidades.
Los estilos numerados pueden adaptarse a flujos de trabajo de ingeniería, informática o estilo IEEE.
## Preguntas frecuentes [#preguntas-frecuentes]
BibGenie lee los estilos CSL instalados en Zotero. Instale o habilite el estilo en Zotero primero.
No. Esta configuración afecta principalmente la visualización del contexto del chat de BibGenie.
# Gestionar conversaciones (/es/docs/conversation-management)
BibGenie conserva cada conversación como una línea de investigación que puede corregir, ampliar o ramificar. Puede modificar su última pregunta, regenerar una respuesta, abrir una conversación independiente desde una respuesta anterior y compactar el contexto antiguo cuando el intercambio se vuelve extenso.
Modifique el último mensaje del usuario que se pueda editar de forma segura y vuelva a enviarlo.
Pida a BibGenie que genere de nuevo la última respuesta a partir del mismo contexto anterior.
Inicie una conversación independiente desde una respuesta completada sin perder la línea original.
Resuma los intercambios antiguos y conserve los mensajes recientes para la siguiente solicitud al modelo.
## Editar la última pregunta [#editar-la-última-pregunta]
Sitúe el puntero sobre el último mensaje editable del usuario y seleccione **Edit**. Después de modificarlo y enviarlo de nuevo, BibGenie continuará la conversación actual desde la pregunta actualizada.
La edición reemplaza todo lo que sigue al mensaje seleccionado en la línea actual. La respuesta anterior y cualquier estado posterior derivado de ella dejan de formar parte de esa línea. Si desea conservar el enfoque original, [cree primero una rama](#crear-una-rama).
La edición puede no estar disponible mientras la IA responde, una herramienta sigue en ejecución o hay una aprobación pendiente.
## Regenerar una respuesta [#regenerar-una-respuesta]
Si la última respuesta no es satisfactoria, seleccione **Retry** debajo de ella. BibGenie conserva el contexto anterior y vuelve a generar esa respuesta.
Retry reemplaza la respuesta original en la línea actual. Si existe un registro de compactación posterior que depende de esa respuesta, también deja de ser válido. BibGenie vuelve a evaluar el contexto cuando se envía el siguiente mensaje.
Para conservar ambos resultados, cree una rama desde la respuesta original antes de usar Retry en una de las conversaciones.
## Crear una rama [#crear-una-rama]
Fork crea una conversación nueva a partir de una respuesta completada. Sitúe el puntero sobre una respuesta del asistente apta para crear una rama, seleccione **Fork** y confirme. BibGenie creará y abrirá la conversación nueva.
```text
Conversación original: Pregunta 1 → Respuesta 1 → Pregunta 2 → Respuesta 2
│
Rama nueva: └→ Pregunta nueva → Respuesta nueva
```
La rama hereda la respuesta seleccionada y todo el contexto anterior. A partir de ese punto, ambas conversaciones evolucionan de forma independiente: enviar, editar o usar Retry en una no reescribe los mensajes posteriores de la otra.
Fork resulta útil para:
* Explorar interpretaciones o hipótesis diferentes a partir del mismo artículo.
* Comparar prompts, modelos o métodos de análisis.
* Conservar un resultado antes de probar una operación que pueda cambiar lo que sigue.
Solo se pueden crear ramas desde respuestas del asistente completadas y estables. Espere a que terminen la respuesta, la llamada a una herramienta o la aprobación en curso antes de volver a intentarlo.
## Compactar conversaciones extensas [#compactar-conversaciones-extensas]
Todos los modelos tienen una ventana de contexto limitada. A medida que se acumulan mensajes, artículos, imágenes y resultados de herramientas, la conversación se acerca a ese límite. BibGenie puede resumir los intercambios antiguos en un contexto compacto y conservar los mensajes recientes necesarios para continuar.
El agente de BibGenie suele compactar la conversación automáticamente cuando es necesario. Salvo que quiera compactar el contexto anterior de inmediato, continúe formulando preguntas sin seleccionar Compact por su cuenta.
### Compactación automática [#compactación-automática]
BibGenie comprueba el contexto disponible en estos momentos:
* Antes de enviar un mensaje nuevo: si la solicitud prevista se aproxima al límite del modelo, BibGenie compacta primero el contexto anterior y después envía el mensaje automáticamente.
* Al finalizar un turno: si el uso del contexto ha alcanzado el umbral de compactación, BibGenie compacta el contenido anterior en segundo plano.
La compactación automática y la manual utilizan el mismo indicador de progreso. Si el envío de un mensaje activa la compactación, el mensaje pendiente se envía automáticamente cuando esta termina correctamente; no es necesario enviarlo de nuevo.
### Compactación manual [#compactación-manual]
Si quiere compactar inmediatamente la conversación actual, sitúe el puntero sobre el indicador **Context Window** en la esquina inferior derecha del editor y seleccione el icono de compactación en la esquina superior derecha de la tarjeta. Durante el proceso, la conversación muestra **Compacting earlier context…**. Puede seguir editando el contenido del editor o seleccionar **Cancel** antes de que termine la compactación.
### Revisar el resumen compactado [#revisar-el-resumen-compactado]
Después de la compactación, aparece en la conversación un separador **Earlier context compacted**. Despliéguelo para revisar:
* El resumen de los intercambios anteriores.
* El número de tokens de contexto antes de la compactación.
* El modelo y la información de la ventana de contexto utilizados.
El separador no se trata como una pregunta normal del usuario y las respuestas posteriores no contestan directamente a él. Antes de cada solicitud al modelo, BibGenie combina el resumen más reciente con los mensajes recientes conservados para formar el contexto efectivo.
## Cómo se relacionan estas acciones [#cómo-se-relacionan-estas-acciones]
| Acción | Efecto en la conversación actual | Crea una conversación | Llama al modelo |
| :------ | :---------------------------------------------------------------------------------- | :-------------------: | :------------------: |
| Edit | Reemplaza el mensaje seleccionado y todo lo posterior en la línea actual | No | Al volver a enviarlo |
| Retry | Reemplaza la última respuesta que se puede regenerar y su estado posterior | No | Sí |
| Fork | Conserva el original y crea una línea independiente desde la respuesta seleccionada | Sí | No |
| Compact | Resume el contexto anterior y conserva los mensajes recientes | No | Sí |
Si una operación puede reemplazar una respuesta que aún necesita, cree primero una rama.
## Cuando una acción no está disponible [#cuando-una-acción-no-está-disponible]
Edit, Retry, Fork o Compact pueden no estar disponibles temporalmente cuando:
* BibGenie está generando una respuesta.
* Una llamada a una herramienta sigue en ejecución o espera su aprobación.
* La conversación se está compactando o un mensaje enviado espera a que termine la compactación.
* El mensaje seleccionado no está en una posición que se pueda editar o ramificar de forma segura.
* El historial guardado está dañado y la conversación se ha abierto en modo de solo lectura.
Finalice o cancele la operación en curso y vuelva a intentarlo. Si una conversación se abre en modo de solo lectura, BibGenie conserva el historial que puede mostrar de forma segura y no modifica los datos originales guardados.
# Modelos personalizados (/es/docs/custom-models)
Los modelos personalizados le permiten utilizar su propia clave API, proveedor externo, modelo local o servicio de modelo institucional. Una vez configurado, BibGenie envía solicitudes directamente desde el complemento Zotero local al proveedor que elija.
## Agregar un modelo [#agregar-un-modelo]
Abra BibGenie y vaya a **Configuración del modelo**.
Haga clic en **Agregar modelo** en la sección modelos personalizados.
Seleccione o ingrese un **ID de proveedor**. BibGenie carga proveedores comunes desde un catálogo de modelos y completa automáticamente el Nombre del proveedor, el Tipo de proveedor y la URL base cuando es posible.
Seleccione o ingrese un **ID de modelo**. Si el modelo existe en el catálogo, BibGenie completa automáticamente el nombre del modelo, la familia, los tipos de modelo, la ventana de contexto, los tokens Max y la descripción.
Ingrese su clave API. Para servicios locales como Ollama, normalmente no se requiere una clave API.
Haga clic en **Probar** para verificar la conexión. Una prueba exitosa muestra **Conectado**. Si la prueba falla, BibGenie muestra el mensaje de error del proveedor para que pueda corregir la configuración.
Revise los campos autocompletados y ajuste los tipos de modelo, la ventana de contexto o los tokens Max si es necesario.
Haga clic en **Agregar modelo**. El modelo se guarda, se habilita y pasa a estar disponible en el selector de modelos de chat.
## Comportamiento de autocompletar [#comportamiento-de-autocompletar]
Agregar un modelo personalizado no es del todo manual. BibGenie carga información de proveedor y modelo del catálogo `models.dev` cuando esté disponible:
* La identificación del proveedor admite la búsqueda de proveedores comunes y el ingreso manual de un proveedor personalizado.
* Al seleccionar un proveedor, se pueden completar automáticamente el nombre del proveedor, el tipo de proveedor y la URL base.
* El ID del modelo lo filtra el proveedor seleccionado y admite tanto modelos de catálogo como ID de modelos personalizados.
* Al seleccionar un modelo de catálogo, se pueden completar automáticamente el nombre del modelo, la familia, los tipos de modelo, la ventana de contexto, los tokens Max, la descripción y los metadatos de precios.
* Si no se puede cargar el catálogo de modelos, BibGenie utiliza una lista de proveedores alternativos incorporada y aún puede agregar modelos manualmente.
Si su proveedor y modelo aparecen en los menús desplegables de búsqueda, selecciónelos en lugar de escribir todo manualmente. Esto reduce los errores en el tipo de proveedor, la URL base, las capacidades del modelo y los límites de contexto.
## Campos [#campos]
| Campo | Requerido | Descripción |
| :------------------- | :-------- | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| ID del proveedor | Requerido | Identificador de proveedor único, como `openai`, `anthropic` o `openrouter`; Se admiten ID personalizados |
| Nombre del proveedor | Requerido | Nombre para mostrar del proveedor; generalmente se completa automáticamente desde el catálogo |
| ID del modelo | Requerido | ID de modelo real utilizado por la API del proveedor, como `gpt-4.1` o `claude-sonnet-4-5` |
| Nombre del modelo | Requerido | Nombre para mostrar que se muestra en BibGenie; generalmente se completa automáticamente desde el catálogo |
| Clave API | Opcional | La clave API de su proveedor; Los proveedores locales como Ollama generalmente no requieren uno. |
| URL base | Opcional | punto final API; a menudo se completa automáticamente para los proveedores de catálogos, pero los servicios locales o compatibles pueden requerir confirmación manual |
| Tipo de proveedor | Requerido | Tipo de integración API, como OpenAI, Anthropic, Ollama o OpenAI Compatible |
| Familia | Opcional | Familia de modelos, como `qwen`, `gpt` o `claude`; a menudo se completa automáticamente |
| Tipos de modelos | Requerido | Capacidades como texto, visión, razonamiento, llamada a funciones o Web Search |
| Ventana de contexto | Opcional | Ventana de contexto del modelo; a menudo se completa automáticamente para los modelos de catálogo |
| Max Fichas | Opcional | Tokens de salida máximos; a menudo se completa automáticamente para los modelos de catálogo |
| Descripción | Opcional | Descripción del modelo; a menudo se completa automáticamente |
## Guía de tipos de proveedores [#guía-de-tipos-de-proveedores]
| Tipo de proveedor | Usar cuando |
| :---------------- | :------------------------------------------------------------------------ |
| OpenAI | Utiliza la API oficial OpenAI |
| Anthropic | Utiliza la API Anthropic Claude |
| xAI | usa la API de Grok xAI |
| DeepSeek | Utiliza la API oficial DeepSeek |
| Google | usa la API Gemini |
| Groq | usa la API Groq |
| Moonshot AI | usa modelos Kimi / Moonshot |
| OpenRouter | usa la API OpenRouter |
| Alibaba | Generalmente a través de OpenAI Compatible |
| Z.AI / Zhipu AI | Generalmente a través de OpenAI Compatible |
| Ollama | Utiliza un servicio local Ollama |
| OpenAICompatible | Utiliza LM Studio, un proxy API o un punto final institucional compatible |
## URL base [#url-base]
Muchos proveedores oficiales tienen una URL base predeterminada. Generalmente necesita editar la URL base solo cuando:
* usa OpenAICompatible.
* Utiliza un proxy API.
* Utiliza un servicio de modelo local.
* Su proveedor requiere un punto final personalizado.
Ejemplos:
```text
https://api.openai.com/v1
https://openrouter.ai/api/v1
http://localhost:11434
http://localhost:1234/v1
```
Muchas API compatibles requieren una URL base que termine en `/v1`. La falta de la ruta de la versión puede causar errores de NetworkError, 404 o modelo no encontrado.
## Ollama Ejemplo [#ollama-ejemplo]
Asegúrese de que Ollama esté instalado y ejecutándose.
Ejecute `ollama list` en una terminal para confirmar que hay un modelo local disponible.
Si Ollama aún no se está ejecutando, inícielo con `ollama serve`. Debería ver un resultado que confirme que está escuchando en `127.0.0.1:11434`.
Agregue un modelo en BibGenie y elija **Ollama** como Tipo de proveedor.
Utilice `http://localhost:11434` como URL base.
Utilice el nombre del modelo mostrado por `ollama list`, como `llama3.1:8b`, como ID del modelo.
## LM Studio Ejemplo [#lm-studio-ejemplo]
LM Studio generalmente se configura a través de OpenAI Compatible:
Inicie el servidor API local en LM Studio.
Agregue un modelo en BibGenie y elija **OpenAI Compatible** como Tipo de proveedor.
Ingrese la dirección API LM Studio como URL base, generalmente similar a `http://localhost:1234/v1`.
Ingrese la ID del modelo actualmente cargado en LM Studio como ID del modelo.
## Tipos de modelos [#tipos-de-modelos]
Seleccione capacidades según lo que realmente admite el modelo:
* **Texto**: chat de texto; generalmente requerido.
* **Visión**: entrada de imagen, captura de pantalla y figura.
* **Razonamiento**: útil para tareas de razonamiento complejas.
* **Llamadas a funciones**: afecta a los flujos de trabajo de búsqueda, lectura y gestión de bibliotecas.
* **Web Search**: habilitar solo si el proveedor y el modelo lo admiten.
La configuración de capacidad incorrecta puede causar `ModelNotSupported` o fallas en la llamada de herramientas.
## Preguntas frecuentes [#preguntas-frecuentes]
Asegúrese de que el modelo se haya guardado y activado. Si aún no aparece, vuelva a abrir la configuración del modelo o reinicie Zotero.
Las solicitudes de modelos personalizados se envían directamente desde el complemento local de Zotero al proveedor que configure. Consulte [Trae tu propia clave](/docs/byok) para ver los detalles del flujo de datos.
Asegúrese de que el servicio local esté en ejecución, que el puerto sea correcto, que la URL base sea accesible y que ningún firewall o proxy bloquee la solicitud.
Sí. Su clave API se cifra y se almacena solo en la configuración local de Zotero. Se usa directamente para enviar solicitudes al proveedor del modelo y **nunca** pasa por los servidores de BibGenie.
Haga clic en el botón **Restablecer** en el área modelos personalizados para restaurar todas las configuraciones personalizadas a su estado inicial. **Advertencia: esto eliminará todos los modelos que haya agregado manualmente.**
# Solución de problemas (/es/docs/error-in-bibgenie)
Esta página le ayuda a diagnosticar errores BibGenie comunes y a elegir el siguiente paso correcto.
Antes de solucionar problemas, asegúrese de estar utilizando la última versión de BibGenie. Es posible que muchos problemas de modelo, compatibilidad con Zotero y red ya se hayan solucionado en una versión más reciente.
Los cuadros de diálogo de error suelen incluir detalles útiles como el nombre del modelo, la URL de solicitud, la respuesta del proveedor y el motivo del error. Léalos atentamente antes de cambiar la configuración.
## Modelo no compatible [#modelo-no-compatible]
Un cuadro de diálogo titulado "ModelNotSupported".
El modelo seleccionado no admite el tipo de entrada actual. Esto sucede a menudo cuando envía una imagen a un modelo que no admite entrada de visión.
### Cómo solucionarlo [#cómo-solucionarlo]
Elija un modelo que admita la capacidad requerida, como Vision para entrada de imágenes o capturas de pantalla.
Si está utilizando un modelo personalizado y sabe que admite imágenes, verifique que el modelo esté marcado como modelo **Vision** en modelos personalizados.
Si la tarea requiere el uso de herramientas, asegúrese de que el modelo admita **Llamadas a funciones**.
## AI\_APICallError [#ai_apicallerror]
Un cuadro de diálogo titulado "AI\_APICallError".
La solicitud de API del modelo falló. Las causas comunes incluyen clave API no válida, ID de modelo incorrecto, URL base incorrecta, tiempo de espera del proveedor o falla de la red.
### Tipos de errores comunes [#tipos-de-errores-comunes]
Las claves no válidas o caducadas pueden generar mensajes como:
```text
Unauthorized Failure reason: Authentication Fails
(auth header format should be Bearer sk-...)
```
```text
Incorrect API key provided.
```
Verifique que la clave API esté completa, activa y pertenezca al proveedor que seleccionó.
Las ID de modelo incorrectas pueden generar mensajes como:
```text
Model Not Exist
```
Compare el ID del modelo en BibGenie con el ID del modelo exacto mostrado por el proveedor.
Las URL base incorrectas pueden producir errores de solicitud o 404.
Muchos proveedores requieren una URL base que termine en `/v1`. Una URL como `/v/` en lugar de `/v1/` fallará.
### Cómo solucionarlo [#cómo-solucionarlo-1]
Actualice la lista de modelos oficiales en Configuración del modelo. Si el problema persiste, actualice BibGenie y comuníquese con el soporte técnico con el mensaje de error completo.
Verifique el tipo de proveedor, la identificación del proveedor, la identificación del modelo, la clave API y la URL base. Utilice el botón Probar en modelos personalizados para verificar la conexión.
Asegúrese de que Ollama, LM Studio o su servidor local se estén ejecutando, que el puerto sea correcto y que se pueda acceder a la URL base desde el entorno del navegador de Zotero.
## Error de red [#error-de-red]
Un error como `TypeError: NetworkError when attempting to fetch resource.`
BibGenie no pudo alcanzar el punto final del proveedor.
Posibles causas:
* El servidor del modelo local no se está ejecutando.
* La URL base o el puerto son incorrectos.
* El firewall, el proxy o la política de red bloquean la solicitud.
* El punto final del proveedor no está disponible temporalmente.
* El proveedor configurado no admite solicitudes del lado del navegador en su entorno.
## Problemas de apego o contexto [#problemas-de-apego-o-contexto]
Si BibGenie no puede leer un PDF, una instantánea, una nota o un texto seleccionado:
* Asegúrese de que el archivo exista en este dispositivo.
* Si utiliza la sincronización Zotero, verifique que el archivo adjunto se haya descargado localmente.
* Para los usuarios de WebDAV, verifique que la sincronización del archivo Zotero esté funcionando.
* Intente abrir el archivo adjunto directamente en Zotero.
* Reinicie Zotero si el estado del lector parece obsoleto.
## MCP Problemas de conexión [#mcp-problemas-de-conexión]
Si un cliente MCP externo no puede conectarse:
* Confirme que **Habilitar servidor MCP** esté activado.
* Copie la URL del servidor nuevamente.
* Haga clic en **Probar conexión** en Configuración de MCP.
* Asegúrese de que Zotero todavía se esté ejecutando.
* Desconecte a los clientes en los que no confía.
## Obtener ayuda [#obtener-ayuda]
Si el problema persiste, envíe la siguiente información cuando solicite ayuda:
* Versión BibGenie
* Versión Zotero
* Sistema operativo
* Ya sea que esté utilizando un modelo oficial o personalizado
* Tipo de proveedor e ID de modelo
* Mensaje de error completo
* Si el problema ocurre con un PDF, nota o tipo de contexto específico
Puede unirse al [BibGenie Discord community](https://discord.gg/kDXFAAYDNE) para obtener ayuda.
# Empezando (/es/docs/getting-started)
Esta guía lo lleva por el camino más rápido hacia una configuración funcional: descargue el complemento, instálelo en Zotero, abra la barra lateral y haga su primera pregunta sobre un artículo.
BibGenie es compatible con Zotero 7, Zotero 8, Zotero 9 y Zotero 10. Recomendamos utilizar una versión reciente de Zotero para obtener la experiencia de lector y complemento más estable.
## Descargue el complemento [#descargue-el-complemento]
Vaya a [página de descarga de BibGenie](https://www.bibgenie.com/download) y descargue la última versión del complemento.
El archivo descargado suele llamarse:
```text
bibgenie-.xpi
```
donde `` es el número de versión.
## Instale BibGenie en Zotero [#instale-bibgenie-en-zotero]
Abra Zotero y elija **Herramientas -> Complementos** en la barra de menú.
En la ventana del Administrador de complementos, haga clic en el ícono de ajustes en la esquina superior derecha y elija **Instalar complemento desde archivo...**.
Seleccione el archivo `bibgenie-.xpi` que descargó.
Reinicie Zotero después de la instalación.
Después de reiniciar, abra BibGenie desde la barra de herramientas Zotero o el menú Herramientas.
## Abrir BibGenie [#abrir-bibgenie]
Puede abrir BibGenie de varias maneras:
* Haga clic en el icono BibGenie en la barra de herramientas Zotero.
* Elija **Herramientas -> BibGenie** en la barra de menú.
* Utilice el método abreviado de teclado configurado para mostrar o cambiar la barra lateral BibGenie.
Si el acceso directo entra en conflicto con Zotero o su sistema operativo, puede cambiarlo en [Atajos de teclado](/docs/keyboard-shortcuts).
## Iniciar sesión [#iniciar-sesión]
Los usuarios gratuitos pueden comenzar con las funciones principales de chat y contexto. Después de iniciar sesión, BibGenie puede sincronizar el estado de su suscripción, el saldo de Credits y el acceso al modelo oficial.
Incluye las funciones principales, la lectura de artículos y la búsqueda externa con OpenAlex, Web Search y Web Extract.
Incluye más Credits mensuales para la lectura frecuente, las comparaciones y los flujos de investigación.
## Haga su primera pregunta [#haga-su-primera-pregunta]
Una buena primera tarea es comenzar con un documento en PDF:
Seleccione un elemento Zotero que tenga un archivo PDF adjunto.
En el primer lanzamiento, BibGenie utiliza un modelo integrado de forma predeterminada. No necesita configurar una clave API ni elegir manualmente un modelo antes de hacer su primera pregunta.
En el cuadro de entrada BibGenie, escriba un espacio seguido de `@`, luego busque y agregue el documento. También puede hacer clic derecho en el elemento Zotero y elegir **Agregar al chat**.
Haga una pregunta concreta, por ejemplo:
```text
Resume la pregunta de investigación, el método, los hallazgos principales y las limitaciones de este artículo.
```
Si la respuesta es útil, haga clic en **Guardar como nota** en el último mensaje del asistente para guardarlo como una nota Zotero.
Si desea utilizar su propia clave API, un modelo local o un servicio de modelo institucional más adelante, lea [Trae tu propia clave](/docs/byok) y [Modelos personalizados](/docs/custom-models).
Las indicaciones potentes especifican tanto el objetivo como el formato esperado, como "resumir en cinco puntos", "utilizar secciones para el método, los resultados y las limitaciones" o "convertir esto en una nota de revisión de la literatura".
## Próximos pasos [#próximos-pasos]
* Aprenda cómo agregar un contexto más rico: [Añadir contexto](/docs/add-context)
* Aprenda a editar, regenerar, ramificar y compactar conversaciones: [Gestionar conversaciones](/docs/conversation-management)
* Comprender las opciones de modelo: [Modelos](/docs/models)
* Comprender planes y Credits: [Precios y Credits](/docs/pricing-credits)
* Crear mensajes reutilizables: [Indicaciones rápidas](/docs/quick-prompts)
## Actualizando BibGenie [#actualizando-bibgenie]
BibGenie busca actualizaciones automáticamente cuando se inicia Zotero. Cuando se detecta una nueva versión, aparece un botón de actualización en la barra de menú BibGenie; haga clic en él para instalar la última versión.
También puede habilitar las actualizaciones automáticas a través del Administrador de complementos de Zotero:
Abra Zotero y elija **Herramientas -> Complementos**.
Seleccione BibGenie en la lista de complementos.
Establezca **Permitir actualizaciones automáticas** en Activado. Zotero actualizará BibGenie automáticamente cuando haya nuevas versiones disponibles.
# Descripción general (/es/docs)
BibGenie es un agente de investigación IA integrado directamente en Zotero. En lugar de actuar como un chatbot web independiente, funciona dentro de su espacio de trabajo Zotero con su biblioteca, archivos PDF, instantáneas web, notas y el material que está leyendo.
Agregue elementos de Zotero, archivos adjuntos en PDF, instantáneas, notas, texto seleccionado, contexto de página, imágenes o capturas de pantalla a una conversación, luego pídale a BibGenie que lea, explique, busque, organice y analice su material de investigación.
La experiencia principal de BibGenie se ejecuta en su entorno Zotero. El historial de chat y muchas configuraciones se almacenan localmente. Cuando utiliza un modelo personalizado o local, las solicitudes se envían directamente al proveedor que configura.
## Flujo de trabajo principal [#flujo-de-trabajo-principal]
Agregue elementos de Zotero, archivos PDF, instantáneas, notas, texto seleccionado o capturas de pantalla para que BibGenie comprenda el material con el que está trabajando.
Resuma artículos, explique figuras, busque en su biblioteca, compare artículos, use OpenAlex para registros académicos públicos o busque información en la web pública.
Utilice OpenAlex para buscar artículos externos, autores, lugares, citas vecinas y tendencias de publicación, manteniéndolos separados de los elementos Zotero guardados.
Cruce información con arXiv, Semantic Scholar, OpenAlex, DBLP y OpenReview, complete campos vacíos y actualice preprints a publicaciones formales con seguridad. Más información en [Revisión de metadatos](/docs/metadata-review).
Guarde respuestas útiles como notas Zotero o pídale a BibGenie que le ayude a organizar etiquetas, colecciones y metadatos.
## Qué puede hacer con BibGenie [#qué-puede-hacer-con-bibgenie]
* Leer artículos: resumir preguntas de investigación, métodos, contribuciones, limitaciones y trabajos futuros.
* Extractos de lectura profunda: explique pasajes, fórmulas, figuras o resultados experimentales seleccionados.
* Busque en su biblioteca: encuentre artículos relevantes por palabra clave o describiendo un tema de investigación en lenguaje natural.
* Descubra literatura externa: utilice OpenAlex para encontrar registros académicos públicos, citas vecinas, autores, lugares y tendencias de investigación más allá de su biblioteca de Zotero.
* Revisar y actualizar metadatos: cotejar artículos con múltiples bases académicas, transformar preprints de arXiv en publicaciones formales y preservar las claves de Better BibTeX. Más información en [Revisión de metadatos](/docs/metadata-review).
* Organice su biblioteca: administre etiquetas, colecciones, metadatos y movimiento de elementos.
* Guarde notas: convierta las respuestas estructuradas de la IA en notas Zotero.
* Gestione conversaciones: edite la última pregunta, regenere respuestas, cree ramas y compacte el contexto anterior.
* Conecte herramientas externas: exponga las herramientas Zotero locales a través del servidor MCP de BibGenie.
## Ruta de lectura recomendada [#ruta-de-lectura-recomendada]
**Configuración por primera vez**: comience con [Primeros pasos](/docs/getting-started) para instalar BibGenie y haga su primera pregunta.
**Comprender modelos y Credits**: lea [Models](/docs/models) y [Pricing & Credits](/docs/pricing-credits).
**Conozca las funciones principales**: continúe con [Añadir contexto](/docs/add-context), [Gestionar conversaciones](/docs/conversation-management), [Búsqueda de literatura](/docs/literature-search), [Investigación OpenAlex](/docs/openalex-research), [Revisión de metadatos](/docs/metadata-review) y [Guardar como nota](/docs/save-as-note).
**Configuración avanzada**: si tiene su propia clave API o un modelo local, lea [Traiga su propia clave](/docs/byok) y [Modelos personalizados](/docs/custom-models).
## Secciones de documentación [#secciones-de-documentación]
Instalación, modelos, precios y Credits.
Contexto, indicaciones, búsqueda Zotero, investigación OpenAlex, revisión de metadatos, acceso web, gestión de biblioteca, notas y MCP.
Modelos personalizados, MCP, Agregar al chat, accesos directos, formato de cita e indexación semántica.
Errores comunes, fallos del modelo, problemas de red y compatibilidad con Zotero.
# Atajos de teclado (/es/docs/keyboard-shortcuts)
BibGenie admite un atajo de teclado para mostrar o cambiar la barra lateral del chat. Puede personalizarlo para que coincida con su flujo de trabajo.
## Cambiar el atajo [#cambiar-el-atajo]
Abra BibGenie Preferencias.
Busque la sección **Atajos de teclado**.
Elija un modificador, como Ctrl + Mayús o Comando + Mayús.
Ingrese la clave principal, como `L`.
Verifique las advertencias de conflicto y guarde.
## Detección de conflictos [#detección-de-conflictos]
BibGenie busca conflictos con comandos comunes de Zotero. Si se encuentra un conflicto, la página de configuración muestra el comando en conflicto.
Si el atajo no funciona, las posibles causas incluyen:
* Conflicto con un acceso directo Zotero integrado.
* Conflicto con un acceso directo del sistema operativo.
* Conflicto con otro complemento Zotero.
* El foco se encuentra actualmente dentro de un control de entrada, modal o de sistema.
* Su método de entrada o sistema operativo interceptó la combinación de teclas.
## Solución de problemas [#solución-de-problemas]
Pruebe con otra combinación, como Ctrl / Command + Mayús + L. Además, haga clic en la ventana principal de Zotero antes de presionar el atajo.
Eso normalmente significa que hay un conflicto. Elija una tecla principal menos común en Atajos de teclado.
Comando + Mayús suele ser la mejor convención de macOS.
# Gestión de biblioteca (/es/docs/library-management)
BibGenie puede hacer más que leer papers. Puede ayudar a organizar su biblioteca de Zotero administrando etiquetas, creando colecciones, moviendo elementos y editando metadatos.
Las acciones de administración de biblioteca pueden modificar su biblioteca de Zotero. Para operaciones por lotes, solicite a BibGenie que muestre un plan o una vista previa antes de aplicar cualquier cambio.
## Tareas de organización admitidas [#tareas-de-organización-admitidas]
| Tarea | Ejemplos |
| :----------------------------- | :----------------------------------------------------------------------- |
| Gestión de etiquetas | Agregar, eliminar y enumerar etiquetas |
| Gestión de colecciones | Crear colecciones, enumerar colecciones, mover elementos |
| Edición de metadatos | Editar título, resumen, título de publicación, DOI y campos relacionados |
| Lectura de metadatos | Inspeccionar autores, año, archivos adjuntos, notas y etiquetas. |
| Clasificación de la literatura | Agrupar papers por tema, método, año o proyecto. |
Si necesita consultar arXiv, Semantic Scholar, OpenAlex, DBLP u OpenReview para enriquecer automáticamente resúmenes faltantes, DOI, abreviaturas de revistas o normalizar mayúsculas/minúsculas, consulte la guía dedicada de [Revisión y limpieza de metadatos](/docs/metadata-review).
## Flujos de trabajo comunes [#flujos-de-trabajo-comunes]
Agregue `literature-review` o una etiqueta de proyecto a los elementos seleccionados.
Cree una nueva colección en torno a un tema de investigación e incluya papers relevantes en ella.
Encuentre papers a los que les falta DOI, resumen o título de publicación.
Agrupe los papers en una estructura de biblioteca más clara basada en temas de investigación.
## Indicaciones de ejemplo [#indicaciones-de-ejemplo]
```text
Review the selected papers and propose a collection structure by research topic. Do not modify Zotero yet.
```
```text
Add the tags deep-research and llm-agent to the currently selected papers.
```
```text
Find papers in this collection that are missing a DOI or abstract, and return a table.
```
## Flujo de trabajo recomendado [#flujo-de-trabajo-recomendado]
Pídale a BibGenie que busque o enumere los trabajos de los candidatos.
Solicite un plan de organización, que incluya qué elementos se modificarán.
Revisa el plan.
Autorizar explícitamente a BibGenie para aplicar los cambios.
Solicite un resumen de lo que se cambió.
Para el trabajo por lotes, especifique el alcance: "solo elementos seleccionados", "solo esta colección" o "no editar metadatos, solo agregar etiquetas".
## Tenga mucho cuidado con [#tenga-mucho-cuidado-con]
* Moviendo muchos artículos a la vez.
* Eliminación de etiquetas de forma masiva.
* Sobrescribir títulos, resúmenes, DOI u otros metadatos clave.
* Crear o reorganizar colecciones en muchos papers.
Para estas operaciones, trabaje en lotes más pequeños y solicite a BibGenie que enumere primero los elementos afectados.
# Búsqueda de literatura (/es/docs/literature-search)
De forma predeterminada, BibGenie busca y lee primero su biblioteca de Zotero en lugar de ir directamente a la web pública. Esto mantiene las respuestas basadas en el material que ya ha recopilado y organizado.
Cuando necesite documentos además de los Zotero guardados, utilice [OpenAlex Research](/docs/openalex-research). OpenAlex busca metadatos académicos públicos, como obras, autores, lugares, instituciones, temas, recuentos de citas y relaciones entre citas. No significa que el artículo ya esté en su biblioteca.
## Tres modos de búsqueda [#tres-modos-de-búsqueda]
Es mejor cuando conoce el título, autor, año, DOI, etiqueta, colección u otra pista explícita.
Es mejor cuando desea describir un tema de investigación, teoría, método o problema en lenguaje natural.
Lo mejor para enumerar trabajos candidatos, hojear resultados o inspeccionar elementos dentro de un alcance definido.
## Búsqueda de palabras clave [#búsqueda-de-palabras-clave]
La búsqueda de palabras clave funciona bien cuando ya conoce parte de la información de destino:
* Palabras en el título del artículo.
* Nombre del autor
* Año
* DOI
* Nombre de la colección
* Nombre de etiqueta
* Nombre de la revista o conferencia
Ejemplos:
```text
Encuentra papers en mi biblioteca de Zotero sobre aprendizaje contrastivo.
```
```text
Encuentra papers de inferencia causal después de 2022 con la etiqueta revisión.
```
La búsqueda de palabras clave es precisa y fácil de controlar. La desventaja es que puede omitir papers relevantes cuando su redacción no coincide con los metadatos.
## Búsqueda Semántica [#búsqueda-semántica]
La búsqueda semántica está diseñada para consultas conceptuales. No es necesario adivinar los términos exactos utilizados en títulos o resúmenes; en su lugar, describa el tema de investigación.
Ejemplos:
```text
Encuentra papers que discuten cómo los modelos de lenguaje grandes afectan las normas de escritura académica.
```
```text
Mi proyecto trata sobre cómo las herramientas de IA cambian el trabajo de conocimiento de los investigadores. Encuentra papers relacionados.
```
La búsqueda semántica utiliza un índice local de Zotero títulos y resúmenes de elementos regulares. Tener en mente:
* No es una búsqueda de texto completo en PDF.
* Los papers sin resúmenes pueden ser más difíciles de igualar.
* La primera ejecución puede requerir tiempo para crear el índice semántico.
Consulte [Semantic Index](/docs/semantic-index) para conocer el estado del índice y la solución de problemas.
## Listar elementos [#listar-elementos]
Listar elementos se utiliza para mostrar documentos coincidentes o continuar explorando los resultados.
Solicitudes de ejemplo:
```text
Lista los 20 papers más recientes en esta colección.
```
```text
Muestra más resultados.
```
```text
Lista papers etiquetados como revisión-sistemática y ordénalos por año.
```
Listar elementos es especialmente útil cuando desea que BibGenie muestre primero un conjunto de candidatos y luego decida qué archivos PDF o notas leer a continuación.
## Flujo de trabajo recomendado [#flujo-de-trabajo-recomendado]
Utilice la búsqueda semántica para encontrar papers relacionados con un tema amplio.
Pídale a BibGenie que enumere títulos, años, autores y resúmenes.
Seleccione algunos papers y agréguelos como contexto.
Pídale a BibGenie que lea archivos PDF, compare reclamos, genere una tabla o guarde una nota.
## Cuándo cambiar a OpenAlex [#cuándo-cambiar-a-openalex]
Utilice la búsqueda de biblioteca de Zotero cuando desee trabajar con elementos guardados, papers seleccionados, colecciones, etiquetas, notas o archivos PDF adjuntos.
Utilice OpenAlex cuando desee:
* Encuentre documentos que aún no ha guardado.
* Resuelva un autor, institución, revista, tema, editor o financiador en un ID estable OpenAlex.
* Explore trabajos que citan un artículo inicial, trabajos citados por un artículo inicial u trabajos relacionados.
* Agrupe registros académicos públicos por año, fuente, país, tema, estado de acceso abierto u otro campo admitido.
Mantenga los dos tipos de resultados separados en las indicaciones cuando sea necesario:
```text
Busca primero en mi biblioteca de Zotero papers sobre agentes LLM, luego usa OpenAlex para encontrar papers externos que pueda estar perdiendo. Mantén los resultados de Zotero y los resultados externos de OpenAlex separados.
```
Agregue límites de año, etiqueta, colección o resultados para que las búsquedas sean más útiles. Por ejemplo: "solo después de 2020", "dentro de la colección de Métodos" o "devolver como máximo 10 papers".
# Configuración de MCP (/es/docs/mcp-settings)
La configuración de MCP controla el servidor MCP local de BibGenie. Cuando está habilitado, los clientes MCP externos pueden conectarse a la URL del servidor y acceder a las herramientas Zotero de BibGenie.
## Controles [#controles]
Inicia o detiene el servidor local MCP.
La URL que utilizan los clientes externos para conectarse a BibGenie. Generalmente se parece a `http://127.0.0.1:23119/bibgenie/mcp`, pero el puerto puede ser diferente si Zotero usa un puerto de servidor HTTP personalizado.
Copia la URL del servidor a tu portapapeles.
Envía una solicitud de inicialización MCP con HTTP POST JSON-RPC para verificar que se pueda acceder al punto final.
Abrir la URL del servidor directamente en su navegador no es lo mismo que una conexión MCP. Los clientes MCP envían solicitudes POST JSON-RPC, mientras que la barra de direcciones del navegador envía una solicitud GET. Utilice **Probar conexión** para una verificación real.
## Referencia de estado [#referencia-de-estado]
| Estado | Significado |
| :----------------------- | :--------------------------------------------------------- |
| El servidor está apagado | MCP El servidor está deshabilitado |
| A partir de | El servidor está iniciando |
| Servidor en ejecución | El servidor está listo para clientes externos. |
| Conexión de prueba | La prueba de conexión se está ejecutando |
| Conexión verificada | Prueba exitosa |
| La conexión falló | La prueba falló; comprobar la URL o el estado del servidor |
## Cuando falla la conexión [#cuando-falla-la-conexión]
* Asegúrese de que Zotero se esté ejecutando.
* Asegúrese de que BibGenie esté habilitado en Zotero.
* Asegúrese de que **Habilitar servidor MCP** esté activado.
* Copie la URL del servidor mostrada en lugar de asumir el puerto `23119`.
* Reinicie Zotero si el servidor se habilitó recientemente o se actualizó el complemento.
## Habilitar MCP [#habilitar-mcp]
Abra BibGenie Preferencias.
Busque la sección **MCP Servidor**.
Active **Habilitar servidor MCP**.
Espere a que aparezca la URL del servidor.
Haga clic en Copiar y pegue la URL en su cliente externo MCP.
Haga clic en Probar conexión para verificar que funciona.
## Deshabilitar MCP [#deshabilitar-mcp]
Cuando no esté utilizando clientes externos, desactive **Habilitar servidor MCP**. Los clientes externos ya no podrán acceder a las herramientas MCP de BibGenie.
Las herramientas MCP pueden leer o modificar su biblioteca de Zotero. Comparta la URL del servidor solo con clientes en los que confíe.
# MCP (/es/docs/mcp)
MCP significa Model Context Protocol. BibGenie puede iniciar un servidor MCP local que permite a los clientes compatibles con MCP acceder a herramientas relacionadas con Zotero.
Si solo chatea dentro del complemento BibGenie, no necesita configurar MCP. MCP es principalmente para usuarios avanzados, clientes externos y flujos de trabajo automatizados.
## ¿Qué puede hacer MCP? [#qué-puede-hacer-mcp]
Los clientes externos pueden utilizar las herramientas Zotero de BibGenie para:
* Buscar elementos de Zotero
* Ejecutar búsqueda de literatura semántica
* Leer archivos adjuntos en PDF
* Leer instantáneas
* Leer notas de Zotero
* Listar etiquetas y colecciones
* Crear notas de Zotero
* Administrar etiquetas y colecciones
* Obtener o editar metadatos
## ¿Qué es Zotero MCP? [#qué-es-zotero-mcp]
Zotero MCP es el puente local de BibGenie entre su biblioteca de Zotero y clientes AI externos. En lugar de exportar archivos o copiar metadatos manualmente, un cliente compatible con MCP puede solicitar a BibGenie el contexto de Zotero a través de un protocolo local.
Por ejemplo, un cliente externo puede buscar en su biblioteca, inspeccionar colecciones, leer un archivo PDF adjunto o crear una nota Zotero a través de las herramientas MCP de BibGenie.
## Ventajas principales [#ventajas-principales]
El servidor MCP de BibGenie se ejecuta dentro del complemento Zotero. No necesita un servicio Python independiente ni un backend local personalizado.
El punto final MCP se ejecuta en el servidor HTTP local de Zotero. Su cliente externo habla con Zotero en su propio dispositivo.
Las herramientas están diseñadas para flujos de trabajo Zotero: papers, archivos PDF, colecciones, etiquetas, notas, instantáneas y metadatos.
MCP permite que herramientas como Cursor, Claude Code, Claude Desktop y Cherry Studio utilicen el contexto Zotero sin salir de su propia interfaz.
## Características principales [#características-principales]
| Característica | En qué ayuda |
| :---------------------------- | :------------------------------------------------------------------------------------------------------------------------------------- |
| Búsqueda de papers | Encuentre papers por título, autor, publicación, palabra clave o tema. |
| búsqueda semántica | Descubra papers relacionados por significado, no solo por palabras clave exactas. |
| Acceso a metadatos | Lea los metadatos detallados del elemento Zotero antes de citarlo, organizarlo o editarlo. |
| Lectura de PDF | Lea texto de Zotero archivos adjuntos PDF cuando el cliente necesite contenido en papel. |
| Lectura visual de PDF | Represente páginas PDF como imágenes cuando las figuras, tablas o páginas escaneadas necesiten una inspección visual. |
| Notas e instantáneas | Lea notas Zotero e instantáneas web de su biblioteca. |
| Organización de la biblioteca | Enumere colecciones y etiquetas, cree colecciones y administre etiquetas o membresías en colecciones. |
| Revisión de metadatos | Ejecute `review_metadata` de solo lectura para agregar datos de arXiv, Semantic Scholar, OpenAlex, DBLP y OpenReview con diagnósticos. |
| Escritura controlada | Los clientes de confianza pueden crear notas o validar y aplicar actualizaciones de metadatos mediante llamadas a `edit_metadata`. |
## Chat de complemento frente a MCP [#chat-de-complemento-frente-a-mcp]
| Modo | Lo mejor para | Configuración requerida |
| :------------------------------ | :----------------------------------------------------- | :---------------------- |
| BibGenie chat en el complemento | La mayoría de los usuarios | No |
| Servidor local MCP | Usuarios que conectan Zotero a clientes de IA externos | Sí |
## Tipo de servidor y URL [#tipo-de-servidor-y-url]
El servidor MCP de BibGenie utiliza **HTTP transmitible**. La URL del servidor suele verse así:
```text
http://127.0.0.1:23119/bibgenie/mcp
```
El puerto puede ser diferente si su servidor HTTP Zotero utiliza un puerto personalizado. Copie siempre la URL del servidor que se muestra en la configuración de BibGenie en lugar de escribirla a mano.
Los clientes MCP se conectan enviando solicitudes HTTP POST JSON-RPC. Abrir la URL del servidor directamente en un navegador envía una solicitud GET y no es una prueba de conexión MCP confiable. Utilice **Probar conexión** en la configuración BibGenie o en un cliente MCP.
## Habilitar servidor MCP [#habilitar-servidor-mcp]
Abra la configuración de BibGenie.
Busque la sección **MCP Servidor**.
Active **Habilitar servidor MCP**.
Copie la URL del servidor mostrada.
Pegue la URL en su cliente externo MCP.
Haga clic en **Probar conexión** para verificar que funciona.
## Conectar clientes externos [#conectar-clientes-externos]
Utilice la URL del servidor de la configuración BibGenie en clientes que admitan Streamable HTTP MCP.
### Cursor [#cursor]
Cursor puede conectarse directamente al punto final HTTP Streamable de BibGenie.
Abra Configuración de Cursor y vaya a **Herramientas y MCP**.
Haga clic en **+ Nuevo servidor MCP**.
Pegue esta configuración:
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"url": "http://127.0.0.1:23119/bibgenie/mcp"
}
}
}
```
Reemplace la URL si la configuración de BibGenie muestra un puerto diferente.
Guarde la configuración. Cuando Cursor muestra el servidor MCP como conectado, puede usar el contexto Zotero en el chat Cursor.
### Claude Código [#claude-código]
El código Claude admite servidores HTTP MCP directamente:
```bash
claude mcp add ZoteroBibGenie --transport http http://127.0.0.1:23119/bibgenie/mcp
```
Reemplace la URL si la configuración de BibGenie muestra un puerto diferente.
### Claude Escritorio [#claude-escritorio]
Algunas compilaciones de escritorio Claude se conectan a servidores stdio MCP de manera más confiable que los puntos finales HTTP locales. En ese caso, utilice `mcp-remote` como un pequeño puente desde el escritorio Claude al servidor HTTP local de BibGenie.
Instale Node.js si `node` y `npx` no están disponibles en su sistema.
Abra el escritorio Claude.
Abra **Configuración**, luego vaya a la sección **Desarrollador**.
Haga clic en **Editar configuración** para abrir `claude_desktop_config.json`.
Agregue esta configuración:
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"command": "npx",
"args": ["mcp-remote", "http://127.0.0.1:23119/bibgenie/mcp"]
}
}
}
```
Reemplace la URL si la configuración de BibGenie muestra un puerto diferente.
Guarde el archivo y reinicie Claude Desktop.
### Cherry Studio [#cherry-studio]
Cherry Studio admite Streamable HTTP MCP directamente.
Abra Cherry Studio Configuración y cambie a la pestaña **MCP**.
Haga clic en **Agregar** y elija **Creación rápida**.
Llenar:
* **Nombre**: `ZoteroBibGenie`
* **Tipo**: `Streamable HTTP`
* **URL**: la URL del servidor copiada de la configuración de BibGenie

Opcional: abra **Configuración avanzada** y configure:
* **URL del proveedor**: `https://www.bibgenie.com/`
* **URL del logotipo**: `https://www.bibgenie.com/favicon.png`

Haga clic en **Guardar**, active el servicio y use el botón de verificación de Cherry Studio para verificar la conexión.
## Indicaciones de ejemplo [#indicaciones-de-ejemplo]
* "Busque Zotero papers sobre generación de recuperación aumentada publicados después de 2023".
* "Lea el archivo adjunto en PDF para este artículo Zotero y resuma la contribución principal del artículo".
* "Enumera los elementos de mi colección de aprendizaje automático y encuentra las entradas a las que les faltan metadatos del año".
## Recomendaciones de seguridad [#recomendaciones-de-seguridad]
* Comparta la URL del servidor MCP solo con clientes en los que confíe.
* Tenga cuidado con las herramientas que escriben en su biblioteca de Zotero, como crear notas, editar metadatos o administrar etiquetas y colecciones.
* Apague el servidor cuando no esté utilizando MCP.
* Si un cliente externo se comporta inesperadamente, detenga el servidor MCP y revise la configuración del cliente.
## Preguntas frecuentes [#preguntas-frecuentes]
No. El chat integrado puede utilizar las capacidades internas de BibGenie directamente. MCP es sólo para clientes externos.
No. Es un servicio local que se ejecuta en su entorno Zotero y BibGenie.
Asegúrese de que el servidor MCP esté habilitado, que la URL se haya copiado correctamente, que Zotero se esté ejecutando y que la prueba de conexión sea exitosa. Si su servidor HTTP Zotero usa un puerto personalizado, es posible que la URL no use `23119`.
No. La barra de direcciones del navegador envía una solicitud GET, mientras que los clientes MCP utilizan solicitudes POST JSON-RPC. Utilice Conexión de prueba o configure un cliente MCP.
Las listas de herramientas las carga el cliente MCP. Reinicie el cliente externo, asegúrese de que BibGenie esté actualizado y vuelva a conectar el servidor MCP. Algunos clientes también almacenan en caché listas de herramientas hasta que se reinicia la aplicación.
Sí. La conexión básica Zotero MCP proporcionada por **BibGenie** es gratuita. Puede usarlo para conectar cualquier cliente que admita MCP.
# Revisión y limpieza de metadatos (/es/docs/metadata-review)
La revisión y limpieza de metadatos es una de las funciones fundamentales de BibGenie. Los artículos importados desde sitios académicos, archivos PDF o extractores web comunes suelen presentar metadatos incompletos (falta de resúmenes, DOI, número de páginas o revistas), títulos en mayúsculas sostenidas, ausencia de abreviaturas normalizadas, preprints desactualizados tras su publicación y listas de autores truncadas.
BibGenie combina **el razonamiento académico de los grandes modelos de lenguaje** con **bases de datos académicas de referencia**. Con un motor de revisión de solo lectura, evidencia documental transparente y aprobación mediante diferencias visuales, mantendrá su biblioteca de Zotero limpia, completa y estandarizada.
La fase de revisión opera de forma estrictamente de solo lectura y nunca modifica su biblioteca en segundo plano sin su consentimiento. La IA genera una **tarjeta de previsualización visual (Action Preview)** comparando los valores actuales con los cambios propuestos. Los datos se guardan en Zotero únicamente cuando hace clic explícito en «Aprobar».
## Capacidades principales [#capacidades-principales]
Agrega arXiv, Semantic Scholar, OpenAlex, DBLP y OpenReview, enrutando de forma inteligente según DOI, arXiv ID o clave DBLP.
Elija entre `lint` (formato y estándares locales), `blank` (completar datos faltantes, predeterminado) y `all` (sincronización y actualización total).
A diferencia de reglas rígidas basadas en expresiones regulares, BibGenie comprende el contexto científico, protegiendo términos como `mRNA`, `CRISPR-Cas9` o `PyTorch`.
Comparación antes/después destacada, avisos en cambios de tipo de elemento, conservación de claves de Better BibTeX y reversión atómica en caso de error.
## Fuentes de datos académicas admitidas [#fuentes-de-datos-académicas-admitidas]
BibGenie integra canales de búsqueda académica adaptados a diversas áreas de conocimiento y etapas de publicación:
| Fuente | Cobertura y aspectos destacados | Ideal para |
| :--------------------- | :------------------------------------------------------------------ | :--------------------------------------------------------------------------------------- |
| **OpenAlex** | Más de 250 millones de registros de ciencia abierta | Búsqueda multidisciplinaria, compleción de metadatos base, análisis de citas |
| **arXiv** | Repositorio de preprints de física, informática y matemáticas | Metadatos de preprints, identificadores de versión oficial, enlaces a DOI definitivos |
| **DBLP** | Bibliografía de referencia en ciencias de la computación | Congresos y revistas de primer nivel en CS, desambiguación de autores |
| **OpenReview** | Congresos destacados de IA y Machine Learning (ICLR, NeurIPS, etc.) | Verificación de áreas de envío, protección de autores anónimos, seguimiento camera-ready |
| **Semantic Scholar** | Corpus de alta precisión para computación y biomedicina | Identificadores exactos de publicaciones, resúmenes TLDR, análisis de citas |
| **Zotero Translators** | Traductores web y de editoriales nativos de Zotero | Resolución directa en portales de editoriales (IEEE, ACM, Springer, Nature) |
## Tres modos de revisión [#tres-modos-de-revisión]
Según sus necesidades organizativas, puede indicar a BibGenie que actúe en distintos modos:
**Modo predeterminado**. Consulta fuentes académicas oficiales y **únicamente propone completar campos y listas de autores vacíos**:
* Conserva intactos los títulos, autores, años y nombres de publicaciones existentes.
* Rellena resúmenes (Abstract), rangos de páginas (Pages), DOI, títulos de revista o actas de congreso ausentes.
* Adecuado para la gran mayoría de revisiones bibliográficas rutinarias.
**Modo de estandarización local**. Omite la consulta de hechos externos y audita los metadatos existentes mediante reglas académicas:
* Normalización de títulos a mayúscula inicial (Sentence Case).
* Abreviaturas normalizadas de revistas conforme al estándar LTWA.
* Detección precisa de idioma (ISO-639-1).
* Detección de nombres de dominio o URLs erróneamente almacenados en campos de metadatos.
* Idóneo cuando la información ya está completa y solo se requiere uniformidad tipográfica.
**Modo de sincronización integral**. Consulta bases de datos externas y **propone actualizar campos no vacíos, permitiendo la sustitución completa de la lista de autores**:
* Útil para subsanar datos erróneos procedentes de capturas web de baja calidad.
* Ideal para actualizar un preprint cuando ha sido formalmente aceptado en congreso o revista, ajustando el tipo de documento.
* *Nota: No utilice `all` simplemente por falta de algunos datos; emplee el modo `blank`.*
## Seguridad y compatibilidad con el ecosistema [#seguridad-y-compatibilidad-con-el-ecosistema]
1. **Compatibilidad total con Better BibTeX**:
* Muchos investigadores emplean Better BibTeX para gestionar claves en LaTeX. El módulo Extra de BibGenie protege estrictamente `Citation Key:`, `tex.*`, `bibtex:` y notas libres, sin alterar jamás sus claves de citación.
2. **Protección en conversiones de tipo de documento**:
* Si se propone cambiar el tipo de elemento (por ejemplo, de `preprint` a `journalArticle`), la tarjeta de aprobación muestra advertencias específicas sobre los campos que podrían reasignarse o descartarse.
3. **Criterio académico inteligente**:
* Las sustituciones mecánicas a menudo desfiguran acrónimos o nombres de librerías de software. BibGenie aplica el conocimiento contextual del modelo para preservar la ortografía técnica exacta.
## Ejemplos de instrucciones (Prompts) [#ejemplos-de-instrucciones-prompts]
```text
Examina el artículo que tengo seleccionado y usa el modo blank para completar su resumen, páginas y DOI faltantes.
```
```text
Estandariza las mayúsculas del título y las abreviaturas de revista de los elementos seleccionados, manteniendo intactos los términos científicos.
```
```text
Este artículo era originalmente un preprint de arXiv. Comprueba en DBLP o Semantic Scholar si ya se ha publicado en congreso o revista, y sugiere la actualización de tipo y metadatos.
```
```text
Localiza en esta colección los documentos a los que les falte el resumen o el DOI y realiza una revisión para completarlos.
```
## Flujo de trabajo recomendado [#flujo-de-trabajo-recomendado]
**Seleccionar elementos**: Elija uno o varios elementos en Zotero y agréguelos a la conversación con `@` o describa su consulta.
**Revisión en solo lectura con IA**: BibGenie busca en las fuentes académicas y evalúa las reglas para estructurar las propuestas.
**Comprobar la tarjeta de diferencias visuales**: Aparece una tarjeta **Action Preview** en el chat que resalta claramente los cambios propuestos.
**Aprobar y guardar**: Al pulsar «Aprobar», los cambios se guardan de forma atómica en Zotero. Si los descarta, su biblioteca permanece inalterada.
# Modelos (/es/docs/models)
BibGenie admite dos tipos de modelos: **modelos oficiales** y **modelos personalizados**.
* Los modelos oficiales son mantenidos por BibGenie y funcionan desde el primer momento. No es necesario configurar su propia clave API.
* Usted configura los modelos personalizados, incluido el proveedor, la URL base, la clave API y las capacidades del modelo.
Puede gestionar ambos desde **Configuración del modelo**.
## Modelos Oficiales [#modelos-oficiales]
Hay muchos modelos de IA en el mercado, pero sólo un pequeño subconjunto funciona bien como agente Zotero. BibGenie no elige modelos basándose únicamente en puntos de referencia públicos. Nos preocupamos por si pueden manejar de forma fiable flujos de trabajo de investigación reales:
* Lectura de artículos de contexto largo
* Comparación de varios artículos
* Razonamiento de investigación complejo
* Llamada de herramientas y salida estructurada
* Entradas multimodales como figuras, fórmulas y capturas de pantalla.
* Respuestas precisas basadas en el contexto Zotero
La configuración del proveedor también importa. El mismo modelo puede comportarse de manera muy diferente entre proveedores debido a los límites de contexto, el soporte de llamadas de herramientas, los límites de velocidad, los parámetros predeterminados y la confiabilidad de la red.
Para reducir el trabajo de configuración para los usuarios, BibGenie hace varias cosas:
Probamos un conjunto seleccionado de modelos sobre lectura de artículos, búsqueda de literatura, gestión de bibliotecas y flujos de trabajo para tomar notas.
Cuando es posible, analizamos los patrones de implementación y uso recomendados con los equipos de modelos o proveedores.
Trabajamos con proveedores seleccionados para asegurarnos de que los modelos se proporcionen de una manera que funcione bien para BibGenie.
Comparamos combinaciones de modelo-proveedor y mantenemos una lista de recomendaciones.
## Modelos personalizados [#modelos-personalizados]
Si tiene su propia clave API o desea utilizar un modelo local, puede agregar un modelo personalizado.
Los modelos personalizados son útiles cuando:
* Ya paga por un proveedor como OpenAI, Anthropic, DeepSeek o OpenRouter.
* Su institución requiere que las solicitudes vayan directamente a un proveedor específico.
* Quiere utilizar Ollama o LM Studio localmente.
* necesita un modelo que actualmente no esté incluido en la lista oficial.
Consulte [Custom Models](/docs/custom-models) para obtener instrucciones de configuración.
## ¿Qué significan los multiplicadores? [#qué-significan-los-multiplicadores]
Es posible que vea etiquetas como `0x`, `1.5x` o `2x` después del nombre del modelo.
Estas etiquetas indican la velocidad aproximada a la que el modelo puede consumir Credits:
| Etiqueta | Significado |
| :-------------- | :--------------------------------------------------------------------------------------------- |
| `1x` | Velocidad de consumo estándar. |
| `1.5x` | Puede consumir Credits más rápido que un modelo estándar para una tarea similar. |
| `2x` o superior | Generalmente indica un modelo de mayor costo, que es mejor reservar para tareas más exigentes. |
Los multiplicadores se muestran como una pista para el usuario. El uso de Credit real se calcula a partir de tokens de entrada, tokens de salida, precios de modelos y uso de herramientas.
## Actualizar la lista de modelos [#actualizar-la-lista-de-modelos]
La lista oficial de modelos se actualiza automáticamente. También puede actualizarlo manualmente:
Abra BibGenie.
Vaya a **Configuración del modelo**.
Haga clic en **Actualizar** en la sección de modelos oficiales.
Si falta un modelo, las posibles razones incluyen:
* La versión de su complemento no está actualizada.
* La lista de modelos aún no se ha actualizado.
* El modelo no está disponible temporalmente o se está ajustando.
* El estado de su cuenta no se ha sincronizado.
## Elegir un modelo [#elegir-un-modelo]
Comience con un modelo oficial de bajo multiplicador.
Utilice un modelo oficial con manejo de contexto confiable y una sólida calidad de salida.
Utilice un modelo con mayor capacidad de razonamiento y una ventana de contexto más larga.
Utilice BYOK, un proveedor personalizado, Ollama o LM Studio.
# Búsqueda académica de OpenAlex (/es/docs/openalex-research)
OpenAlex Research está disponible en BibGenie v0.7.0 y le ayuda a explorar el catálogo académico público más allá de su biblioteca de Zotero. Úselo cuando desee descubrir nuevos papers, encontrar autores o instituciones, analizar tendencias de investigación o mapear citas en torno a un trabajo conocido.
Los resultados OpenAlex son metadatos bibliográficos externos. No significan que un artículo ya esté guardado en su biblioteca de Zotero y no reemplazan la lectura del artículo en sí.
La búsqueda OpenAlex está disponible para todos los usuarios. En Free, cada llamada correcta a una herramienta OpenAlex cuesta **1 Credit**; los planes pagos incluyen estas llamadas **sin Credits adicionales**.
## Qué puede hacer [#qué-puede-hacer]
Busque registros académicos públicos por tema, frase exacta, DOI, PMID, PMCID, ID de OpenAlex y filtros o campos de ordenación compatibles.
Encuentre IDs estables de OpenAlex para autores, instituciones, revistas, temas, editores y financiadores.
Encuentre trabajos que citan un artículo base, trabajos referenciados por un artículo base o trabajos relacionados.
Agrupe y cuente los resultados por año de publicación, estado de acceso abierto, país, fuente, tema u otro campo admitido.
## Cuándo utilizar OpenAlex [#cuándo-utilizar-openalex]
Utilice OpenAlex cuando su pregunta sea sobre registros académicos públicos fuera de su biblioteca de Zotero actual:
* Encuentre papers recientes sobre un tema de investigación.
* Descubra trabajos anteriores influyentes o papers de revisión.
* Siga las citas sobre un DOI o una identificación de trabajo OpenAlex.
* Muestre aleatoriamente registros coincidentes cuando desee una cobertura exploratoria en lugar de solo una clasificación por relevancia o recuento de citas.
* Compare la actividad de publicación por año, fuente, institución, país, tema u organismo financiador.
* Identifique autores, revistas, instituciones, editoriales o financiadores antes de filtrar los papers según ellos.
Utilice la búsqueda de biblioteca de Zotero en su lugar cuando pregunte sobre elementos guardados, papers seleccionados, colecciones, etiquetas, notas o archivos PDF adjuntos.
OpenAlex puede identificar documentos que vale la pena considerar, pero no los agrega a Zotero automáticamente. Pregunte a BibGenie explícitamente antes de importar, etiquetar, mover o editar cualquier elemento Zotero.
## Cómo preguntar [#cómo-preguntar]
```text
Search OpenAlex for recent review papers about retrieval augmented generation after 2023. Return title, year, venue, authors, citation count, DOI, and why each result may be useful.
```
```text
Use OpenAlex to find papers by Geoffrey Hinton about deep learning. Resolve the author first, then list the most cited works with year, venue, DOI, and citation count.
```
```text
Use OpenAlex to explore papers that cite 10.48550/arXiv.1706.03762. Focus on papers after 2021 and explain which ones look most relevant to LLM research.
```
```text
Use OpenAlex to analyze publication trends for graph neural networks from 2018 to 2025. Group by publication year and summarize the trend carefully.
```
## Flujo de trabajo recomendado [#flujo-de-trabajo-recomendado]
Comience con una búsqueda amplia de OpenAlex utilizando un pequeño recuento de resultados.
Pídale a BibGenie que refine por año, tipo de trabajo, estado de acceso abierto, fuente, autor, institución o tema.
Para obtener un artículo semilla prometedor, solicite citas vecinas, referencias o trabajos relacionados.
Agregue solo los candidatos más relevantes a Zotero después de revisar los resultados.
## Buenos patrones rápidos [#buenos-patrones-rápidos]
```text
Search OpenAlex for papers about AI tools in academic writing. Prefer review articles after 2020 and return at most 10 results.
```
```text
Find the OpenAlex record for this DOI, then show its cited-by papers and related works:
10.1038/nature12373
```
```text
Resolve "Stanford University" in OpenAlex, then find highly cited works about human-computer interaction from that institution since 2020.
```
```text
First search my Zotero library for papers about LLM agents, then use OpenAlex to find external papers I may be missing. Keep Zotero results and external OpenAlex results separate.
```
## Límites importantes [#límites-importantes]
* OpenAlex proporciona metadatos como título, autores, año, lugar, DOI, estado de acceso abierto y recuento de citas.
* No trate el recuento de citas como prueba de calidad.
* No infiera los métodos, afirmaciones o hallazgos de un artículo únicamente a partir de metadatos.
* Para una lectura detallada, agregue el artículo a Zotero o proporcione el texto completo legible, luego solicite a BibGenie que lea el contenido fuente.
# Citas a nivel de párrafo (/es/docs/paragraph-citations)
Al leer literatura académica, no basta con que una respuesta “parezca correcta”. Un asistente de lectura con IA realmente fiable debe poder responder una pregunta más estricta:
**¿De qué parte exacta del artículo sale esta afirmación?**
Las citas a nivel de párrafo de BibGenie están diseñadas precisamente para eso. Permiten rastrear las conclusiones clave de una respuesta de IA hasta bloques concretos de texto dentro del PDF: al hacer clic en un marcador de cita dentro de la respuesta, volverá directamente al Zotero PDF Reader y verá resaltada la zona correspondiente en el texto original.
No se trata de hacer que la respuesta parezca más “académica”. Su valor central es otro: cada juicio importante que haga la IA se puede volver a revisar, releer y confirmar.
Las citas a nivel de párrafo convierten una respuesta de IA que “le dice la conclusión” en una que “le muestra de dónde viene la evidencia”: al hacer clic en el marcador de cita, vuelve directamente al párrafo correspondiente del PDF original.
## En qué se diferencian de las citas habituales [#en-qué-se-diferencian-de-las-citas-habituales]
Aunque todas sean citas, el nivel de detalle cambia por completo lo que usted puede comprobar:
| Nivel de cita | Qué puede saber | Casos adecuados | ¿Basta para una lectura detallada? |
| :-------------------------- | :---------------------------------------------------------- | :------------------------------------------------------------------------------------ | :------------------------------------------------------------- |
| Cita a nivel de documento | De qué artículo procede aproximadamente la respuesta | Lectura exploratoria, listas de referencias, comprensión rápida del contexto | Demasiado amplia; solo identifica la fuente |
| Cita a nivel de página | De qué página del PDF procede aproximadamente la respuesta | Localizar rápidamente el contenido general de una página | Sigue siendo amplia; una página contiene demasiada información |
| **Cita a nivel de párrafo** | **A qué bloque de texto original corresponde la respuesta** | **Lectura detallada, verificación de hechos, toma de notas, redacción de revisiones** | **Permite comprobar directamente la evidencia** |
Las citas a nivel de documento le indican la fuente; las citas a nivel de página le ayudan a encontrar la página; **las citas a nivel de párrafo le permiten comprobar directamente la evidencia**.
El objetivo de BibGenie no es decirle solo “este artículo respalda esta respuesta”, sino permitirle ver con sus propios ojos “este fragmento del texto original respalda esta respuesta”. Para quien investiga, lo segundo importa mucho más que lo primero: no necesita una conclusión ya preparada, sino poder juzgar por sí mismo si esa conclusión se sostiene.
## De “dar respuestas” a “mostrar evidencia” [#de-dar-respuestas-a-mostrar-evidencia]
Antes, leer artículos con IA solía quedarse en “pídale a la IA que lo resuma”.
Eso, por supuesto, es útil: puede entender rápidamente el contenido general, los métodos y las conclusiones de un artículo. Pero en el trabajo académico serio, lo que realmente consume tiempo no es “entender la idea general”, sino hacer preguntas como estas:
* ¿El autor formuló realmente esta conclusión de forma explícita?
* ¿La IA ha combinado en exceso el sentido de varios párrafos distintos?
* ¿Son correctos los detalles sobre resultados experimentales, definiciones de variables o métricas de evaluación?
* ¿Esta frase es una afirmación central del autor o una síntesis hecha por la IA?
* ¿Puede incluirse este punto con seguridad en sus notas, revisión bibliográfica o borrador de artículo?
Si la IA solo ofrece una respuesta fluida, usted todavía tiene que volver al PDF para buscar, pasar páginas, localizar y releer. Ese proceso interrumpe el razonamiento y, a veces, hace que uno termine por no comprobar nada.
Las citas a nivel de párrafo eliminan ese paso.
Cuando BibGenie responde basándose en el texto original del PDF, la respuesta incluye automáticamente marcadores de cita como `[1]` y `[2]`. Usted no necesita pedirle a BibGenie que agregue citas. Al hacer clic en un marcador, BibGenie abre el PDF correspondiente, salta a la página relacionada y resalta el párrafo citado en su ubicación original.
En otras palabras, BibGenie no solo le dice “cuál es la respuesta”, sino que devuelve “de dónde viene la respuesta” al lugar exacto de lectura.
## Por qué importan las citas a nivel de párrafo [#por-qué-importan-las-citas-a-nivel-de-párrafo]
La lectura académica no es como leer noticias. Usted no solo necesita obtener una conclusión; también necesita entender cómo el artículo la respalda.
Por eso cada vez más investigaciones y productos de IA insisten en la atribución de fuentes (source attribution), las respuestas fundamentadas (grounded answers) y la verificación de citas (citation verification). La IA puede generar explicaciones que parecen verdaderas, y también citas que parecen verdaderas. Pero “parece verdadero” no significa “resiste la verificación”.
En el contexto de la literatura académica, una cita fiable debe cumplir tres condiciones al mismo tiempo:
1. **Fuente real**: la cita no debe ser una entrada bibliográfica inventada.
2. **Ubicación precisa**: la cita no debe señalar solo un artículo completo, sino la ubicación concreta de la evidencia.
3. **Contenido compatible**: el texto original citado debe respaldar realmente lo que acaba de decir la IA.
Con frecuencia necesita decidir:
* ¿El autor dijo realmente esta conclusión?
* ¿La IA ha mezclado párrafos, experimentos o incluso artículos distintos?
* ¿Los detalles metodológicos proceden del cuerpo del texto, de un pie de figura, de un apéndice o de una síntesis de la IA?
* ¿Puede escribir esta frase con confianza en una nota o en un borrador de artículo?
* ¿Esta cita solo “parece relacionada”, pero en realidad no respalda la afirmación concreta de la respuesta?
Las citas tradicionales de IA suelen limitarse a decirle “qué artículo se consultó” o “de qué página viene”. Eso puede bastar para una lectura exploratoria, pero es muy insuficiente para una lectura detallada: una sola página de PDF puede contener al mismo tiempo el problema de investigación, el método, fórmulas, configuración experimental, interpretación de resultados y discusión de limitaciones. Una cita a nivel de página solo le dice “más o menos está aquí”; una cita a nivel de párrafo reduce la evidencia al lugar que usted realmente necesita revisar.
## Por qué no basta con dar el número de página [#por-qué-no-basta-con-dar-el-número-de-página]
Muchas herramientas de IA para literatura proporcionan números de página. Son útiles, desde luego, pero no son el punto final.
Una página de un PDF académico suele tener una densidad de información muy alta. En especial en documentos con dos columnas, artículos de revisión, trabajos metodológicos y estudios experimentales de medicina o ingeniería, una sola página puede contener:
* Dos o tres párrafos independientes
* Una tabla o un pie de figura
* Varias fórmulas
* Configuración experimental, métricas de evaluación e interpretación de resultados
* Matices del autor sobre las limitaciones del estudio
Si la IA dice “los autores sostienen que este método mejora la generalización” y solo le indica “véase la página 6”, todavía tendrá que determinar si se refiere al párrafo de resultados experimentales, al párrafo de ablación o a la explicación de la sección de discusión.
Las citas a nivel de párrafo no sustituyen al número de página; van un paso más allá: le muestran directamente el pequeño fragmento de evidencia citado por la IA. Son especialmente útiles cuando una misma página contiene varias evidencias posibles.
## Por qué más detalle no siempre es mejor [#por-qué-más-detalle-no-siempre-es-mejor]
Quizá piense que cuanto más precisa sea una cita, mejor: idealmente, cada frase y cada afirmación deberían poder localizarse. Pero en la lectura académica real, la evidencia rara vez consiste en una sola frase aislada. Los autores suelen definir primero un concepto, describir después la configuración experimental y explicar los resultados en la frase siguiente. Si se extrae una sola frase, puede perderse contexto necesario.
La cita a nivel de párrafo es un punto de equilibrio natural:
* Más precisa que un artículo completo
* Más fácil de comprobar que una página entera del PDF
* Conserva más contexto que una cita de una sola frase
* Genera menos ruido que una cita de varios párrafos
También coincide con la forma real en que los investigadores leen artículos: no miran solo una frase, sino un bloque breve, entienden las condiciones y matices alrededor, y luego deciden si respalda una idea.
## Qué le ayuda a hacer [#qué-le-ayuda-a-hacer]
Haga clic en los marcadores de cita de la respuesta para volver directamente a la ubicación original en el PDF de Zotero, sin pasar páginas manualmente, buscar palabras clave ni adivinar qué párrafo consultó la IA.
Cuando la IA resume métodos, resultados o limitaciones, puede revisar de inmediato el texto original y decidir si la respuesta respeta el sentido del artículo.
Para definiciones teóricas, configuraciones experimentales, explicación de variables, conclusiones de figuras o tablas y matices del autor, las citas a nivel de párrafo se ajustan mejor que las páginas al modo real de verificación académica.
La respuesta, los marcadores de cita, la página del PDF y el resaltado del texto original quedan conectados, de modo que sus preguntas posteriores, notas y juicios tienen una procedencia clara que puede consultar.
## Casos de uso habituales [#casos-de-uso-habituales]
Al leer cuidadosamente un artículo, puede pedir a BibGenie que organice el problema de investigación, el método, el diseño experimental, los hallazgos principales y las limitaciones. Antes quizá obtenía un resumen completo, pero aún tenía que volver a buscar la evidencia punto por punto. Ahora la respuesta incluye citas clicables, y puede regresar al texto original para verificarlas una por una.
```text
Lea este artículo en detalle y resúmalo por problema, método, experimento, hallazgos principales y limitaciones.
```
La IA sabe convertir contenido complejo en una explicación fluida, pero esa fluidez a veces oculta problemas. Por ejemplo, si el artículo solo dice “funciona mejor en cierto conjunto de datos”, la IA podría resumirlo como “el método supera ampliamente a los métodos existentes”; si el artículo solo dice “los autores observaron una tendencia”, la IA podría escribir “los autores demostraron un mecanismo”. Las citas a nivel de párrafo le permiten volver rápidamente al texto original y comprobar si la formulación de la IA va más allá de lo que el autor quiso decir.
```text
Enumere las 5 conclusiones de este artículo que más fácilmente podrían malinterpretarse o generalizarse en exceso.
```
Una buena nota de literatura no solo registra “qué dice este artículo”, sino también “por qué lo entiendo así”. Las citas a nivel de párrafo le ayudan a conectar las notas estructuradas generadas por la IA con la evidencia del texto original. Cuando vuelva a revisar esas notas, podrá saltar al párrafo del PDF que sirvió de base, sin tener que buscar de nuevo en todo el artículo.
```text
Convierta este artículo en un borrador de nota de Zotero, conservando especialmente el problema de investigación, el método, los hallazgos y las limitaciones.
```
En una revisión bibliográfica, dos cosas son especialmente peligrosas: citas imprecisas y origen poco claro de las ideas. Al comparar varios artículos, las citas a nivel de párrafo permiten que cada punto de comparación tenga una procedencia: cómo define el problema el artículo A, qué conjunto de datos usa el artículo B, cuáles son las limitaciones del artículo C. Cada comparación puede volver al texto original, y al escribir la revisión podrá distinguir con más claridad “lo que dijo el autor”, “lo que resumió la IA” y “su propio juicio”.
```text
Compare estos artículos en cuanto a problema de investigación, supuestos metodológicos, configuración experimental y limitaciones.
```
Los métodos y detalles experimentales no admiten vaguedades. Tamaño del conjunto de datos, métodos de referencia, métricas de evaluación, hiperparámetros, criterios de exclusión, pruebas estadísticas, experimentos de ablación: si interpreta mal cualquiera de estos detalles, todo lo que venga después puede desviarse. Las citas a nivel de párrafo le permiten saltar rápidamente al párrafo donde aparecen esos detalles y comprobar si la IA omitió alguna condición clave.
```text
Extraiga la configuración experimental de este artículo, incluidos el conjunto de datos, los métodos de referencia, las métricas de evaluación y los principales resultados comparativos.
```
## Cómo funciona [#cómo-funciona]
Cuando BibGenie lee un PDF, analiza la página en bloques de texto estructurados. Cada bloque conserva el número de página, el orden de lectura y la información de ubicación dentro de la página.
Cuando la IA cita un bloque de texto en una respuesta, BibGenie lo representa como un marcador de cita como `[1]` o `[2]`. Después de hacer clic en el marcador, BibGenie:
1. Abre el PDF correspondiente en Zotero.
2. Salta a la página donde se encuentra la cita.
3. Resalta en el texto original el párrafo o bloque de texto citado.
Lo que usted ve no es “este artículo respalda esta respuesta”, sino “este fragmento del texto original respalda esta respuesta”.
## Flujo de lectura detallada con evidencia [#flujo-de-lectura-detallada-con-evidencia]
Las citas a nivel de párrafo le ayudan a crear un hábito de lectura con IA “verificable por evidencia”:
**Agregar contexto del PDF**: agregue el archivo adjunto PDF de Zotero a la conversación de BibGenie, o pregunte directamente sobre el PDF que está leyendo.
**Plantear una pregunta de lectura**: por ejemplo, pida a BibGenie que resuma el método, explique el diseño experimental, organice las limitaciones o compare las diferencias entre varios artículos.
**Revisar la estructura de la respuesta**: mire primero la organización general que ofrece la IA y valore si captó el hilo principal del artículo.
**Hacer clic en las citas para comprobar el original**: para las conclusiones que piense adoptar, haga clic en el marcador de cita y vuelva al PDF de Zotero para comprobar si el párrafo resaltado respalda realmente esa conclusión.
**Seguir preguntando o corregir**: si descubre que la IA generalizó en exceso u omitió alguna condición, pregunte de nuevo: “reformule esto basándose en el texto original citado”.
El objetivo de este flujo no es que la IA lea el artículo por usted, sino que le ayude a llegar más rápido a una lectura detallada que pueda verificarse.
## Limitaciones y precauciones [#limitaciones-y-precauciones]
Las citas a nivel de párrafo mejoran mucho la trazabilidad, pero no son una garantía automática de corrección. Tenga en cuenta lo siguiente:
* **La ubicación de la cita es relevante, pero no garantiza que la interpretación de la IA sea correcta**: la IA puede haber encontrado un párrafo relacionado y aun así interpretarlo con sesgo o imprecisión.
* **El resaltado ayuda a localizar, pero no equivale al formato final de cita**: para escritura formal, siga usando el formato requerido por APA, MLA, Chicago, GB/T 7714 o la revista de destino.
* **La calidad de la capa de texto del PDF afecta el resultado**: documentos escaneados, OCR deficiente, maquetación compleja o páginas densas en fórmulas pueden afectar el análisis de bloques de texto y la precisión de la ubicación.
* **Las figuras y fórmulas requieren lectura visual**: si la pregunta depende de gráficos, páginas escaneadas o disposición visual, conviene proporcionar también una captura de pantalla o imagen de la página.
* **La IA no sustituye su juicio académico**: las citas a nivel de párrafo hacen más cómoda la verificación, pero el juicio final debe basarse en el texto original, el diseño de investigación y su comprensión profesional.
Deje que BibGenie reduzca el rango de verificación; luego decida usted si ese fragmento del texto original respalda realmente una conclusión.
## Recomendaciones de uso [#recomendaciones-de-uso]
* Acostúmbrese a hacer clic en las citas y comprobar el texto original cuando se trate de conclusiones importantes, datos, configuraciones experimentales u opiniones del autor.
* Si la formulación de la IA es demasiado general, pregunte: “reformule esto basándose en el texto original citado”.
* En PDF escaneados o con una capa de texto de baja calidad, la precisión de la ubicación de citas puede verse afectada; conviene proporcionar también una imagen de la página.
* Para escritura formal, trate las respuestas de IA como apoyo de lectura y tome siempre el texto original del artículo como referencia final.
* Al comparar varios artículos, compruebe primero la evidencia de cada artículo por separado y luego revise la síntesis de BibGenie.
* Cuando encuentre un término desconocido, haga primero clic en la cita para leer el texto original y después pida a BibGenie que explique el contexto.
* Cuando una respuesta implique causalidad, explicación de mecanismos o conclusiones estadísticas, vuelva siempre al párrafo citado para confirmar si el autor realmente lo expresó así.
Es fácil interpretar los marcadores de cita en una respuesta de IA como “insignias de credibilidad”. Al ver `[1]` o `[2]`, uno tiende a sentir que la frase ya está respaldada.
Pero el hábito más eficaz es tratar la cita como una entrada.
Ábrala, vuelva al texto original y confirme tres cosas:
1. Si el texto original trata realmente ese punto.
2. El tono del texto original: si es una conclusión fuerte, una observación débil o una discusión hipotética.
3. Si el resumen de la IA omitió condiciones, alcance o contraejemplos.
Este paso parece costar solo unos segundos más, pero reduce de forma significativa el riesgo de “haber leído sin verificar”. En especial al escribir revisiones, preparar presentaciones de investigación u organizar hipótesis, esta comprobación afecta directamente la fiabilidad del trabajo posterior.
# Precios y Credits (/es/docs/pricing-credits)
BibGenie usa Credits para medir el uso del modelo oficial. Credits no son lo mismo que los recuentos de solicitudes: el costo de una solicitud depende del modelo, la longitud del contexto, la longitud de la salida y el uso de la herramienta.
Todos los planes pueden utilizar OpenAlex, Web Search y Web Extract. En Free, cada llamada correcta a una herramienta externa cuesta 1 Credit; los planes pagos incluyen estas llamadas sin Credits adicionales y ofrecen más Credits mensuales. Max proporciona los Credits mensuales más altos para flujos de trabajo intensivos de lectura, comparación y revisión.
## Comparación de planes [#comparación-de-planes]
| Plan | Precio | Credits mensuales | Capacidades principales |
| :---------- | :----------------- | :------------------- | :------------------------------------------------------------------------------------------- |
| Gratis | $0 | 200 Credits / mes | Funciones principales + OpenAlex, Web Search y Web Extract por 1 Credit por llamada correcta |
| Pro Mensual | $9.99 / mes | 10.000 Credits / mes | Todo en Gratis + sin Credits adicionales por llamadas a herramientas externas |
| Pro Anual | $99 / año | 10.000 Credits / mes | Todo en Pro Mensual |
| Max Mensual | $30 / mes | 35.000 Credits / mes | Todo en Pro + más espacio para lectura profunda, comparación y generación de reseñas |
| Max Anual | $295 / año | 35.000 Credits / mes | Todo en Max Mensual |
| Lifetime | $199 por única vez | 10.000 Credits / mes | Beneficios Pro a largo plazo |
Los precios, descuentos y promociones pueden cambiar. El precio final es el que se muestra en la página de Precios y en Stripe Checkout.
## Credit Booster [#credit-booster]
Los usuarios gratuitos y pagos pueden comprar un paquete de Credit adicional:
| Paquete | Cantidad | Precio | Vencimiento |
| :------- | :----------- | :----- | :---------- |
| Refuerzo | 5000 Credits | $6.99 | 6 meses |
## Cómo se consumen Credits [#cómo-se-consumen-credits]
El uso de Credit se ve afectado principalmente por:
* Elección de modelo: los modelos de mayor coste suelen consumir Credits más rápidamente.
* Longitud de entrada: los archivos PDF, notas, instantáneas, imágenes e historial de chat aumentan los tokens de entrada.
* Longitud de la salida: las reseñas largas, las tablas largas y las notas completas utilizan más tokens.
* Uso de herramientas: la búsqueda, la lectura de archivos adjuntos, la búsqueda web y la extracción web pueden implicar múltiples llamadas de modelo.
* **Herramientas externas**: en Free, cada llamada correcta a OpenAlex, Web Search o Web Extract cuesta **1 Credit**. Los planes pagos incluyen estas llamadas **sin Credits adicionales**. El uso del modelo en la conversación se mide por separado.
* Multiplicador de modelo: etiquetas como `1.5x` o `2x` proporcionan una pista de uso aproximada.
Los modelos personalizados, Ollama y LM Studio no utilizan el servicio de modelo oficial de BibGenie, por lo que no consumen Credits BibGenie. Cualquier costo o uso de cómputo lo maneja su proveedor o su máquina local.
## ¿Cuántos Credits se utilizan para leer un artículo? [#cuántos-credits-se-utilizan-para-leer-un-artículo]
No hay una cantidad fija. El consumo depende del modelo elegido, el contexto de entrada, la longitud de la salida y el precio actual del modelo. Consulta la página Usage para ver el cargo exacto registrado para cada solicitud.
## ¿Qué sucede cuando se agota Credits? [#qué-sucede-cuando-se-agota-credits]
Si su saldo de Credits es insuficiente, es posible que las solicitudes de modelos oficiales no continúen. Puede:
* Espere la próxima actualización mensual.
* Actualice a Pro, Max o Lifetime.
* Compre un Refuerzo de Credits.
* Utilice BYOK o un modelo local.
## Consultar su saldo [#consultar-su-saldo]
Después de iniciar sesión, BibGenie sincroniza el estado de su cuenta y el saldo de Credits. También puede consultar su saldo desde el área de cuenta del sitio web o la página de usuario del complemento.
# Indicaciones rápidas (/es/docs/quick-prompts)
Las indicaciones rápidas son atajos reutilizables para tareas de investigación recurrentes. Guarde las indicaciones que utiliza con frecuencia, insértelas rápidamente en el cuadro de entrada y adáptelas al contexto actual.
## ¿Para qué sirven las indicaciones rápidas? [#para-qué-sirven-las-indicaciones-rápidas]
Resumir las preguntas de investigación, los métodos, las contribuciones, las limitaciones y el trabajo futuro.
Traduzca texto seleccionado, pule párrafos en inglés o ajusta el tono académico.
Extraiga reclamaciones, genere tablas comparativas y organice el trabajo relacionado.
Analizar supuestos, debilidades metodológicas, solidez de la evidencia y reproducibilidad.
## Crear un mensaje rápido [#crear-un-mensaje-rápido]
Abra BibGenie y vaya a **Configuración de mensajes**.
Haga clic en el botón Agregar para crear un nuevo mensaje rápido.
Introduzca un nombre, contenido del mensaje, descripción y etiquetas.
Utilice el interruptor para controlar si aparece en la página de chat.
Guarde su configuración y vuelva al chat.
## Utilice un mensaje rápido [#utilice-un-mensaje-rápido]
En la página de chat, haga clic en un mensaje rápido o búsquelo en el menú de mensajes. Una vez insertado, pasa a formar parte de la entrada actual, por lo que puede continuar editándolo, agregar contexto o especificar un formato de salida.
Ejemplo:
```text
Based on the paper I added, please use the following structure:
1. Research question
2. Method and data
3. Core findings
4. Limitations
5. How I might cite this paper
```
## Indicaciones rápidas versus instrucciones personalizadas [#indicaciones-rápidas-versus-instrucciones-personalizadas]
| Tipo | Alcance | Lo mejor para |
| :--------------------------- | :------------------------------------------- | :----------------------------------------------------------------------- |
| Indicaciones rápidas | La entrada actual | Plantillas de tareas como resumen, traducción, comparación y extracción. |
| Instrucciones personalizadas | Preferencias de comportamiento a largo plazo | Preferencias de idioma, tono, función y formato de respuesta |
Coloque preferencias personales estables en Instrucciones personalizadas y flujos de trabajo específicos de tareas en Avisos rápidos.
## Aviso del sistema [#aviso-del-sistema]
Las indicaciones del sistema guían el comportamiento general de la IA en todas las conversaciones. A diferencia de las indicaciones rápidas (que se aplican a la entrada actual), una indicación del sistema tiene efecto **globalmente**: cada conversación sigue la misma instrucción.
Por ejemplo, configurar el mensaje del sistema para:
```text
Always respond in English. Use academic writing conventions appropriate for computer science.
```
significa que cada respuesta seguirá esta instrucción sin necesidad de repetirla.
Puede configurar un mensaje del sistema en **Configuración de mensajes**. El valor predeterminado es `Always respond in English.`. Puede cambiarlo para que coincida con su idioma de respuesta, tono, función o estilo de formato preferido.
## Configuración rápida de avisos [#configuración-rápida-de-avisos]
Cada mensaje rápido tiene los siguientes campos:
Requerido. Cuando está habilitado, este nombre se muestra como un botón encima del cuadro de entrada del chat.
Requerido. El texto que se enviará al modelo de IA como contexto.
Opcional. Describe el propósito del mensaje, que se muestra al pasar el mouse.
Opcional. Se utiliza para categorizar y filtrar cuando se administran muchas indicaciones.
## Plantillas de ejemplo [#plantillas-de-ejemplo]
```text
Read the paper I added and summarize it using this structure:
- Research question
- Core hypothesis
- Method and data
- Main findings
- Limitations
- Relevance to my current research
```
```text
Explain the selected text I added:
- What is the passage saying?
- What are the key concepts?
- How does it relate to the paper's main argument?
- What should I be careful about if I cite it?
```
```text
Extract material from these papers for a literature review:
- Core claim of each paper
- Agreements and disagreements between papers
- Themes that can be synthesized
- Remaining research gaps
```
# Guardar como nota (/es/docs/save-as-note)
Guardar como nota convierte respuestas BibGenie útiles en notas Zotero que puede conservar, buscar y reutilizar en su flujo de trabajo de investigación.
## Dos formas de ahorrar [#dos-formas-de-ahorrar]
Dígale a BibGenie: "Guarde el resumen anterior como una nota para este documento".
Haga clic en **Guardar como nota** en el último mensaje del asistente para guardar la última respuesta.
## Contenido admitido [#contenido-admitido]
BibGenie convierte contenido Markdown/HTML en notas Zotero. El contenido compatible común incluye:
* Encabezados y párrafos
* Listas ordenadas y desordenadas
* Fórmulas matemáticas
* Bloques de código
* Mesas
* Citas y enlaces
* Texto en negrita y código en línea
Las notas Zotero tienen su propio editor y soporte HTML. Los formatos más comunes funcionan bien, pero se pueden simplificar Markdown muy complejo o HTML personalizado.
## Lógica del elemento principal [#lógica-del-elemento-principal]
Al guardar una nota, BibGenie la coloca en la ubicación más adecuada que puede determinar.
| Aporte | Resultado |
| :--------------------------------------------------- | :------------------------------------------------------------------------------------------------------------------- |
| Artículo normal especificado | Crea una nota secundaria debajo de ese elemento. |
| Archivo adjunto PDF especificado | Encuentra el elemento principal habitual del archivo adjunto cuando es posible y adjunta la nota allí |
| Nota infantil especificada | Encuentra el elemento principal habitual de la nota secundaria cuando es posible y adjunta la nota allí |
| Ningún padre especificado | Crea una nota independiente |
| Tanto el padre como la colección están especificados | La colección se ignora porque Zotero notas secundarias heredan la membresía de la colección de su elemento principal |
## Ejemplos [#ejemplos]
```text
Save the paper summary above as a Zotero note for this item, titled "Paper Summary".
```
```text
Turn the comparison above into a literature review note and save it to Zotero.
```
```text
Convert the method section into reproducible experimental steps and save it as a note. Preserve code blocks and tables.
```
## Consejos [#consejos]
* Pídale a BibGenie que estructure la respuesta antes de guardarla.
* Para conversaciones largas, primero pídale a BibGenie que "reescriba esto como una nota" y luego guárdela.
* Si la nota debe pertenecer a un artículo específico, nombre explícitamente el elemento de destino.
* Si desea una nota independiente, indique que no debe adjuntarse a un documento.
# Índice semántico (/es/docs/semantic-index)
El índice semántico impulsa la búsqueda de literatura semántica de BibGenie. Indexa localmente los títulos y resúmenes de los elementos habituales de Zotero, por lo que puede describir un tema de investigación en lenguaje natural en lugar de depender únicamente de palabras clave.
## ¿Qué indexa? [#qué-indexa]
El índice semántico actualmente se centra en elementos regulares de Zotero:
* Título
* Resumen
* Metadatos seleccionados útiles para la búsqueda
La búsqueda semántica no es lo mismo que la búsqueda de texto completo en PDF. Si un artículo no tiene resumen o tiene metadatos incompletos, la coincidencia semántica puede ser menos precisa.
## Referencia de estado [#referencia-de-estado]
| Estado | Significado |
| :----------- | :------------------------------------------------------ |
| arranque | La capacidad de indexación se está inicializando |
| indexación | El índice se está construyendo. |
| actualizando | Las entradas de índice existentes se están actualizando |
| inactivo | El índice está listo. |
| error | Se produjo un error de indexación |
## Métrica [#métrica]
| Métrico | Significado |
| :---------------- | :-------------------------------------------- |
| Recuento indexado | Número de elementos indexados correctamente |
| Conteo fallido | Número de elementos que no pudieron indexarse |
| Mensaje | Estado actual o mensaje de error |
## Cuándo comprobar el índice semántico [#cuándo-comprobar-el-índice-semántico]
* La búsqueda semántica arroja muy pocos resultados.
* BibGenie informa que el índice semántico no está disponible.
* Los artículos recién importados no aparecen en la búsqueda semántica.
* El recuento fallido sigue aumentando.
* Zotero acaba de comenzar y el índice aún se está iniciando o indexando.
## Solución de problemas [#solución-de-problemas]
Abra Preferencias y verifique el estado del índice semántico.
Si se está indexando o actualizando, espere a que finalice.
Si hay elementos fallidos, vuelva a intentar la indexación fallida.
Compruebe si los artículos relevantes tienen títulos y resúmenes.
Si las fallas continúan, reinicie Zotero y verifique nuevamente.
## Consejos [#consejos]
* Los resúmenes completos mejoran la calidad de la búsqueda semántica.
* Utilice descripciones en lenguaje natural en lugar de solo palabras clave.
* Combine la búsqueda semántica con filtros de año, etiqueta o colección.
* Después de encontrar los artículos candidatos, agregue los archivos PDF o las notas como contexto para una lectura profunda.
# Cómo BibGenie entiende su biblioteca (/es/docs/semantic-understanding)
## Por qué existe esta página [#por-qué-existe-esta-página]
Cuando busca en BibGenie, el objetivo no es solo encontrar papers que contengan exactamente las mismas palabras que escribió. En muchos casos, desea que BibGenie encuentre papers que **tratan sobre la misma idea**, incluso si usan terminología diferente.
Ahí es donde entran las **incrustaciones** y la **indexación**.
## ¿Qué es una incrustación? [#qué-es-una-incrustación]
Una incrustación es una forma de convertir un fragmento de texto en una representación numérica que captura su significado.
No es necesario pensar en las matemáticas detrás de esto. La idea práctica es simple:
* Texto similar tiende a producir incrustaciones similares
* Diferentes temas tienden a producir incrustaciones más distantes
* Esto permite a BibGenie comparar el significado, no solo la redacción exacta.
Por ejemplo, es posible que aún se encuentre un artículo sobre *descubrimiento de fármacos con gráficos de conocimiento* cuando se busca *métodos gráficos para investigación biomédica*, incluso si la redacción no es idéntica.
## Cómo BibGenie usa incrustaciones [#cómo-bibgenie-usa-incrustaciones]
Actualmente, BibGenie crea búsquedas semánticas a partir del **título** y el **resumen** de sus elementos Zotero habituales.
El proceso es:
1. BibGenie lee el título y el resumen de un artículo.
2. Convierte ese texto en una incrustación.
3. Almacena el resultado en un índice de búsqueda local para su biblioteca de Zotero.
4. Cuando hace una pregunta de estilo de tema, BibGenie también convierte su consulta en una incrustación.
5. Compara su consulta con los papers indexados y devuelve las coincidencias más cercanas.
Esta es la razón por la que la búsqueda semántica puede revelar papers que son relevantes por su significado, no sólo por su redacción.
## ¿Qué es la indexación? [#qué-es-la-indexación]
La indexación es el paso de preparación que hace que la búsqueda semántica sea rápida y práctica.
En lugar de volver a calcular todo cada vez que realiza una búsqueda, BibGenie primero prepara un índice local de incrustaciones para su biblioteca. Una vez que existe ese índice, BibGenie puede buscar en sus documentos de manera mucho más eficiente.
En breve:
* **Incrustar** ayuda a BibGenie a representar el significado
* **La indexación** ayuda a BibGenie a buscar ese significado rápidamente
## ¿En qué ayuda esto? [#en-qué-ayuda-esto]
La indexación semántica es especialmente útil cuando se desea:
* Encuentre papers relacionados con un tema de investigación.
* Descubra trabajos que utilizan diferentes palabras para una idea similar
* Explorar un método, teoría o área problemática.
* Busque una biblioteca grande Zotero de forma más natural
La búsqueda de palabras clave sigue siendo útil cuando conoce el autor, título, término o frase exactos. La búsqueda semántica es más útil cuando la pregunta es conceptual.
## ¿Qué contenido está incluido? [#qué-contenido-está-incluido]
BibGenie utiliza actualmente:
* Títulos de artículos
* Resúmenes de artículos
BibGenie actualmente **no** construye este índice semántico a partir de:
* PDF texto completo
* Notas
* Anotaciones
* Adjuntos
Esto ayuda a mantener la indexación enfocada, predecible y rápida.
## ¿Necesito reconstruir el índice con frecuencia? [#necesito-reconstruir-el-índice-con-frecuencia]
Generalmente, **no**.
La mayoría de las veces, BibGenie maneja las actualizaciones de indexación automáticamente en segundo plano a medida que cambia su biblioteca. Si agrega documentos, modifica registros o elimina elementos, BibGenie generalmente se encargará de las actualizaciones necesarias por usted.
Es posible que desee reconstruir el índice en algunas situaciones:
* La primera vez que configura la indexación semántica
* Después de cambiar a un modelo de incrustación diferente
* Después de una importación grande, si los resultados parecen incompletos o desactualizados
* Si BibGenie le dice que el índice actual necesita atención
* Si los resultados semánticos parecen claramente incorrectos y desea una reconstrucción limpia
Si la búsqueda semántica funciona normalmente, normalmente no es necesario hacer nada. Reconstruya solo cuando la aplicación lo sugiera o cuando los resultados ya no coincidan con sus expectativas.
## ¿Qué significan los botones en la página de Indexación? [#qué-significan-los-botones-en-la-página-de-indexación]
### Construir / Reconstruir [#construir--reconstruir]
Esto crea el índice por primera vez o lo reconstruye desde cero cuando es necesario.
Úselo cuando:
* está configurando la indexación por primera vez.
* Cambiaste los modelos de incrustación
* quiere actualizar todo el índice
### Reintentar elementos fallidos [#reintentar-elementos-fallidos]
Esto solo reintenta los trabajos que fallaron durante intentos de indexación anteriores.
Úselo cuando:
* El recuento de elementos fallidos es mayor que cero.
* Quiere un paso de recuperación más ligero antes de intentar una reconstrucción completa
## Preguntas comunes [#preguntas-comunes]
La búsqueda de palabras clave busca palabras coincidentes. La búsqueda semántica busca significados relacionados. Por eso, la búsqueda semántica puede devolver papers que son relevantes incluso cuando la redacción es diferente.
Sin incrustaciones, BibGenie dependería principalmente de términos exactos. Las incrustaciones permiten buscar por tema, concepto y similitud semántica.
Es posible que un artículo aún no haya sido indexado, que no contenga suficiente título o contenido abstracto, o que el índice necesite atención. Si el problema persiste, intente reconstruir el índice.
No. En uso normal, BibGenie está diseñado para actualizar el índice automáticamente. La reconstrucción manual es principalmente para la primera configuración, cambios de modelo y escenarios de recuperación.
## Próximos pasos [#próximos-pasos]
* Verifique el estado del índice y solucione problemas: [Semantic Index](/docs/semantic-index)
* Aprenda a utilizar la búsqueda semántica en la práctica: [Literature Search](/docs/literature-search)
# Web Search y Web Extract (/es/docs/web-search-extract)
De forma predeterminada, BibGenie busca y lee primero su biblioteca de Zotero. Web Search / Web Extract están disponibles para todos los usuarios y permiten complementar su biblioteca con información de la web pública.
En Free, cada llamada correcta a Web Search o Web Extract cuesta **1 Credit**. Los planes pagos incluyen estas llamadas a herramientas externas **sin Credits adicionales**. El uso del modelo en la conversación puede seguir consumiendo Credits normalmente.
## Web Search frente a Web Extract [#web-search-frente-a-web-extract]
Busca en la web pública y devuelve extractos clasificados y legibles por IA.
Lee una página web específica y extrae su contenido principal para la conversación.
## Cuándo utilizar el acceso web [#cuándo-utilizar-el-acceso-web]
Web Search / Web Extract es útil cuando necesita:
* Busque la página del proyecto, el repositorio de códigos o la página del conjunto de datos de un artículo.
* Reúna información de antecedentes reciente.
* Lea la documentación pública de un modelo, herramienta, institución o producto.
* Información complementaria que aún no está en su biblioteca de Zotero.
* Resumir, extraer o comparar el contenido de una página web.
El contenido web puede cambiar y puede ser inexacto. Para citas formales, verifique la información con el artículo original, la documentación oficial u otra fuente autorizada.
## Cómo encenderlo [#cómo-encenderlo]
Inicie sesión en su cuenta de BibGenie.
Busque el botón **Web Search** debajo del cuadro de entrada del chat.
Haga clic en el botón para activar o desactivar la búsqueda web.
Cuando esté habilitado, solicite explícitamente a BibGenie que busque en la web o lea una página web.
## Ejemplos [#ejemplos]
```text
Search the web to see whether this paper has an official project page, code repository, or dataset page.
```
```text
Read this web page and summarize the parts relevant to my paper topic:
https://example.com
```
```text
First search my Zotero library, then search the web for recent developments in this area.
```
## Nota de privacidad [#nota-de-privacidad]
Las herramientas web acceden a páginas web públicas. Evite incluir material sensible, inédito o confidencial en solicitudes que requieran acceso a la web. Para trabajos privados, utilice el contexto de biblioteca de Zotero, el contexto local, BYOK o modelos locales.
# Anotaciones de Zotero (/es/docs/zotero-annotations)
BibGenie puede trabajar directamente con anotaciones guardadas de Zotero, incluidos resaltados, comentarios, imágenes, trazos y subrayados. Puede recuperar las anotaciones de un archivo adjunto conocido o buscarlas en toda la biblioteca, manteniendo un enlace rastreable a Zotero.
## Dos herramientas de anotaciones [#dos-herramientas-de-anotaciones]
| Herramienta | Cuándo usarla | Alcance y filtros |
| :------------------- | :-------------------------------------- | :---------------------------------------------------------------------------------------------------- |
| `get_annotations` | Conoces el PDF, EPUB o snapshot adjunto | Devuelve sus anotaciones en orden de lectura |
| `search_annotations` | Necesitas buscar en toda la biblioteca | Texto resaltado, comentario, etiqueta, color, tipo, autor, adjunto, colección y fecha de modificación |
Los resultados están paginados y BibGenie solo obtiene la página siguiente cuando es necesario.
`get_annotations` trabaja con un archivo adjunto, no con su item bibliográfico principal. BibGenie identifica primero el adjunto si partes de un item normal de Zotero.
## Añadir al chat [#añadir-al-chat]
* En el lector de Zotero, selecciona una o varias anotaciones guardadas, haz clic derecho y elige **Add to Chat**.
* En la biblioteca, selecciona items de anotación y elige **Add to Chat**.
* **Reader Annotations** y **Library Items** en [Add to Chat Settings](/es/docs/add-to-chat-settings) controlan estas entradas.
Los comentarios son interpretaciones de sus autores y no deben atribuirse al documento fuente. Para saber cómo funcionan las citas, consulte [BibGenie Citation](/es/docs/bibgenie-citations).
Al hacer clic en una referencia se abre el archivo adjunto principal y se intenta navegar a la anotación. BibGenie no edita ni elimina anotaciones existentes. Las anotaciones de imagen o tinta pueden contener poco texto que se pueda buscar.
# Guía de colecciones y etiquetas de Zotero (/es/docs/zotero-collections-tags-best-practices)
Las colecciones y etiquetas de Zotero ayudan a organizar las referencias, pero resuelven diferentes problemas. Una biblioteca de Zotero mantenible rara vez se basa solo en colecciones o solo en etiquetas. En su lugar, utilice colecciones como puntos de entrada de proyectos o temas, etiquetas como dimensiones de búsqueda entre colecciones y búsquedas guardadas para flujos de trabajo dinámicos.
Si utiliza BibGenie, esta guía es más que una metodología de "cómo organizar": se convierte en un flujo de trabajo procesable. La función Organización de la biblioteca de BibGenie puede inventariar sus colecciones, etiquetas y elementos existentes, proponer un plan de organización basado en su sistema de investigación y luego (después de su confirmación) crear colecciones por lotes, agregar o eliminar etiquetas, mover elementos y cambiar el nombre o fusionar etiquetas desordenadas.
Las colecciones responden "¿A qué proyecto, curso, revisión o tema de entrada pertenecen estas referencias?" Las etiquetas responden "¿Qué características, métodos, estados, objetos o casos de uso tiene esta referencia?"
Zotero proporciona las capacidades de organización básicas: colecciones y etiquetas. La función de organización de la biblioteca de BibGenie actúa como su asistente de organización de la biblioteca: primero comprende cómo se organiza, luego propone un plan revisable y finalmente lo ejecuta después de su aprobación.
Para obtener una introducción completa a las capacidades de organización de la biblioteca de BibGenie y ejemplos de indicaciones, consulte la [documentación de Library Management](https://www.bibgenie.com/docs/library-management).
## Referencia rápida [#referencia-rápida]
Si recién está comenzando a organizar su Zotero, siga estas reglas:
| Guión | Recomendado | Cómo ayuda BibGenie |
| :------------------------------------------------------------------------------- | :-------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------ |
| Trabajo, curso, proyecto, tesis, disertación. | Recopilación | Genere una estructura de colección de proyectos a partir de elementos seleccionados y agregue referencias a la colección coincidente. |
| Tema de investigación, método, tipo de datos, región, marco teórico. | Etiqueta | Lea títulos, resúmenes y metadatos, y sugiera etiquetas coherentes de tema/método/estado. |
| `to-read`, `read`, `important`, `reviewed` | Etiqueta de color o etiqueta lisa | Agregue o elimine etiquetas de estado por lotes para su flujo de trabajo de lectura actual |
| Agregado recientemente (7 días), no leído, falta DOI, combinaciones de etiquetas | Búsqueda guardada | Ayudar a diseñar criterios de búsqueda y seguimiento de reglas de organización. |
| Reseña de libro y el libro reseñado, distintas versiones de una misma obra | Artículos relacionados | Identifique entradas potencialmente relacionadas, aunque es mejor dejar el establecimiento de relaciones para la confirmación manual. |
| Demasiadas subcolecciones anidadas | Evitar | Identifique colecciones demasiado profundas, fragmentadas o duplicadas y sugiera fusionarlas |
## Qué puede hacer la organización bibliotecaria de BibGenie [#qué-puede-hacer-la-organización-bibliotecaria-de-bibgenie]
Al organizar manualmente colecciones y etiquetas Zotero, la parte que requiere mucho tiempo no es hacer clic en los botones, sino decidir: qué etiquetas están duplicadas, qué elementos pertenecen a qué colección, qué metadatos faltan y qué operaciones afectan a demasiados elementos. Ahí es donde brilla la función Organización de la biblioteca de BibGenie.
| Tarea | Qué puede hacer BibGenie |
| :---------------------------------- | :----------------------------------------------------------------------------------------------------------------------------------------------------- |
| Auditar la estructura existente | Jerarquía de colecciones de listas, vocabulario de etiquetas, elementos de una colección o etiqueta específica |
| Encuentra elementos para organizar | Localice elementos no archivados, referencias agregadas recientemente, entradas a las que les falta DOI/resumen, elementos por etiqueta o colección |
| Diseñar un esquema de organización. | Proponer un sistema de clasificación basado en títulos, resúmenes, metadatos, etiquetas existentes y colecciones. |
| Artículos organizados por lotes | Agregar o eliminar etiquetas, agregar o eliminar de colecciones para elementos específicos |
| Crear colecciones | Cree nuevas colecciones bajo el padre correcto y, opcionalmente, coloque elementos candidatos dentro |
| Limpiar etiquetas | Cambiar el nombre de las etiquetas, fusionar etiquetas antiguas con las existentes, eliminar etiquetas no utilizadas en toda la biblioteca |
| Organizar colecciones | Cambiar el nombre de las colecciones, mover colecciones, eliminar colecciones vacías o no utilizadas (eliminar una colección no elimina sus elementos) |
| Verificar metadatos | Lea metadatos completos, identifique campos faltantes y ayude a corregirlos cuando haya fuentes confiables disponibles |
Modificar metadatos, crear colecciones, mover elementos, editar etiquetas por lotes, cambiar el nombre o eliminar colecciones/etiquetas son todas operaciones de escritura. BibGenie propondrá acciones y esperará su aprobación. Nunca debería modificar su biblioteca de Zotero sin una confirmación explícita.
Una buena solicitud de organización BibGenie debe incluir alcance, objetivo y limitaciones:
```text
Please organize the currently selected items. First read the existing collections and tags, then propose an organization plan based on titles, abstracts, and metadata.
Prefer reusing existing collections and tags; only suggest creating new ones if there is genuinely no suitable place.
Do not modify Zotero yet. First output which items will be affected, which tags will be added, and which collections will be used.
```
El principio detrás de este mensaje es el flujo de trabajo principal de la función Organización de la biblioteca de BibGenie: primero descubra el estado actual, luego identifique los elementos para organizar, luego proponga un plan y finalmente ejecútelo.
## ¿Qué son las colecciones? [#qué-son-las-colecciones]
Las colecciones son las carpetas y subcarpetas en la barra lateral izquierda de Zotero. La documentación oficial de Zotero recomienda pensar en las colecciones como "listas de reproducción" en lugar de carpetas del sistema de archivos: el mismo elemento puede aparecer en varias colecciones sin duplicar la referencia. La verdadera biblioteca completa sigue siendo `My Library` o la biblioteca del grupo correspondiente.
Las colecciones funcionan mejor como puntos de entrada. Por ejemplo:
* `PhD Thesis`
* `2026 Systematic Review`
* `Course - Research Methods`
* `Project - AI Literature Review`
* `Topic - Retrieval-Augmented Generation`
La ventaja es la claridad, la visibilidad y la preparación para el proyecto. Abra una colección y verá las referencias principales necesarias para ese trabajo en este momento.
Cuando utilice BibGenie, pídale que redacte una estructura de colección alineada con los objetivos de su proyecto antes de mover elementos:
```text
Please list my existing collections first, then decide whether the selected items can fit into existing collections.
If the existing structure isn't sufficient, design a one-to-two-level collection draft for my "literature review writing project."
Output each collection's purpose and the proposed items it would contain. Do not modify Zotero.
```
Al eliminar una colección normal, solo se elimina este punto de entrada organizacional, no los elementos que contiene. Para eliminar realmente elementos, debe moverlos a la Papelera. Esta distinción es importante para los nuevos usuarios.
Esta es también la razón por la que BibGenie le advierte explícitamente al eliminar una colección: eliminar una colección solo elimina la entrada de la organización; Los elementos permanecen en la biblioteca de Zotero. Si una colección tiene subcolecciones, BibGenie se negará a eliminar la principal directamente y le pedirá que decida cómo manejar las subcolecciones primero.
## ¿Qué son las etiquetas? [#qué-son-las-etiquetas]
Las etiquetas son etiquetas de texto adjuntas a elementos, archivos adjuntos y notas. No tienen jerarquía pero pueden describir el mismo artículo desde múltiples ángulos. La documentación oficial de Zotero señala que las etiquetas se pueden usar para tema, método, estado, calificación o flujo de trabajo personal.
Las etiquetas funcionan mejor como dimensiones. Por ejemplo:
* Tema: `llm-agent`, `scientific-discovery`, `citation-network`
* Método: `survey`, `experiment`, `meta-analysis`, `case-study`
* Objeto: `clinical-trial`, `graduate-students`, `zotero-users`
* Estado: `to-read`, `read`, `skimmed`, `cited`
* Uso: `intro-section`, `related-work`, `method-baseline`
El poder de las etiquetas reside en la búsqueda combinatoria. Puede filtrar dentro de una colección los elementos etiquetados con `llm-agent` y `survey`, o buscar en toda su biblioteca todo lo etiquetado con `to-read` y `citation-network`.
El punto fuerte de BibGenie es que sugiere etiquetas por lotes según el contenido del artículo. Comience pidiéndole que analice solo:
```text
Please list my existing tags first, then review the titles, abstracts, and existing tags of items in this collection.
Prefer reusing existing tags; only suggest new tags when no suitable one exists.
Finally, present recommended tags to keep, merge, add, and delete in a table. Do not modify Zotero.
```
## Colecciones vs Etiquetas [#colecciones-vs-etiquetas]
| Dimensión | Colecciones | Etiquetas |
| :-------------------------------------- | :-------------------------------------------------------- | :-------------------------------------------------------- |
| Organización | Jerárquico con subcolecciones | Plano, sin subetiquetas nativas |
| Lo mejor para expresar | Proyectos, cursos, artículos, puntos de entrada de temas. | Tema, método, estado, calidad, atributos de casos de uso. |
| ¿Puede un elemento aparecer en varios? | Sí | Sí |
| Se conserva al copiar entre bibliotecas | Por lo general no | Generalmente sí con el artículo. |
| Hojeada | Fuerte | Moderado |
| Filtrado cruzado | Moderado | Fuerte |
| Riesgo de mantenimiento | hinchazón de colección | Sinónimos de etiquetas y deriva ortográfica |
| Granularidad recomendada | Pocos, estables | Puede ser mejor, pero los nombres deben ser consistentes |
Si ya tiene una colección `Topic - LLM Agents`, no necesariamente necesita etiquetar todos los elementos que contiene con `llm-agents`, a menos que desee buscar ese tema en otras colecciones.
Cuando utilice BibGenie para organizar, agregue este principio a su mensaje:
```text
Please avoid making tags and collections fully redundant. Don't mechanically add the same tag to every item when the collection already expresses the project membership. Only add topic tags when cross-collection search is needed.
```
## Modelo de organización recomendado [#modelo-de-organización-recomendado]
Para la mayoría de los investigadores, una estructura sólida Zotero tiene tres capas.
### 1. Algunas colecciones de alto nivel para grandes direcciones [#1-algunas-colecciones-de-alto-nivel-para-grandes-direcciones]
No cree demasiadas colecciones de nivel superior. Diseñelos como puntos de entrada a los que no cambiará el nombre con frecuencia:
```text
My Library
Inbox
Thesis
Papers
Projects
Topics
Teaching
Archive
```
O más estrechamente alineado con su dominio de investigación:
```text
My Library
Domain - AI for Science
Domain - Bibliometrics
Domain - Human-Computer Interaction
Project - BibGenie SEO
Project - Zotero flujo de trabajo Study
```
### 2. Uno o dos niveles de subcolecciones para proyectos [#2-uno-o-dos-niveles-de-subcolecciones-para-proyectos]
No profundice indefinidamente. Normalmente dos niveles son suficientes:
```text
Project - Systematic Review
01 Search Results
02 Screening
03 Included Studies
04 Background Reading
05 Cited in Manuscript
```
Esta estructura se adapta al flujo de trabajo de la investigación, lo que la hace más práctica para la escritura real que una docena de subdivisiones basadas en temas.
### 3. Etiquetas como dimensiones transversales componibles [#3-etiquetas-como-dimensiones-transversales-componibles]
Las etiquetas no deberían reemplazar todas las colecciones. Son mejores para registrar "qué más se puede buscar en este documento":
```text
method:survey
method:experiment
topic:semantic-search
topic:zotero
status:to-read
status:read
use:background
use:key-citation
```
Zotero no tiene etiquetas jerárquicas nativas, pero puede simular espacios de nombres con prefijos como `method:`, `topic:`, `status:`. Esto reduce la ambigüedad y facilita el escaneo en el selector de etiquetas.
## Convenciones de nomenclatura de etiquetas [#convenciones-de-nomenclatura-de-etiquetas]
Un buen sistema de etiquetas no se trata de tener más etiquetas; se trata de ser consistente.
| Regla | Recomendado | No recomendado |
| :---------------------------------------------------------------- | :------------------ | :------------------------------------- |
| Usar minúsculas | `semantic-search` | `Semantic Search`, `semantic Search` |
| Utilice guiones para palabras compuestas | `citation-network` | `citation network`, `citation_network` |
| Categorías de prefijo | `method:survey` | Mixto `survey`, `surveys` |
| Mantenga las etiquetas de estado consistentes | `status:to-read` | Mixto `unread`, `to read`, `todo` |
| Evite etiquetas demasiado amplias | `topic:llm-agent` | `ai`, `paper`, `research` |
| Evite etiquetas demasiado temporales que contaminen la biblioteca | `use:intro-section` | `maybe-use-in-chapter-2-later` |
Si ya tiene etiquetas duplicadas, cambie el nombre de la etiqueta anterior al nombre de destino en el selector de etiquetas para fusionarlas. Por ejemplo, cambie el nombre de `to read` a `status:to-read`.
Si las etiquetas ya están desordenadas, pídale a BibGenie que primero realice una auditoría de etiquetas:
```text
Please list the current library's tags and identify potentially duplicate or synonymous tags — for example, different casing, spaces vs hyphens, singular vs plural.
Give merge suggestions and note how many items each tag affects.
Do not execute any renaming or deletion yet.
```
Luego confirme antes de ejecutar:
```text
I confirm the merge plan. Please rename the tag `to read` to `status:to-read`.
If `status:to-read` already exists, merge the two tags. Before executing, confirm how many items will be affected.
```
El cambio de nombre y la fusión de etiquetas de BibGenie no recorre los elementos uno por uno; utiliza las operaciones de etiquetas de toda la biblioteca de Zotero. Cuando cambia el nombre de una etiqueta antigua a un nombre de etiqueta existente, Zotero las fusiona. Esto es más confiable y más adecuado para limpiar etiquetas sinónimas acumuladas durante mucho tiempo que agregar manualmente nuevas etiquetas y eliminar las antiguas elemento por elemento.
## Cómo utilizar etiquetas de colores [#cómo-utilizar-etiquetas-de-colores]
Zotero admite la asignación de colores a una pequeña cantidad de etiquetas, que se pueden agregar o eliminar rápidamente con teclas numéricas. La documentación oficial actual establece un máximo de 9 etiquetas de colores.
Las etiquetas de colores son mejores para "estados de alta frecuencia", no para todos los temas:
| Etiqueta de color | Objetivo |
| :----------------- | :--------------------- |
| `status:to-read` | leer |
| `status:reading` | Actualmente leyendo |
| `status:read` | Leer |
| `use:key-citation` | Cita clave |
| `use:write-next` | Para próximos escritos |
Evite asignar estados de etiquetas de colores a etiquetas de temas comunes como `machine-learning`, `history` o `statistics`. Los temas se multiplican con el tiempo, pero los espacios para etiquetas de colores son escasos.
BibGenie no puede decidir qué etiquetas deben ocupar permanentemente sus espacios para etiquetas de colores, pero puede ayudar a identificar las etiquetas similares a estados que usa con más frecuencia y sugerir si se deben consolidar en menos etiquetas de alta frecuencia.
## ¿Debería conservar las etiquetas automáticas? [#debería-conservar-las-etiquetas-automáticas]
Cuando Zotero guarda elementos de bases de datos, sitios web o catálogos de bibliotecas, a veces importa automáticamente títulos de materia o palabras clave. Estas etiquetas automáticas a veces pueden ser útiles, pero a menudo crean ruido: carcasa inconsistente, granularidad desordenada, términos demasiado amplios y etiquetas excesivas.
Estrategias recomendadas:
1. Nuevas bibliotecas u organizadores pesados: desactive las etiquetas automáticas y mantenga las etiquetas principales manualmente.
2. Usuarios médicos, legales y bibliotecológicos que dependen de vocabularios controlados: mantenga las etiquetas automáticas inicialmente y luego limpie periódicamente.
3. Usuarios con una gran acumulación de etiquetas automáticas: primero oculten las etiquetas automáticas y luego elimínenlas por lotes después de confirmar que son inútiles.
Para desactivarlo, vaya a Configuración/Preferencias de Zotero > General y desmarque `Automatically tag items with keywords and subject headings`.
Si no está seguro de qué etiquetas automáticas son valiosas, solicite a BibGenie que las agrupe por frecuencia y semántica:
```text
Please check the current library's tags and list those that may be from automatic import, overly broad, or inconsistently cased. Do not delete anything, just give cleanup suggestions.
```
## Las búsquedas guardadas son una herramienta de organización subestimada [#las-búsquedas-guardadas-son-una-herramienta-de-organización-subestimada]
Las búsquedas guardadas son como "colecciones inteligentes". Almacenan criterios de búsqueda, no resultados fijos, por lo que se actualizan automáticamente a medida que cambia su biblioteca.
Buenos casos de uso para búsquedas guardadas:
* `Unread`: la etiqueta no es `status:read`
* `Recent Additions`: elementos agregados en los últimos 7 días
* `Missing DOI`: elementos donde DOI está vacío
* `Need Review`: elementos etiquetados `status:to-read` en una colección específica
* `Key RAG Papers`: artículos con `topic:rag` y `use:key-citation`
Si utiliza repetidamente los mismos criterios de filtro, considere crear una búsqueda guardada en lugar de una nueva colección estática.
BibGenie es más adecuado para ayudarle a diseñar reglas de búsqueda guardadas que convertir cada tarea dinámica en una colección. Por ejemplo:
```text
I want to create a dynamic view of "unread RAG articles."
Please review my existing tags and collections first, then suggest Zotero saved search criteria.
If existing tags aren't suitable, explain which tags need to be standardized first.
```
BibGenie también puede utilizar un enfoque de búsqueda guardada similar para encontrar elementos para organizar, como "elementos agregados en los últimos 30 días que no se han colocado en ninguna colección", "artículos de revistas a los que les faltan DOI" o "elementos con etiquetas antiguas pero sin etiquetas nuevas". Estas tareas se manejan mejor generando primero una lista de candidatos y luego decidiendo si se realizan cambios por lotes.
## Cómo utilizar elementos relacionados [#cómo-utilizar-elementos-relacionados]
Los elementos relacionados no deben reemplazar etiquetas ni colecciones. Como se discutió en los foros Zotero, el problema con Relacionado es que solo expresa "dos elementos están relacionados" sin aclarar "por qué están relacionados". Por lo tanto, es mejor para relaciones explícitas uno a uno o de pequeña escala:
* Una reseña de un libro y el libro reseñado.
* Un artículo de conferencia y su versión de revista ampliada.
* Un documento de conjunto de datos y el documento de referencia que lo utiliza.
* Una preimpresión, una versión publicada y una corrección del mismo estudio.
* Artículos de fuentes principales discutidos repetidamente en un artículo de revisión
Si simplemente desea expresar "todos estos elementos pertenecen al mismo tema", utilice etiquetas o colecciones.
## Tres flujos de trabajo comunes [#tres-flujos-de-trabajo-comunes]
### Flujo de trabajo A: redacción de un artículo o reseña [#flujo-de-trabajo-a-redacción-de-un-artículo-o-reseña]
Cree una colección para su proyecto de escritura, por ejemplo, `Project - LLM Agent Review`.
Coloque los trabajos de los candidatos en `01 Search Results` o `Inbox` primero.
Utilice etiquetas para marcar temas, métodos y estados, por ejemplo, `topic:tool-use`, `method:benchmark`, `status:to-read`.
Después de la selección, mueva o agregue documentos básicos a `03 Included Studies`.
Utilice `use:key-citation`, `use:intro-section`, `use:method-section` para marcar propósitos de escritura.
Aviso BibGenie adecuado:
```text
Please examine the `Project - LLM Agent Review` collection.
First list the existing subcollections and tags, then classify the papers into five categories following a review writing workflow: search results, screening, included, background, and cited.
Prefer using existing subcollections; justify any new ones needed.
First output a table, do not move any items yet.
```
Después de la confirmación:
```text
I confirm this classification table. Please add these items to the corresponding collections per the table, and add the `use:key-citation` tag to core articles.
After completion, summarize how many items were modified, which collections were used, and which tags were added.
```
### Flujo de trabajo B: creación de un dominio de investigación a largo plazo [#flujo-de-trabajo-b-creación-de-un-dominio-de-investigación-a-largo-plazo]
Cree una colección a largo plazo, por ejemplo, `Domain - AI for Science`.
Cree una cantidad limitada de subcolecciones solo cuando sea realmente necesario, por ejemplo, `Foundation Papers`, `Benchmarks`, `Applications`.
Utilice etiquetas detalladas para registrar temas, métodos, conjuntos de datos y sujetos experimentales.
Verifique periódicamente `Unfiled Items` y agregue elementos huérfanos a las colecciones apropiadas o elimínelos.
Aviso BibGenie adecuado:
```text
Please analyze the items in `Domain - AI for Science`.
First read the existing tags, identify 5 to 8 stable research topics, and suggest corresponding `topic:` tags.
Avoid creating too many subcollections; prefer tags unless a topic will be maintained separately long-term.
```
### Flujo de trabajo C: usuarios ligeros [#flujo-de-trabajo-c-usuarios-ligeros]
Si no desea mantener un sistema complejo, siga estas reglas mínimas:
* Colecciones: Crear por proyecto o curso.
* Etiquetas: utilice solo de 5 a 15 estados o temas de alta frecuencia.
* Etiquetas de colores: Solo marca `to-read`, `read`, `important`.
* Limpieza mensual: etiquetas automáticas, duplicados y elementos sin archivar.
Un sistema liviano que se mantiene es más confiable que uno complejo que no se mantiene.
Los usuarios ligeros aún pueden usar BibGenie, pero la atención debe centrarse en reducir los gastos generales de mantenimiento, no en generar más etiquetas:
```text
Please classify the currently selected items into only three statuses: `status:to-read`, `status:reading`, `status:read`. If you can't determine the status, put it in `status:to-read` and show a preview first.
```
## Lista de verificación de mantenimiento mensual [#lista-de-verificación-de-mantenimiento-mensual]
Realizar Zotero limpieza de la biblioteca mensualmente:
* Abra `Unfiled Items` y procese elementos que no estén en ninguna colección.
* Abra `Duplicate Items` y combine duplicados en lugar de eliminar uno.
* Consulte el selector de etiquetas para ver si hay etiquetas sinónimas, por ejemplo, `methods` y `research-methods`.
* Oculta o elimina etiquetas automáticas inútiles.
* Verifique los elementos agregados recientemente para ver si el título, el autor, el año, el DOI y el resumen están limpios.
* Elimine las subcolecciones temporales que hayan perdido su propósito para evitar un aumento excesivo de la colección.
Pídale a BibGenie que enumere los elementos candidatos y los cambios propuestos antes de ejecutar adiciones de etiquetas por lotes, creaciones de colecciones, movimientos de elementos o comprobaciones de metadatos. Para cualquier operación por lotes, primero obtenga una vista previa y alcance su alcance, por ejemplo, "procesar solo los elementos seleccionados actualmente" o "procesar solo esta colección".
Un mensaje de organización mensual sólido BibGenie:
```text
Please help me with Zotero library housekeeping:
1. First list existing collections and tags.
2. Check for unfiled items, duplicate or synonymous tags, overly deep collections, and recently added unorganized items.
3. When checking items missing DOI or abstract, consider the item type to determine whether a DOI is actually expected.
4. Only output the problem list, impact scope, and suggested actions. Do not modify Zotero.
```
Si desea colocar elementos sin archivar en ubicaciones apropiadas, solicite a BibGenie que ejecute una tarea más específica:
```text
Please find the most recent 50 unfiled items and determine which collections they best fit into based on existing collections.
Do not create new collections unless the existing structure clearly has no suitable place.
First output each item, the suggested collection, the reason, and your confidence level.
```
## Errores comunes [#errores-comunes]
### Error 1: utilizar colecciones como único sistema de organización [#error-1-utilizar-colecciones-como-único-sistema-de-organización]
Si crea una subcolección para cada tema menor, terminará con docenas o cientos de colecciones después de unos años. Los objetos quedan enterrados en árboles profundos, lo que hace que sea más difícil encontrarlos.
Cuando utilice BibGenie, no le pida que cree colecciones para cada tema pequeño. Una mejor instrucción: "Cree colecciones únicamente para proyectos, cursos, artículos o temas estables a largo plazo; use etiquetas para conceptos detallados".
### Error 2: etiquetas sin reglas de nomenclatura [#error-2-etiquetas-sin-reglas-de-nomenclatura]
Si `to read`, `ToRead`, `unread`, `todo` coexisten, la búsqueda se interrumpe. Los sistemas de etiquetas temen sobre todo la deriva de sinónimos.
BibGenie puede detectar esta desviación y cambiar el nombre de las etiquetas antiguas por etiquetas unificadas. Cambiar el nombre a una etiqueta existente las fusiona de manera efectiva.
### Error 3: utilizar la membresía de temas relacionados con Express [#error-3-utilizar-la-membresía-de-temas-relacionados-con-express]
Relacionado es mejor para relaciones explícitas, no para vincular un lote de elementos temáticamente similares. La membresía del tema debe utilizar etiquetas o colecciones.
### Error 4: olvidar la configuración de visualización de la subcolección [#error-4-olvidar-la-configuración-de-visualización-de-la-subcolección]
En Zotero, los elementos de la subcolección no necesariamente se muestran en la colección principal de forma predeterminada. Cambie esto a través de `View -> Show Items from Subcollections`. Esta configuración afecta la forma en que comprende las relaciones de colección entre padres e hijos, por lo que es mejor estandarizar los flujos de trabajo del equipo.
### Error 5: ignorar las etiquetas automáticas durante demasiado tiempo [#error-5-ignorar-las-etiquetas-automáticas-durante-demasiado-tiempo]
Las etiquetas importadas automáticamente saturan el selector de etiquetas. A menos que dependa explícitamente de estas palabras clave, oculte, elimine o deshabilite periódicamente las etiquetas automáticas.
### Error 6: tratar "Organizar toda mi biblioteca" como un comando vago [#error-6-tratar-organizar-toda-mi-biblioteca-como-un-comando-vago]
"Por favor, organice toda mi biblioteca" suena conveniente pero suele ser demasiado amplio. La función Organización de la biblioteca de BibGenie es más adecuada para comenzar con puntos débiles específicos, como:
* Elementos agregados recientemente pero desorganizados.
* Artículos de una colección que necesitan una mayor subdivisión.
* Etiquetas duplicadas o sinónimas.
* A las entradas les falta DOI, resumen o título de publicación.
* Artículos básicos para marcar con `use:key-citation` para un próximo proyecto de escritura.
Un mensaje mejor:
```text
Please don't organize the entire library yet. Help me diagnose the 3 most pressing categories of issues: unfiled items, duplicate tags, and missing metadata. Only output the problem scope and suggested next steps.
```
### Error 7: hacer que la IA complete metadatos no verificables [#error-7-hacer-que-la-ia-complete-metadatos-no-verificables]
BibGenie puede verificar los metadatos y ayudar a corregirlos cuando haya fuentes confiables disponibles, pero nunca debe pedirle a AI que escriba su propio DOI, resumen, nombre de la revista, autor o número de página. Para las escrituras de metadatos, las fuentes confiables deben provenir de los metadatos existentes de Zotero, información proporcionada por el usuario, contenido de elementos ya leídos o búsquedas de referencias externas verificables de BibGenie.
Un buen mensaje:
```text
Please check the metadata completeness of the most recent 20 items. For entries missing a DOI or abstract, only suggest corrections when verifiable through reliable sources. Mark unverifiable items as "unconfirmed" and do not generate or guess content.
```
## Plantilla recomendada [#plantilla-recomendada]
Puede comenzar directamente desde esta plantilla:
```text
Collections
Inbox
Project - [Project Name]
01 Search Results
02 To Screen
03 Included
04 Background
05 Cited
Domain - [Long-term Topic]
Foundation Papers
Methods
Applications
Archive
Tags
status:to-read
status:reading
status:read
use:key-citation
use:intro-section
use:method-section
method:survey
method:experiment
method:case-study
topic:[Topic Name]
```
## Flujo de trabajo de seguridad para usar BibGenie [#flujo-de-trabajo-de-seguridad-para-usar-bibgenie]
BibGenie puede administrar etiquetas, colecciones, membresía de elementos y algunos metadatos, pero la organización de la biblioteca implica modificar los datos de Zotero. Siga siempre este proceso de cuatro pasos:
Pídale a BibGenie que lea la estructura existente: colecciones, etiquetas y el alcance de los elementos a organizar.
Requerir que BibGenie prefiera reutilizar colecciones y etiquetas existentes; sólo crear otros nuevos si realmente no existe un lugar adecuado.
Pídale a BibGenie que genere el plan de organización, incluidas las etiquetas que agregar, las etiquetas que eliminar, las colecciones a las que mover elementos, qué elementos se ven afectados y qué operaciones requieren aprobación.
Después de la confirmación manual, autorice explícitamente a BibGenie a ejecutarse. Después de la ejecución, solicite un resumen de modificaciones, elementos omitidos y tareas incompletas.
Plantilla de aviso recomendada:
```text
Please organize the currently selected items. The goal is to establish clear Zotero collections and tags:
1. First list existing collections and tags.
2. Prefer reusing existing collections and tags; don't create similar names unnecessarily.
3. Determine which items should go into the same collection.
4. Then suggest consistent `topic:`, `method:`, `status:` tags.
5. Output which tags and collections will be added or removed for each item.
6. Do not modify Zotero yet; wait for my confirmation.
```
Después de la confirmación:
```text
I confirm the organization plan above. Please execute these changes, then summarize how many items were modified, which tags were added, and which collections were used.
```
Para operaciones por lotes en más de 50 artículos, sea más específico:
```text
This is a large batch organization task. First give a brief plan including which existing collections/tags will be used, whether new ones are needed, how many items will be affected, and which write operations need my approval.
After I confirm, execute in focused batches by shared purpose. Do not run one operation per item.
```
Si solo necesita cambiar el nombre, fusionar o eliminar una etiqueta de toda la biblioteca, no permita que BibGenie modifique los elementos uno por uno. Describa la operación a nivel de etiqueta directamente:
```text
Please merge the library-wide tag `methodology` into the existing tag `method:methods`.
First confirm that both tags exist and how many items are affected, then wait for my approval.
```
Si solo necesita cambiar el nombre o mover una colección, haga que BibGenie opere en la colección misma en lugar de crear una nueva colección y mover todos los elementos:
```text
Please rename the collection `Old Thesis Reading` to `Project - Dissertation Reading`.
First list the matching collection key and its item count, wait for my confirmation, then execute.
```
## Referencias [#referencias]
* [Zotero Official Docs: Collections and Tags](https://www.zotero.org/support/collections_and_tags)
* [Zotero Official KB: Organizing a library](https://www.zotero.org/support/kb/organizing_a_library)
* [Zotero Forums: tags and collections best practice?](https://forums.zotero.org/discussion/115437/tags-and-collections-best-practice)
* [Zotero Forums: Collections vs tags](https://forums.zotero.org/discussion/116758/collections-vs-tags)
* [Zotero Forums: best use for related, tags, collections](https://forums.zotero.org/discussion/129569/best-use-for-related-tags-collections)
* [Mastering Zotero: Working with Tags](https://pressbooks.library.yorku.ca/masteringzotero/chapter/working-with-tags/)
* [Zotero Manual: Tags](https://zotero-manual.github.io/tags/)
* [Harvard Library: Organize Your Zotero Library](https://guides.library.harvard.edu/c.php?g=1245347\&p=9129454)
* [UMGC Library: Collections & Tags](https://libguides.umgc.edu/c.php?g=930616\&p=6753118)
* [Massachusetts General Hospital: Organizing Your Library](https://libguides.massgeneral.org/zotero/organizing-library)
* [Catherine Pope: Keeping Your Zotero Library Tidy](https://catherinepope.com/posts/keeping-your-zotero-library-tidy/)
* [Reddit: Collections and Tags](https://www.reddit.com/r/zotero/comments/1izhq0m/collections_and_tags/)
# Zotero WebDAV (/es/docs/zotero-webdav)
La sincronización Zotero le permite mantener su biblioteca disponible en todos los dispositivos. En Zotero, la sincronización tiene dos partes separadas: **sincronización de datos** y **sincronización de archivos**. WebDAV se utiliza para la sincronización de archivos, que incluyen archivos PDF, imágenes, instantáneas y otros archivos adjuntos.
WebDAV no afecta directamente los modelos, Credits o funciones de chat oficiales de BibGenie. Sin embargo, si usa Zotero en varios dispositivos, WebDAV puede ayudar a garantizar que los archivos adjuntos estén disponibles localmente, lo que afecta si BibGenie puede leer archivos PDF o instantáneas en un dispositivo determinado.
## Sincronización de datos versus sincronización de archivos [#sincronización-de-datos-versus-sincronización-de-archivos]
| Tipo | lo que sincroniza | Notas |
| :------------------------- | :------------------------------------------------------------------------------------------ | :----------------------------------------------------------------------------------------------------------------- |
| Sincronización de datos | Elementos, títulos, autores, años de publicación, notas, etiquetas, colecciones y metadatos | Zotero proporciona sincronización de datos ilimitada y gratuita |
| Sincronización de archivos | Archivos PDF, imágenes, instantáneas, audio y otros archivos adjuntos | El almacenamiento gratuito de archivos de Zotero está limitado a 300 MB; WebDAV se puede utilizar como alternativa |
Para utilizar la sincronización Zotero, normalmente debe iniciar sesión en una cuenta Zotero y habilitar la sincronización de datos. WebDAV maneja únicamente archivos adjuntos; no reemplaza la sincronización de datos de la cuenta Zotero.
Primero configure la sincronización de datos de Zotero iniciando sesión en su cuenta Zotero en las preferencias de Zotero. WebDAV solo reemplaza la parte de almacenamiento de archivos.
## ¿Qué es WebDAV? [#qué-es-webdav]
WebDAV es un protocolo que permite a las aplicaciones administrar archivos en un servidor remoto. Zotero puede usar WebDAV como alternativa al propio almacenamiento de archivos de Zotero, lo que permite sincronizar archivos adjuntos a través de proveedores de almacenamiento de terceros compatibles.
Esto es útil si desea que los archivos PDF y archivos adjuntos estén disponibles en todos los dispositivos sin comprar el plan de almacenamiento de archivos oficial de Zotero.
## Proveedores comunes de WebDAV [#proveedores-comunes-de-webdav]
| proveedor | Espacio libre/límites | Sitio web | Notas |
| :--------- | :---------------------------------------------------------------------------------- | :--------------------------------------------------------- | :------------------------------------------ |
| Koofr | 2 GB inicialmente; hasta 10 GB después de completar las tareas de la cuenta | [https://koofr.eu/](https://koofr.eu/) | Fácil de configurar; servidores en europa |
| Jianguoyun | Tráfico de carga de 1 GB/mes y tráfico de descarga de 3 GB/mes en el nivel gratuito | [https://www.jianguoyun.com/](https://www.jianguoyun.com/) | A menudo más rápido desde China continental |
Consulte la página oficial [WebDAV proveedores](https://www.zotero.org/support/kb/webdav_services) de Zotero para obtener más opciones.
## Configurar Koofr WebDAV [#configurar-koofr-webdav]
Koofr es un proveedor de almacenamiento en la nube con sede en Europa. Se recomienda comúnmente porque la configuración es sencilla y Koofr proporciona orientación WebDAV específica de Zotero.
Regístrese para obtener un [Koofr account](https://koofr.eu/) e inicie sesión en la aplicación web Koofr.
Haga clic en su avatar en la esquina superior derecha y abra **Preferencias**.
Seleccione **Contraseña** en el menú de la izquierda, luego desplácese hasta **Contraseñas de aplicaciones**.
Ingrese el nombre de una aplicación como `Zotero`, haga clic en **Generar** y guarde la contraseña generada. Koofr muestra esta contraseña sólo una vez.
Abra Zotero y vaya a **Editar -> Preferencias -> Sincronizar**. En macOS, use **Zotero -> Configuración -> Sincronización**.
En **Sincronización de archivos**, habilite la sincronización de archivos adjuntos y elija **WebDAV**.
Ingresar:
* **URL**: `https://app.koofr.net/dav/Koofr`
* **Nombre de usuario**: correo electrónico de su cuenta Koofr
* **Contraseña**: la contraseña de la aplicación Koofr que generó
Haga clic en **Verificar servidor**. Después de que la verificación sea exitosa, haga clic en **Aceptar** para guardar la configuración.
Haga clic en el botón de sincronización de Zotero para comenzar a sincronizar archivos adjuntos.
El segmento `Koofr` de la URL debe comenzar con K mayúscula.
## Configurar Jianguoyun WebDAV [#configurar-jianguoyun-webdav]
Inicie sesión en [Jianguoyun](https://www.jianguoyun.com/) en su navegador.
Haga clic en el nombre de su cuenta en la esquina superior derecha y abra **Información de cuenta**.
Abra **Opciones de seguridad**.
En **Administración de aplicaciones de terceros**, haga clic en **Agregar aplicación**.
Ingrese un nombre como `Zotero`, genere una contraseña y guárdela. Esta es una contraseña específica de la aplicación, no su contraseña de inicio de sesión de Jianguoyun.
Abra Zotero y vaya a **Editar -> Preferencias -> Sincronizar**. En macOS, use **Zotero -> Configuración -> Sincronización**.
En **Sincronización de archivos**, habilite **Sincronizar archivos adjuntos en Mi biblioteca** y elija **WebDAV**.
Ingresar:
* **URL**: `https://dav.jianguoyun.com/dav/`
* **Nombre de usuario**: tu cuenta de Jianguoyun, normalmente tu correo electrónico
* **Contraseña**: la contraseña específica de la aplicación generada en Jianguoyun
Haga clic en **Verificar servidor**. Si Zotero solicita crear una carpeta `zotero` en el servidor WebDAV, confírmelo.
La dirección habitual del servidor Jianguoyun WebDAV es `https://dav.jianguoyun.com/dav/`.
Si usa Zotero en varias computadoras, configure las mismas configuraciones de WebDAV en cada dispositivo y asegúrese de que la sincronización de datos de Zotero use la misma cuenta.
# コンテキスト追加 (/ja/docs/add-context)
BibGenieは、AIにファイル名だけを見せるわけではありません。Add Contextは、Zoteroの研究対象、文書内容、現在の読書位置を会話に取り込みます。これによりAIは、どの文献を調べているのか、どのセクションを読んでいるのか、どの一節が重要なのかを把握できます。
Zoteroアイテム全体から質問を始め、PDFの1ページ、EPUBセクション、さらにPDF・EPUB・スナップショット内の選択テキストまで、コンテキストを絞り込めます。質問に近いコンテキストほど回答が的確になり、原文との照合もしやすくなります。
Add Contextは、「どの資料か」と「どこを読んでいるか」の両方を扱います。アイテム、添付ファイル、ノート、コレクション、タグに加え、現在のPDFページ、EPUBセクション、Readerで選択したテキストも追加できます。
## コンテキストを追加する方法 [#コンテキストを追加する方法]
入力欄でスペースに続けて `@` を入力すると、Zoteroアイテム、添付ファイル、ノート、タグ、コレクションなどを検索して挿入できます。
入力欄の近くにあるAdd Contextボタンをクリックして、選択ダイアログを開きます。
Zoteroアイテム、コレクション、タグ、リーダータブ、選択テキストからコンテキストを追加します。
入力欄に画像を貼り付けるか、Zotero側のスクリーンショットを使って図、数式、ページ領域を扱います。
## 対応しているコンテキスト種別 [#対応しているコンテキスト種別]
| 種別 | 向いている用途 |
| :----------------------------- | :---------------------------------- |
| 通常アイテム | 書誌メタデータ、タイトル、著者、年、関連添付ファイル |
| PDF添付ファイル | 論文全体の読解、セクション要約、方法、結果 |
| EPUB添付ファイル | 電子書籍全体の読解と、論理ページまたはセクション単位の参照 |
| Snapshot | Zoteroに保存したWebページの読解 |
| ノート | Zoteroノート、抜粋、研究ノートをコンテキストとして利用 |
| 保存済みアノテーション | ハイライト、コメント、色、タグ、出典位置をコンテキストとして利用 |
| コレクション | 論文セットを扱う |
| タグ | 特定タグ配下の論文を扱う |
| PDF / EPUB / Snapshotからの選択テキスト | 文章の正確な説明 |
| 現在のPDFページコンテキスト | 読んでいるページについて質問 |
| 現在のEPUBセクション | 閲覧中のEPUBコンテンツ単位を読み、メッセージからReaderへ戻る |
| 画像 / スクリーンショット | 図、数式、ダイアグラム、ページ領域の分析 |
## `@` でコンテキストを追加 [#-でコンテキストを追加]
入力欄でスペースに続けて `@` を入力すると、コンテキスト検索メニューが開きます。タイトル、著者、キーワード、ノート名、タグ名、コレクション名を入力して結果を絞り込めます。
よくある例:
```text
@attention is all you need
@Smith 2023
@my research note
@systematic-review
@my project collection
```
結果を選択すると、入力欄にコンテキストブロックとして表示されます。質問する前に複数のコンテキストブロックを追加できます。
## Zoteroからコンテキストを追加 [#zoteroからコンテキストを追加]
現在のZoteroオブジェクトをBibGenieへ直接追加できます。
* 1つ以上のライブラリアイテムを右クリックし、**Add to Chat** を選択する。
* コレクションツリー内のコレクションを右クリックする。
* タグセレクター内のタグを右クリックする。
* PDF、snapshot、ノートのタブを右クリックする。
* PDF、EPUB、snapshot内のテキストを選択してチャットに追加する。
* PDF Readerでは現在のページを追加し、EPUB Readerでは **Add Section to Chat** を選んで現在のセクションを追加する。
これらの入口は[Add to Chat Settings](/docs/add-to-chat-settings)で有効化または無効化できます。
## Readerから正確なコンテキストを追加 [#readerから正確なコンテキストを追加]
BibGenieは、文書形式ごとに適した読書単位を使用します。
| Reader | 追加できる正確なコンテキスト | 向いている用途 |
| :------- | :-------------- | :------------------------- |
| PDF | 現在のページ、選択テキスト | ページ固有の記述、図、一節の確認 |
| EPUB | 現在のセクション、選択テキスト | 章に相当する内容単位の読解や、特定の一節の説明 |
| Snapshot | 選択テキスト | Zoteroに保存したWebページ内の特定箇所の分析 |
追加したコンテキストはユーザーメッセージに表示されます。有効な位置情報がある場合は、メッセージ内のコンテキストをクリックすると、対応するReaderを開いて関連箇所へ戻れます。
EPUBの目次階層とファイル構造は、必ずしも一対一ではありません。現在のセクションは通常、EPUB spine内の1つのXHTMLコンテンツ単位に対応します。複数の下位目次項目が同じXHTMLを共有している場合、Add Section to Chatはアンカーで区切られた1小節ではなく、そのコンテンツ単位全体を追加します。
## 例 [#例]
PDFを追加して次のように質問します。
```text
この論文を、研究課題、方法、データ、主な知見、限界に分けて要約してください。
```
EPUB Readerから現在のセクションを追加して質問します。
```text
このセクションの中心的な主張を要約し、本全体のテーマとの関係を説明してください。
```
関連論文を複数追加して次のように質問します。
```text
これらの論文を、前提、方法、結論の観点で比較し、比較表で返してください。
```
選択した文章を追加して次のように質問します。
```text
この一節の論理を説明し、主要な概念を特定してください。
```
図のスクリーンショットを追加して次のように質問します。
```text
この図の軸、曲線、主な結論を説明してください。
```
## ヒント [#ヒント]
* 現在の質問に関連するコンテキストだけを追加します。
* 複雑なタスクでは、まず要約を依頼し、その後で詳細を質問します。
* 複数論文の比較では、統合する前に各論文を列挙するようBibGenieに依頼します。
* スクリーンショットは図や数式に有用ですが、引用レベルの根拠が必要な場合は元のPDFまたはアイテムも追加してください。
# Add to Chat設定 (/ja/docs/add-to-chat-settings)
BibGenieは、普段使っているZoteroライブラリやReaderの操作位置に **Add to Chat** を配置します。テキストをコピーし、添付ファイルを探し、チャットへ戻る手間をかけずに、関連資料や読んでいる箇所をそのままAIへ渡せます。
必要な入口は研究スタイルによって異なります。よく使うPDF選択テキストやEPUBセクションは残し、使用頻度の低い項目は非表示にして、Zoteroのコンテキストメニューをすっきり保てます。
Add to Chatの入口を無効にすると、通常はそのメニュー項目またはショートカットが非表示になります。ただし、BibGenieがその種類のコンテキストを他の方法で追加できないという意味ではありません。
## 利用可能なトグル [#利用可能なトグル]
| 設定 | 制御する内容 |
| :---------------------- | :---------------------------------------------- |
| Library Items | 保存済みアノテーションを含む対応ZoteroアイテムにAdd to Chatを表示 |
| Collections | コレクションツリーにAdd to Chatを表示 |
| Tags | タグセレクターにAdd to Chatを表示 |
| Reader Tabs | 開いているPDF、snapshot、ノートタブにAdd to Chatを表示 |
| PDF Text Selection | 選択したPDFテキストをチャットに追加 |
| EPUB Text Selection | 選択したEPUBテキストをチャットに追加 |
| Snapshot Text Selection | 選択したsnapshotテキストをチャットに追加 |
| Reader Annotations | Readerのコンテキストメニューから保存済みアノテーションをチャットに追加 |
| Reader Page Context | PDF ReaderにAdd Page to Chatを表示し、現在のページを追加 |
| EPUB Section Context | EPUB ReaderにAdd Section to Chatを表示し、現在のセクションを追加 |
## 各入口から追加される内容 [#各入口から追加される内容]
Add to Chatは、次の3段階のコンテキストを扱います。
アイテム、コレクション、タグによって、どの文献または文献群を扱っているかをBibGenieに伝えます。
ReaderタブからPDF、スナップショット、ノート全体を追加できます。要約や複数資料の統合に適しています。
PDFページ、EPUBセクション、選択テキストによって、現在読んでいる箇所に質問を絞り込めます。
コンテキストに有効な位置情報が含まれている場合は、メッセージ内のコンポーネントをクリックして文書を開き直し、関連箇所へ戻れます。
## 推奨デフォルト [#推奨デフォルト]
BibGenieを初めて使う場合は、デフォルト設定のままにしてください。よくある設定方針:
Library Items、Reader Tabs、および普段使う形式のText Selectionを有効にしておきます。
プロジェクト、テーマ、文献グループ単位でよく作業する場合は、CollectionsとTagsを有効にしておきます。
Zoteroのコンテキストメニューが混みすぎていると感じる場合は、使用頻度の低い入口を無効にします。
## ヒント [#ヒント]
* PDFをよく読む場合は、PDF Text SelectionとReader Page Contextを有効にします。
* 電子書籍をよく読む場合は、EPUB Text SelectionとEPUB Section Contextを有効にします。
* 保存したWebページを分析する場合は、Snapshot Text Selectionを有効にします。
* 文献レビューを書く場合は、CollectionsとTagsを有効にします。
* 最小構成を好む場合は、Library Itemsと入力欄の `@` メニューを残します。
# BibGenie Citation (/ja/docs/bibgenie-citations)
BibGenie Citationは、**AIの回答**、**原文の根拠**、**Zoteroの研究対象**を追跡可能な形でつなぐシステムです。
BibGenieがあなたのZoteroライブラリ、PDF、ノート、スナップショット、Webページ、OpenAlexの結果に基づいて回答するとき、必要に応じて `[1]`、`[2]` のような引用マーカーを自動で追加します。手動で有効にしたり、特別なプロンプトを覚えたりする必要はありません。引用マーカーが表示されたら、それをクリックして出典へ戻り、回答が何に基づいているか確認できます。
BibGenieは、見た目が似ていても役割の異なる2種類のリンクを区別します。
* **Citation** は、PDF、EPUB、スナップショット内のテキストブロックや選択範囲など、回答を支える根拠を指します。
* **クリック可能なエンティティ** は、回答内で言及されたZoteroアイテム、添付ファイル、ノート、コレクション、タグなどを指します。対象を開いて作業を続けるためのもので、それ自体を文章の根拠として扱うものではありません。
目的は、回答をより「学術的」に見せることではありません。目的は、次のような判断を助けることです。
* この結論はどこから来たのか。
* AIが出典を読み違えたり、過度に一般化したりしていないか。
* この情報をノート、文献レビュー、研究草稿で安心して使えるか。
* 続けて調べるなら、どの出典を読み直すべきか。
Citationは原文の根拠へ戻るためのリンク、クリック可能なエンティティはZoteroで作業を続けるためのリンクです。1つの回答に両方を含められます。
## 2種類のクリック可能なリンク [#2種類のクリック可能なリンク]
| 種類 | 答える問い | 主なリンク先 | 根拠を表すか |
| :----------- | :---------------- | :-------------------------------------------- | :----- |
| Citation | 「この記述の根拠は何か?」 | 文書ブロック、選択テキスト、保存済みアノテーション、ノート、Web、OpenAlexの結果 | はい |
| Zoteroエンティティ | 「回答が指している対象はどれか?」 | アイテム、添付ファイル、ノート、アノテーション、コレクション、タグ | いいえ |
たとえばBibGenieは、主張の根拠としてEPUB内の特定テキストブロックを引用しながら、回答中で言及したEPUB添付ファイルをクリック可能な対象として表示できます。前者は主張の検証に、後者は資料を開いて作業を続けるために使います。
## 何を解決するのか [#何を解決するのか]
研究にAIを使うとき、最大のリスクは「答えがない」ことではない場合が多いです。むしろ、流暢な答えが返ってきても、それがどこから来たのか分からないことです。
実際の文献作業では、次の3つを分けて考える必要があります。
| 種類 | 意味 | なぜ重要か |
| :----- | :---------------------------------- | :----------------- |
| 原典 | PDF、ノート、スナップショット、Webページ、OpenAlexの結果 | 回答の土台になるもの |
| AIの要約 | BibGenieによる出典内容の圧縮、整理、説明 | 便利ですが、確認する価値があります |
| あなたの判断 | 出典と研究文脈に基づくあなた自身の結論 | 執筆や研究上の意思決定を導くべきもの |
BibGenie Citationは、これらの層の間に明確な道筋を残します。AIの回答から出典へ戻り、その回答が信頼できるかどうかをあなた自身で判断しやすくします。
## 対応している出典 [#対応している出典]
BibGenieの引用はPDFだけのものではありません。Zotero内でさまざまな出典を扱うとき、引用は複数の種類の研究資料をカバーできます。
BibGenieがPDFを読むとき、回答はページ、テキストブロック、段落位置を引用できます。PDF固有の段落ジャンプについては、[段落単位の引用](https://www.bibgenie.com/ja/docs/paragraph-citations)をご覧ください。
BibGenieがEPUB全体または現在のセクションを読むとき、回答は抽出された特定のテキストブロックを引用し、Zotero EPUB Readerの関連箇所へ戻れます。
回答がZoteroのノート、抜粋、研究メモに基づく場合、引用によって、その情報がどのノート内容から来たのか分かります。
BibGenieがZoteroに保存されたWebスナップショットを読むとき、回答はテキストブロックや有効な選択範囲を引用し、保存済みのWebページ資料へ戻れます。
Web検索やWeb抽出を使うとき、引用は回答がどの検索結果やWebページ本文を使ったのかを示せます。
BibGenieがOpenAlexの学術検索を使うとき、引用は論文、著者、掲載先、機関、引用ネットワークなどの外部学術メタデータを指すことができます。
アイテム、添付ファイル、ノート、コレクション、タグは、回答内にクリック可能なエンティティとして表示できます。原文の根拠と混同せず、対象のZoteroオブジェクトを直接開けます。
## 選択テキストも引用できます [#選択テキストも引用できます]
PDF、EPUB、スナップショットで選択したテキストを会話に追加できます。BibGenieに対象の一節を直接渡すだけでなく、有効なReader位置情報があれば原文へ戻る経路も作られます。
Readerで説明または確認したい一節を選択し、**Add to Chat** を選びます。
選択範囲について質問します。BibGenieは、明示的に追加された一節を優先して扱います。
回答がその選択範囲を引用したら、Citationをクリックして文書を開き直し、関連箇所へ戻れます。PDFなど対応する場面では、一時的なハイライトが原文の発見を助けます。
選択テキスト自体は会話のコンテキストとして利用できます。ただし保存された位置が欠落、破損、または安全に解決できない場合、BibGenieはクリックできそうに見えて原文へ戻れないCitationを生成しません。
## 文書内の引用を正確に保つ仕組み [#文書内の引用を正確に保つ仕組み]
BibGenieはPDF、EPUB、スナップショットを読むとき、文書内容を安定した識別子付きのテキストブロックに整理します。添付ファイル全体を一括して出典とするのではなく、主張を実際に支えるブロックを引用します。
これには3つの実用的な利点があります。
* 引用をクリックしたとき、関連するページ、セクション、原文位置へ戻りやすくなります。
* 複数の添付ファイルを同時に分析しても、各記述がどの資料に支えられているか区別できます。
* 回答をコピーしたりZoteroノートとして保存したりしても、引用には読みやすい出典情報が残ります。
## 引用でできること [#引用でできること]
重要な結論、データ、方法の説明、著者の主張について、引用をクリックして出典へ戻り、その資料が本当に回答を支えているか確認できます。
役に立つ回答に出会ったとき、引用は最も関連するPDF、ノート、スナップショット、Webコンテンツへ戻してくれるため、そのまま読み進められます。
研究内容をノートにするとき、引用は要約から出典への道筋を保つため、あとで根拠を探し直す必要が減ります。
ローカルのZoteroアイテム、Webページ、OpenAlexの結果を組み合わせるとき、引用はローカルライブラリの根拠と外部検索結果を区別する助けになります。
## よくある使い方 [#よくある使い方]
BibGenieに論文の研究課題、方法、実験設計、発見、限界を要約してもらえます。回答内の引用は、論文に戻って重要な主張を確認する助けになります。
PDF引用が原文の正確な段落へ戻る機能について知りたい場合は、[段落単位の引用](https://www.bibgenie.com/ja/docs/paragraph-citations)をご覧ください。
EPUB添付ファイル全体または現在のセクションを追加し、論点の要約、概念の説明、章同士の比較を依頼できます。回答内の引用は実際に使用されたEPUBテキストブロックへ対応し、メッセージ内のセクションコンポーネントから追加時の読書位置へ戻れます。
PDF、EPUB、スナップショットでテキストを選択して会話へ追加すると、質問を1つの一節に絞れます。選択範囲に有効な位置情報があれば、回答内のCitationから原文の文脈へ戻れます。
Zoteroに抜粋、読書ノート、研究アイデアを保存している場合、BibGenieはそれらをテーマ別に整理できます。引用があれば、すべてが追跡不能な回答に混ざるのではなく、要約がどのノートから来たのか分かります。
プロジェクトのホームページ、データセット説明、ツールドキュメント、ニュースページをZoteroスナップショットとして保存している場合、BibGenieはそれを読み、引用で出典を示せます。Web検索やWeb抽出を使う場合も、引用は回答の根拠になったWebページを確認する助けになります。
OpenAlexは、タイトル、著者、DOI、掲載先、引用数、引用関係などの外部学術メタデータを返します。引用は、回答を特定のOpenAlex結果へたどれるようにし、外部検索メタデータをBibGenieが論文全文を読んだ結果のように扱ってしまうことを防ぎます。
ローカルPDF、Zoteroノート、OpenAlexの結果、Web資料を1つのワークフローで組み合わせられます。引用は、統合された回答のどの部分が保存済み文献に由来し、どの部分が外部の補助資料に由来するのかを区別する助けになります。
## 引用の読み方 [#引用の読み方]
BibGenieの回答には、 `[1]`、`[2]` のような引用マーカーが含まれることがあります。これらは出典への入口として扱ってください。
**回答の構造を読む**:まずBibGenieが質問の要点を理解しているか確認します。
**重要な主張を見つける**:採用する、保存する、引用する、または追問に使う可能性のある結論に注目します。
**引用をクリックする**:関連するPDF、ノート、スナップショット、Webページ、OpenAlexの出典へ戻ります。
**出典内容を確認する**:出典がその記述を支えているか、範囲、表現、文脈に注意して確認します。
**追問または修正する**:回答が広すぎる場合は、引用された出典に基づいて言い直すようBibGenieに依頼します。
## BibGenie Citationと正式な参考文献の違い [#bibgenie-citationと正式な参考文献の違い]
BibGenie Citationは主に**読解、検証、出典追跡**のためのものです。論文の最終的な参考文献形式ではありません。
| 項目 | BibGenie Citation | 正式な参考文献 |
| :------ | :---------------- | :---------------------- |
| 主な目的 | AI回答の背後にある出典へ戻る | 論文、レポート、ジャーナルの書式要件を満たす |
| 表示される場所 | BibGenieのチャット回答内 | 文書の本文と参考文献リスト内 |
| 重視すること | 出典追跡、根拠確認、継続的な読解 | 引用スタイル、出版メタデータ、書式 |
| 提出に使えるか | 正式な引用としては推奨されません | 必要なスタイルで生成し、確認する必要があります |
論文、課題、助成金申請書、正式なレポートを書く場合は、APA、MLA、Chicago、GB/T 7714、または投稿先が求める形式など、Zoteroの引用スタイルを使ってください。
BibGenie Citationは、回答がどこから来たのかを確認するためのものです。正式な執筆では、Zoteroアイテムと原典へ戻り、必要な参考文献形式を使ってください。
## 引用がない回答がある理由 [#引用がない回答がある理由]
すべての文に引用が付くわけではありません。よくある理由は次のとおりです。
* **質問が操作に関するもの**:たとえば「このコレクションを整理して」では、出典箇所を引用するよりも次の作業手順を示す回答になることがあります。
* **回答が総合的なもの**:複数の出典を組み合わせた要約は、1つの引用へきれいに対応しないことがあります。
* **出典が十分に明確でない**:入力に追跡可能な資料が含まれていない場合、BibGenieは一般的な助言だけを返すことがあります。
* **外部Webやメタデータに限界がある**:OpenAlexやWeb結果は要約やメタデータであることが多く、全文読解ではありません。
* **文書構造やテキスト品質が解析に影響する**:スキャンPDF、精度の低いOCR、複雑なレイアウト、EPUBの目次とspineの不一致、特殊なスナップショット構造は、引用位置に影響することがあります。
重要な記述に引用がない場合は、「この結論は何に基づいていますか」や「どの論文、ノート、Webページから来ていますか」と自然に追問できます。BibGenieが出典を追跡できるときは、引用自体は自動で追加されます。
## 使い方のヒント [#使い方のヒント]
* 重要な結論について、AIの要約だけに頼らないでください。引用をクリックして出典を確認します。
* 引用がPDF、EPUB、スナップショットを指している場合は、ハイライトされたテキストだけでなく周辺の文脈も読みます。
* 引用がOpenAlexから来ている場合、それは通常、学術メタデータを示しており、論文全文を読んだ結果ではないことを覚えておいてください。
* 引用がWebから来ている場合、Webコンテンツは変わることがあります。正式に使う前に、元ページまたは別の信頼できる出典で確認してください。
* 文献ノートを書くときは、自動生成された引用を残しておくと、あとで出典を見直しやすくなります。
* 正式な論文では、BibGenie Citationをそのままコピーしないでください。Zoteroで標準的な参考文献を生成します。
* 回答に引用がない場合は、「この結論は何に基づいていますか」または「どの論文、ノート、Webページから来ていますか」と尋ねてください。
## 段落単位の引用との関係 [#段落単位の引用との関係]
BibGenie Citationはより広い概念です。PDF、ノート、スナップショット、Webページ、OpenAlex、その他の追跡可能な出典を対象にします。これは次の問いに答えます。
**このAI回答の情報はどこから来たのか?**
[段落単位の引用](https://www.bibgenie.com/ja/docs/paragraph-citations)は、より具体的で、より強力なPDF読解機能です。これは次の問いに答えます。
**このPDFに基づく結論は、元の論文の正確な段落へ戻れるか?**
PDFの精読、原文ハイライト、引用をクリックしてZotero PDF Readerへ戻ることを主に重視する場合は、続けて[段落単位の引用](https://www.bibgenie.com/ja/docs/paragraph-citations)をご覧ください。
BibGenie Citationは全体像です。回答に出典を与えます。段落単位の引用はPDF精読のハイライトです。PDF回答を原文の段落へ戻れるようにします。
# 独自APIキー(BYOK) (/ja/docs/byok)
BYOKはBring Your Own Keyの略です。自分のモデルプロバイダー、APIキー、またはローカルモデルをBibGenieで使用できます。
## BYOKを使う理由 [#byokを使う理由]
カスタムモデルのリクエストは、ローカルZoteroプラグインから設定したプロバイダーへ直接送信されます。
OllamaまたはLM Studioを使って、自分のマシン上でモデルを実行します。
BYOKリクエストはBibGenieの公式モデルサービスを使用しないため、BibGenieクレジットを消費しません。
公式一覧にまだ含まれていないモデルを使用できます。
## データはBibGenieのサービスを通過しますか? [#データはbibgenieのサービスを通過しますか]
カスタムモデルを追加した場合、リクエストデータはBibGenieのモデルサービスを通過しません。ローカルZoteroプラグインが、設定したプロバイダーへ直接リクエストを送信します。
つまり:
* OpenAI API key:リクエストはOpenAIへ直接送信されます。
* Anthropic API key:リクエストはAnthropicへ直接送信されます。
* OpenAI互換プロキシ:リクエストは入力したBase URLへ送信されます。
* OllamaまたはLM Studio:リクエストを完全に自分のマシン内に留めることができます。
BYOKはBibGenieのモデルサービスを迂回しますが、クラウドプロバイダーは送信された内容を受け取ります。所属機関、研究室、プロジェクトのデータポリシーに従ってプロバイダーを選択してください。
## 対応プロバイダー [#対応プロバイダー]
BibGenieは複数のプロバイダー種別に対応しています。
| プロバイダー | メモ |
| :---------------- | :------------------ |
| OpenAI | OpenAI GPTモデル |
| Anthropic | Claudeモデル |
| xAI | Grokモデル |
| DeepSeek | DeepSeekモデル |
| Google | Geminiモデル |
| Groq | Groqホストモデル |
| Moonshot AI | Kimiモデル |
| OpenRouter | 統合モデルルーティングプラットフォーム |
| Ollama | ローカルモデルサービス |
| OpenAI Compatible | 任意のOpenAI互換API |
LM Studioは通常、**OpenAI Compatible** 経由で設定します。
## BYOKが適している場合 [#byokが適している場合]
* すでにプロバイダーのAPIキーを持っている。
* プロバイダーの請求を自分のアカウントで処理したい。
* 所属機関のモデルサービスを使う必要がある。
* リクエストをBibGenieの公式モデルサービスを通さずに送信したい。
* 機密性の高い資料をローカルモデルで処理したい。
* 公式一覧にまだないモデルが必要。
## 次のステップ [#次のステップ]
[カスタムモデル](/docs/custom-models)を読み、プロバイダーを追加し、Base URLとAPIキーを入力して接続をテストしてください。
# 引用形式 (/ja/docs/citation-format)
Citation Format は、BibGenie がチャットコンテキスト内で Zotero アイテムをどのように表示するかを制御します。特に、入力欄で `@` を入力したあとに表示されるアイテムコンテキストの形式に影響します。
## 影響する内容 [#影響する内容]
* `@` 検索結果でのアイテム表示。
* チャットコンテキストに追加した後のアイテム表示。
* BibGenie がコンテキストとして受け取る引用形式の表現。
Citation Format は表示だけを変更します。アイテムのタイトル、著者、年、ジャーナル、その他の Zotero メタデータは編集されません。
## CSL スタイルを選ぶ [#csl-スタイルを選ぶ]
BibGenie は Zotero にインストールされている CSL スタイルを使用します。デフォルトの CSL スタイルは、Preferences の **Citation Format** から選択できます。
よく使われるスタイル:
* APA
* Chicago
* MLA
* IEEE
* Nature
* Vancouver
## 変更するとよい場面 [#変更するとよい場面]
分野、投稿先ジャーナル、または原稿で指定されているスタイルを選びます。
社会科学や人文科学では、著者年形式のほうが一覧で把握しやすいことがあります。
番号形式は、工学、コンピューターサイエンス、IEEE 系のワークフローに合う場合があります。
## FAQ [#faq]
BibGenie は Zotero にインストールされている CSL スタイルを読み込みます。まず Zotero でそのスタイルをインストールまたは有効化してください。
いいえ。この設定は主に BibGenie のチャットコンテキスト表示に影響します。
# 会話を管理する (/ja/docs/conversation-management)
BibGenieでは、会話を修正・継続・分岐できる研究経路として保存します。直近の質問を修正したり、回答を再生成したり、過去の回答から別の会話を始めたりできます。会話が長くなった場合は、古いコンテキストを圧縮して作業を続けられます。
安全に編集できる最新のユーザーメッセージを修正し、再送信します。
それまでのコンテキストを維持したまま、直近の回答を生成し直します。
完了済みの回答から別の会話を開始し、元の研究経路も残します。
以前の内容を要約し、直近のメッセージを次のモデルリクエスト用に保持します。
## 直近の質問を編集する [#直近の質問を編集する]
編集可能な最新のユーザーメッセージにポインターを合わせ、**Edit** を選択します。内容を修正して再送信すると、BibGenieは更新後の質問から現在の会話を続けます。
編集すると、選択したメッセージより後にある現在の経路の内容が置き換わります。元の回答と、それに基づく末尾の状態は現在の経路から外れます。元の検討経路を残したい場合は、先に[会話をFork](#会話をforkする)してください。
AIが回答を生成中の場合、ツールが実行中の場合、または承認待ちの場合は、編集を一時的に利用できないことがあります。
## 回答を再生成する [#回答を再生成する]
直近の回答が期待に合わない場合は、回答の下にある **Retry** を選択します。BibGenieはそれ以前のコンテキストを保持し、その回答を生成し直します。
Retryを実行すると、現在の経路にある元の回答が置き換わります。その回答に依存する末尾の圧縮記録がある場合、それも無効になります。次にメッセージを送信するとき、BibGenieがコンテキストをあらためて評価します。
両方の結果を残したい場合は、元の回答からForkしたうえで、一方の会話でRetryしてください。
## 会話をForkする [#会話をforkする]
Forkは、完了済みの回答を起点に新しい会話を作成します。分岐できるアシスタント回答にポインターを合わせて **Fork** を選択し、操作を確定します。BibGenieは新しい会話を作成して開きます。
```text
元の会話:質問1 → 回答1 → 質問2 → 回答2
│
新しい分岐: └→ 新しい質問 → 新しい回答
```
新しい分岐には、選択した回答とそれ以前のコンテキストが引き継がれます。それ以降、2つの会話は独立して進みます。一方で送信、編集、Retryを行っても、もう一方の後続メッセージは書き換わりません。
Forkは次のような場合に便利です。
* 同じ論文から異なる解釈や研究仮説を検討する。
* プロンプト、モデル、分析方針を比較する。
* 後続内容を変える可能性がある操作を試す前に、現在の結果を残す。
Forkできるのは、安定して完了したアシスタント回答だけです。回答生成、ツール実行、承認処理が進行中の場合は、完了してから再度お試しください。
## 長い会話を圧縮する [#長い会話を圧縮する]
モデルが一度に処理できるコンテキストには上限があります。メッセージ、論文、画像、ツール結果が増えると、会話は現在のモデルのContext Window上限に近づきます。BibGenieは古いターンを短い要約にまとめ、最近のメッセージを保持したまま作業を続けられます。
BibGenie Agentは、必要なタイミングで会話を自動的に圧縮します。古いコンテキストを今すぐ圧縮したい場合を除き、Compactを手動で選択せず、そのまま質問を続けてください。
### 自動圧縮 [#自動圧縮]
BibGenieは次のタイミングで利用可能なコンテキストを確認します。
* 新しいメッセージを送信する前:予定されるリクエストがモデル上限に近づく場合、古いコンテキストを先に圧縮し、その後メッセージを自動送信します。
* 1回の応答が完了した後:コンテキスト使用量が圧縮しきい値に達している場合、バックグラウンドで古い内容を圧縮します。
自動圧縮と手動圧縮では、同じ進行状況が表示されます。送信時に圧縮が始まった場合、圧縮が成功すると保留中のメッセージが自動的に送信されます。再度送信する必要はありません。
### 手動圧縮 [#手動圧縮]
現在の会話を明示的に圧縮したい場合は、入力欄右下の **Context Window** インジケーターにポインターを合わせ、カード右上の圧縮アイコンを選択します。処理中は会話内に **Compacting earlier context…** と表示されます。入力内容の編集は続けられ、圧縮が完了する前なら **Cancel** も選択できます。
### 圧縮された要約を確認する [#圧縮された要約を確認する]
圧縮が完了すると、会話内に **Earlier context compacted** という区切りが表示されます。展開すると、次の情報を確認できます。
* 以前のターンの要約。
* 圧縮前のコンテキストtoken数。
* 圧縮に使用したモデルとContext Windowの情報。
この区切りは通常のユーザー質問として扱われず、後続の回答が直接応答することもありません。モデルへ送信する前に、BibGenieが最新の要約と保持された最近のメッセージを組み合わせ、有効なコンテキストを構成します。
## 各操作の関係 [#各操作の関係]
| 操作 | 現在の会話への影響 | 新しい会話を作成 | モデルを呼び出す |
| :------ | :------------------------------ | :------: | :------: |
| Edit | 選択したユーザーメッセージと、それ以降の現在の経路を置き換える | いいえ | 再送信時 |
| Retry | 再生成可能な直近の回答と末尾の状態を置き換える | いいえ | はい |
| Fork | 元の会話を保持し、選択した回答から独立した経路を作成する | はい | いいえ |
| Compact | 古いコンテキストを要約し、最近のメッセージを保持する | いいえ | はい |
必要な回答が置き換わる可能性がある場合は、先に会話をForkしてください。
## 操作を利用できない場合 [#操作を利用できない場合]
次の状況では、Edit、Retry、Fork、Compactを一時的に利用できないことがあります。
* BibGenieが回答を生成している。
* ツール呼び出しが実行中、または承認待ちになっている。
* 会話を圧縮中、または送信済みのメッセージが圧縮完了を待っている。
* 選択したメッセージが、安全に編集またはForkできる位置にない。
* 保存済みの会話履歴が破損し、読み取り専用で開かれている。
進行中の操作を完了またはキャンセルしてから、もう一度お試しください。会話が読み取り専用で開かれた場合、BibGenieは安全に表示できる履歴を保持し、保存済みの元データは変更しません。
# カスタムモデル (/ja/docs/custom-models)
カスタムモデルを使うと、自分のAPIキー、第三者プロバイダー、ローカルモデル、または所属機関のモデルサービスを利用できます。設定後、BibGenieはローカルZoteroプラグインから選択したプロバイダーへ直接リクエストを送信します。
## モデルを追加する [#モデルを追加する]
BibGenieを開き、
**Model Settings**
に移動します。
Custom Modelsセクションで
**Add Model**
をクリックします。
**Provider ID**
を選択または入力します。BibGenieはモデルカタログから一般的なプロバイダーを読み込み、可能な場合はProvider Name、Provider Type、Base URLを自動入力します。
**Model ID**
を選択または入力します。モデルがカタログに存在する場合、BibGenieはModel Name、Family、Model Types、Context Window、Max Tokens、Descriptionを自動入力します。
API Keyを入力します。Ollamaなどのローカルサービスでは通常APIキーは不要です。
**Test**
をクリックして接続を確認します。成功すると
**Connected**
と表示されます。失敗した場合、BibGenieはプロバイダーのエラーメッセージを表示するため、設定を修正できます。
自動入力されたフィールドを確認し、必要に応じてModel Types、Context Window、Max Tokensを調整します。
**Add Model**
をクリックします。モデルが保存、有効化され、チャットのモデルセレクターで利用可能になります。
## 自動入力の動作 [#自動入力の動作]
カスタムモデルの追加は完全な手作業ではありません。利用可能な場合、BibGenieは `models.dev` カタログからプロバイダーおよびモデル情報を読み込みます。
* Provider IDでは、一般的なプロバイダーの検索とカスタムプロバイダーの手入力ができます。
* プロバイダーを選択すると、Provider Name、Provider Type、Base URLが自動入力される場合があります。
* Model IDは選択したプロバイダーで絞り込まれ、カタログ内モデルとカスタムモデルIDの両方に対応します。
* カタログモデルを選択すると、Model Name、Family、Model Types、Context Window、Max Tokens、Description、価格メタデータが自動入力される場合があります。
* モデルカタログを読み込めない場合、BibGenieは内蔵のフォールバックプロバイダー一覧を使用し、それでもモデルを手動追加できます。
プロバイダーとモデルが検索ドロップダウンに表示される場合は、すべて手入力するのではなく選択してください。Provider Type、Base URL、モデル機能、コンテキスト上限のミスを減らせます。
## フィールド [#フィールド]
| フィールド | 必須 | 説明 |
| :------------- | :- | :-------------------------------------------------------------------- |
| Provider ID | 必須 | `openai`、`anthropic`、`openrouter` などの一意なプロバイダー識別子。カスタムIDも対応 |
| Provider Name | 必須 | プロバイダーの表示名。通常はカタログから自動入力 |
| Model ID | 必須 | `gpt-4.1` や `claude-sonnet-4-5` など、プロバイダーAPIで使う実際のモデルID |
| Model Name | 必須 | BibGenie内で表示される名前。通常はカタログから自動入力 |
| API Key | 任意 | プロバイダーAPIキー。Ollamaなどのローカルプロバイダーでは通常不要 |
| Base URL | 任意 | APIエンドポイント。カタログプロバイダーでは多くの場合自動入力されますが、互換APIやローカルサービスでは手動確認が必要な場合があります |
| Provider Type | 必須 | OpenAI、Anthropic、Ollama、OpenAI CompatibleなどのAPI統合タイプ |
| Family | 任意 | `qwen`、`gpt`、`claude` などのモデルファミリー。多くの場合自動入力 |
| Model Types | 必須 | Text、Vision、Reasoning、Function Calling、Web Searchなどの機能 |
| Context Window | 任意 | モデルのコンテキストウィンドウ。カタログモデルでは多くの場合自動入力 |
| Max Tokens | 任意 | 最大出力トークン数。カタログモデルでは多くの場合自動入力 |
| Description | 任意 | モデル説明。多くの場合自動入力 |
## Provider Typeガイド [#provider-typeガイド]
| Provider Type | 使う場面 |
| :---------------- | :--------------------------------------- |
| OpenAI | 公式OpenAI APIを使う場合 |
| Anthropic | Anthropic Claude APIを使う場合 |
| xAI | xAI Grok APIを使う場合 |
| DeepSeek | 公式DeepSeek APIを使う場合 |
| Google | Gemini APIを使う場合 |
| Groq | Groq APIを使う場合 |
| Moonshot AI | Kimi / Moonshotモデルを使う場合 |
| OpenRouter | OpenRouter APIを使う場合 |
| Alibaba | 通常はOpenAI Compatible経由 |
| Z.AI / Zhipu AI | 通常はOpenAI Compatible経由 |
| Ollama | ローカルOllamaサービスを使う場合 |
| OpenAI Compatible | LM Studio、APIプロキシ、または所属機関の互換エンドポイントを使う場合 |
## Base URL [#base-url]
多くの公式プロバイダーにはデフォルトのBase URLがあります。通常、Base URLを編集する必要があるのは次の場合です。
* OpenAI Compatibleを使う。
* APIプロキシを使う。
* ローカルモデルサービスを使う。
* プロバイダーがカスタムエンドポイントを要求する。
例:
```text
https://api.openai.com/v1
https://openrouter.ai/api/v1
http://localhost:11434
http://localhost:1234/v1
```
多くの互換APIでは、Base URLが `/v1` で終わる必要があります。バージョンパスが欠けていると、NetworkError、404、model-not-foundエラーが発生することがあります。
## Ollamaの例 [#ollamaの例]
Ollamaがインストールされ、実行中であることを確認します。
ターミナルで
`ollama list`
を実行し、ローカルモデルが利用可能であることを確認します。
まだ実行されていない場合は、
`ollama serve`
でOllamaを起動します。
`Listening on 127.0.0.1:11434`
のような出力が表示されます。
BibGenieでモデルを追加し、Provider Typeとして
**Ollama**
を選択します。
Base URLには
`http://localhost:11434`
を使用します。
`ollama list`
に表示されるモデル名、たとえば
`llama3.1:8b`
をModel IDとして使用します。
## LM Studioの例 [#lm-studioの例]
LM Studioは通常、OpenAI Compatible経由で設定します。
LM StudioでローカルAPIサーバーを起動します。
BibGenieでモデルを追加し、Provider Typeとして
**OpenAI Compatible**
を選択します。
LM StudioのAPIアドレスをBase URLとして入力します。通常は
`http://localhost:1234/v1`
のような形式です。
LM Studioで現在読み込まれているモデルのIDをModel IDとして入力します。
## Model Types [#model-types]
モデルが実際に対応している機能に合わせて選択してください。
* **Text**:テキストチャット。通常は必須。
* **Vision**:画像、スクリーンショット、図の入力。
* **Reasoning**:複雑な推論タスクに有用。
* **Function Calling**:検索、読解、ライブラリ管理ワークフローに影響。
* **Web Search**:プロバイダーとモデルが対応している場合のみ有効化。
機能設定が正しくないと、`ModelNotSupported` やツール呼び出しの失敗が発生することがあります。
## FAQ [#faq]
モデルが保存され、有効化されていることを確認してください。それでも表示されない場合は、Model Settingsを開き直すかZoteroを再起動してください。
カスタムモデルのリクエストは、ローカルZoteroプラグインから設定したプロバイダーへ直接送信されます。データフローの詳細は[Bring Your Own Key](/docs/byok)を参照してください。
ローカルサービスが実行中であること、ポートが正しいこと、Base URLに到達できること、ファイアウォールやプロキシがリクエストをブロックしていないことを確認してください。
安全です。APIキーは暗号化され、ローカルのZotero設定にのみ保存されます。モデルプロバイダーへのリクエストに直接使用され、BibGenieのサーバーを**経由することはありません**。
Custom Modelsエリアの **Reset** ボタンをクリックすると、すべてのカスタム設定が初期状態に戻ります。**注意:手動で追加したモデルはすべて削除されます。**
# トラブルシューティング (/ja/docs/error-in-bibgenie)
このページでは、BibGenie でよくあるエラーを診断し、適切な次の手順を選ぶための情報をまとめています。
トラブルシューティングの前に、BibGenie の最新版を使用していることを確認してください。モデル、Zotero 互換性、ネットワークに関する多くの問題は、新しいリリースですでに修正されている場合があります。
エラーダイアログには、モデル名、Request URL、プロバイダーの応答、失敗理由などの有用な情報が含まれることがあります。設定を変更する前に、内容をよく確認してください。
## ModelNotSupported [#modelnotsupported]
"ModelNotSupported" というタイトルのダイアログ。
選択中のモデルが現在の入力タイプに対応していません。Vision 入力に対応していないモデルへ画像を送信した場合によく発生します。
### 修正方法 [#修正方法]
画像やスクリーンショット入力には Vision など、必要な機能に対応したモデルを選びます。
カスタムモデルを使っていて、そのモデルが画像に対応している場合は、Custom Models で **Vision** モデルとしてマークされているか確認します。
タスクでツール利用が必要な場合は、モデルが **Function Calling** に対応していることを確認します。
## AI\_APICallError [#ai_apicallerror]
"AI\_APICallError" というタイトルのダイアログ。
モデル API リクエストに失敗しました。一般的な原因には、無効な API Key、誤った Model ID、不正な Base URL、プロバイダーのタイムアウト、ネットワーク障害などがあります。
### よくあるエラー種別 [#よくあるエラー種別]
無効または期限切れのキーでは、次のようなメッセージが表示されることがあります。
```text
Unauthorized Failure reason: Authentication Fails
(auth header format should be Bearer sk-...)
```
```text
Incorrect API key provided.
```
API Key が完全で有効であり、選択したプロバイダーのものか確認してください。
誤った Model ID では、次のようなメッセージが表示されることがあります。
```text
Model Not Exist
```
BibGenie の Model ID と、プロバイダーが表示している正確なモデル ID を照合してください。
不正な Base URL は、リクエストエラーや 404 エラーを引き起こすことがあります。
多くのプロバイダーでは、Base URL が `/v1` で終わる必要があります。`/v1/` ではなく `/v/` のような URL は失敗します。
### 修正方法 [#修正方法-1]
Model Settings で公式モデル一覧を更新してください。問題が続く場合は BibGenie を更新し、完全なエラーメッセージを添えてサポートに連絡してください。
Provider Type、Provider ID、Model ID、API Key、Base URL を確認してください。Custom Models の Test ボタンで接続を検証します。
Ollama、LM Studio、またはローカルサーバーが起動していること、ポートが正しいこと、Base URL が Zotero のブラウザー環境から到達可能であることを確認してください。
## NetworkError [#networkerror]
`TypeError: NetworkError when attempting to fetch resource.` のようなエラー。
BibGenie がプロバイダーのエンドポイントへ到達できませんでした。
考えられる原因:
* ローカルモデルサーバーが起動していない。
* Base URL またはポートが正しくない。
* ファイアウォール、プロキシ、ネットワークポリシーがリクエストをブロックしている。
* プロバイダーのエンドポイントが一時的に利用できない。
* 設定されたプロバイダーが、この環境でブラウザー側リクエストをサポートしていない。
## 添付ファイルまたはコンテキストの問題 [#添付ファイルまたはコンテキストの問題]
BibGenie が PDF、スナップショット、ノート、選択テキストを読めない場合:
* ファイルがこのデバイスに存在することを確認してください。
* Zotero 同期を使っている場合は、添付ファイルがローカルにダウンロード済みか確認してください。
* WebDAV ユーザーは、Zotero のファイル同期が機能しているか確認してください。
* Zotero で添付ファイルを直接開いてみてください。
* リーダーの状態が古いように見える場合は、Zotero を再起動してください。
## MCP 接続の問題 [#mcp-接続の問題]
外部 MCP クライアントが接続できない場合:
* **Enable MCP Server** がオンになっていることを確認します。
* Server URL をもう一度コピーします。
* MCP Settings で **Test Connection** をクリックします。
* Zotero がまだ起動していることを確認します。
* 信頼できないクライアントは切断します。
## ヘルプを受ける [#ヘルプを受ける]
問題が続く場合は、問い合わせ時に次の情報を送ってください。
* BibGenie のバージョン
* Zotero のバージョン
* オペレーティングシステム
* 公式モデルまたはカスタムモデルのどちらを使用しているか
* Provider Type と Model ID
* 完全なエラーメッセージ
* 特定の PDF、ノート、コンテキスト種別で発生する問題かどうか
サポートが必要な場合は、[BibGenie Discord コミュニティ](https://discord.gg/kDXFAAYDNE) に参加できます。
# はじめに (/ja/docs/getting-started)
このガイドでは、プラグインのダウンロード、Zoteroへのインストール、サイドバーの表示、論文に関する最初の質問まで、最短で動作する環境を作る手順を説明します。
BibGenieはZotero 7、Zotero 8、Zotero 9、Zotero 10に対応しています。最も安定したプラグインおよびリーダー体験のため、最近のZoteroバージョンの使用を推奨します。
## プラグインをダウンロード [#プラグインをダウンロード]
[BibGenieダウンロードページ](https://www.bibgenie.com/download)にアクセスし、最新のプラグインリリースをダウンロードします。
ダウンロードされるファイル名は通常、次の形式です。
```text
bibgenie-.xpi
```
`` はリリース番号です。
## ZoteroにBibGenieをインストール [#zoteroにbibgenieをインストール]
Zoteroを開き、メニューバーから **Tools -> Plugins** を選択します。
Plugin Managerウィンドウで、右上の歯車アイコンをクリックし、**Install Plugin From File...** を選択します。
ダウンロードした `bibgenie-.xpi` ファイルを選択します。
インストール後、Zoteroを再起動します。
再起動後、ZoteroツールバーまたはToolsメニューからBibGenieを開きます。
## BibGenieを開く [#bibgenieを開く]
BibGenieは複数の方法で開けます。
* ZoteroツールバーのBibGenieアイコンをクリックする。
* メニューバーから **Tools -> BibGenie** を選択する。
* 設定済みのキーボードショートカットでBibGenieサイドバーを表示または切り替える。
ショートカットがZoteroまたはOSと競合する場合は、[キーボードショートカット](/docs/keyboard-shortcuts)で変更できます。
## サインイン [#サインイン]
無料ユーザーは、コアのチャットおよびコンテキスト機能から始められます。サインイン後、BibGenieはサブスクリプション状態、クレジット残高、公式モデルへのアクセスを同期できます。
コア研究機能、論文読解、OpenAlex、Web Search、Web Extractによる外部検索を利用できます。
頻繁な論文読解、比較、研究ワークフロー向けに月間クレジットが増えます。
## 最初の質問をする [#最初の質問をする]
最初のタスクとしては、PDF論文から始めるのがおすすめです。
PDF添付ファイルを持つZoteroアイテムを選択します。
初回起動時、BibGenieはデフォルトで内蔵モデルを使用します。最初の質問をする前に、APIキーを設定したりモデルを手動で選択したりする必要はありません。
BibGenieの入力欄で、スペースに続けて `@` を入力し、論文を検索して追加します。Zoteroアイテムを右クリックして **Add to Chat** を選択することもできます。
具体的な質問をします。例:
```text
Summarize this paper's research question, method, main findings, and limitations.
```
回答が役に立つ場合は、最後のアシスタントメッセージで **Save as Note** をクリックし、Zoteroノートとして保存します。
後で独自のAPIキー、ローカルモデル、または所属機関のモデルサービスを使用したい場合は、[Bring Your Own Key](/docs/byok) と [カスタムモデル](/docs/custom-models) を読んでください。
よいプロンプトは、目的と期待する形式の両方を指定します。たとえば「5つの箇条書きで要約」「方法、結果、限界のセクションに分ける」「文献レビュー用ノートに変換する」などです。
## 次のステップ [#次のステップ]
* より豊かなコンテキスト追加を学ぶ:[コンテキスト追加](/docs/add-context)
* 会話の編集、Retry、Fork、圧縮を学ぶ:[会話を管理する](/docs/conversation-management)
* モデル選択を理解する:[モデル](/docs/models)
* プランとクレジットを理解する:[料金とクレジット](/docs/pricing-credits)
* 再利用可能なプロンプトを作る:[Quick Prompts](/docs/quick-prompts)
## BibGenieのアップデート [#bibgenieのアップデート]
BibGenieはZotero起動時に自動的に更新をチェックします。新しいバージョンが検出されると、BibGenieのメニューバーに更新ボタンが表示されるので、クリックするだけで最新版をインストールできます。
ZoteroのPlugin Managerから自動更新を有効にすることもできます:
Zoteroを開き、メニューバーから **ツール -> プラグイン** を選択します。
プラグインリストからBibGenieを選択します。
**自動更新を許可** (Allow automatic updates) を On に設定します。これにより、新しいバージョンがリリースされるとZoteroが自動的にBibGenieを更新します。
# 概要 (/ja/docs)
BibGenieは、Zoteroに直接組み込まれたAIリサーチエージェントです。独立したWebチャットボットのように動くのではなく、Zoteroの作業空間の中で、ライブラリ、PDF、Webスナップショット、ノート、読んでいる資料と一緒に動作します。
Zoteroアイテム、PDF添付ファイル、スナップショット、ノート、選択テキスト、ページコンテキスト、画像、スクリーンショットを会話に追加し、BibGenieに研究資料の読解、説明、検索、整理、保存を依頼できます。
BibGenieの中核体験はZotero環境内で動作します。チャット履歴や多くの設定はローカルに保存されます。カスタムモデルやローカルモデルを使用する場合、リクエストは設定したプロバイダーへ直接送信されます。
## 基本ワークフロー [#基本ワークフロー]
Zoteroアイテム、PDF、スナップショット、ノート、選択テキスト、スクリーンショットを追加し、BibGenieが作業対象の資料を理解できるようにします。
論文を要約し、図を説明し、ライブラリを検索し、論文を比較し、OpenAlexで公開学術情報を調べたり、Web検索で公開情報を収集したりできます。
arXiv、Semantic Scholar、OpenAlex、DBLP、OpenReviewを横断検索し、論文メタデータを検証・補完し、プレプリントを正式出版版へ安全にアップグレードします。詳細:[メタデータ照合と正規化](/docs/metadata-review)。
役立つ回答をZoteroノートとして保存したり、BibGenieにタグ、コレクション、メタデータの整理を依頼したりできます。
## BibGenieでできること [#bibgenieでできること]
* 論文を読む:研究課題、方法、貢献、限界、今後の課題を要約する。
* 抜粋を深く読む:選択した文章、数式、図、実験結果を説明する。
* ライブラリを検索する:キーワードまたは自然言語で研究トピックを説明して関連論文を探す。
* メタデータの照合とアップグレード:複数の学術データベースと照合して文献情報を検証し、arXivプレプリントを正式な会議/論文誌レコードにアップグレードし、Better BibTeX引用キーを安全に保護します。詳細:[メタデータ照合と正規化](/docs/metadata-review)。
* ライブラリを整理する:タグ、コレクション、メタデータ、アイテム移動を管理する。
* ノートを保存する:構造化されたAI回答をZoteroノートに変換する。
* 会話を管理する:直近の質問を編集し、回答をRetryし、分岐を作成して、古いコンテキストを圧縮する。
* 外部ツールを接続する:BibGenieのMCPサーバーを通じてローカルZoteroツールを公開する。
## 推奨される読み進め方 [#推奨される読み進め方]
**初回セットアップ**:[はじめに](/docs/getting-started)から始め、BibGenieをインストールして最初の質問を行います。
**モデルとクレジットを理解する**:[モデル](/docs/models)と[料金とクレジット](/docs/pricing-credits)を読みます。
**主要機能を学ぶ**:[コンテキスト追加](/docs/add-context)、[会話を管理する](/docs/conversation-management)、[文献検索](/docs/literature-search)、[メタデータ照合と正規化](/docs/metadata-review)、[ノートとして保存](/docs/save-as-note)へ進みます。
**高度な設定**:独自のAPIキーやローカルモデルを使う場合は、[Bring Your Own Key](/docs/byok)と[カスタムモデル](/docs/custom-models)を読んでください。
## ドキュメントの構成 [#ドキュメントの構成]
インストール、モデル、料金、クレジット。
コンテキスト、プロンプト、検索、Webアクセス、メタデータ照合、ライブラリ管理、ノート、MCP。
カスタムモデル、MCP、Add to Chat、ショートカット、引用形式、セマンティックインデックス。
よくあるエラー、モデルの失敗、ネットワーク問題、Zotero互換性。
# キーボードショートカット (/ja/docs/keyboard-shortcuts)
BibGenieは、チャットサイドバーを表示または切り替えるためのキーボードショートカットに対応しています。ワークフローに合わせてカスタマイズできます。
## ショートカットを変更する [#ショートカットを変更する]
BibGenie Preferencesを開きます。
**Keyboard Shortcuts** セクションを探します。
Ctrl + ShiftやCommand + Shiftなどの修飾キーを選択します。
`L` などのメインキーを入力します。
競合警告を確認して保存します。
## 競合検出 [#競合検出]
BibGenieは、一般的なZoteroコマンドとの競合を確認します。競合が見つかった場合、設定ページに競合しているコマンドが表示されます。
ショートカットが動作しない場合、考えられる原因は次のとおりです。
* Zotero組み込みショートカットとの競合。
* OSショートカットとの競合。
* 別のZoteroプラグインとの競合。
* 現在フォーカスが入力欄、モーダル、システムコントロール内にある。
* 入力方式またはOSがキーの組み合わせを先に処理している。
## トラブルシューティング [#トラブルシューティング]
Ctrl / Command + Shift + Lなど、別の組み合わせを試してください。また、ショートカットを押す前にZoteroのメインウィンドウをクリックしてください。
通常は競合があることを意味します。Keyboard Shortcutsで、より使われにくいメインキーを選んでください。
macOSでは通常、Command + Shiftの方が自然な慣例です。
# ライブラリ管理 (/ja/docs/library-management)
BibGenieは論文を読むだけではありません。タグ管理、コレクション作成、アイテム移動、メタデータ編集を通じて、Zoteroライブラリの整理も支援できます。
ライブラリ管理アクションはZoteroライブラリを変更する可能性があります。一括操作では、変更を適用する前にBibGenieに計画またはプレビューを表示させてください。
## 対応している整理タスク [#対応している整理タスク]
| タスク | 例 |
| :------- | :----------------------------------- |
| タグ管理 | タグの追加、削除、一覧表示 |
| コレクション管理 | コレクション作成、コレクション一覧、アイテム移動 |
| メタデータ編集 | タイトル、Abstract、出版物タイトル、DOI、関連フィールドの編集 |
| メタデータ読解 | 著者、年、添付ファイル、ノート、タグの確認 |
| 文献分類 | トピック、方法、年、プロジェクトごとに論文をグループ化 |
arXiv、Semantic Scholar、OpenAlex、DBLP、OpenReviewなどの複数の外部学術ソースから不足している要約、DOI、ジャーナル略称を補完したり表記を統一したい場合は、専用の [メタデータレビューとマルチソースクレンジング](/docs/metadata-review) ドキュメントを参照してください。
## よくあるワークフロー [#よくあるワークフロー]
選択したアイテムに `literature-review` やプロジェクトタグを追加します。
研究トピックに沿って新しいコレクションを作成し、関連論文を移動します。
DOI、Abstract、出版物タイトルが欠けている論文を見つけます。
研究テーマに基づいて、より明確なライブラリ構造へ論文をグループ化します。
## プロンプト例 [#プロンプト例]
```text
Review the selected papers and propose a collection structure by research topic. Do not modify Zotero yet.
```
```text
Add the tags deep-research and llm-agent to the currently selected papers.
```
```text
Find papers in this collection that are missing a DOI or abstract, and return a table.
```
## 推奨ワークフロー [#推奨ワークフロー]
BibGenieに候補論文を検索または一覧表示させます。
変更されるアイテムを含めた整理計画を依頼します。
計画を確認します。
BibGenieに変更の適用を明示的に許可します。
変更内容の要約を依頼します。
一括作業では、範囲を指定します:"only selected items"、"only this collection"、"do not edit metadata, only add tags" など。
## 特に注意が必要な操作 [#特に注意が必要な操作]
* 多数の論文を一度に移動する。
* タグを一括削除する。
* タイトル、Abstract、DOI、その他重要なメタデータを上書きする。
* 多数のアイテムにまたがってコレクションを作成または再編成する。
これらの操作では、小さな単位で作業し、まず影響を受けるアイテムをBibGenieに一覧表示させてください。
# 文献検索 (/ja/docs/literature-search)
デフォルトでは、BibGenieは公開Webへ直接行く前に、まずZoteroライブラリを検索して読みます。これにより、回答はすでに収集・整理した資料に基づいたものになります。
## 3つの検索モード [#3つの検索モード]
タイトル、著者、年、DOI、タグ、コレクションなど明示的な手がかりが分かっている場合に適しています。
研究トピック、理論、方法、問題を自然言語で説明したい場合に適しています。
候補論文の一覧表示、結果のページング、定義された範囲内のアイテム確認に適しています。
## Keyword Search [#keyword-search]
Keyword Searchは、対象情報の一部がすでに分かっている場合にうまく機能します。
* 論文タイトル内の語
* 著者名
* 年
* DOI
* コレクション名
* タグ名
* ジャーナル名または会議名
例:
```text
Find papers in my Zotero library about contrastive learning.
```
```text
Find causal inference papers after 2022 with the tag review.
```
Keyword Searchは正確で制御しやすい一方、表現がメタデータと一致しない場合、関連論文を見逃すことがあります。
## Semantic Search [#semantic-search]
Semantic Searchは概念的な検索向けです。タイトルやAbstractで使われている正確な語を推測する必要はありません。研究トピックを説明してください。
例:
```text
Find papers that discuss how large language models affect academic writing norms.
```
```text
My project is about how AI tools change researchers' knowledge work. Find related papers.
```
Semantic Searchは、Zoteroの通常アイテムのタイトルとAbstractのローカルインデックスを使用します。注意点:
* PDF全文検索ではありません。
* Abstractがない論文は一致しにくい場合があります。
* 初回実行時はセマンティックインデックスの構築に時間がかかる場合があります。
インデックス状態とトラブルシューティングについては[Semantic Index](/docs/semantic-index)を参照してください。
## List Items [#list-items]
List Itemsは、一致した論文を表示したり、結果を続けて閲覧したりするために使います。
リクエスト例:
```text
List the 20 most recent papers in this collection.
```
```text
Show more results.
```
```text
List papers tagged systematic-review and sort them by year.
```
List Itemsは、BibGenieにまず候補セットを表示させ、その後どのPDFやノートを読むか決めたい場合に特に便利です。
## 推奨ワークフロー [#推奨ワークフロー]
Semantic Searchを使って、広いトピックに関連する論文を見つけます。
BibGenieにタイトル、年、著者、Abstractを一覧表示させます。
いくつかの論文を選び、コンテキストとして追加します。
BibGenieにPDF読解、主張の比較、表の生成、ノート保存を依頼します。
年、タグ、コレクション、結果数制限を追加すると検索がより有用になります。例:"only after 2020"、"within the Methods collection"、"return at most 10 papers"。
# MCP設定 (/ja/docs/mcp-settings)
MCP Settingsは、BibGenieのローカルMCPサーバーを制御します。有効にすると、外部MCPクライアントがServer URLへ接続し、BibGenieのZoteroツールにアクセスできます。
## コントロール [#コントロール]
ローカルMCPサーバーを開始または停止します。
外部クライアントがBibGenieへ接続するために使用するURLです。通常は `http://127.0.0.1:23119/bibgenie/mcp` のような形式ですが、Zotero がカスタム HTTP ポートを使っている場合は異なることがあります。
Server URLをクリップボードにコピーします。
HTTP POST JSON-RPC で MCP initialize リクエストを送信し、エンドポイントに到達できるか確認します。
Server URL をブラウザで直接開いても、MCP 接続とは同じではありません。MCP クライアントは POST JSON-RPC を送信し、ブラウザのアドレスバーは GET を送信します。実際の確認には **Test Connection** を使ってください。
## ステータス一覧 [#ステータス一覧]
| ステータス | 意味 |
| :------------------ | :------------------------------- |
| Server is off | MCP Serverは無効です |
| Starting | サーバーを起動中です |
| Server running | サーバーは外部クライアントから利用可能です |
| Testing connection | 接続テストを実行中です |
| Connection verified | テストに成功しました |
| Connection failed | テストに失敗しました。URLまたはサーバー状態を確認してください |
## 接続に失敗する場合 [#接続に失敗する場合]
* Zotero が起動していることを確認してください。
* BibGenie が Zotero で有効になっていることを確認してください。
* **Enable MCP Server** がオンになっていることを確認してください。
* ポートが必ず `23119` だと仮定せず、表示された Server URL をコピーしてください。
* Server を有効化した直後やプラグイン更新直後は、Zotero を再起動してから再試行してください。
## MCPを有効化する [#mcpを有効化する]
BibGenie Preferencesを開きます。
**MCP Server** セクションを探します。
**Enable MCP Server** をオンにします。
Server URLが表示されるまで待ちます。
Copyをクリックし、URLを外部MCPクライアントへ貼り付けます。
Test Connectionをクリックして動作を確認します。
## MCPを無効化する [#mcpを無効化する]
外部クライアントを使用していない場合は、**Enable MCP Server** をオフにします。外部クライアントはBibGenieのMCPツールにアクセスできなくなります。
MCPツールはZoteroライブラリを読み取ったり変更したりする可能性があります。Server URLは信頼できるクライアントとのみ共有してください。
# MCP (/ja/docs/mcp)
MCP は Model Context Protocol の略です。BibGenie はローカル MCP サーバーを起動でき、MCP 対応クライアントが Zotero 関連ツールにアクセスできるようになります。
BibGenie プラグイン内だけでチャットする場合、MCP を設定する必要はありません。MCP は主に上級ユーザー、外部クライアント、自動化ワークフロー向けです。
## MCP でできること [#mcp-でできること]
外部クライアントは BibGenie の Zotero ツールを使って、次のことができます。
* Zotero アイテムを検索する
* セマンティック文献検索を実行する
* PDF 添付ファイルを読む
* スナップショットを読む
* Zotero ノートを読む
* タグとコレクションを一覧表示する
* Zotero ノートを作成する
* タグとコレクションを管理する
* メタデータを取得または編集する
## Zotero MCP とは? [#zotero-mcp-とは]
Zotero MCP は、BibGenie が Zotero ライブラリと外部 AI クライアントの間に作るローカルな橋渡しです。ファイルを書き出したりメタデータを手動でコピーしたりしなくても、MCP 対応クライアントはローカルプロトコルを通じて BibGenie に Zotero の文脈を問い合わせられます。
たとえば外部クライアントは、BibGenie の MCP ツールを通じてライブラリ検索、コレクション確認、PDF 添付ファイルの読み取り、Zotero ノートの作成を行えます。
## 主な利点 [#主な利点]
BibGenie の MCP Server は Zotero プラグイン内で動作します。別の Python サービスや独自のローカルバックエンドは不要です。
MCP endpoint は Zotero のローカル HTTP サーバー上で動作します。外部クライアントはあなたのデバイス上で Zotero と通信します。
ツールは Zotero のワークフロー、論文、PDF、コレクション、タグ、ノート、スナップショット、メタデータ向けに設計されています。
MCP により Cursor、Claude Code、Claude Desktop、Cherry Studio などが、それぞれの画面のまま Zotero の文脈を使えます。
## 主な機能 [#主な機能]
| 機能 | 役立つ場面 |
| :----------- | :----------------------------------------------------------------------------------------------------- |
| アイテム検索 | タイトル、著者、出版物、キーワード、トピックで論文を探す。 |
| セマンティック検索 | 完全一致キーワードだけでなく、意味にもとづいて関連論文を見つける。 |
| メタデータ取得 | 引用、整理、編集の前に Zotero アイテムの詳細メタデータを読む。 |
| PDF 読み取り | クライアントが論文本文を必要とするとき、Zotero PDF 添付ファイルのテキストを読む。 |
| PDF の視覚読み取り | 図、表、スキャンページなど視覚的な確認が必要な場合に PDF ページを画像としてレンダリングする。 |
| ノートとスナップショット | ライブラリ内の Zotero ノートと Web スナップショットを読む。 |
| ライブラリ整理 | コレクションとタグの一覧表示、コレクション作成、タグや所属コレクションの管理を行う。 |
| メタデータレビュー | 読み取り専用の `review_metadata` を実行し、arXiv、Semantic Scholar、OpenAlex、DBLP、OpenReview からのマルチソース検索と正規化提案を取得する。 |
| 制御された書き込み | 信頼できるクライアントが明示的な MCP tool call を通じてノートを作成したり、`edit_metadata` を呼び出してメタデータを検証・書き込みする。 |
## プラグイン内チャットと MCP [#プラグイン内チャットと-mcp]
| モード | 最適な用途 | 設定が必要 |
| :------------------- | :---------------------------- | :---- |
| BibGenie のプラグイン内チャット | ほとんどのユーザー | いいえ |
| ローカル MCP Server | Zotero を外部 AI クライアントに接続するユーザー | はい |
## サーバータイプと URL [#サーバータイプと-url]
BibGenie の MCP Server は **Streamable HTTP** を使用します。Server URL は通常、次のような形式です。
```text
http://127.0.0.1:23119/bibgenie/mcp
```
Zotero の HTTP サーバーがカスタムポートを使っている場合、ポートは異なることがあります。手入力ではなく、BibGenie 設定に表示される Server URL をコピーしてください。
MCP クライアントは HTTP POST JSON-RPC リクエストで接続します。ブラウザのアドレスバーは GET リクエストを送るため、MCP 接続テストとしては信頼できません。BibGenie 設定の **Test Connection** または MCP クライアントを使ってください。
## MCP Server を有効化する [#mcp-server-を有効化する]
BibGenie の設定を開きます。
**MCP Server** セクションを探します。
**Enable MCP Server** をオンにします。
表示された Server URL をコピーします。
外部 MCP クライアントに URL を貼り付けます。
**Test Connection** をクリックして動作を確認します。
## 外部クライアントを接続する [#外部クライアントを接続する]
Streamable HTTP MCP をサポートするクライアントで、BibGenie 設定に表示される Server URL を使います。
### Cursor [#cursor]
Cursor は BibGenie の Streamable HTTP endpoint に直接接続できます。
Cursor Settings を開き、**Tools & MCP** に移動します。
**+ New MCP Server** をクリックします。
次の設定を貼り付けます。
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"url": "http://127.0.0.1:23119/bibgenie/mcp"
}
}
}
```
BibGenie 設定に別のポートが表示されている場合は、その URL に置き換えます。
設定を保存します。Cursor が MCP server を接続済みとして表示したら、Cursor chat で Zotero の文脈を使えます。
### Claude Code [#claude-code]
Claude Code は HTTP MCP server を直接追加できます。
```bash
claude mcp add ZoteroBibGenie --transport http http://127.0.0.1:23119/bibgenie/mcp
```
BibGenie 設定に別のポートが表示されている場合は、その URL に置き換えてください。
### Claude Desktop [#claude-desktop]
Claude Desktop の一部のバージョンでは、ローカル HTTP endpoint より stdio MCP server の方が安定して接続できます。その場合は `mcp-remote` を Claude Desktop と BibGenie のローカル HTTP Server の橋渡しとして使います。
`node` と `npx` が使えない場合は Node.js をインストールします。
Claude Desktop を開きます。
**Settings** を開き、**Developer** セクションに移動します。
**Edit Config** をクリックし、`claude_desktop_config.json` を開きます。
次の設定を追加します。
```json
{
"mcpServers": {
"ZoteroBibGenie": {
"command": "npx",
"args": ["mcp-remote", "http://127.0.0.1:23119/bibgenie/mcp"]
}
}
}
```
BibGenie 設定に別のポートが表示されている場合は、設定内の URL を置き換えます。
ファイルを保存し、Claude Desktop を再起動します。
### Cherry Studio [#cherry-studio]
Cherry Studio は Streamable HTTP MCP に直接対応しています。
Cherry Studio Settings を開き、**MCP** タブに切り替えます。
**Add** をクリックし、**Quick Create** を選択します。
次を入力します。
* **Name**: `ZoteroBibGenie`
* **Type**: `Streamable HTTP`
* **URL**: BibGenie 設定からコピーした Server URL

任意で **Advanced Settings** を開き、次を設定します。
* **Provider URL**: `https://www.bibgenie.com/`
* **Logo URL**: `https://www.bibgenie.com/favicon.png`

**Save** をクリックし、サービスをオンにして、Cherry Studio の verify ボタンで接続を確認します。
## プロンプト例 [#プロンプト例]
* 「2023 年以降に発表された retrieval-augmented generation に関する Zotero 論文を探して。」
* 「この Zotero アイテムの PDF 添付ファイルを読んで、論文の主要な貢献を要約して。」
* 「Machine Learning コレクションのアイテムを一覧表示し、年のメタデータがないものを見つけて。」
## セキュリティ上の推奨事項 [#セキュリティ上の推奨事項]
* MCP Server URL は信頼できるクライアントにのみ共有してください。
* ノート作成、メタデータ編集、タグやコレクション管理など、Zotero ライブラリへ書き込むツールには注意してください。
* MCP を使っていないときはサーバーをオフにしてください。
* 外部クライアントが予期しない動作をする場合は、MCP サーバーを停止し、クライアント設定を確認してください。
## FAQ [#faq]
いいえ。プラグイン内チャットは BibGenie の内部機能を直接使用できます。MCP は外部クライアント専用です。
いいえ。Zotero と BibGenie の環境内で動作するローカルサービスです。
MCP サーバーが有効であること、URL が正しくコピーされていること、Zotero が起動していること、Test Connection が成功することを確認してください。Zotero がカスタム HTTP ポートを使っている場合、URL は `23119` ではない可能性があります。
いいえ。ブラウザのアドレスバーは GET リクエストを送りますが、MCP クライアントは POST JSON-RPC を使用します。Test Connection または MCP クライアントを使ってください。
MCP クライアントはツール一覧を読み込み、キャッシュすることがあります。外部クライアントを再起動し、BibGenie が最新であることを確認して、MCP server に再接続してください。
はい。**BibGenie** が提供する基本的な Zotero MCP 接続機能は無料です。MCP に対応する任意のクライアントを接続できます。
# メタデータレビューとマルチソースクレンジング (/ja/docs/metadata-review)
メタデータレビューとマルチソースクレンジングはBibGenieの中核機能です。ウェブサイトやPDF、各種エクストラクタからインポートした論文データには、要約・DOI・ページ番号・ジャーナル名の欠落、タイトルの全大文字表記、ジャーナル標準略称の不足、プレプリントの正式出版未反映、著者リストの途切れなどの問題が頻繁に発生します。
BibGenieは**大規模言語モデル(LLM)の学術的理解力**と**マルチソースの権威ある学術データベース**を融合させ、読み取り専用のレビュー、透明性のある根拠比較、視覚的な差分承認を通じて、整然とした信頼性の高いZoteroライブラリの構築を支援します。
レビュープロセスは完全に読み取り専用で実行され、バックグラウンドで勝手にライブラリが変更されることはありません。AIは現在の値と提案された値を比較する\*\*視覚的な差分プレビューカード(Action Preview)\*\*を生成し、あなたが明示的に「承認」をクリックしたときのみZoteroへ安全に書き込まれます。
## 主な機能 [#主な機能]
arXiv、Semantic Scholar、OpenAlex、DBLP、OpenReviewを統合し、DOI、arXiv ID、DBLP Keyなどの識別子に基づいて自動で最適ルートを選択します。
`lint`(フォーマット規約)、`blank`(空フィールドの補完・推奨)、`all`(完全リフレッシュ)から目的に応じて選択できます。
機械的な正規表現処理とは異なり、BibGenieは学術文脈を理解し、`mRNA`、`CRISPR-Cas9`、`PyTorch`やローマ数字などの大文字小文字を誤って変更しません。
変更前後のハイライト比較、タイプ変換時のフィールド警告、Better BibTeXのCitation Key保持、書き込み失敗時のアトミックロールバックを提供します。
## サポートされている学術データソース [#サポートされている学術データソース]
BibGenieは分野や発表形式に応じた専門的な学術検索ルートを統合しています:
| データソース | カバレッジと特徴 | 最適な用途 |
| :--------------------- | :------------------------------ | :----------------------------------------- |
| **OpenAlex** | 全分野2億5,000万件超のオープン学術グラフ | 総合的な文献検索、基礎メタデータの欠落補完、引用文脈の調査 |
| **arXiv** | 物理・計算機科学・数学などのプレプリントリポジトリ | プレプリントメタデータ取得、公式版識別、正式出版DOIへのリンク |
| **DBLP** | 計算機科学の権威ある文献目録 | CSトップカンファレンス/論文誌の校正、著者名寄せ |
| **OpenReview** | 機械学習・AI分野の主要国際会議(ICLR、NeurIPS等) | 採択トラックの確認、査読中匿名著者の保護、Camera-ready版の追跡 |
| **Semantic Scholar** | CSおよび生物医学の高精度コーパス | 精確な論文識別子解決、TLDR要約、引用関係分析 |
| **Zotero Translators** | ZoteroネイティブのWeb・出版社トランスレータ | 出版社公式サイトからの直接取得(IEEE、ACM、Springer、Nature等) |
## 3つのレビューモード [#3つのレビューモード]
整理の目的に応じて、BibGenieに以下のモードを指定できます:
**デフォルトモード**。外部の学術データベースを検索し、**ローカルで空になっているフィールドと著者リストのみ**を補完します。
* 既存のタイトル、著者、発行年、出版物名などの非空データは一切上書きせずそのまま保持します。
* 欠落している要約(Abstract)、ページ範囲(Pages)、DOI、ジャーナル名、論文集名(Proceedings Title)を自動補完します。
* 日常的なライブラリ充実作業の大部分に最適です。
**ローカル規約チェックモード**。外部事実の検索をスキップし、組み込みの学術ルールに基づいて既存メタデータの書式チェックと整形を行います:
* タイトルのセンテンスケース(Sentence Case)正規化。
* LTWA国際規格および辞書に基づくジャーナル標準略称の補完。
* 高精度な言語コード判定(ISO-639-1)。
* 出版社のドメイン名や不要なURLが混入したフィールドの検知。
* すでに完全なデータが揃っており、書誌フォーマットのみを統一したい場合に最適です。
**完全同期モード**。外部の最新メタデータを照会し、**既存の非空フィールドの更新提案および著者リスト全体の置換**を行います。
* 初期インポート時の誤記や低品質なウェブスクレイピングによる乱れたデータの修正に適しています。
* プレプリント(Preprint)が学会やジャーナルで正式出版された後のメタデータ更新とアイテムタイプ変換に最適です。
* *注意:単に一部のフィールドが不足しているだけであれば `all` は使用せず、`blank` モードを使用してください。*
## 安全性とエコシステム保護 [#安全性とエコシステム保護]
1. **Better BibTeX との完全な互換性**:
* 多くの研究者がLaTeXの引用キー管理にBetter BibTeXを使用しています。BibGenieのExtra処理モジュールは、`Citation Key:`、`tex.*`、`bibtex:`などの構造化キーや自由記述テキストを厳格に保護し、決して削除・改ざんしません。
2. **アイテムタイプ変換時の安全保護**:
* アイテムタイプが変更される場合(例:`preprint` から `journalArticle` へ)、承認プレビューカード上で移行されない・失われる可能性のあるフィールドを明確に警告し、確認の上で反映できます。
3. **学術的インテリジェンス(専門用語の保護)**:
* 単純な機械的置換ツールとは異なり、BibGenieはLLMのドメイン知識を活かして誤った大文字小文字変換を防ぎ、学術的に正確な表記を維持します。
## プロンプトの例 [#プロンプトの例]
```text
選択中の論文を確認し、blank モードで不足している要約、ページ番号、DOI を補完してください。
```
```text
選択した文献のタイトルケースとジャーナル略称を標準化してください。専門用語のスペルはそのまま保持してください。
```
```text
この論文は以前 arXiv プレプリントとして登録したものです。DBLP や Semantic Scholar で正式出版されているか確認し、出版されていればアイテムタイプとメタデータの更新案を提示してください。
```
```text
このコレクション内で要約や DOI が抜けている文献を探し、メタデータのレビューと補完を一括で行ってください。
```
## 推奨される操作手順 [#推奨される操作手順]
**アイテムを選択**: Zoteroのメイン画面でレビューしたい1つまたは複数のアイテムを選択し、チャット入力欄に `@` で追加するか、直接指示を入力します。
**AI が読み取り専用レビューを実行**: BibGenieが外部学術ソースの照会とルール検証を行い、構造化された提案を生成します。
**視覚的差分カードを確認**: チャット内に\*\*承認プレビューカード(Action Preview)\*\*が表示され、変更前後の値が赤緑の差分で明瞭に比較できます。
**承認して安全に書き込み**: カードの「承認」をクリックすると、Zoteroアイテムへアトミックに変更が書き込まれます。却下した場合はライブラリに一切影響を与えません。
# モデル (/ja/docs/models)
BibGenieは、**公式モデル**と**カスタムモデル**の2種類のモデルに対応しています。
* 公式モデルはBibGenieが管理しており、すぐに利用できます。自分のAPIキーを設定する必要はありません。
* カスタムモデルは、プロバイダー、Base URL、APIキー、モデルの機能を自分で設定します。
どちらも **Model Settings** から管理できます。
## 公式モデル [#公式モデル]
市場には多くのAIモデルがありますが、Zoteroエージェントとしてうまく機能するものは一部に限られます。BibGenieは公開ベンチマークだけでモデルを選びません。実際の研究ワークフローを信頼して扱えるかを重視します。
* 長いコンテキストを持つ論文読解
* 複数論文の比較
* 複雑な研究上の推論
* ツール呼び出しと構造化出力
* 図、数式、スクリーンショットなどのマルチモーダル入力
* Zoteroコンテキストに基づいた正確な回答
プロバイダー設定も重要です。同じモデルでも、コンテキスト上限、ツール呼び出し対応、レート制限、デフォルトパラメータ、ネットワーク信頼性によって、プロバイダーごとに挙動が大きく異なることがあります。
ユーザーの設定作業を減らすため、BibGenieは以下を行っています。
論文読解、文献検索、ライブラリ管理、ノート作成のワークフローで、選定したモデルをテストします。
可能な場合は、モデルまたはプロバイダーチームと推奨されるデプロイおよび利用パターンを確認します。
選定したプロバイダーと連携し、BibGenieでうまく機能する形でモデルが提供されるようにします。
モデルとプロバイダーの組み合わせをベンチマークし、推奨リストを維持します。
## カスタムモデル [#カスタムモデル]
自分のAPIキーを持っている場合やローカルモデルを使いたい場合は、カスタムモデルを追加できます。
カスタムモデルは次のような場合に便利です。
* OpenAI、Anthropic、DeepSeek、OpenRouterなどのプロバイダーにすでに支払っている。
* 所属機関が特定のプロバイダーへ直接リクエストを送ることを求めている。
* OllamaまたはLM Studioをローカルで使いたい。
* 公式一覧にまだ含まれていないモデルが必要。
設定手順は[カスタムモデル](/docs/custom-models)を参照してください。
## 倍率の意味 [#倍率の意味]
モデル名の後に `0x`、`1.5x`、`2x` のようなラベルが表示されることがあります。
これらのラベルは、そのモデルがクレジットを消費するおおよその速度を示します。
| ラベル | 意味 |
| :------ | :----------------------------------- |
| `1x` | 標準的な消費速度です。 |
| `1.5x` | 同様のタスクで標準モデルより速くクレジットを消費する場合があります。 |
| `2x` 以上 | 通常は高コストモデルを示し、より要求の高いタスクに使うのが適しています。 |
倍率はユーザー向けの目安です。実際のクレジット使用量は、入力トークン、出力トークン、モデル価格、ツール利用から計算されます。
## モデル一覧を更新する [#モデル一覧を更新する]
公式モデル一覧は自動で更新されます。手動で更新することもできます。
BibGenieを開きます。
**Model Settings** に移動します。
公式モデルセクションで **Refresh** をクリックします。
モデルが見つからない場合、考えられる理由は次のとおりです。
* プラグインのバージョンが古い。
* モデル一覧がまだ更新されていない。
* モデルが一時的に利用できない、または調整中である。
* アカウント状態がまだ同期されていない。
## モデルを選ぶ [#モデルを選ぶ]
低倍率の公式モデルから始めます。
信頼できるコンテキスト処理と高い出力品質を持つ公式モデルを使います。
より強い推論能力と長いコンテキストウィンドウを持つモデルを使います。
BYOK、カスタムプロバイダー、Ollama、LM Studioを使います。
# OpenAlex学術検索 (/ja/docs/openalex-research)
OpenAlex Research は BibGenie v0.7.0 で利用可能な機能で、Zotero ライブラリの外にある公開学術カタログを探索できます。新しい論文の発見、著者や機関の特定、研究トレンドの分析、既知の論文を中心とした引用マッピングにご利用ください。
OpenAlex の結果は外部の書誌メタデータです。論文が Zotero に保存済みであることを意味するものではなく、本文の精読の代わりにもなりません。
OpenAlex Searchはすべてのユーザーが利用できます。Freeでは、OpenAlexツールの成功した呼び出しごとに**1クレジット**を消費し、有料プランではこれらの呼び出しに**追加クレジットはかかりません**。
## できること [#できること]
トピック、完全一致フレーズ、DOI、PMID、PMCID、OpenAlex ID、およびサポートされているフィルターや並び替えフィールドで公開学術レコードを検索できます。
著者、機関、ジャーナル、トピック、出版社、助成機関の安定した OpenAlex ID を見つけます。
シード論文を引用している論文、シード論文が参照している論文、または関連論文を見つけます。
出版年、オープンアクセス状況、国、ソース、トピック、またはその他のサポートされているフィールドで結果をグループ化・集計します。
## OpenAlex を使うタイミング [#openalex-を使うタイミング]
現在の Zotero ライブラリの外部にある公開学術レコードに関する質問には OpenAlex を使用します:
* 研究トピックに関する最近の論文を見つける。
* 影響力のある初期の研究やレビュー論文を発見する。
* DOI や OpenAlex Work ID を中心に引用を追跡する。
* 関連性や被引用数ランキングだけでなく、探索的なカバレッジが必要な場合に一致レコードをランダムサンプリングする。
* 年、ソース、機関、国、トピック、助成機関別に出版活動を比較する。
* 論文をフィルタリングする前に、著者、ジャーナル、機関、出版社、助成機関を特定する。
保存済みアイテム、選択済み論文、コレクション、タグ、ノート、添付 PDF について質問する場合は、Zotero ライブラリ検索を使用してください。
OpenAlex は検討に値する論文を特定できますが、自動的に Zotero に追加するわけではありません。Zotero アイテムのインポート、タグ付け、移動、編集を行う前に、明示的に BibGenie に依頼してください。
## 質問の仕方 [#質問の仕方]
```text
OpenAlex で 2023 年以降の retrieval augmented generation に関する最近のレビュー論文を検索してください。タイトル、年、ソース、著者、被引用数、DOI、および各結果が有用な理由を返してください。
```
```text
OpenAlex を使って Geoffrey Hinton の deep learning に関する論文を検索してください。まず著者を解決し、次に最も引用されている作品を年、ソース、DOI、被引用数とともにリストしてください。
```
```text
OpenAlex を使って 10.48550/arXiv.1706.03762 を引用している論文を探索してください。2021 年以降の論文に焦点を当て、どの論文が LLM 研究に最も関連しているか説明してください。
```
```text
OpenAlex を使って 2018 年から 2025 年までの graph neural networks に関する出版トレンドを分析してください。出版年ごとにグループ化し、トレンドを注意深く要約してください。
```
## 推奨ワークフロー [#推奨ワークフロー]
少ない結果数で幅広い OpenAlex 検索から始めます。
BibGenie に年、作業タイプ、オープンアクセス状況、ソース、著者、機関、トピックで絞り込むよう依頼します。
有望なシード論文について、引用近傍、参考文献、または関連作品を依頼します。
結果を確認した後、最も関連性の高い候補のみを Zotero に追加します。
## 便利なプロンプトパターン [#便利なプロンプトパターン]
```text
OpenAlex で学術執筆における AI ツールに関する論文を検索してください。2020 年以降のレビュー記事を優先し、最大 10 件の結果を返してください。
```
```text
この DOI の OpenAlex レコードを見つけ、その被引用論文と関連作品を表示してください:
10.1038/nature12373
```
```text
OpenAlex で Stanford University を解決し、2020 年以降の同機関におけるヒューマンコンピュータインタラクションに関する高被引用論文を見つけてください。
```
```text
最初に私の Zotero ライブラリで LLM エージェントに関する論文を検索し、次に OpenAlex を使って私が見逃している可能性のある外部論文を見つけてください。Zotero の結果と OpenAlex の外部結果は分けて表示してください。
```
## 重要な制限 [#重要な制限]
* OpenAlex はタイトル、著者、年、ソース、DOI、オープンアクセス状況、被引用数などのメタデータを提供します。
* 被引用数を品質の証明として扱わないでください。
* メタデータのみから論文の方法、主張、発見を推測しないでください。
* 詳細な読解には、論文を Zotero に追加するか、読み取り可能な全文を提供してから、BibGenie にソースコンテンツを読むよう依頼してください。
# 段落単位の引用 (/ja/docs/paragraph-citations)
文献を読むとき、回答が「正しそうに見える」だけでは十分ではありません。信頼できるAI読書アシスタントには、もっと厳密な問いに答えられることが必要です。
**この一文は、論文のどこから来ているのか?**
BibGenieの段落単位の引用は、そのために作られています。AIの回答に含まれる重要な結論を、PDF内の具体的なテキストブロックまでたどれるようにします。回答内の引用マーカーをクリックすると、Zotero PDF Readerへ直接戻り、原文上で対応するハイライト箇所を確認できます。
これは回答をより「学術的」に見せるためのものではありません。中心にある価値は、AIが行った重要な判断を、あなた自身がもう一度確認し、読み直し、納得できる形で検証できることです。
段落単位の引用は、AIの回答を「結論を教える」ものから「根拠の場所を示す」ものへ進めます。引用マーカーをクリックすると、PDF原文の対応する段落へ直接戻れます。
## 段落単位の引用と通常の引用の違い [#段落単位の引用と通常の引用の違い]
同じ引用でも、粒度が違えば判断できることも大きく変わります。
| 引用の粒度 | 分かること | 向いている場面 | 精読に十分か |
| :---------- | :------------------------- | :------------------------- | :----------------- |
| 文献単位の引用 | 回答がおおよそどの論文に基づくか | ざっと読む、参考文献を並べる、背景をすばやく把握する | 粗すぎて、出典しか分からない |
| ページ単位の引用 | 回答がおおよそPDFのどのページに基づくか | 特定ページの全体内容をすばやく探す | まだ粗く、1ページ内の情報が多すぎる |
| **段落単位の引用** | **回答が原文のどのテキストブロックに対応するか** | **精読、事実確認、ノート作成、レビュー執筆** | **根拠を直接確認できる** |
文献単位の引用は出典を教え、ページ単位の引用はページを見つける助けになります。**段落単位の引用は、根拠そのものを直接確認できるようにします**。
BibGenieが重視しているのは、「この論文がこの回答を支えている」と伝えるだけではありません。「この原文の段落がこの回答を支えている」と、あなたの目で確認できるようにすることです。研究者にとって、後者は前者よりずっと重要です。必要なのは出来合いの結論ではなく、その結論が本当に成り立つかを自分で判断できる材料だからです。
## 「答えを出す」から「根拠を出す」へ [#答えを出すから根拠を出すへ]
これまでAIで論文を読む体験は、多くの場合「AIに要約してもらう」段階にとどまっていました。
もちろん、それ自体は便利です。論文のおおまかな内容、方法、結論をすばやく把握できます。ただ、真剣な文献作業で本当に時間がかかるのは「だいたい分かる」ことではなく、次のような判断です。
* 著者は本当にこの結論を明確に述べているのか。
* AIが複数の段落の意味をまとめすぎていないか。
* 実験結果、変数定義、評価指標などの細部は正確か。
* この一文は著者の中心的な主張なのか、それともAIによる要約なのか。
* この見解を自分のノート、レビュー、論文草稿に安心して書けるか。
AIが流暢な回答を1つ出すだけなら、結局あなたはPDFに戻り、検索し、ページをめくり、場所を探し、読み直す必要があります。この作業は思考を中断させるだけでなく、面倒になって確認をやめてしまう原因にもなります。
段落単位の引用は、この手間を減らします。
BibGenieがPDF原文に基づいて回答するとき、回答には `[1]`、`[2]` のような引用マーカーが自動で埋め込まれます。ユーザーが引用を依頼する必要はありません。マーカーをクリックすると、BibGenieは対応するPDFを開き、該当ページへ移動し、引用された段落を原文上でハイライトします。
言い換えると、BibGenieは「答えは何か」だけでなく、「その答えはどこから来たのか」も、あなたの読書の現場へ直接戻してくれます。
## 段落単位の引用が重要な理由 [#段落単位の引用が重要な理由]
学術文献を読むことは、ニュースを眺めることとは違います。結論を得るだけでなく、その結論が論文の中でどのように支えられているかを理解する必要があります。
だからこそ、AI研究やAI製品では、source attribution(出典追跡)、grounded answer(根拠に基づく回答)、citation verification(引用検証)がますます重視されています。AIは本物らしい説明を生成できますし、本物らしい引用も生成できます。しかし「本物らしく見える」ことと「検証に耐える」ことは同じではありません。
文献の場面で信頼できる引用には、次の3つが同時に必要です。
1. **実在する出典**:引用が作り上げられた論文情報であってはいけません。
2. **明確な位置**:論文全体を示すだけでなく、根拠の具体的な場所を示す必要があります。
3. **内容の一致**:引用された原文が、AIの直前の説明を実際に支えている必要があります。
よく確認したくなるのは、次のような点です。
* この結論を著者は本当に述べているのか。
* AIが別々の段落、別々の実験、あるいは別々の論文を混同していないか。
* 方法の細部は本文、図注、付録のどこに基づくのか。それともAIの要約なのか。
* この一文をノートや論文草稿に安心して書けるか。
* この引用は「関連していそうに見える」だけで、回答中の具体的な主張を支えていないのではないか。
従来のAI引用は、多くの場合「どの論文を参照したか」または「何ページから来たか」までしか示せません。ざっと読むには十分でも、精読には足りません。PDFの1ページには、研究課題、方法、数式、実験設定、結果解釈、限界の議論が同時に含まれることがあります。ページ単位の引用は「だいたいこのページ」と示すだけですが、段落単位の引用は、確認すべき根拠の範囲を本当に必要な場所まで絞り込みます。
## ページ番号だけでは足りない理由 [#ページ番号だけでは足りない理由]
多くのAI文献ツールはページ番号を提示します。ページ番号はもちろん有用ですが、そこで終わりではありません。
学術PDFの1ページは、情報密度が非常に高いものです。特に二段組の論文、レビュー論文、方法論の論文、医学や工学の実験論文では、1ページの中に次のような内容が同時に含まれることがあります。
* 2つから3つの独立した段落
* 表や図注
* 複数の数式
* 実験設定、評価指標、結果解釈
* 著者による限界条件の説明
AIが「著者はこの方法が汎化性能を高めると考えている」と述べ、根拠として「6ページ」とだけ示した場合、あなたはそれが実験結果の段落なのか、アブレーション実験の段落なのか、Discussionの説明なのかを自分で判断しなければなりません。
段落単位の引用はページ番号を置き換えるものではなく、ページ番号の上にもう一段進めるものです。AIが引用した小さな根拠のまとまりを直接見られるようにします。特に「同じページに複数の候補となる根拠がある」場面で役立ちます。
## 細かければよいとは限らない理由 [#細かければよいとは限らない理由]
引用は細かいほどよい、と感じるかもしれません。できればすべての文、すべての主張に位置が付いていてほしい、と思うこともあります。ただ、実際の文献読解では、根拠が孤立した一文で完結することはあまりありません。著者はまず概念を定義し、次に実験設定を説明し、その次の文で結果を解釈することがよくあります。一文だけを切り出すと、必要な文脈が失われることがあります。
段落単位の引用は、自然な折り合いです。
* 論文全体より正確
* PDFの1ページより確認しやすい
* 一文単位の引用より文脈を保てる
* 複数段落の引用よりノイズが少ない
これは研究者が実際に論文を読む方法とも合っています。ひとつの文だけを見つめるのではなく、小さな段落を読み、前後の条件を理解し、それがある主張を支えているかを判断するからです。
## できること [#できること]
回答内の引用マーカーをクリックして、Zotero PDFの原文位置へ直接戻れます。手でページをめくったり、キーワード検索をしたり、AIがどの段落を参照したのか推測したりする必要がありません。
AIが方法、結果、研究上の限界を要約したとき、すぐに原文を確認し、AIが論文の意図に忠実かどうかを判断できます。
理論上の定義、実験設定、変数の説明、図表の結論、著者が付けた条件を確認する場面では、段落単位の引用のほうがページ番号より研究者の確認作業に合っています。
回答、引用マーカー、PDFページ、原文ハイライトがつながるため、追問、ノート、判断のそれぞれに明確な出所を残せます。
## よくある使い方 [#よくある使い方]
論文を丁寧に読むとき、BibGenieに研究課題、方法、実験設計、主な発見、限界を整理してもらえます。以前ならまとまった要約を得たあと、根拠を1つずつ探し直す必要がありました。今は回答にクリック可能な引用が付くため、項目ごとに原文へ戻って確認できます。
```text
この論文を精読し、「問題、方法、実験、主な発見、限界」に分けて要約してください。
```
AIは複雑な内容を流暢な表現に整理するのが得意ですが、その流暢さが問題を隠すことがあります。たとえば論文が「あるデータセットで性能がよい」とだけ述べているのに、AIが「この方法は既存手法を全面的に上回る」とまとめることがあります。論文が「著者はある傾向を観察した」と述べているだけなのに、AIが「著者はあるメカニズムを証明した」と書くこともあります。段落単位の引用があれば、すばやく原文に戻り、AIの表現が著者の意図を超えていないか確認できます。
```text
この論文で誤読または過度な一般化につながりやすい結論を5つ挙げてください。
```
よい文献ノートは「この論文が何を述べているか」だけでなく、「なぜ自分がそう理解したのか」も残します。段落単位の引用は、AIが作った構造化ノートと原文の根拠を結び付ける助けになります。あとでノートを見返すときも、論文全体を検索し直さず、そのとき根拠にしたPDFの段落へすぐ戻れます。
```text
この論文をZoteroノートの下書きとして整理し、研究課題、方法、発見、限界を重点的に残してください。
```
文献レビューで特に避けたいのは、引用が不正確なことと、見解の出どころが曖昧なことです。複数の論文を比較するとき、段落単位の引用があれば、比較項目ごとに出典を確認できます。A論文が問題をどう定義したか、B論文がどのデータセットを使ったか、C論文の限界は何か。各比較点から原文へ戻れるため、レビューを書くときに「著者が述べたこと」「AIが要約したこと」「自分の判断」を自然に区別できます。
```text
これらの論文について、研究課題、方法上の仮定、実験設定、限界の違いを比較してください。
```
方法と実験の細部は曖昧にできません。データセットの規模、ベースライン手法、評価指標、ハイパーパラメータ、除外基準、統計検定、アブレーション実験など、どれか1つを読み違えるだけで、その後の理解がずれてしまいます。段落単位の引用があれば、こうした細部が書かれた段落へすばやく移動し、AIが重要な条件を見落としていないか確認できます。
```text
この論文の実験設定を抽出してください。データセット、ベースライン手法、評価指標、主な比較結果を含めてください。
```
## 仕組み [#仕組み]
BibGenieはPDFを読むとき、ページを構造化されたテキストブロックとして解析します。各テキストブロックには、ページ番号、読書順序、ページ上の位置情報が保持されます。
AIが回答内で特定のテキストブロックを引用すると、BibGenieはそれを `[1]`、`[2]` のような引用マーカーとして表示します。マーカーをクリックすると、BibGenieは次の動作を行います。
1. 対応するZotero PDFを開く。
2. 引用があるページへ移動する。
3. 原文内で引用された段落またはテキストブロックをハイライトする。
表示されるのは「この論文がこの回答を支えている」ではなく、「この原文の段落がこの回答を支えている」という関係です。
## 根拠付きで精読する流れ [#根拠付きで精読する流れ]
段落単位の引用は、「根拠を確認しながら読む」AI精読の習慣を作る助けになります。
**PDFコンテキストを追加**:Zotero内のPDF attachmentをBibGenieの会話に追加するか、現在読んでいるPDFについてそのまま質問します。
**読書の問いを出す**:たとえば、BibGenieに方法の要約、実験設計の説明、限界の整理、複数論文の比較を依頼します。
**回答の構成を眺める**:まずAIが示した全体構造を見て、論文の主線を捉えているか判断します。
**引用をクリックして原文を確認**:採用しようとしている結論について、引用マーカーをクリックしてZotero PDFへ戻り、ハイライトされた段落が本当にその結論を支えているか確認します。
**追問または修正する**:AIがまとめすぎていたり、条件を落としていたりする場合は、「この原文に基づいて言い直してください」と続けて質問します。
この流れの目的は、AIに論文を代わりに読み終えてもらうことではありません。AIを使って、検証可能な精読状態へより早く入ることです。
## 限界と注意点 [#限界と注意点]
段落単位の引用は追跡可能性を大きく高めますが、「自動的に正しさを保証する」魔法ではありません。使うときは次の点に注意してください。
* **引用位置が関連していても、AIの解釈が必ず正しいとは限りません**:AIが関連する段落を見つけていても、その段落の理解にずれがある可能性はあります。
* **ハイライト範囲は位置確認の補助であり、最終的な引用形式ではありません**:正式な執筆では、APA、MLA、Chicago、GB/T 7714、または投稿先の指定形式に従って引用を整えてください。
* **PDFのテキスト層の品質が結果に影響します**:スキャン文書、OCR品質が低いPDF、複雑なレイアウト、数式が密集したページでは、テキストブロックの解析や位置合わせの精度に影響が出ることがあります。
* **図表や数式は視覚的な確認が必要です**:質問が図表、スキャンページ、視覚的なレイアウトに依存する場合は、スクリーンショットやページ画像も一緒に提供することをおすすめします。
* **AIはあなたの学術的判断を置き換えません**:段落単位の引用は確認を楽にしますが、最終的な判断は原文、研究設計、あなた自身の専門的理解に基づいて行ってください。
BibGenieに確認範囲を絞ってもらい、その原文が本当にある結論を支えているかはあなた自身が判断します。
## 使い方のヒント [#使い方のヒント]
* 重要な結論、データ、実験設定、著者の見解については、引用をクリックして原文を確認する習慣を付けます。
* AIの表現が大まかすぎる場合は、「引用箇所の原文に基づいて言い直してください」と追問します。
* スキャン文書やテキスト層の品質が低いPDFでは、引用位置の精度に影響が出ることがあります。必要に応じてページ画像も提供してください。
* 正式な執筆では、AIの回答を読解補助として扱い、論文の原文を最終的な根拠にしてください。
* 複数論文を比較するときは、まず各論文の根拠を1本ずつ確認し、その後でBibGenieの総合分析を見ます。
* 見慣れない用語に出会ったら、先に引用をクリックして原文を読み、そのうえでBibGenieに文脈を説明してもらいます。
* 回答が因果関係、メカニズムの説明、統計的結論に触れている場合は、必ず引用段落へ戻り、著者が本当にそのように述べているか確認します。
AI回答内の引用マーカーは、「信頼できそう」という印のように見えがちです。`[1]`、`[2]` が付いていると、その文にはもう根拠があるように感じます。
ただ、より効果的なのは、引用を入口として使うことです。
クリックして原文に戻り、次の3点を確認します。
1. 原文が本当にその問題を扱っているか。
2. 原文の語調が、強い結論なのか、弱い観察なのか、仮説的な議論なのか。
3. AIの要約が条件、範囲、反例を落としていないか。
この確認は数秒余分にかかるように見えますが、「読んだつもりで検証していない」リスクを大きく下げます。特にレビューを書いたり、研究発表を準備したり、研究仮説を整理したりするとき、この確認は後続作業の信頼性に直接関わります。
# 料金とクレジット (/ja/docs/pricing-credits)
BibGenieは、公式モデルの利用量を測るためにクレジットを使用します。クレジットはリクエスト回数とは異なります。1回のリクエストのコストは、モデル、コンテキスト長、出力長、ツール利用によって変わります。
すべてのプランでOpenAlex、Web Search、Web Extractを利用できます。Freeでは、外部ツールの成功した呼び出しごとに1クレジットを消費します。有料プランでは追加クレジットなしで利用でき、月間クレジットも増えます。Maxは、重い読解、比較、レビュー作成ワークフロー向けに最大の月間クレジットを提供します。
## プラン比較 [#プラン比較]
| プラン | 価格 | 月間クレジット | 主な機能 |
| :---------- | :-------- | :-------------- | :-------------------------------------------------------- |
| Free | $0 | 200クレジット / 月 | 基本機能 + OpenAlex、Web Search、Web Extract(成功した呼び出しごとに1クレジット) |
| Pro Monthly | $9.99 / 月 | 10,000クレジット / 月 | Freeのすべて + 外部ツール呼び出しの追加クレジットなし |
| Pro Yearly | $99 / 年 | 10,000クレジット / 月 | Pro Monthlyのすべて |
| Max Monthly | $30 / 月 | 35,000クレジット / 月 | Proのすべて + 深い読解、比較、レビュー生成の余裕 |
| Max Yearly | $295 / 年 | 35,000クレジット / 月 | Max Monthlyのすべて |
| Lifetime | $199 一括払い | 10,000クレジット / 月 | 長期的なPro特典 |
価格、割引、プロモーションは変更される場合があります。最終価格はPricingページおよびStripe Checkoutに表示される価格です。
## Credit Booster [#credit-booster]
無料ユーザーと有料ユーザーは追加クレジットパッケージを購入できます。
| パッケージ | 数量 | 価格 | 有効期限 |
| :------ | :--------- | :---- | :--- |
| Booster | 5,000クレジット | $6.99 | 6か月 |
## クレジットの消費方法 [#クレジットの消費方法]
クレジット使用量に主に影響する要素は次のとおりです。
* モデル選択:高コストモデルは通常、クレジットをより速く消費します。
* 入力長:PDF、ノート、スナップショット、画像、チャット履歴は入力トークンを増やします。
* 出力長:長いレビュー、長い表、完全なノートはより多くのトークンを使います。
* ツール利用:検索、添付ファイル読解、Web検索、Web抽出は複数のモデル呼び出しを伴う場合があります。
* **外部ツール**:Freeでは、OpenAlex、Web Search、Web Extractの成功した呼び出しごとに**1クレジット**を消費します。有料プランでは、これらの呼び出しに**追加クレジットはかかりません**。会話内のモデル利用は別に計測されます。
* モデル倍率:`1.5x` や `2x` などのラベルは、おおよその利用目安です。
カスタムモデル、Ollama、LM StudioはBibGenieの公式モデルサービスを使用しないため、BibGenieクレジットを消費しません。費用や計算資源は、利用するプロバイダーまたはローカルマシン側で扱われます。
## 論文を読むと何クレジット使いますか? [#論文を読むと何クレジット使いますか]
固定値はありません。消費量は選択したモデル、入力コンテキスト、出力の長さ、現在のモデル価格によって変わります。各リクエストの正確な消費量は Usage ページで確認できます。
## クレジットがなくなった場合 [#クレジットがなくなった場合]
クレジット残高が不足している場合、公式モデルへのリクエストは続行できないことがあります。次の対応が可能です。
* 次回の月次更新を待つ。
* Pro、Max、Lifetimeへアップグレードする。
* Credit Boosterを購入する。
* BYOKまたはローカルモデルを使用する。
## 残高を確認する [#残高を確認する]
サインイン後、BibGenieはアカウント状態とクレジット残高を同期します。Webサイトのアカウント領域またはプラグインのユーザーページからも残高を確認できます。
# クイックプロンプト (/ja/docs/quick-prompts)
Quick Promptsは、繰り返し行う研究タスクのための再利用可能なショートカットです。よく使うプロンプトを保存し、入力欄へ素早く挿入して、現在のコンテキストに合わせて調整できます。
## Quick Promptsの用途 [#quick-promptsの用途]
研究課題、方法、貢献、限界、今後の課題を要約します。
選択テキストの翻訳、英語段落の推敲、学術的なトーンの調整を行います。
主張を抽出し、比較表を生成し、関連研究を整理します。
前提、方法論上の弱点、エビデンスの強さ、再現性を分析します。
## Quick Promptを作成する [#quick-promptを作成する]
BibGenieを開き、**Prompts Settings** に移動します。
追加ボタンをクリックして新しいquick promptを作成します。
名前、プロンプト本文、説明、タグを入力します。
トグルを使って、チャットページに表示するかどうかを制御します。
設定を保存し、チャットに戻ります。
## Quick Promptを使う [#quick-promptを使う]
チャットページでQuick Promptをクリックするか、プロンプトメニューから検索します。挿入後は現在の入力の一部になるため、編集を続けたり、コンテキストを追加したり、出力形式を指定したりできます。
例:
```text
Based on the paper I added, please use the following structure:
1. Research question
2. Method and data
3. Core findings
4. Limitations
5. How I might cite this paper
```
## Quick PromptsとCustom Instructionsの違い [#quick-promptsとcustom-instructionsの違い]
| 種類 | 範囲 | 向いている用途 |
| :------------------ | :---------- | :---------------------- |
| Quick Prompts | 現在の入力 | 要約、翻訳、比較、抽出などのタスクテンプレート |
| Custom Instructions | 長期的な振る舞いの好み | 回答言語、トーン、役割、書式設定の好み |
安定した個人的な好みはCustom Instructionsに入れ、タスク固有のワークフローはQuick Promptsに入れます。
## システムプロンプト [#システムプロンプト]
System Prompt は、すべての会話にわたってAIの全体的な振る舞いを導きます。Quick Prompts(現在の入力に適用)とは異なり、System Promptは**グローバル**に有効で、すべての会話が同じ指示に従います。
例えば、システムプロンプトを次のように設定すると:
```text
Always respond in English. Use academic writing conventions appropriate for computer science.
```
すべての応答は、繰り返し指示しなくても自動的にこのルールに従います。
**Prompts Settings** で1つのSystem Promptを設定できます。デフォルトは `Always respond in English.` です。お好みの回答言語、トーン、役割、書式スタイルに合わせて変更できます。
## Quick Prompt の設定項目 [#quick-prompt-の設定項目]
各Quick Promptには以下のフィールドがあります:
必須。有効にするとチャット入力欄の上にボタンとして表示されます。
必須。AIモデルにコンテキストとして送信されるテキストです。
任意。プロンプトの目的を説明し、ホバー時に表示されます。
任意。多数のプロンプトを管理する際の分類とフィルタリングに使用します。
## テンプレート例 [#テンプレート例]
```text
Read the paper I added and summarize it using this structure:
- Research question
- Core hypothesis
- Method and data
- Main findings
- Limitations
- Relevance to my current research
```
```text
Explain the selected text I added:
- What is the passage saying?
- What are the key concepts?
- How does it relate to the paper's main argument?
- What should I be careful about if I cite it?
```
```text
Extract material from these papers for a literature review:
- Core claim of each paper
- Agreements and disagreements between papers
- Themes that can be synthesized
- Remaining research gaps
```
# ノートとして保存 (/ja/docs/save-as-note)
Save as Noteは、役に立つBibGenieの回答を、保存、検索、再利用できるZoteroノートに変換します。
## 保存する2つの方法 [#保存する2つの方法]
BibGenieに次のように伝えます:"Save the summary above as a note for this paper."
最新の回答を保存するには、最後のアシスタントメッセージで **Save as Note** をクリックします。
## 対応している内容 [#対応している内容]
BibGenieはMarkdown / HTMLコンテンツをZoteroノートに変換します。一般的に対応している内容は次のとおりです。
* 見出しと段落
* 番号付きリストと箇条書き
* 数式
* コードブロック
* 表
* 引用とリンク
* 太字テキストとインラインコード
Zoteroノートには独自のエディタとHTMLサポートがあります。一般的な形式の多くはうまく動作しますが、非常に複雑なMarkdownやカスタムHTMLは簡略化される場合があります。
## 親アイテムのロジック [#親アイテムのロジック]
ノートを保存する際、BibGenieは判断できる範囲で最も適切な場所にノートを配置します。
| 入力 | 結果 |
| :------------ | :----------------------------------------------- |
| 通常アイテムを指定 | そのアイテムの子ノートを作成 |
| PDF添付ファイルを指定 | 可能であれば添付ファイルの通常の親アイテムを見つけ、そこにノートを添付 |
| 子ノートを指定 | 可能であれば子ノートの通常の親アイテムを見つけ、そこにノートを添付 |
| 親を指定しない | スタンドアロンノートを作成 |
| 親とコレクションを両方指定 | Zoteroの子ノートは親アイテムからコレクション所属を継承するため、コレクションは無視されます |
## 例 [#例]
```text
Save the paper summary above as a Zotero note for this item, titled "Paper Summary".
```
```text
Turn the comparison above into a literature review note and save it to Zotero.
```
```text
Convert the method section into reproducible experimental steps and save it as a note. Preserve code blocks and tables.
```
## ヒント [#ヒント]
* 保存する前に、BibGenieに回答を構造化するよう依頼します。
* 長い会話では、まずBibGenieに "rewrite this as a note" と依頼してから保存します。
* ノートを特定の論文に紐づけたい場合は、対象アイテムを明示します。
* スタンドアロンノートにしたい場合は、論文に添付しないよう伝えます。
# セマンティックインデックス (/ja/docs/semantic-index)
Semantic Index は BibGenie のセマンティック文献検索を支える仕組みです。Zotero の通常アイテムのタイトルと要旨をローカルでインデックス化するため、キーワードだけに頼らず、研究テーマを自然言語で説明して検索できます。
## 何をインデックス化しますか? [#何をインデックス化しますか]
現在、セマンティックインデックスは Zotero の通常アイテムを中心に扱います。
* タイトル
* 要旨
* 検索に役立つ一部のメタデータ
Semantic Search は PDF 全文検索とは異なります。論文に要旨がない場合やメタデータが不完全な場合、セマンティックマッチングの精度が下がることがあります。
## ステータス一覧 [#ステータス一覧]
| ステータス | 意味 |
| :------------ | :------------------ |
| bootstrapping | インデックス機能を初期化しています |
| indexing | インデックスを作成しています |
| updating | 既存のインデックス項目を更新しています |
| idle | インデックスは利用可能です |
| error | インデックス作成エラーが発生しました |
## 指標 [#指標]
| 指標 | 意味 |
| :------------ | :------------------ |
| Indexed Count | 正常にインデックス化されたアイテム数 |
| Failed Count | インデックス化に失敗したアイテム数 |
| Message | 現在のステータスまたはエラーメッセージ |
## Semantic Index を確認するタイミング [#semantic-index-を確認するタイミング]
* セマンティック検索の結果が非常に少ない。
* BibGenie がセマンティックインデックスを利用できないと表示する。
* 新しくインポートした論文がセマンティック検索に表示されない。
* Failed Count が増え続ける。
* Zotero を起動した直後で、インデックスがまだ bootstrapping または indexing の状態である。
## トラブルシューティング [#トラブルシューティング]
Preferences を開き、Semantic Index のステータスを確認します。
indexing または updating の場合は、完了するまで待ちます。
失敗したアイテムがある場合は、失敗分のインデックス作成を再試行します。
関連する論文にタイトルと要旨があるか確認します。
失敗が続く場合は、Zotero を再起動してもう一度確認します。
## ヒント [#ヒント]
* 要旨が揃っているほど、セマンティック検索の品質は向上します。
* キーワードだけでなく、自然言語の説明を使ってください。
* セマンティック検索を年、タグ、コレクションのフィルターと組み合わせます。
* 候補論文が見つかったら、PDF やノートをコンテキストに追加して深く読み込みます。
# BibGenie がライブラリを理解する仕組み (/ja/docs/semantic-understanding)
## このページの目的 [#このページの目的]
BibGenie で検索するとき、目的は入力した語と完全に同じ言葉を含む論文を見つけることだけではありません。多くの場合、用語が異なっていても、**同じアイデアについて書かれた** 論文を見つけたいはずです。
そこで **embeddings** と **indexing** が役立ちます。
## Embedding とは? [#embedding-とは]
Embedding は、テキストを意味を捉えた数値表現に変換する方法です。
背後の数学を理解する必要はありません。実用上の考え方はシンプルです。
* 似たテキストは似た embedding を生成しやすい
* 異なるトピックはより離れた embedding になりやすい
* これにより BibGenie は、正確な語句だけでなく意味を比較できます
たとえば、*drug discovery with knowledge graphs* についての論文は、語句が完全に一致していなくても、*graph methods for biomedical research* と検索したときに見つかる可能性があります。
## BibGenie が embedding を使う方法 [#bibgenie-が-embedding-を使う方法]
BibGenie は現在、通常の Zotero アイテムの **タイトル** と **要旨** からセマンティック検索を構築します。
流れは次のとおりです。
1. BibGenie が論文のタイトルと要旨を読み取ります。
2. そのテキストを embedding に変換します。
3. 結果を Zotero ライブラリ用のローカル検索インデックスに保存します。
4. トピック型の質問をすると、BibGenie は検索クエリも embedding に変換します。
5. クエリとインデックス済み論文を比較し、もっとも近い一致を返します。
そのためセマンティック検索は、言葉が一致するだけでなく、意味として関連する論文を見つけられます。
## Indexing とは? [#indexing-とは]
Indexing は、セマンティック検索を高速で実用的にするための準備段階です。
検索のたびにすべてを再計算するのではなく、BibGenie はまずライブラリ用の embedding ローカルインデックスを準備します。インデックスが存在すれば、BibGenie は論文全体をはるかに効率よく検索できます。
要するに:
* **Embedding** は BibGenie が意味を表現する助けになります
* **Indexing** は BibGenie がその意味をすばやく検索する助けになります
## 何に役立ちますか? [#何に役立ちますか]
セマンティックインデックスは、次のような場合に特に役立ちます。
* 研究テーマに関連する論文を探す
* 同じようなアイデアを別の言葉で扱う研究を見つける
* 方法、理論、問題領域を探索する
* 大規模な Zotero ライブラリをより自然に検索する
正確な著者、タイトル、用語、フレーズが分かっている場合は、キーワード検索も依然として有用です。質問が概念的な場合は、セマンティック検索のほうが役立ちます。
## 含まれるコンテンツ [#含まれるコンテンツ]
BibGenie が現在使用するもの:
* 論文タイトル
* 論文要旨
BibGenie は現在、次の内容からセマンティックインデックスを構築していません。
* PDF 全文
* ノート
* 注釈
* 添付ファイル
これにより、インデックス化は焦点が明確で、予測可能かつ高速になります。
## インデックスは頻繁に再構築する必要がありますか? [#インデックスは頻繁に再構築する必要がありますか]
通常は **ありません**。
多くの場合、ライブラリが変わると BibGenie がバックグラウンドで自動的にインデックス更新を処理します。論文の追加、レコードの変更、アイテムの削除があっても、必要な更新は通常 BibGenie が行います。
次のような場合は、インデックスの再構築を検討してください。
* セマンティックインデックスを初めて設定するとき
* 別の embedding モデルへ切り替えたあと
* 大量インポート後、結果が不完全または古いように見えるとき
* BibGenie が現在のインデックスに注意が必要だと表示したとき
* セマンティック結果が明らかにおかしく、きれいに作り直したいとき
セマンティック検索が通常どおり動作しているなら、基本的に何もする必要はありません。アプリが提案したとき、または結果が期待と合わなくなったときだけ再構築してください。
## Indexing ページのボタンの意味 [#indexing-ページのボタンの意味]
### Build / Rebuild [#build--rebuild]
初回のインデックス作成、または必要に応じた完全な再構築を行います。
使う場面:
* 初めてインデックスを設定する
* embedding モデルを変更した
* インデックス全体を更新したい
### Retry Failed Items [#retry-failed-items]
過去のインデックス作成で失敗した論文だけを再試行します。
使う場面:
* 失敗したアイテム数が 0 より大きい
* 完全な再構築の前に、軽い回復手順を試したい
## よくある質問 [#よくある質問]
キーワード検索は一致する語を探します。セマンティック検索は関連する意味を探します。そのため、表現が違っていても関連する論文を返すことがあります。
embedding がなければ、BibGenie は主に正確な用語に依存します。embedding によって、トピック、概念、意味的類似性で検索できるようになります。
まだインデックス化されていない、タイトルや要旨の内容が不足している、またはインデックスに注意が必要な可能性があります。問題が続く場合はインデックスの再構築を試してください。
いいえ。通常利用では、BibGenie はインデックスを自動更新する設計です。手動の再構築は主に初回設定、モデル変更、復旧時に使います。
## 次のステップ [#次のステップ]
* インデックスの状態確認とトラブルシューティング:[Semantic Index](/docs/semantic-index)
* 実際にセマンティック検索を使う方法:[Literature Search](/docs/literature-search)
# Web検索とWeb Extract (/ja/docs/web-search-extract)
デフォルトでは、BibGenieはまずZoteroライブラリを検索して読みます。Web Search / Web Extractはすべてのユーザーが利用でき、公開Web上の情報でライブラリを補完できます。
Freeでは、Web SearchまたはWeb Extractの成功した呼び出しごとに**1クレジット**を消費します。有料プランでは、これらの外部ツール呼び出しに**追加クレジットはかかりません**。会話内のモデル利用は通常どおりクレジットを消費する場合があります。
## Web SearchとWeb Extract [#web-searchとweb-extract]
公開Webを検索し、AIが読みやすいランキング済みの抜粋を返します。
特定のWebページを読み、会話に使う主要コンテンツを抽出します。
## Webアクセスを使う場面 [#webアクセスを使う場面]
Web Search / Web Extractは、次のような場合に役立ちます。
* 論文のプロジェクトページ、コードリポジトリ、データセットページを探す。
* 最近の背景情報を集める。
* モデル、ツール、機関、製品の公開ドキュメントを読む。
* Zoteroライブラリにまだない情報を補う。
* Webページ内容を要約、抽出、比較する。
Webコンテンツは変更されることがあり、不正確な場合もあります。正式な引用では、元論文、公式ドキュメント、または他の信頼できる情報源で確認してください。
## 有効化する方法 [#有効化する方法]
BibGenieアカウントにログインします。
チャット入力欄の下にある **Web Search** ボタンを探します。
ボタンをクリックしてWeb検索をオンまたはオフにします。
有効化したら、BibGenieにWeb検索またはWebページ読解を明示的に依頼します。
## 例 [#例]
```text
Search the web to see whether this paper has an official project page, code repository, or dataset page.
```
```text
Read this web page and summarize the parts relevant to my paper topic:
https://example.com
```
```text
First search my Zotero library, then search the web for recent developments in this area.
```
## プライバシーに関する注意 [#プライバシーに関する注意]
Webツールは公開Webページにアクセスします。Webアクセスを必要とするリクエストには、機密性の高い資料、未公開資料、 confidential な資料を含めないでください。非公開の作業には、Zoteroライブラリコンテキスト、ローカルコンテキスト、BYOK、またはローカルモデルを使用してください。
# Zotero アノテーション (/ja/docs/zotero-annotations)
BibGenie は、ハイライト、コメント、画像、インク、下線など、保存済みの Zotero アノテーションを直接扱えます。既知の添付ファイルから取得することも、ライブラリ全体を検索することもでき、会話から Zotero に戻るための追跡可能な参照を保持します。
## 2 つのアノテーションツール [#2-つのアノテーションツール]
| ツール | 使用する場面 | 範囲とフィルター |
| :------------------- | :------------------------------ | :------------------------------------------ |
| `get_annotations` | PDF、EPUB、スナップショットの添付ファイルが分かっている | その添付ファイルのアノテーションを読書順で返す |
| `search_annotations` | ライブラリ全体から探したい | ハイライト本文、コメント、タグ、色、種類、作成者、添付ファイル、コレクション、更新時刻 |
結果はページ分割され、必要な場合にだけ次の offset が取得されます。
`get_annotations` は親の文献 item ではなく添付ファイルを対象にします。通常の Zotero item から始めた場合、BibGenie は先に添付ファイルを特定します。
## チャットに追加 [#チャットに追加]
* Zotero Reader で保存済みアノテーションを選択し、右クリックして **Add to Chat** を選びます。
* ライブラリ表示で annotation item を選択して **Add to Chat** を選びます。
* [Add to Chat Settings](/ja/docs/add-to-chat-settings) の **Reader Annotations** と **Library Items** で各入口を制御できます。
コメントはアノテーション作成者の解釈であり、原資料の記述として扱われません。引用の仕組みについては [BibGenie Citation](/ja/docs/bibgenie-citations) を参照してください。
参照をクリックすると親の添付ファイルが開き、保存済みアノテーションへ移動します。BibGenie は既存のアノテーションを編集または削除しません。画像やインクのアノテーションには検索可能なテキストが少ない場合があります。
# Zoteroコレクションとタグ整理ガイド (/ja/docs/zotero-collections-tags-best-practices)
Zoteroのコレクションとタグはどちらも文献整理に使えますが、解決する問題は異なります。長期的にメンテナンス可能なZoteroライブラリは、コレクションだけ、あるいはタグだけに頼るのではなく、コレクションをプロジェクトやテーマの入り口として、タグをコレクション横断的な検索軸として、保存済み検索を動的に変化するワークフローに使い分けるのが一般的です。
BibGenieを使用している場合、このガイドは「どう整理すべきか」という方法論にとどまらず、実行可能なワークフローにもなります。BibGenieのライブラリ整理機能は、既存のコレクション、タグ、アイテムを棚卸しし、あなたの研究体系に基づいて整理計画を提案し、確認後にコレクションの一括作成、タグの追加/削除、アイテムの移動、混乱したタグのリネームや統合を実行します。
コレクションは「この文献はどのプロジェクト、コース、レビュー、テーマの入り口に属するか?」に答え、タグは「この文献にはどんな特徴、方法、ステータス、対象、用途があるか?」に答えるものです。
Zoteroはコレクションやタグといった基本的な整理機能を提供します。BibGenieのライブラリ整理機能は、あなたの既存の整理方法を理解し、確認可能な計画を提案し、承認後に実行する、ライブラリ整理アシスタントのような存在です。
BibGenieのライブラリ整理機能の完全な能力紹介とプロンプト例については、[ライブラリ管理ドキュメント](https://www.bibgenie.com/ja/docs/library-management)を参照してください。
## クイックリファレンス [#クイックリファレンス]
Zoteroの整理を始めたばかりの方は、以下のルールに従ってください:
| シナリオ | 推奨 | BibGenieの支援内容 |
| :-------------------------------------- | :--------------- | :------------------------------------------------ |
| 論文、コース、課題、プロジェクト、学位論文 | コレクション | 選択した文献からプロジェクトのコレクション構造を生成し、該当するコレクションに文献を追加 |
| 研究テーマ、研究方法、データ種別、地域、理論的枠組み | タグ | タイトル、要旨、メタデータを読み取り、統一的な topic/method/status タグを提案 |
| `to-read`、`read`、`important`、`reviewed` | Coloredタグまたは通常タグ | 現在の読書タスクにステータスタグを一括追加または削除 |
| 最近7日間の追加、未読、DOI欠落、タグの組み合わせ | 保存済み検索 | 検索条件とその後の整理ルールの設計を支援 |
| 書評と評された本、同一作品の異なるバージョン | Related items | 関連する可能性のあるエントリを特定するが、関連付けの確立は手動確認を推奨 |
| 多すぎる細かいサブコレクション | 避けるべき | 深すぎる、細分化されすぎた、重複したコレクションを特定し、統合を提案 |
## BibGenieのライブラリ整理機能でできること [#bibgenieのライブラリ整理機能でできること]
Zoteroのコレクションとタグを手動で整理する際、時間がかかるのはボタンをクリックすることではなく、判断することです:どのタグが重複しているか、どの文献がどのコレクションに属するか、どのメタデータが欠落しているか、どの操作が多すぎるアイテムに影響するか。BibGenieのライブラリ整理機能の価値はここにあります。
| タスク | BibGenieができること |
| :--------- | :------------------------------------------------------- |
| 既存構造の棚卸し | コレクション階層、タグ語彙、特定のコレクションやタグ下のアイテムを一覧表示 |
| 整理対象の特定 | 未分類アイテム、最近追加された文献、DOI/要旨がないエントリ、タグやコレクションごとのアイテムを検索 |
| 整理計画の設計 | タイトル、要旨、メタデータ、既存のタグとコレクションに基づいて分類体系を提案 |
| アイテムの一括整理 | 指定したアイテムにタグを追加/削除、コレクションに追加/から削除 |
| コレクションの作成 | 適切な親の下に新しいコレクションを作成し、候補アイテムを配置することも可能 |
| タグのクリーンアップ | タグのリネーム、古いタグを既存タグに統合、ライブラリ全体で未使用タグを削除 |
| コレクションの整理 | コレクションのリネーム、移動、空または不要なコレクションの削除(コレクションを削除してもアイテムは削除されない) |
| メタデータの確認 | 完全なメタデータを読み取り、欠落フィールドを特定し、信頼できるソースがある場合に修正を支援 |
メタデータの変更、コレクションの作成、アイテムの移動、タグの一括編集、コレクション/タグのリネームや削除はすべて書き込み操作です。BibGenieはアクションを提案し、承認を待ちます。明示的な確認なしにZoteroライブラリを変更することはありません。
適切なBibGenie整理リクエストには、範囲、目的、制約を含める必要があります:
```text
Please organize the currently selected items. First read the existing collections and tags, then propose an organization plan based on titles, abstracts, and metadata.
Prefer reusing existing collections and tags; only suggest creating new ones if there is genuinely no suitable place.
Do not modify Zotero yet. First output which items will be affected, which tags will be added, and which collections will be used.
```
このプロンプトの背後にある原則は、BibGenieのライブラリ整理機能の核となるワークフローです:まず現状を把握し、次に整理対象を特定し、計画を提案し、最後に実行する。
## コレクションとは [#コレクションとは]
コレクションは、Zoteroの左サイドバーにあるフォルダとサブフォルダです。Zoteroの公式ドキュメントでは、コレクションをファイルシステムのフォルダではなく「プレイリスト」として考えることを推奨しています。同じアイテムを複数のコレクションに重複させずに含めることができます。完全なライブラリはあくまで `My Library` または対応するグループライブラリです。
コレクションは入り口として最適です。例:
* `PhD Thesis`
* `2026 Systematic Review`
* `Course - Research Methods`
* `Project - AI Literature Review`
* `Topic - Retrieval-Augmented Generation`
利点は明確さ、可視性、プロジェクトへの即時対応性です。コレクションを開けば、その作業に現在必要な主要な文献がすぐにわかります。
BibGenieを使用する際は、アイテムを移動する前に、プロジェクト目標に沿ったコレクション案を先に作成してもらいましょう:
```text
Please list my existing collections first, then decide whether the selected items can fit into existing collections.
If the existing structure isn't sufficient, design a one-to-two-level collection draft for my "literature review writing project."
Output each collection's purpose and the proposed items it would contain. Do not modify Zotero.
```
通常のコレクションを削除しても、組織上の入り口が削除されるだけで、中のアイテムは削除されません。アイテムを本当に削除するには、ゴミ箱に移動する必要があります。この違いは新しいユーザーにとって重要です。
これが、BibGenieがコレクション削除時に明示的に警告する理由でもあります:コレクションの削除は組織上の入り口を削除するだけで、アイテムはZoteroライブラリに残ります。コレクションにサブコレクションがある場合、BibGenieは親コレクションを直接削除することを拒否し、最初にサブコレクションの処理方法を決定するよう求めます。
## タグとは [#タグとは]
タグは、アイテム、添付ファイル、ノートに付加されるテキストラベルです。階層はありませんが、同じ論文を複数の角度から説明できます。Zoteroの公式ドキュメントでも、タグはトピック、方法、ステータス、評価、個人のワークフローに使用できると強調されています。
タグは「次元」として最適です。例:
* トピック:`llm-agent`、`scientific-discovery`、`citation-network`
* 方法:`survey`、`experiment`、`meta-analysis`、`case-study`
* 対象:`clinical-trial`、`graduate-students`、`zotero-users`
* ステータス:`to-read`、`read`、`skimmed`、`cited`
* 用途:`intro-section`、`related-work`、`method-baseline`
タグの強みは組み合わせ検索にあります。コレクション内で `llm-agent` と `survey` の両方のタグが付いたアイテムをフィルタリングしたり、ライブラリ全体で `to-read` かつ `citation-network` のタグが付いたすべてのアイテムを検索したりできます。
BibGenieの強みは、アイテムの内容に基づいてタグを一括提案できることです。まずは分析だけを依頼しましょう:
```text
Please list my existing tags first, then review the titles, abstracts, and existing tags of items in this collection.
Prefer reusing existing tags; only suggest new tags when no suitable one exists.
Finally, present recommended tags to keep, merge, add, and delete in a table. Do not modify Zotero.
```
## コレクション vs タグ [#コレクション-vs-タグ]
| 比較軸 | コレクション | タグ |
| :---------------- | :-------------------- | :----------------------- |
| 整理方法 | 階層化可能、サブコレクションあり | フラット、ネイティブのサブタグなし |
| 最も適した表現 | プロジェクト、コース、論文、テーマの入り口 | トピック、方法、ステータス、品質、用途などの属性 |
| 1つの文献を複数箇所に配置可能? | はい | はい |
| ライブラリ間コピー時に保持されるか | 通常保持されない | 通常アイテムとともに保持される |
| ブラウジングへの適合性 | 高い | 中程度 |
| クロスフィルタリングへの適合性 | 中程度 | 高い |
| メンテナンスリスク | コレクションの肥大化 | タグの同義語と表記ゆれ |
| 推奨粒度 | 少なく、安定して | より細かくてもよいが、命名は一貫させる |
すでに `Topic - LLM Agents` コレクションがある場合、すべてのアイテムに `llm-agents` タグを付ける必要はありません。ただし、他のコレクションをまたいでこのトピックを検索したい場合は除きます。
BibGenieで整理する際も、このルールをプロンプトに含めることをお勧めします:
```text
Please avoid making tags and collections fully redundant. Don't mechanically add the same tag to every item when the collection already expresses the project membership. Only add topic tags when cross-collection search is needed.
```
## 推奨整理モデル [#推奨整理モデル]
ほとんどの研究者にとって、安定したZotero構造は3つの層で構成されます。
### 1. 少数のトップレベルコレクションで大きな方向性を管理 [#1-少数のトップレベルコレクションで大きな方向性を管理]
トップレベルのコレクションは多すぎないようにします。長期的に頻繁に名前を変更しない入り口として設計しましょう:
```text
My Library
Inbox
Thesis
Papers
Projects
Topics
Teaching
Archive
```
あるいは、より研究分野に近い形で:
```text
My Library
Domain - AI for Science
Domain - Bibliometrics
Domain - Human-Computer Interaction
Project - BibGenie SEO
Project - Zotero Workflow Study
```
### 2. 1~2階層のサブコレクションでプロジェクトを整理 [#2-12階層のサブコレクションでプロジェクトを整理]
無制限に階層を深くすることは避けましょう。通常は2階層で十分です:
```text
Project - Systematic Review
01 Search Results
02 Screening
03 Included Studies
04 Background Reading
05 Cited in Manuscript
```
この構造はトピック別の細分化よりも研究の流れに対応しているため、実際の執筆により適しています。
### 3. タグを組み合わせ可能な横断的次元として使用 [#3-タグを組み合わせ可能な横断的次元として使用]
タグですべてのコレクションを置き換える必要はありません。タグは「この論文には他にどんな検索可能な属性があるか」を記録するのに適しています:
```text
method:survey
method:experiment
topic:semantic-search
topic:zotero
status:to-read
status:read
use:background
use:key-citation
```
Zoteroにはネイティブの階層タグはありませんが、`method:`、`topic:`、`status:` のようなプレフィックスで名前空間をシミュレートできます。これにより曖昧さが減り、タグセレクターでのスキャンが容易になります。
## タグの命名規則 [#タグの命名規則]
優れたタグシステムとは、タグの数が多いことではなく、一貫性があることです。
| ルール | 推奨 | 非推奨 |
| :--------------------- | :------------------ | :------------------------------------ |
| 小文字を使用 | `semantic-search` | `Semantic Search`、`semantic Search` |
| 複合語はハイフンで区切る | `citation-network` | `citation network`、`citation_network` |
| カテゴリにプレフィックスを付ける | `method:survey` | `survey`、`surveys` の混在 |
| ステータスタグは統一する | `status:to-read` | `unread`、`to read`、`todo` の混在 |
| 広すぎるタグを避ける | `topic:llm-agent` | `ai`、`paper`、`research` |
| 一時的なタグがライブラリを汚染するのを避ける | `use:intro-section` | `maybe-use-in-chapter-2-later` |
既に重複したタグがある場合は、タグセレクターで古いタグを対象のタグ名にリネームして統合できます。例えば、`to read` を `status:to-read` にリネームします。
タグがすでに混乱している場合は、まずBibGenieにタグ監査を依頼しましょう:
```text
Please list the current library's tags and identify potentially duplicate or synonymous tags — for example, different casing, spaces vs hyphens, singular vs plural.
Give merge suggestions and note how many items each tag affects.
Do not execute any renaming or deletion yet.
```
確認後に実行:
```text
I confirm the merge plan. Please rename the tag `to read` to `status:to-read`.
If `status:to-read` already exists, merge the two tags. Before executing, confirm how many items will be affected.
```
BibGenieのタグリネームと統合は、アイテムを1つずつループ処理するのではなく、Zoteroのライブラリ全体のタグ操作を使用します。古いタグを既存のタグ名にリネームすると、Zoteroが自動的に統合します。これは、アイテムごとに手動で新しいタグを追加して古いタグを削除するより安定しており、長期間にわたって蓄積された同義タグのクリーンアップに適しています。
## Coloredタグの使い方 [#coloredタグの使い方]
Zoteroは少数のタグに色を割り当てることをサポートしており、数字キーで素早く追加または削除できます。現在の公式ドキュメントでは、最大9つのcoloredタグを設定できます。
Coloredタグは「高頻度ステータス」に最適であり、すべてのトピックに使うべきではありません:
| Coloredタグ | 用途 |
| :----------------- | :--------- |
| `status:to-read` | 未読 |
| `status:reading` | 読書中 |
| `status:read` | 既読 |
| `use:key-citation` | 重要な引用 |
| `use:write-next` | 今後の執筆で使用予定 |
`machine-learning`、`history`、`statistics` のような通常のトピックタグをcoloredタグに設定することは避けましょう。トピックは増え続けますが、coloredタグのスロットは限られています。
BibGenieはどのタグが長期にわたってcoloredタグスロットを占有すべきかを判断できませんが、最も頻繁に使用されるステータス系タグを特定し、より少ない高頻度タグに統合すべきかを提案することはできます。
## 自動タグを保持すべきか [#自動タグを保持すべきか]
Zoteroがデータベース、ウェブサイト、図書館目録からアイテムを保存する際、自動的に件名見出しやキーワードを取り込むことがあります。これらの自動タグは時に有用ですが、ノイズを生むこともよくあります:大文字小文字の不統一、粒度の乱雑さ、範囲が広すぎる用語、タグの肥大化。
推奨戦略:
1. 新しいライブラリまたは整理を徹底するユーザー:自動タグをオフにし、コアタグを手動で管理する。
2. 統制語彙に依存する医学、法律、図書館学のユーザー:最初は自動タグを保持し、定期的にクリーンアップする。
3. 多くの自動タグが蓄積されているユーザー:最初に自動タグを非表示にし、不要と確認できたら一括削除する。
無効化するには、Zoteroの設定/環境設定 > 一般 に移動し、`キーワードと件名標目を含むアイテムに自動的にタグを付ける` のチェックを外します。
どの自動タグに価値があるかわからない場合は、BibGenieに頻度とセマンティクスでグループ化させましょう:
```text
Please check the current library's tags and list those that may be from automatic import, overly broad, or inconsistently cased. Do not delete anything, just give cleanup suggestions.
```
## 保存済み検索は過小評価されている整理ツール [#保存済み検索は過小評価されている整理ツール]
保存済み検索は「スマートコレクション」のようなものです。固定された結果ではなく検索条件を保存するため、ライブラリの変化に応じて自動的に更新されます。
保存済み検索に適したユースケース:
* `Unread`:タグが `status:read` ではない
* `Recent Additions`:最近7日間に追加されたアイテム
* `Missing DOI`:DOIが空のアイテム
* `Need Review`:特定のコレクション内で `status:to-read` タグが付いたアイテム
* `Key RAG Papers`:`topic:rag` と `use:key-citation` の両方を持つアイテム
同じフィルター条件を繰り返し使用している場合は、新しい静的なコレクションを作成するのではなく、保存済み検索の作成を検討すべきです。
BibGenieは、すべての動的タスクをコレクションに変換するよりも、保存済み検索のルール設計を支援する方が適しています。例:
```text
I want to create a dynamic view of "unread RAG papers."
Please review my existing tags and collections first, then suggest Zotero saved search criteria.
If existing tags aren't suitable, explain which tags need to be standardized first.
```
BibGenieは同様の保存済み検索アプローチで整理対象を見つけることもできます。例えば「最近30日間に追加されたがどのコレクションにも入っていないアイテム」「DOIのないジャーナル記事」「古いタグはあるが新しいタグがないアイテム」などです。これらのタスクは、最初に候補リストを出力し、その後で一括変更するかを決定するのに適しています。
## Related Itemsの使い方 [#related-itemsの使い方]
Related itemsはタグやコレクションの代わりにはなりません。Zoteroフォーラムの議論でも指摘されているように、Relatedの問題は、「2つのアイテムが関連している」としか言えず、「なぜ関連しているのか」を明確に表現できないことです。したがって、明確な1対1または少数の関係に適しています:
* 書評と評された本
* 会議論文とその拡張ジャーナル版
* データセット論文とそれを使用するベンチマーク論文
* 同一研究のプレプリント、正式出版版、正誤表
* レビュー記事で繰り返し議論されている核となるソース文献
単に「これらのアイテムはすべて同じトピックに属する」ことを表現したい場合は、タグまたはコレクションを使用しましょう。
## 3つの一般的なワークフロー [#3つの一般的なワークフロー]
### ワークフローA:論文またはレビューを書く [#ワークフローa論文またはレビューを書く]
執筆プロジェクト用のコレクションを作成します(例:`Project - LLM Agent Review`)。
候補の文献をまず `01 Search Results` または `Inbox` に入れます。
タグでトピック、方法、ステータスをマークします(例:`topic:tool-use`、`method:benchmark`、`status:to-read`)。
スクリーニング後、核となる文献を `03 Included Studies` に移動または追加します。
`use:key-citation`、`use:intro-section`、`use:method-section` で執筆上の用途をマークします。
BibGenieに適したプロンプト:
```text
Please examine the `Project - LLM Agent Review` collection.
First list the existing subcollections and tags, then classify the papers into five categories following a review writing workflow: search results, screening, included, background, and cited.
Prefer using existing subcollections; justify any new ones needed.
First output a table, do not move any items yet.
```
確認後:
```text
I confirm this classification table. Please add these items to the corresponding collections per the table, and add the `use:key-citation` tag to core papers.
After completion, summarize how many items were modified, which collections were used, and which tags were added.
```
### ワークフローB:長期的な研究分野の構築 [#ワークフローb長期的な研究分野の構築]
長期的なコレクションを作成します(例:`Domain - AI for Science`)。
本当に必要な場合にのみ、少数のサブコレクションを作成します(例:`Foundation Papers`、`Benchmarks`、`Applications`)。
詳細なタグでトピック、方法、データセット、実験対象を記録します。
定期的に `Unfiled Items` を確認し、未分類の文献を適切なコレクションに追加するか削除します。
BibGenieに適したプロンプト:
```text
Please analyze the items in `Domain - AI for Science`.
First read the existing tags, identify 5 to 8 stable research topics, and suggest corresponding `topic:` tags.
Avoid creating too many subcollections; prefer tags unless a topic will be maintained separately long-term.
```
### ワークフローC:ライトユーザー [#ワークフローcライトユーザー]
複雑なシステムを維持したくない場合は、最小限のルールに従ってください:
* コレクション:プロジェクトまたはコースごとに作成。
* タグ:5~15の高頻度ステータスまたはトピックのみを使用。
* Coloredタグ:`to-read`、`read`、`important` のみマーク。
* 毎月のクリーンアップ:自動タグ、重複、未分類アイテム。
維持されている軽量なシステムは、維持されていない複雑なシステムよりも信頼性が高くなります。
ライトユーザーもBibGenieを使用できますが、焦点は「メンテナンスコストの削減」にあるべきで、より多くのタグを生成することではありません:
```text
Please classify the currently selected items into only three statuses: `status:to-read`, `status:reading`, `status:read`. If you can't determine the status, put it in `status:to-read` and show a preview first.
```
## 定期的なメンテナンスチェックリスト [#定期的なメンテナンスチェックリスト]
毎月Zoteroライブラリのハウスキーピングを行うことをお勧めします:
* `Unfiled Items` を開き、どのコレクションにも属していないアイテムを処理する。
* `Duplicate Items` を開き、重複を統合する(単に削除しない)。
* タグセレクターで同義タグを確認する(例:`methods` と `research-methods`)。
* 不要な自動タグを非表示にするか削除する。
* 最近追加されたアイテムのタイトル、著者、年、DOI、要旨がクリーンか確認する。
* 意味を失った一時的なサブコレクションを削除し、コレクションの肥大化を防ぐ。
タグの一括追加、コレクションの作成、アイテムの移動、メタデータの確認を実行する前に、BibGenieに候補アイテムと変更案をリストアップさせましょう。一括操作の場合は、必ずプレビューを確認し、「現在選択中のアイテムのみ処理」や「このコレクションのみ処理」など範囲を限定してください。
安定したBibGenieの月次整理プロンプト:
```text
Please help me with Zotero library housekeeping:
1. First list existing collections and tags.
2. Check for unfiled items, duplicate or synonymous tags, overly deep collections, and recently added unorganized items.
3. When checking items missing DOI or abstract, consider the item type to determine whether a DOI is actually expected.
4. Only output the problem list, impact scope, and suggested actions. Do not modify Zotero.
```
未分類アイテムを適切な場所に配置したい場合は、BibGenieにより具体的なタスクを依頼します:
```text
Please find the most recent 50 unfiled items and determine which collections they best fit into based on existing collections.
Do not create new collections unless the existing structure clearly has no suitable place.
First output each item, the suggested collection, the reason, and your confidence level.
```
## よくある間違い [#よくある間違い]
### 間違い1:コレクションを唯一の整理システムにする [#間違い1コレクションを唯一の整理システムにする]
すべての小さなトピックにサブコレクションを作成すると、数年後には数十から数百のコレクションができあがります。文献は深い階層に埋もれ、見つけるのに時間がかかるようになります。
BibGenieを使用する際も、細かいトピックごとにコレクションを作成させないでください。「長期的なプロジェクト、コース、論文、安定したトピックにのみコレクションを作成し、細かい概念にはタグを優先して使用する」という指示がより適切です。
### 間違い2:タグに命名規則がない [#間違い2タグに命名規則がない]
`to read`、`ToRead`、`unread`、`todo` が同時に存在すると、検索が機能しなくなります。タグシステムが最も恐れるのは同義語の漂流です。
BibGenieはこの漂流を検出し、古いタグを統一タグにリネームできます。既存のタグにリネームすることは、実質的に統合操作となります。
### 間違い3:Relatedでトピックの所属を表現する [#間違い3relatedでトピックの所属を表現する]
Relatedは明確な関係に適しており、トピックが類似したアイテムをまとめるのには適していません。トピックの所属はタグまたはコレクションを使用すべきです。
### 間違い4:サブコレクションの表示設定を忘れる [#間違い4サブコレクションの表示設定を忘れる]
Zoteroでは、サブコレクション内のアイテムはデフォルトで親コレクションに表示されるとは限りません。`View -> Show Items from Subcollections` で表示方法を変更できます。この設定は親子コレクションの関係の理解に影響するため、チームでの作業ではルールを統一するのが最善です。
### 間違い5:自動タグを長期間放置する [#間違い5自動タグを長期間放置する]
自動インポートされたタグはタグセレクターを散らかします。これらのキーワードに明示的に依存していない限り、定期的に非表示、削除、または自動タグを無効化すべきです。
### 間違い6:「ライブラリ全体を整理」を曖昧なコマンドとして扱う [#間違い6ライブラリ全体を整理を曖昧なコマンドとして扱う]
「ライブラリ全体を整理してください」は便利そうに聞こえますが、通常は範囲が広すぎます。BibGenieのライブラリ整理機能は、具体的な問題から始めるのに適しています。例えば:
* 最近追加されたが未整理のアイテム。
* さらなる細分化が必要なコレクション内のアイテム。
* 重複または同義のタグ。
* DOI、要旨、出版物タイトルが欠落しているエントリ。
* 今後の執筆プロジェクトで `use:key-citation` をマークする必要がある核となる文献。
より良いプロンプト:
```text
Please don't organize the entire library yet. Help me diagnose the 3 most pressing categories of issues: unfiled items, duplicate tags, and missing metadata. Only output the problem scope and suggested next steps.
```
### 間違い7:AIに検証不可能なメタデータを入力させる [#間違い7aiに検証不可能なメタデータを入力させる]
BibGenieはメタデータをチェックし、信頼できるソースがある場合に修正を支援できますが、AIにDOI、要旨、ジャーナル名、著者、ページ番号を独自に作成させるべきではありません。メタデータの書き込みでは、信頼できるソースはZoteroの既存メタデータ、ユーザー提供の情報、既に読んだアイテムの内容、またはBibGenieが検証可能な外部参照クエリ結果から得られるべきです。
適切なプロンプト:
```text
Please check the metadata completeness of the most recent 20 items. For entries missing a DOI or abstract, only suggest corrections when verifiable through reliable sources. Mark unverifiable items as "unconfirmed" and do not generate or guess content.
```
## 推奨テンプレート [#推奨テンプレート]
以下のテンプレートから直接始めることができます:
```text
Collections
Inbox
Project - [Project Name]
01 Search Results
02 To Screen
03 Included
04 Background
05 Cited
Domain - [Long-term Topic]
Foundation Papers
Methods
Applications
Archive
Tags
status:to-read
status:reading
status:read
use:key-citation
use:intro-section
use:method-section
method:survey
method:experiment
method:case-study
topic:[Topic Name]
```
## BibGenieを使用する際の安全なワークフロー [#bibgenieを使用する際の安全なワークフロー]
BibGenieはタグ、コレクション、アイテムの所属、一部のメタデータを管理できますが、ライブラリ整理はZoteroデータを変更する操作です。常に以下の4段階のプロセスに従ってください:
BibGenieに既存の構造(コレクション、タグ、整理対象のアイテム範囲)を読み取らせます。
BibGenieに既存のコレクションとタグを優先的に再利用するよう要求し、本当に適切な場所がない場合にのみ新規作成するよう指示します。
BibGenieに整理計画を出力させます。これには、追加するタグ、削除するタグ、移動先のコレクション、影響を受けるアイテム、承認が必要な操作を含めます。
手動で確認した後、BibGenieに明示的に実行を許可します。実行後、変更数、スキップされたアイテム、未完了タスクの要約を要求します。
推奨プロンプトテンプレート:
```text
Please organize the currently selected items. The goal is to establish clear Zotero collections and tags:
1. First list existing collections and tags.
2. Prefer reusing existing collections and tags; don't create similar names unnecessarily.
3. Determine which items should go into the same collection.
4. Then suggest consistent `topic:`, `method:`, `status:` tags.
5. Output which tags and collections will be added or removed for each item.
6. Do not modify Zotero yet; wait for my confirmation.
```
確認後:
```text
I confirm the organization plan above. Please execute these changes, then summarize how many items were modified, which tags were added, and which collections were used.
```
50アイテム以上の一括操作では、より明確に要求を記述します:
```text
This is a large batch organization task. First give a brief plan including which existing collections/tags will be used, whether new ones are needed, how many items will be affected, and which write operations need my approval.
After I confirm, execute in focused batches by shared purpose. Do not run one operation per item.
```
ライブラリ全体のタグをリネーム、統合、削除するだけの場合は、BibGenieにアイテムを1つずつ修正させないでください。タグレベルの操作を直接記述します:
```text
Please merge the library-wide tag `methodology` into the existing tag `method:methods`.
First confirm that both tags exist and how many items are affected, then wait for my approval.
```
コレクションをリネームまたは移動するだけの場合は、新しいコレクションを作成してすべてのアイテムを移動するのではなく、BibGenieにコレクション自体を操作させます:
```text
Please rename the collection `Old Thesis Reading` to `Project - Dissertation Reading`.
First list the matching collection key and its item count, wait for my confirmation, then execute.
```
## 参考資料 [#参考資料]
* [Zotero公式ドキュメント:Collections and Tags](https://www.zotero.org/support/collections_and_tags)
* [Zotero公式KB:Organizing a library](https://www.zotero.org/support/kb/organizing_a_library)
* [Zotero Forums:tags and collections best practice?](https://forums.zotero.org/discussion/115437/tags-and-collections-best-practice)
* [Zotero Forums:Collections vs tags](https://forums.zotero.org/discussion/116758/collections-vs-tags)
* [Zotero Forums:best use for related, tags, collections](https://forums.zotero.org/discussion/129569/best-use-for-related-tags-collections)
* [Mastering Zotero:Working with Tags](https://pressbooks.library.yorku.ca/masteringzotero/chapter/working-with-tags/)
* [Zotero Manual:Tags](https://zotero-manual.github.io/tags/)
* [Harvard Library:Organize Your Zotero Library](https://guides.library.harvard.edu/c.php?g=1245347\&p=9129454)
* [UMGC Library:Collections & Tags](https://libguides.umgc.edu/c.php?g=930616\&p=6753118)
* [Massachusetts General Hospital:Organizing Your Library](https://libguides.massgeneral.org/zotero/organizing-library)
* [Catherine Pope:Keeping Your Zotero Library Tidy](https://catherinepope.com/posts/keeping-your-zotero-library-tidy/)
* [Reddit:Collections and Tags](https://www.reddit.com/r/zotero/comments/1izhq0m/collections_and_tags/)
# Zotero WebDAV (/ja/docs/zotero-webdav)
Zotero の同期を使うと、複数のデバイスでライブラリを利用できます。Zotero の同期には、**データ同期** と **ファイル同期** の 2 つがあります。WebDAV はファイル同期に使われ、PDF、画像、スナップショット、その他の添付ファイルが対象です。
WebDAV は BibGenie の公式モデル、クレジット、チャット機能に直接影響しません。ただし、複数デバイスで Zotero を使う場合、WebDAV によって添付ファイルをローカルで利用可能にしやすくなります。これは、BibGenie がそのデバイス上で PDF やスナップショットを読めるかどうかに関係します。
## データ同期とファイル同期 [#データ同期とファイル同期]
| 種類 | 同期される内容 | 備考 |
| :----- | :----------------------------------- | :-------------------------------------------- |
| データ同期 | アイテム、タイトル、著者、出版年、ノート、タグ、コレクション、メタデータ | Zotero は無制限のデータ同期を無料で提供 |
| ファイル同期 | PDF、画像、スナップショット、音声、その他の添付ファイル | Zotero の無料ファイルストレージは 300 MB。WebDAV を代替として利用可能 |
Zotero 同期を使うには、通常 Zotero アカウントにサインインし、データ同期を有効化する必要があります。WebDAV が扱うのは添付ファイルのみで、Zotero アカウントのデータ同期を置き換えるものではありません。
まず Zotero の設定で Zotero アカウントにサインインし、データ同期を設定してください。WebDAV はファイルストレージ部分だけを置き換えます。
## WebDAV とは? [#webdav-とは]
WebDAV は、アプリケーションがリモートサーバー上のファイルを管理できるようにするプロトコルです。Zotero は WebDAV を Zotero 独自のファイルストレージの代替として利用でき、対応するサードパーティストレージ経由で添付ファイルを同期できます。
Zotero 公式のファイルストレージプランを購入せずに、PDF や添付ファイルを複数デバイスで使いたい場合に便利です。
## よく使われる WebDAV プロバイダー [#よく使われる-webdav-プロバイダー]
| プロバイダー | 無料容量 / 制限 | Web サイト | 備考 |
| :--------- | :------------------------------ | :--------------------------------------------------------- | :---------------- |
| Koofr | 初期 2 GB。アカウントタスク完了後、最大 10 GB | [https://koofr.eu/](https://koofr.eu/) | 設定しやすい。サーバーはヨーロッパ |
| Jianguoyun | 無料枠は月 1 GB アップロード、月 3 GB ダウンロード | [https://www.jianguoyun.com/](https://www.jianguoyun.com/) | 中国本土からは比較的速いことが多い |
ほかの選択肢については、Zotero 公式の [WebDAV Providers](https://www.zotero.org/support/kb/webdav_services) ページを参照してください。
## Koofr WebDAV を設定する [#koofr-webdav-を設定する]
Koofr はヨーロッパを拠点とするクラウドストレージプロバイダーです。設定が簡単で、Zotero 向けの WebDAV ガイドもあるためよく推奨されます。
[Koofr アカウント](https://koofr.eu/)を作成し、Koofr の Web アプリにログインします。
右上のアバターをクリックし、**Preferences** を開きます。
左メニューで **Password** を選択し、**App Passwords** までスクロールします。
`Zotero` などのアプリ名を入力し、**Generate** をクリックして生成されたパスワードを保存します。Koofr はこのパスワードを一度だけ表示します。
Zotero を開き、**Edit -> Preferences -> Sync** に移動します。macOS では **Zotero -> Settings -> Sync** を使います。
**File Syncing** で添付ファイル同期を有効にし、**WebDAV** を選択します。
次を入力します。
* **URL**: `https://app.koofr.net/dav/Koofr`
* **Username**: Koofr アカウントのメールアドレス
* **Password**: 生成した Koofr アプリパスワード
**Verify Server** をクリックします。検証に成功したら **OK** をクリックして設定を保存します。
Zotero の同期ボタンをクリックして、添付ファイルの同期を開始します。
URL 内の `Koofr` 部分は、大文字の K で始まる必要があります。
## Jianguoyun WebDAV を設定する [#jianguoyun-webdav-を設定する]
ブラウザで [Jianguoyun](https://www.jianguoyun.com/) にログインします。
右上のアカウント名をクリックし、**Account Info** を開きます。
**Security Options** を開きます。
**Third-party App Management** で **Add Application** をクリックします。
`Zotero` などの名前を入力し、パスワードを生成して保存します。これはアプリ専用パスワードで、Jianguoyun のログインパスワードではありません。
Zotero を開き、**Edit -> Preferences -> Sync** に移動します。macOS では **Zotero -> Settings -> Sync** を使います。
**File Syncing** で **Sync attachment files in My Library** を有効にし、**WebDAV** を選択します。
次を入力します。
* **URL**: `https://dav.jianguoyun.com/dav/`
* **Username**: Jianguoyun アカウント。通常はメールアドレス
* **Password**: Jianguoyun で生成したアプリ専用パスワード
**Verify Server** をクリックします。Zotero が WebDAV サーバー上に `zotero` フォルダーを作成するか尋ねた場合は、確認してください。
通常の Jianguoyun WebDAV サーバーアドレスは `https://dav.jianguoyun.com/dav/` です。
複数のコンピューターで Zotero を使う場合は、各デバイスで同じ WebDAV 設定を行い、Zotero データ同期でも同じアカウントを使っていることを確認してください。